AI model benchmarks
GPT vs Claude
GPT-6.2 Astra, Claude Fable 5.2 and GPT-6.2 Sol ran the same Superbench prompts.
Model tiers
24 ranked models across 5 tiers · Updated
Editorial rankings. Open a model for its scores, strengths and test runs.
S


A



B


C


D


Benchmark tools and archive
More current models with published runs
Browse archived models and runs · 156 archived model runs
Benchmark editions
Each edition includes its prompts, rubrics and published runs.
- Superbench 2.1Visual, 3D and game builds: four new single-prompt contracts plus returning Ember Glider and Low-Poly Tower Defense.
- Superbench 2.0One prompt, one HTML file. Constraint solving, event consistency, long-horizon planning and instruction boundaries.
- Superbench 1.xThe original repository-run suite: worldbuilding, gameplay, interaction and simulation tests.
The ADHD edit benchmark
Four edits of the same clip, with a side-by-side playback and per-model stats.
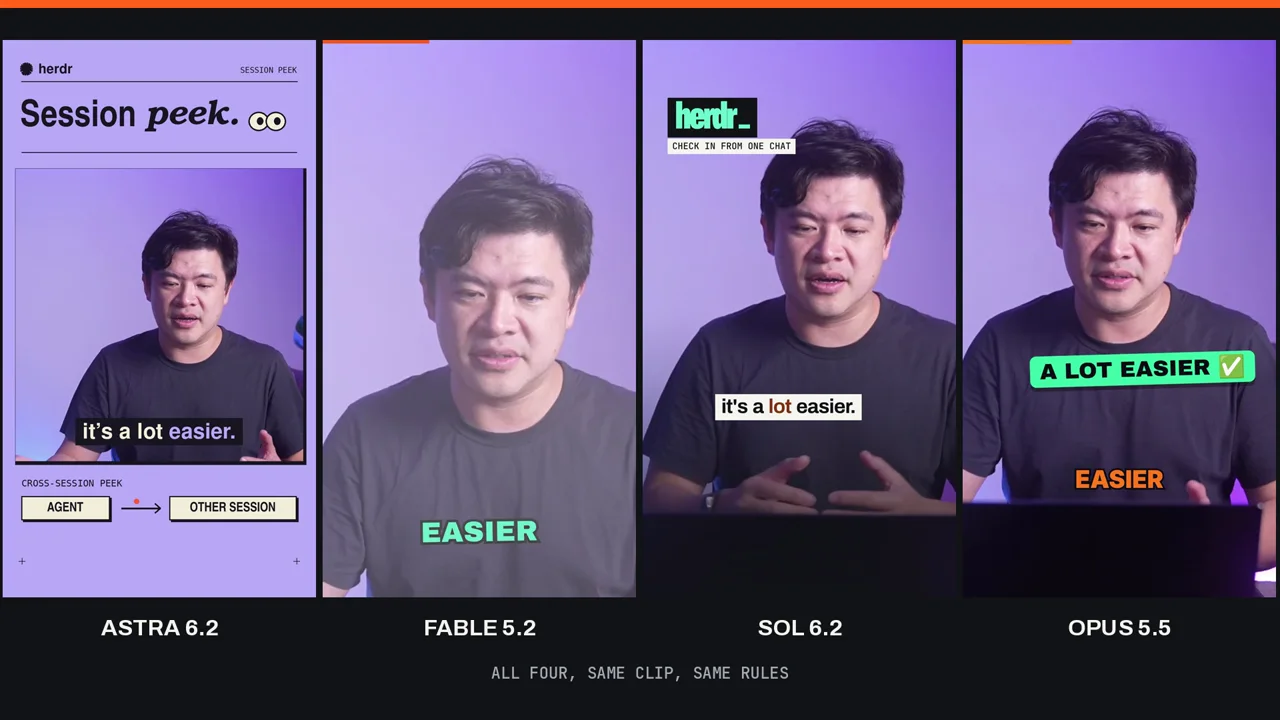 Watch the ADHD edit benchmark