
OpenAI
GPT-6 Astra
S-tier for end-to-end agent work, backed by a complete set of 16 published Superbash visual benchmark runs.
API pricing
USD per million tokens · OpenAI API Standard (≤272K input tokens)- Input
- $10
- Output
- $50
- Cached input
- $1
- Context window
- 1.05M
October 2 showcase: four browser builds and the Giza cinematic →
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-09-07
Specialist test · evaluated separately
Generation provenance: unrecorded
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Run date: 2026-09-07
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
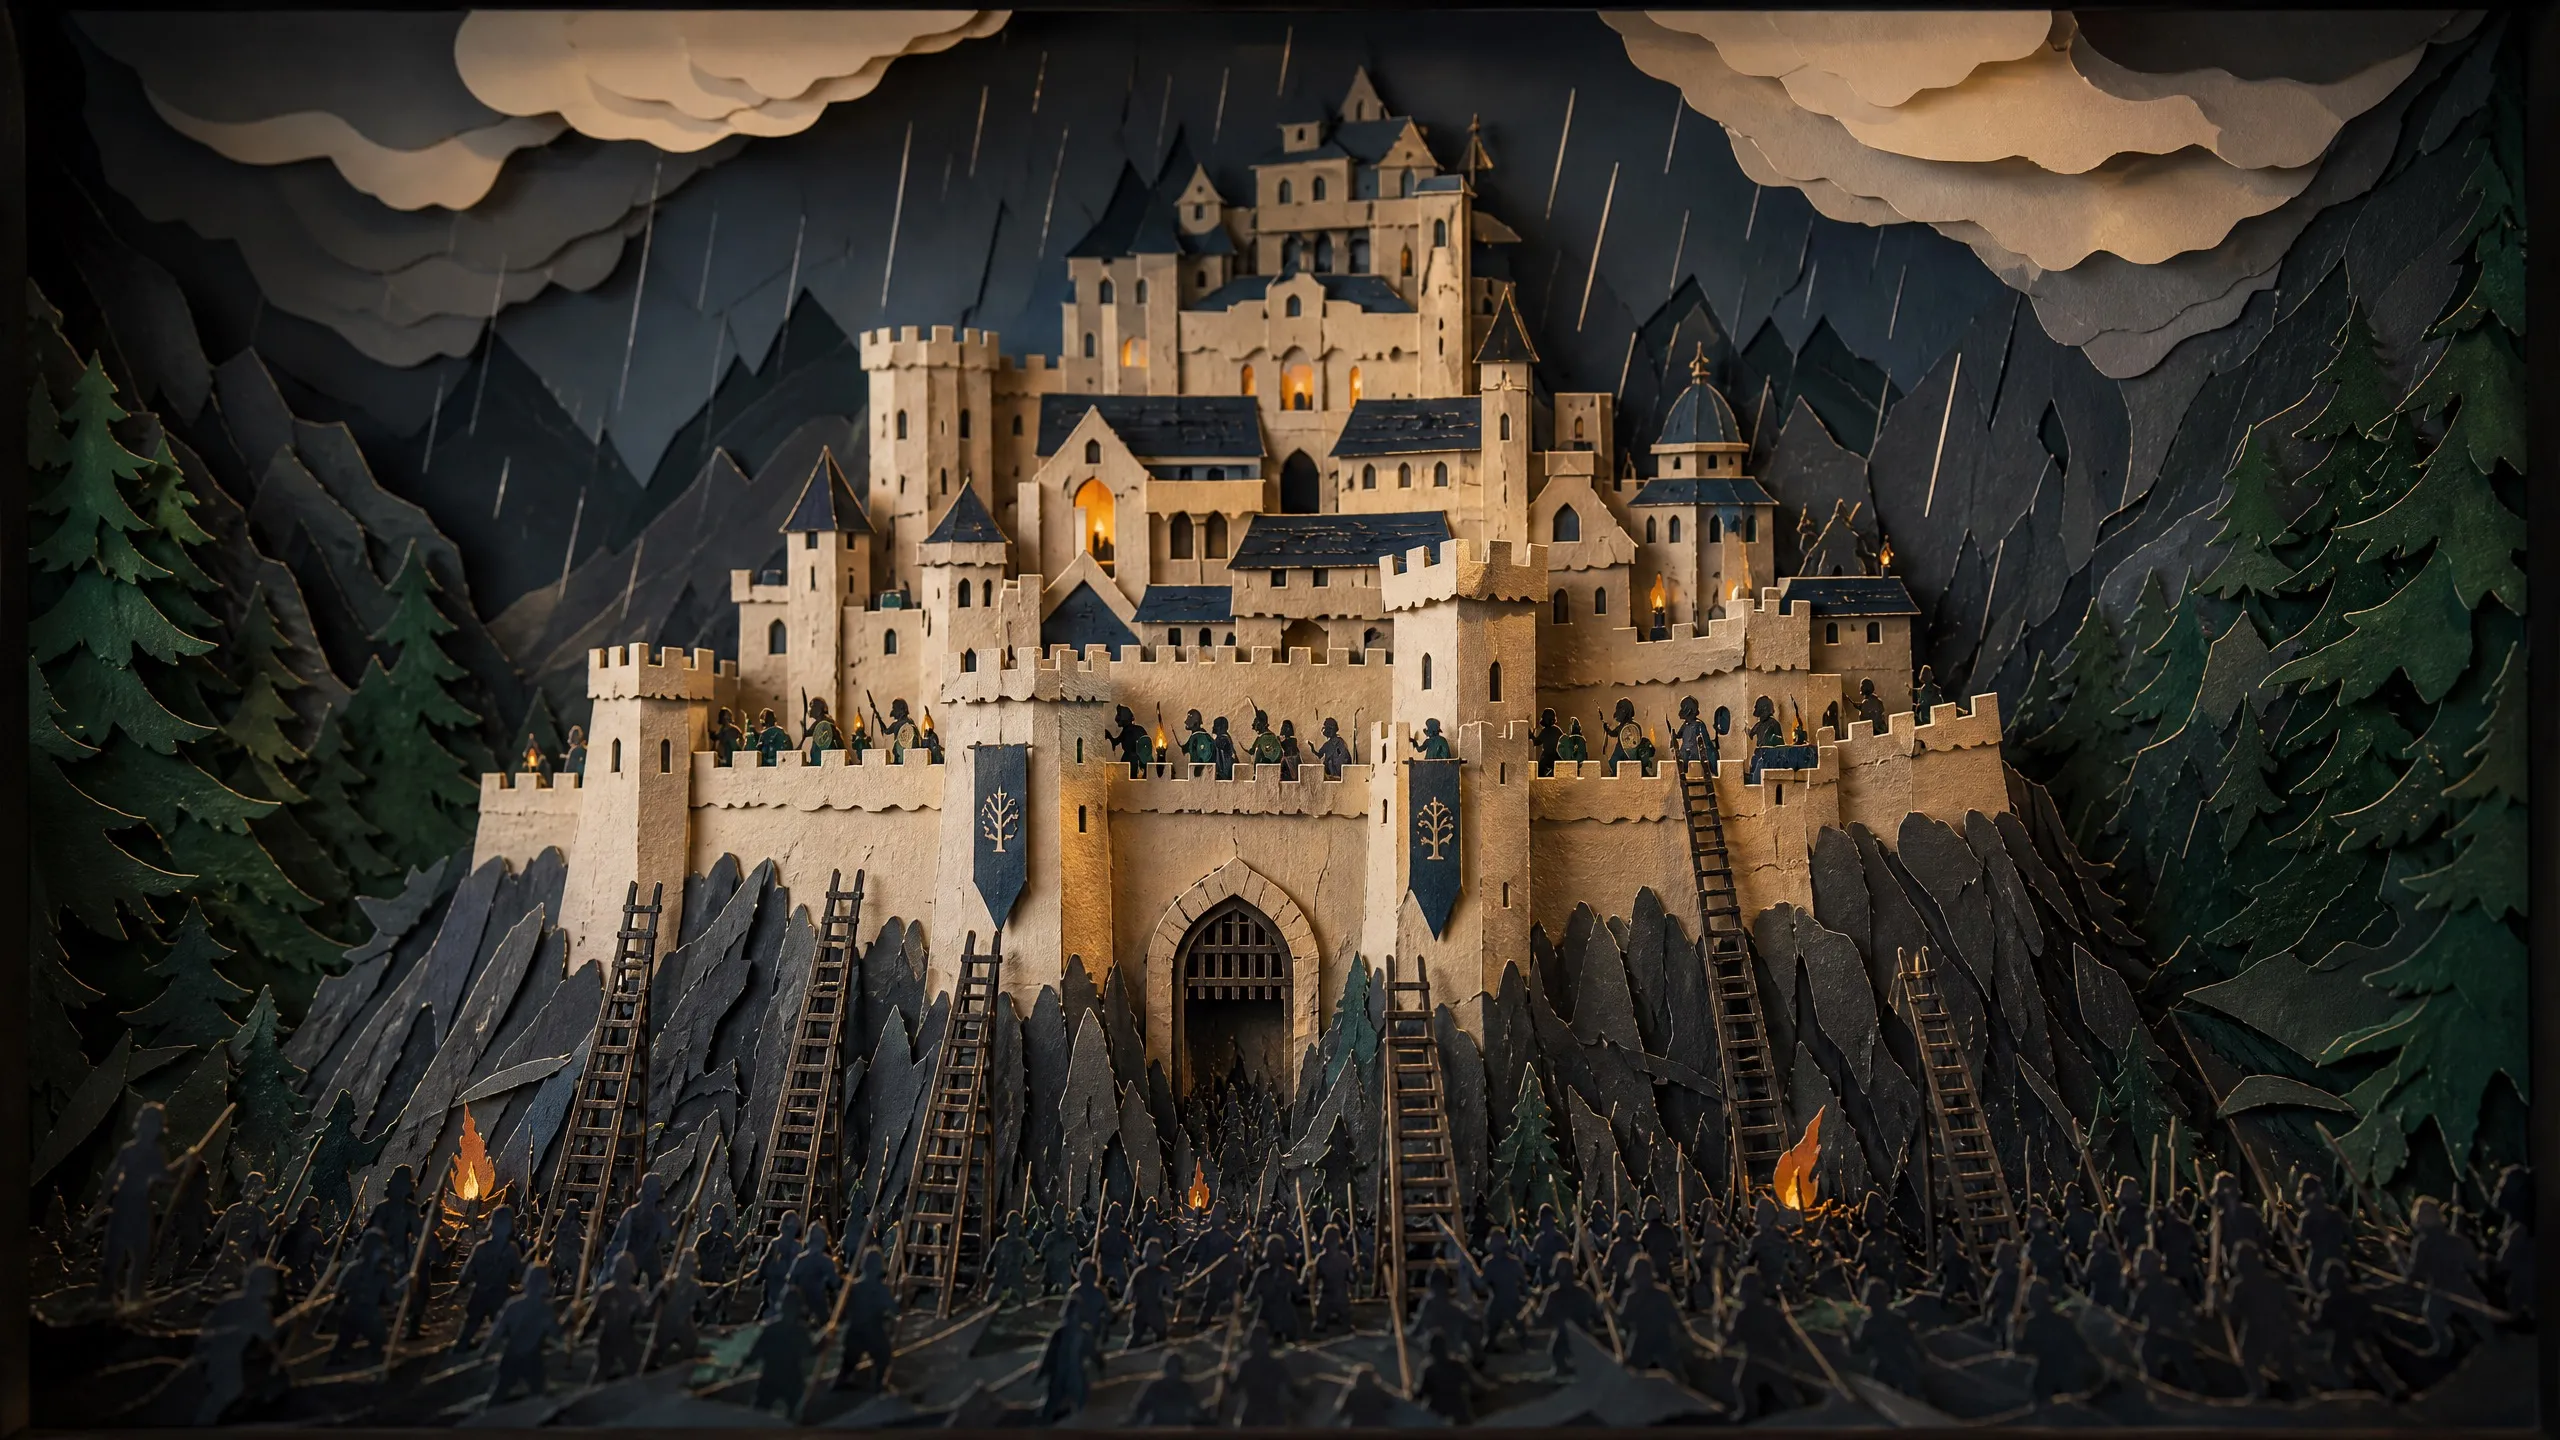
Helm's Deep
Run date: 2026-09-07
Generation provenance: unrecorded
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
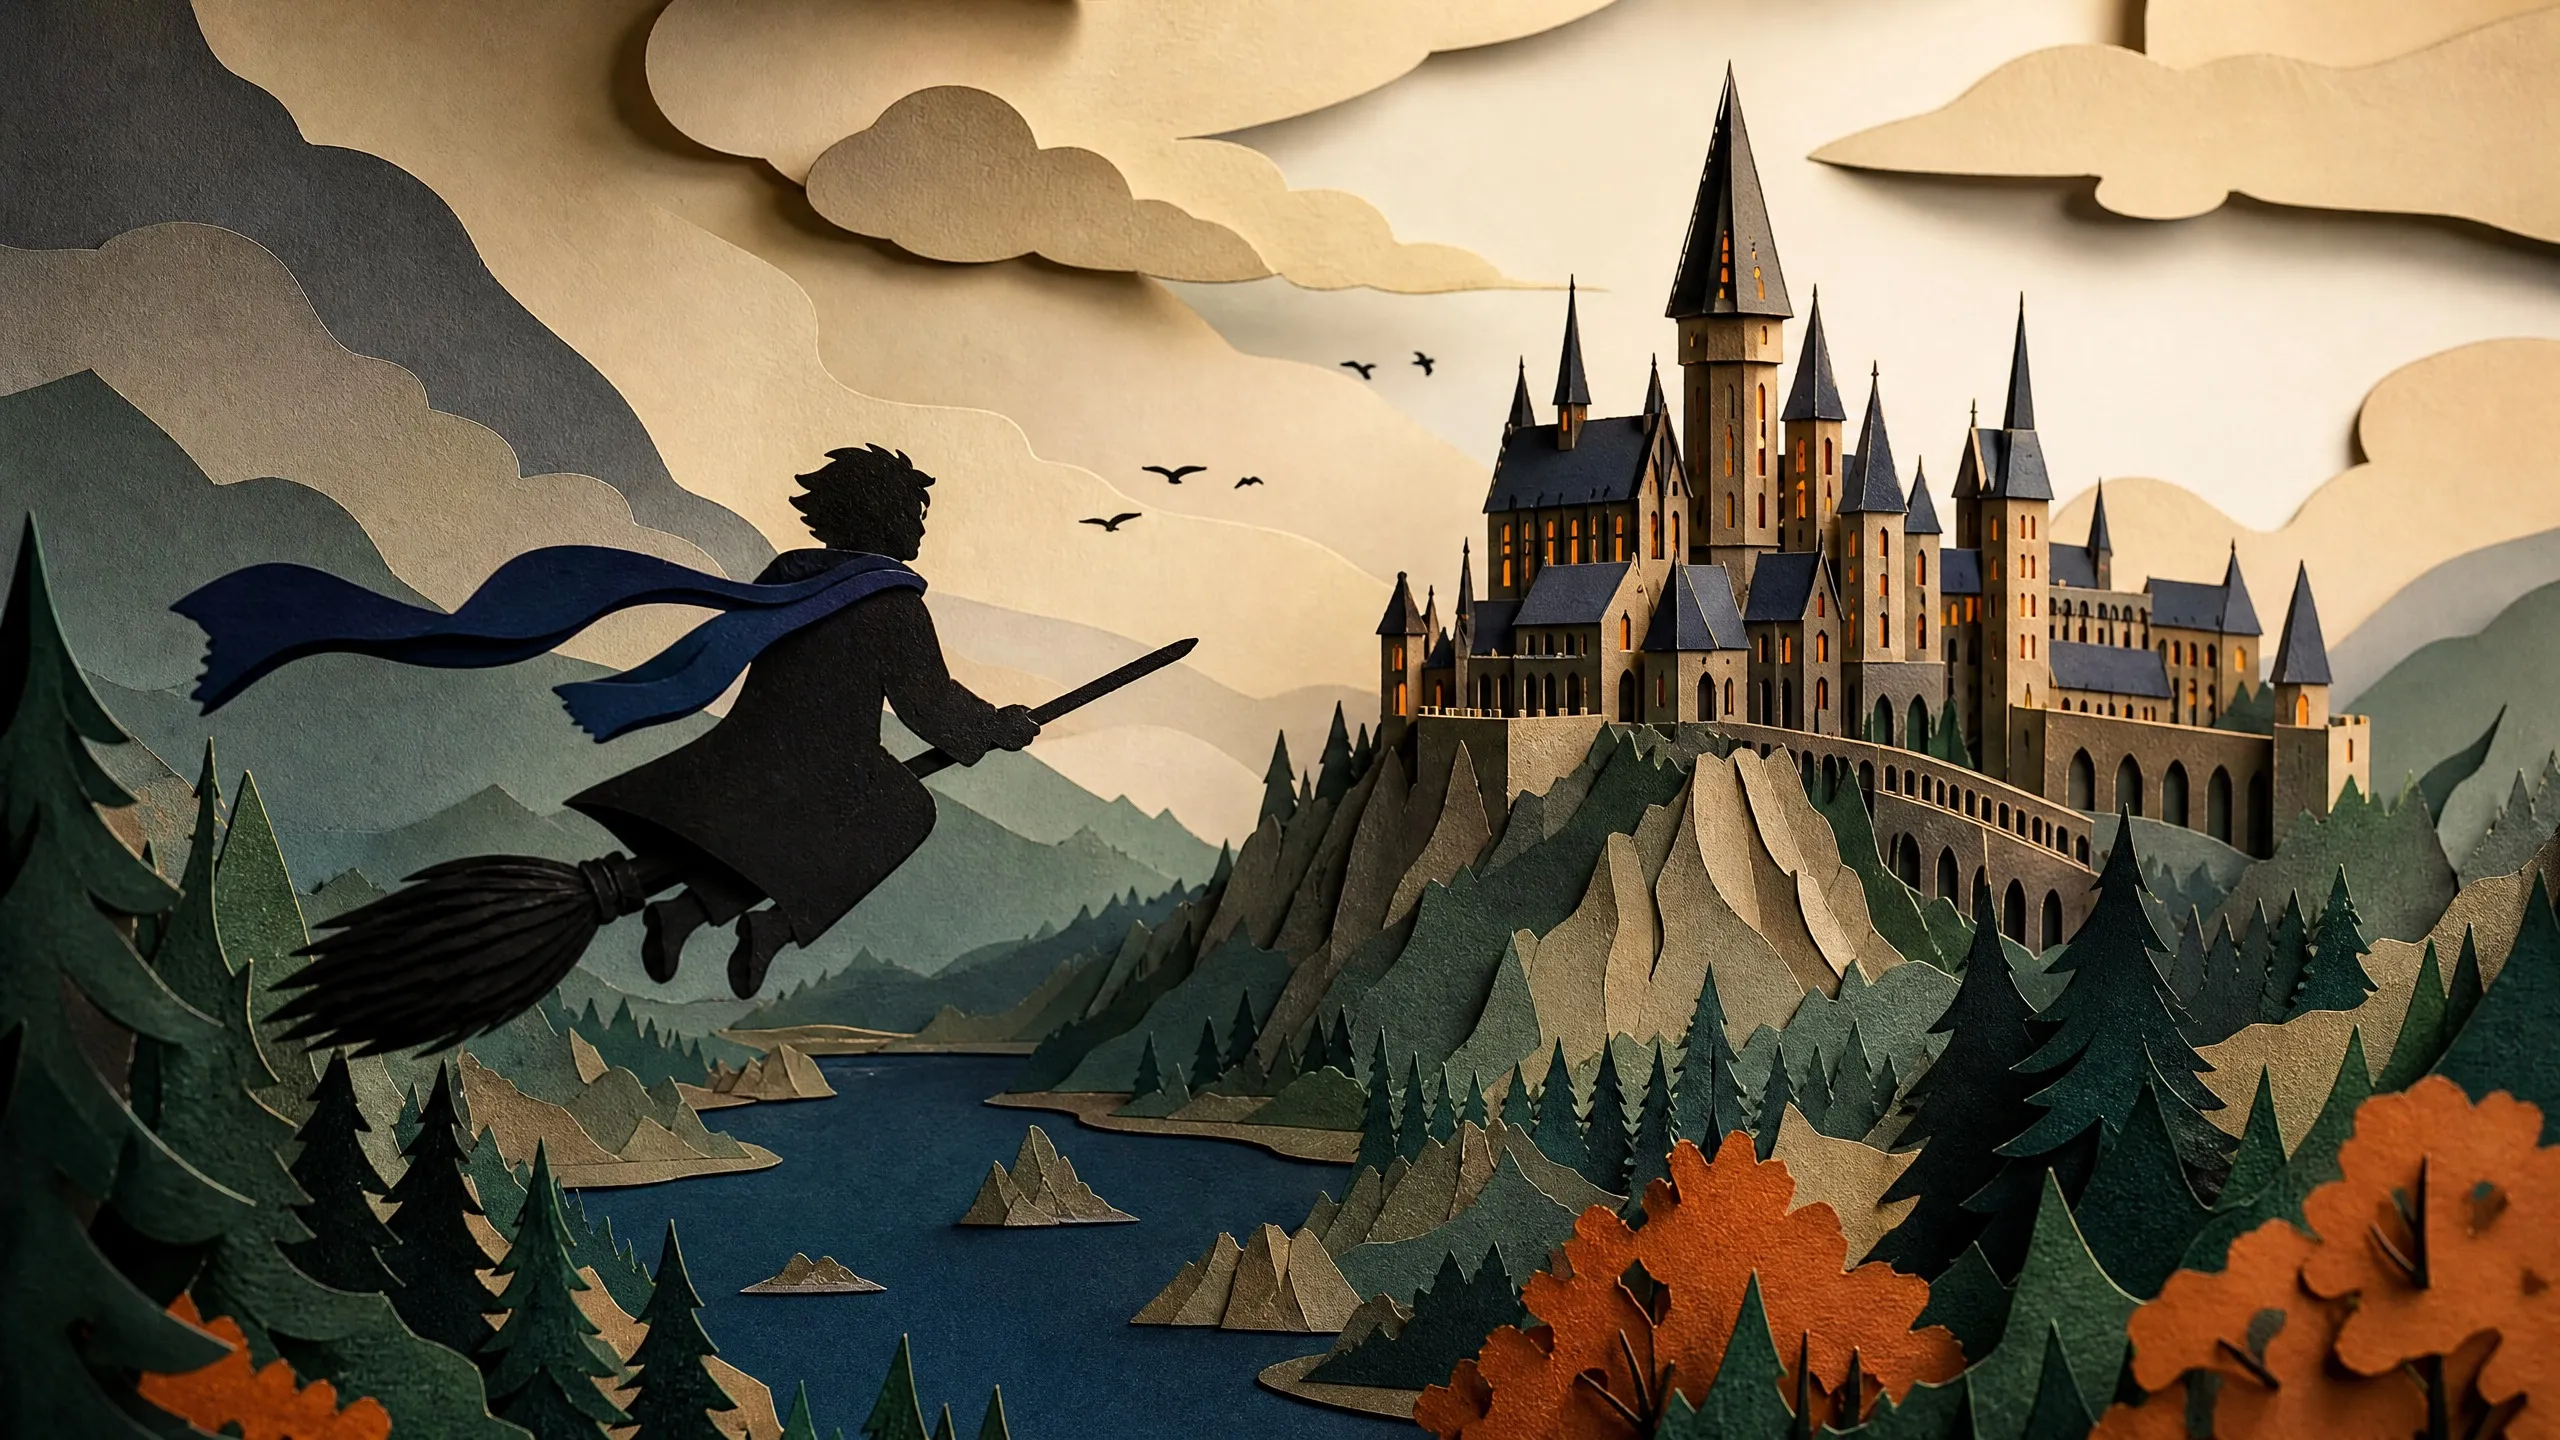
Hogwarts Broom Flight Simulator
Run date: 2026-09-07
Generation provenance: unrecorded
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Low-Poly Tower Defense
Run date: 2026-09-07
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
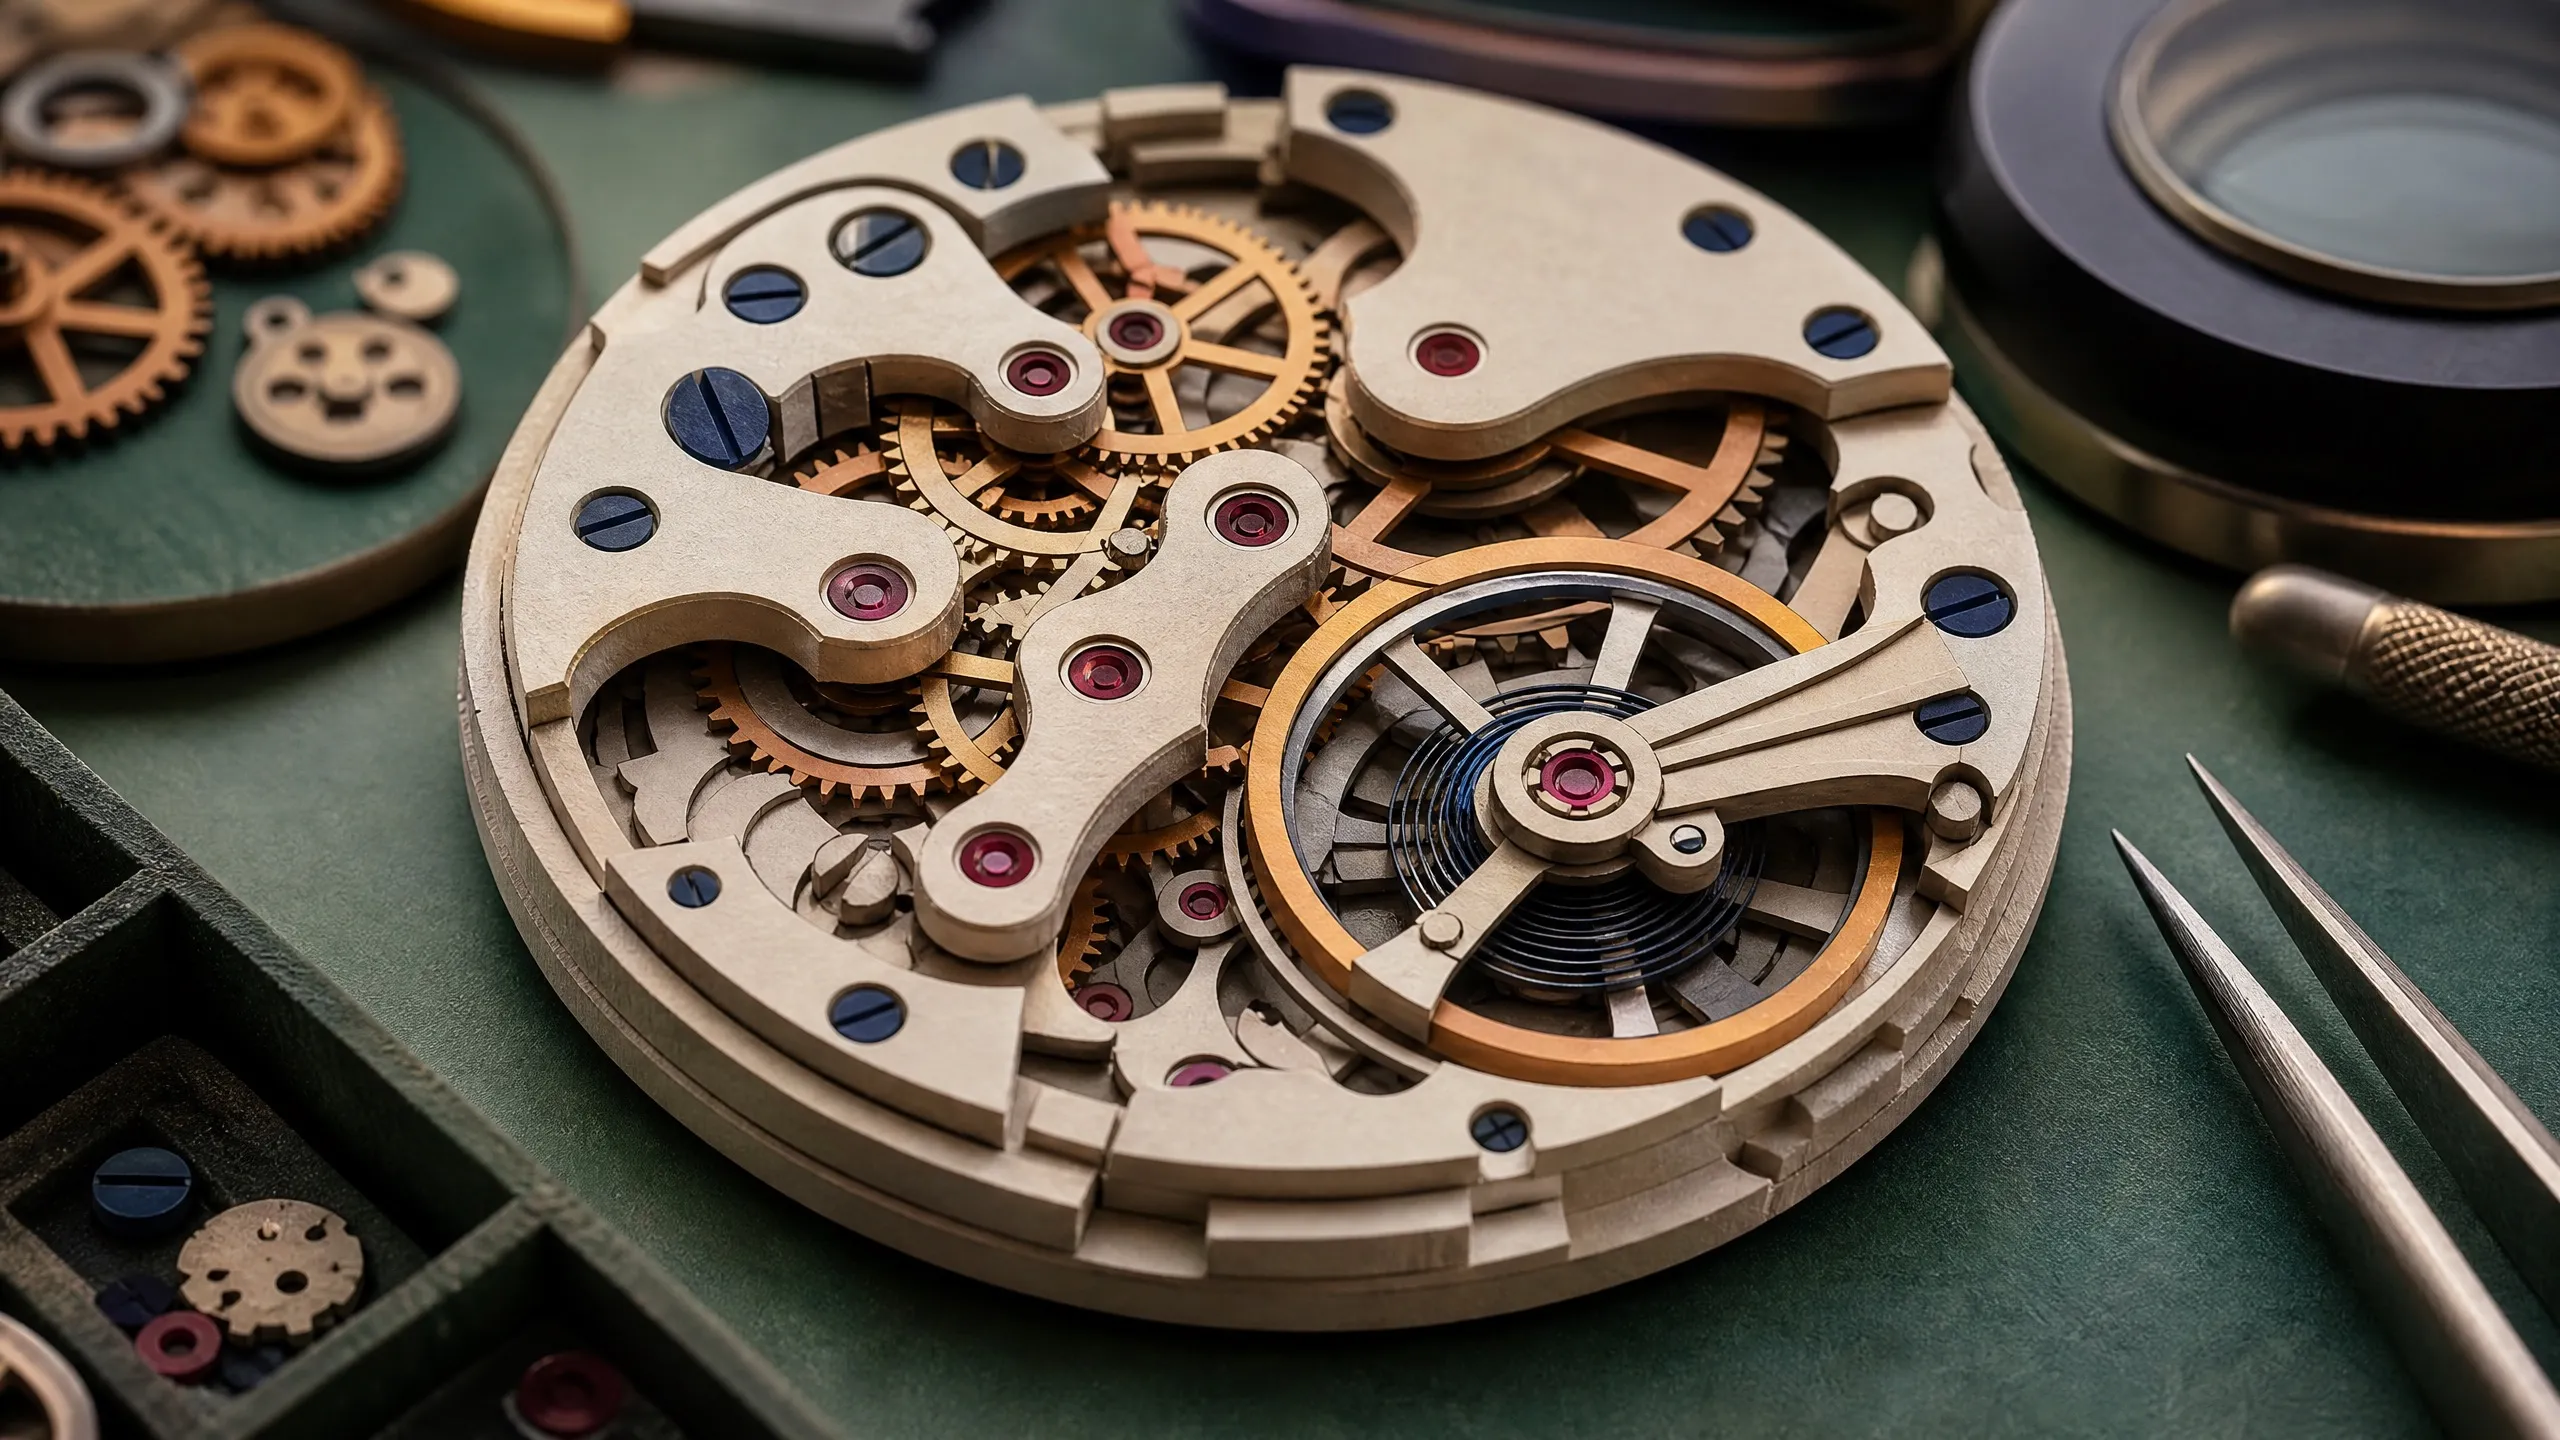
Mechanical Watch Simulator
Run date: 2026-09-07
Generation provenance: unrecorded
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.
Mechanical Watch Simulator
Run date: 2026-10-02
Generation provenance: unrecorded
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Run date: 2026-09-07
Generation provenance: unrecorded
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.
Neon Drift
Run date: 2026-10-02
Generation provenance: unrecorded
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-09-07
Generation provenance: unrecorded
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
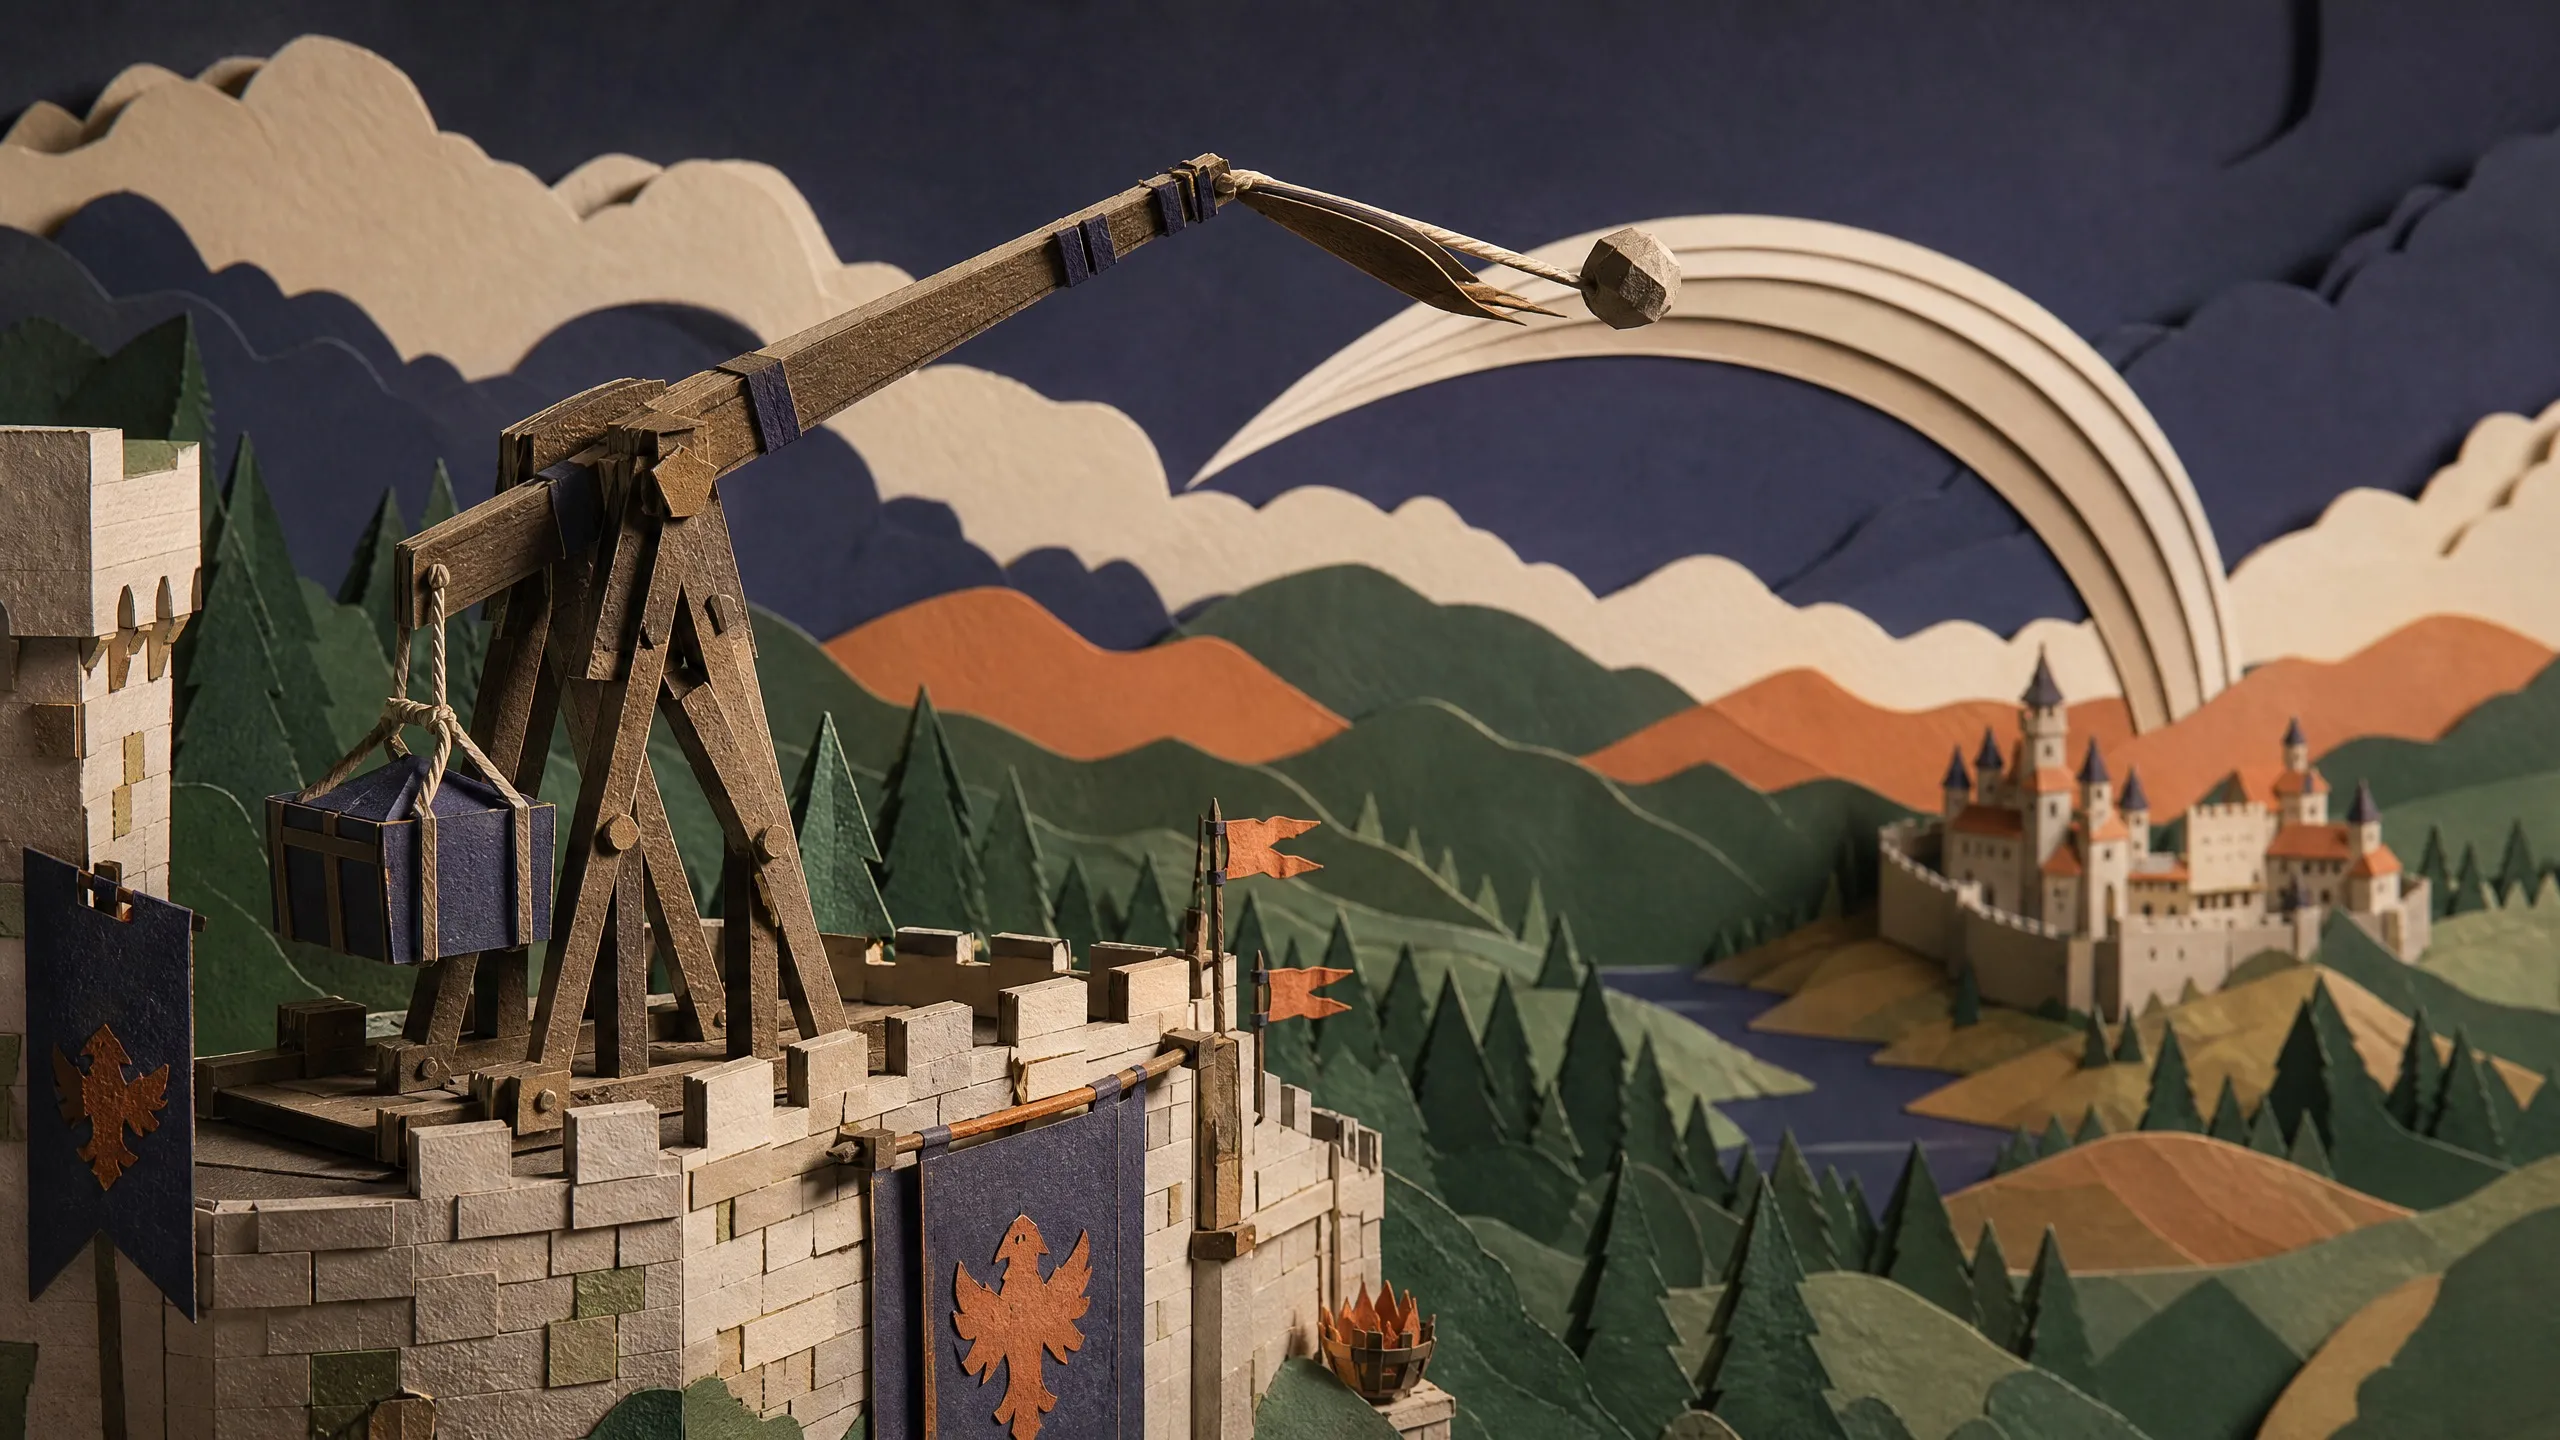
Stormwind Trebuchet Simulator
Run date: 2026-09-07
Generation provenance: unrecorded
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
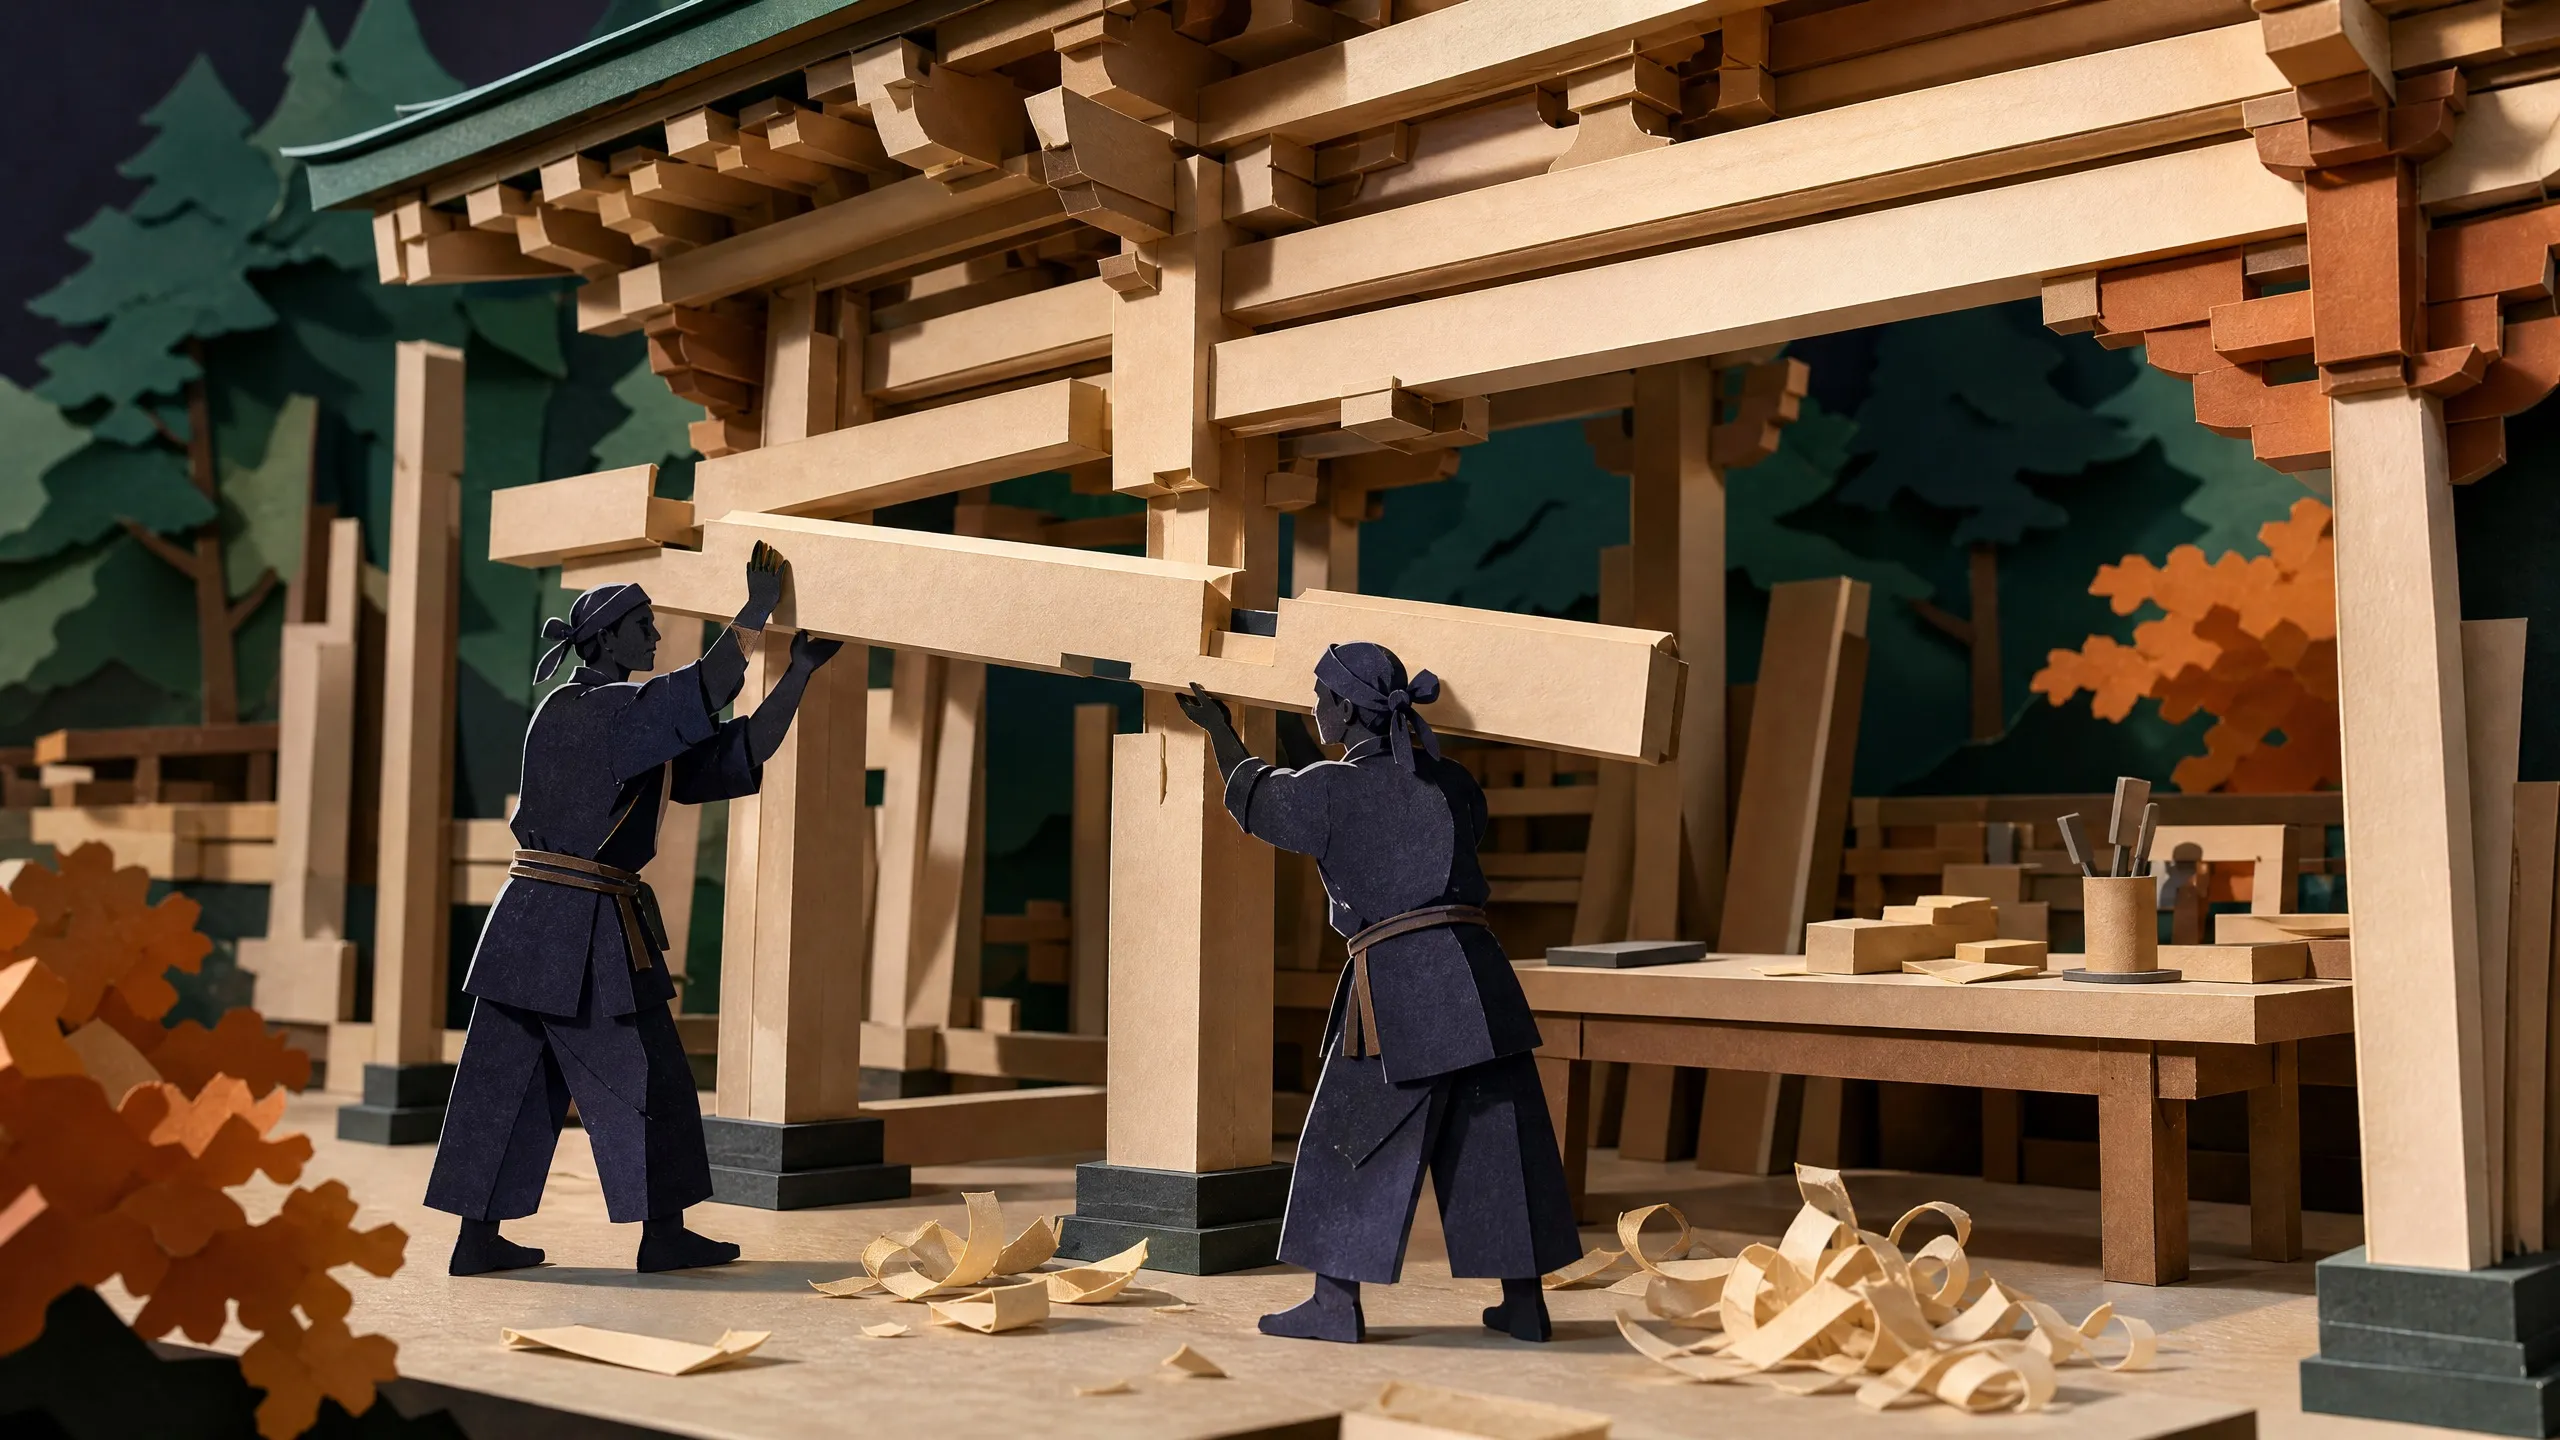
Yingzao Fashi Assembly
Run date: 2026-09-07
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Yingzao Fashi Assembly
Run date: 2026-10-02
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 7 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How GPT-6 Astra compares
Three relevant peers, side by side.
- GPT-6 Astra This model
- Claude Fable 5.1
- GPT-5.6 Sol
- Claude Opus 5
6 benchmarks · 4 models
Official benchmark profile
Astra’s published benchmark results
Full official benchmark table40 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| Terminal-Bench 4.0 | Coding | 57.9% | |
| Terminal-Bench Science 0.1 | Science | 64.6% | |
| AutomationBench | Automation | 41.4% | |
| Humanity’s Last Exam (with tools) | Reasoning | 57.2% | |
| Artificial Analysis Intelligence Index v4.1.1 | Reasoning | 61.2 | |
| FrontierMath Tier 4 (v2) | Reasoning | 97.6% | |
| DeepSWE v1.1 | Coding | 74.1% | |
| FrontierCode 1.1 Extended (score) | Coding | 64.5% | |
| FrontierCode 1.1 Main (score) | Coding | 53.3% | |
| GPQA Diamond | Science | 96.0% | |
| ARC-AGI-2 | Reasoning | 95.0% | |
| ARC-AGI-1 | Reasoning | 98.5% | |
| Agents’ Last Exam | Computer use | 59.3% | |
| OSWorld 2.0 · offline, v2026.08.08 | Computer use | 72.6% | |
| ScreenSpot-Pro (no tools) | Computer use | 92.7% | |
| BenchCAD (with tools) | Professional work | 95.9% | |
| BrowseComp | Research | 91.5% | |
| OpenScore String Quartets (1 − OMR-NED) | Professional work | 0.84 | |
| Design tasks (OpenAI internal) | Professional work | 50.0% | |
| Data science tasks (OpenAI internal) | Science | 40.9% | |
| Database migration (OpenAI internal) | Coding | 63.9% | |
| Artificial Analysis Coding Agent Index v1.4 | Coding | 67.0 | |
| GeneBench Pro | Science | 37.1% | |
| MedChemBench (OpenAI internal) | Science | 49.3% | |
| LifeSciBench | Science | 60.3% | |
| HealthBench Professional (length-adjusted) | Science | 63.4% | |
| ExploitBench | Cybersecurity | 100.0% | |
| ExploitGym | Cybersecurity | 42.4% | |
| ExploitBench (June–August 2026) | Cybersecurity | 39.0% | |
| SRE-Bench (single attempt) | Cybersecurity | 88.0% | |
| SEC-Bench Pro | Cybersecurity | 85.4% | |
| Computer-use safety (OpenAI internal)Lower is better | Alignment | 2.4% | |
| Computer-use safety with AutoReviewLower is better | Alignment | 1.8% | |
| Circumvention (OpenAI internal)Lower is better | Alignment | 0.0% | |
| ExploitGym honeypotLower is better | Alignment | 0.0% | |
| Impossible ExploitGym | Alignment | 100.0% | |
| Hallucination (OpenAI internal)Lower is better | Alignment | 4.2% | |
| MRCR v2 · 8 needles · 256K–512K | Long context | 100.0% | |
| MRCR v2 · 8 needles · 512K–1M | Long context | 96.3% | |
| ARC-AGI-3 | Reasoning | 99.9% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
gpt-6-astra- Context
- 1.05M
- Max output
- 128K
- License
- Not publicly verified
- Access route
- OpenAI API; rolling out through ChatGPT and Codex, Microsoft Azure, and AWS Bedrock. Access depends on account and rollout. The September 7 visual benchmarks used Codex subagents; API prices are not the recorded cost of those runs.
- Modalities
- text input, image input, text output
- Hardware
- Not publicly verified
- OpenAI API Standard (≤272K input tokens) · USD / 1M tokens
- $10 input · $1 cached input · $12.5 cache write · $50 output
Above 272K input tokens, the full request costs $20 input, $2 cached input, $25 cache write, and $75 output per 1M tokens. Batch, Flex, Fast mode, and regional pricing differ.
Benchmark sources
Maximum reported score at any effort; research/API environments. A shared table does not guarantee identical harnesses, budgets, or safeguards.
OpenAI Astra launch comparison tableLocal visual runs and their validation records are separate from these provider-published scores.
Evaluation settings
- Maximum reported score at any effort; research/API environments. A shared table does not guarantee identical harnesses, budgets, or safeguards.
- Lower is better. Maximum reported score at any effort; research/API environments. A shared table does not guarantee identical harnesses, budgets, or safeguards.
- Terminal-Bench Science 0.1
- Anthropic reports standard error of about 3.5–4.5 points per model; small gaps may be noise.
- Artificial Analysis Intelligence Index v4.1.1
- Independent index as reproduced in OpenAI’s launch table; separate from the older v4.1 observations in the cost explorer.
- FrontierCode 1.1 Extended (score)
- Astra uses additional developer guidance about keeping code and tests scoped (source footnote 8).
- FrontierCode 1.1 Main (score)
- Astra uses additional developer guidance about keeping code and tests scoped (source footnote 8).
- OSWorld 2.0 · offline, v2026.08.08
- Partial score on the offline subset. Anthropic’s modified tasks and grading are incompatible; no Fable 5.1 value is supplied here.
- ScreenSpot-Pro (no tools)
- The source labels Mythos’s 87.3 as Fable 5 (footnote 17). It is excluded from the Fable column here because the model’s safeguards differ.
- BenchCAD (with tools)
- Claude results use three evaluation modifications. Scores shown for context; no direct gap is calculated.
- HealthBench Professional (length-adjusted)
- OpenAI re-evaluation with GPT-5.4 grading. Fable 5.1 uses Opus 5 fallback for refusals; not a standalone Fable result.
- ExploitBench
- Astra and Sol evaluated without production safeguards.
- ExploitGym
- The source’s Fable columns are Mythos 5.1 (30.4) and Mythos 5 (28.4), excluded here. Astra/Sol have no six-hour limit and no production safeguards. Not a production-model comparison.
- ExploitBench (June–August 2026)
- OpenAI internal set, without production safeguards. Sol’s 5.5 is affected by a 300-turn cap; source also reports 11.5 with fewer limits.
- SRE-Bench (single attempt)
- Cyber capability evaluation without production safeguards.
- Computer-use safety (OpenAI internal)
- Lower is better. Research harness without production confirmations; provider safeguards and tools still differ.
- ARC-AGI-3
- OpenAI Responses harness with two modified settings; see source footnote 1.
Comparison methodology
Maximum reported score at any effort; research/API environments. A shared table does not guarantee identical harnesses, budgets, or safeguards. Gaps describe reported scores, not statistical significance. Percentage bars run from 0 to 100; index bars use a 0–100 display scale.
- Terminal-Bench Science 0.1
- Anthropic reports standard error of about 3.5–4.5 points per model; small gaps may be noise.
- Artificial Analysis Intelligence Index v4.1.1
- Independent index as reproduced in OpenAI’s launch table; separate from the older v4.1 observations in the cost explorer.
- FrontierCode 1.1 Extended (score)
- Astra uses additional developer guidance about keeping code and tests scoped (source footnote 8).
- FrontierCode 1.1 Main (score)
- Astra uses additional developer guidance about keeping code and tests scoped (source footnote 8).
- OSWorld 2.0 · offline, v2026.08.08
- Partial score on the offline subset. Anthropic’s modified tasks and grading are incompatible; no Fable 5.1 value is supplied here.
- ScreenSpot-Pro (no tools)
- The source labels Mythos’s 87.3 as Fable 5 (footnote 17). It is excluded from the Fable column here because the model’s safeguards differ.
- BenchCAD (with tools)
- Claude results use three evaluation modifications. Scores shown for context; no direct gap is calculated.
- HealthBench Professional (length-adjusted)
- OpenAI re-evaluation with GPT-5.4 grading. Fable 5.1 uses Opus 5 fallback for refusals; not a standalone Fable result.
- ExploitBench
- Astra and Sol evaluated without production safeguards.
- ExploitGym
- The source’s Fable columns are Mythos 5.1 (30.4) and Mythos 5 (28.4), excluded here. Astra/Sol have no six-hour limit and no production safeguards. Not a production-model comparison.
- ExploitBench (June–August 2026)
- OpenAI internal set, without production safeguards. Sol’s 5.5 is affected by a 300-turn cap; source also reports 11.5 with fewer limits.
- SRE-Bench (single attempt)
- Cyber capability evaluation without production safeguards.
- Computer-use safety (OpenAI internal)
- Lower is better. Research harness without production confirmations; provider safeguards and tools still differ.
- ARC-AGI-3
- OpenAI Responses harness with two modified settings; see source footnote 1.
Editorial verdict
Where this model fits
GPT-6 Astra completed all 16 Superbash visual benchmark briefs in independent prompt-only runs. Every published artifact is linked from the benchmark page with its manifest and validation record. S tier reflects the completed, inspectable run set and the editorial assessment of Astra as the strongest current choice for difficult multi-step product work; it is not a numeric leaderboard claim.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: GPT-6 Astra is currently placed in Tier S.
The November 2026 editorial roster places GPT-6 Astra at rank 1.
Open source →Superbash visual benchmark suite: GPT-6 Astra
Takeaway: All 16 prompt-only Astra runs are published with manifests, artifact hashes, and validation records.
The methodology record describes how the local runs were isolated and validated; it is evidence of this site’s visual suite, not a provider benchmark or independent universal score.
Open source →Related guides