
SpaceXAI
Grok 4.7
A-tier price-performance candidate for long-running coding and knowledge work, with the published historical 01–16 Superbash visual suite.
API pricing
USD per million tokens · xAI API (<200K prompt tokens)- Input
- $2
- Output
- $6
- Cached input
- $0.5
- Context window
- 500K
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-09-22
Specialist test · evaluated separately
Generation provenance: unrecorded
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Run date: 2026-09-22
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
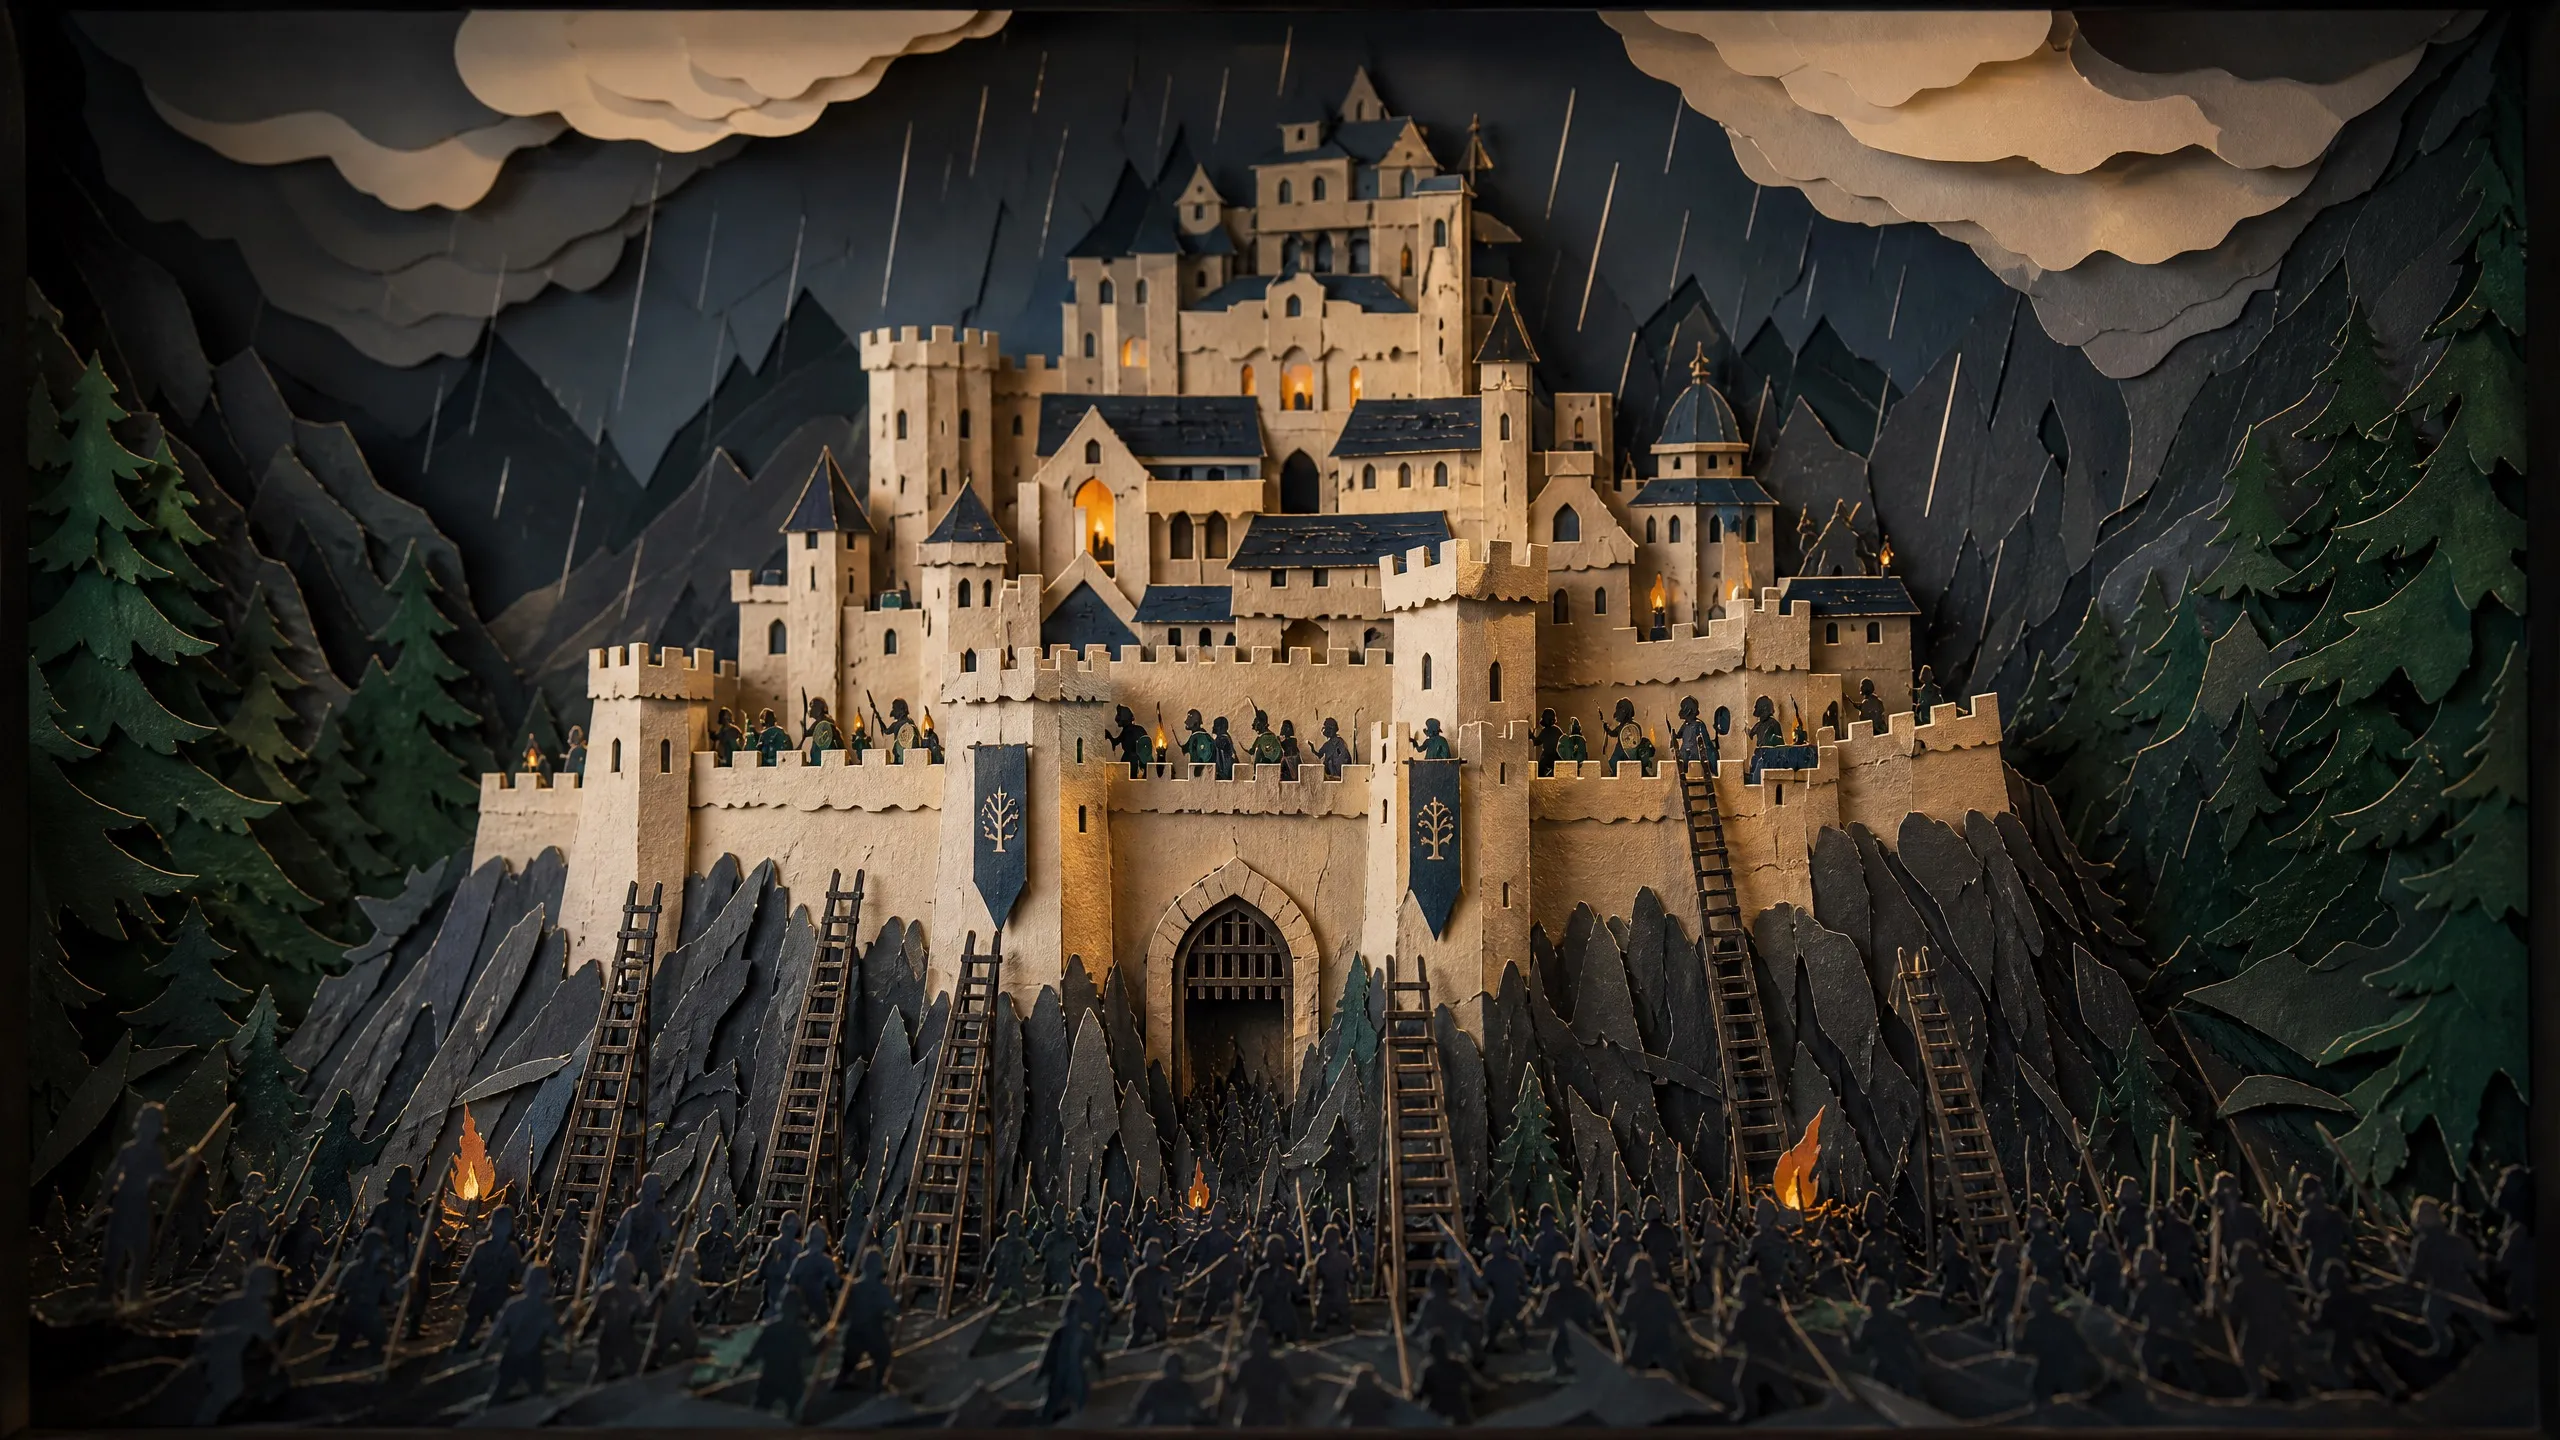
Helm's Deep
Run date: 2026-09-22
Generation provenance: unrecorded
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
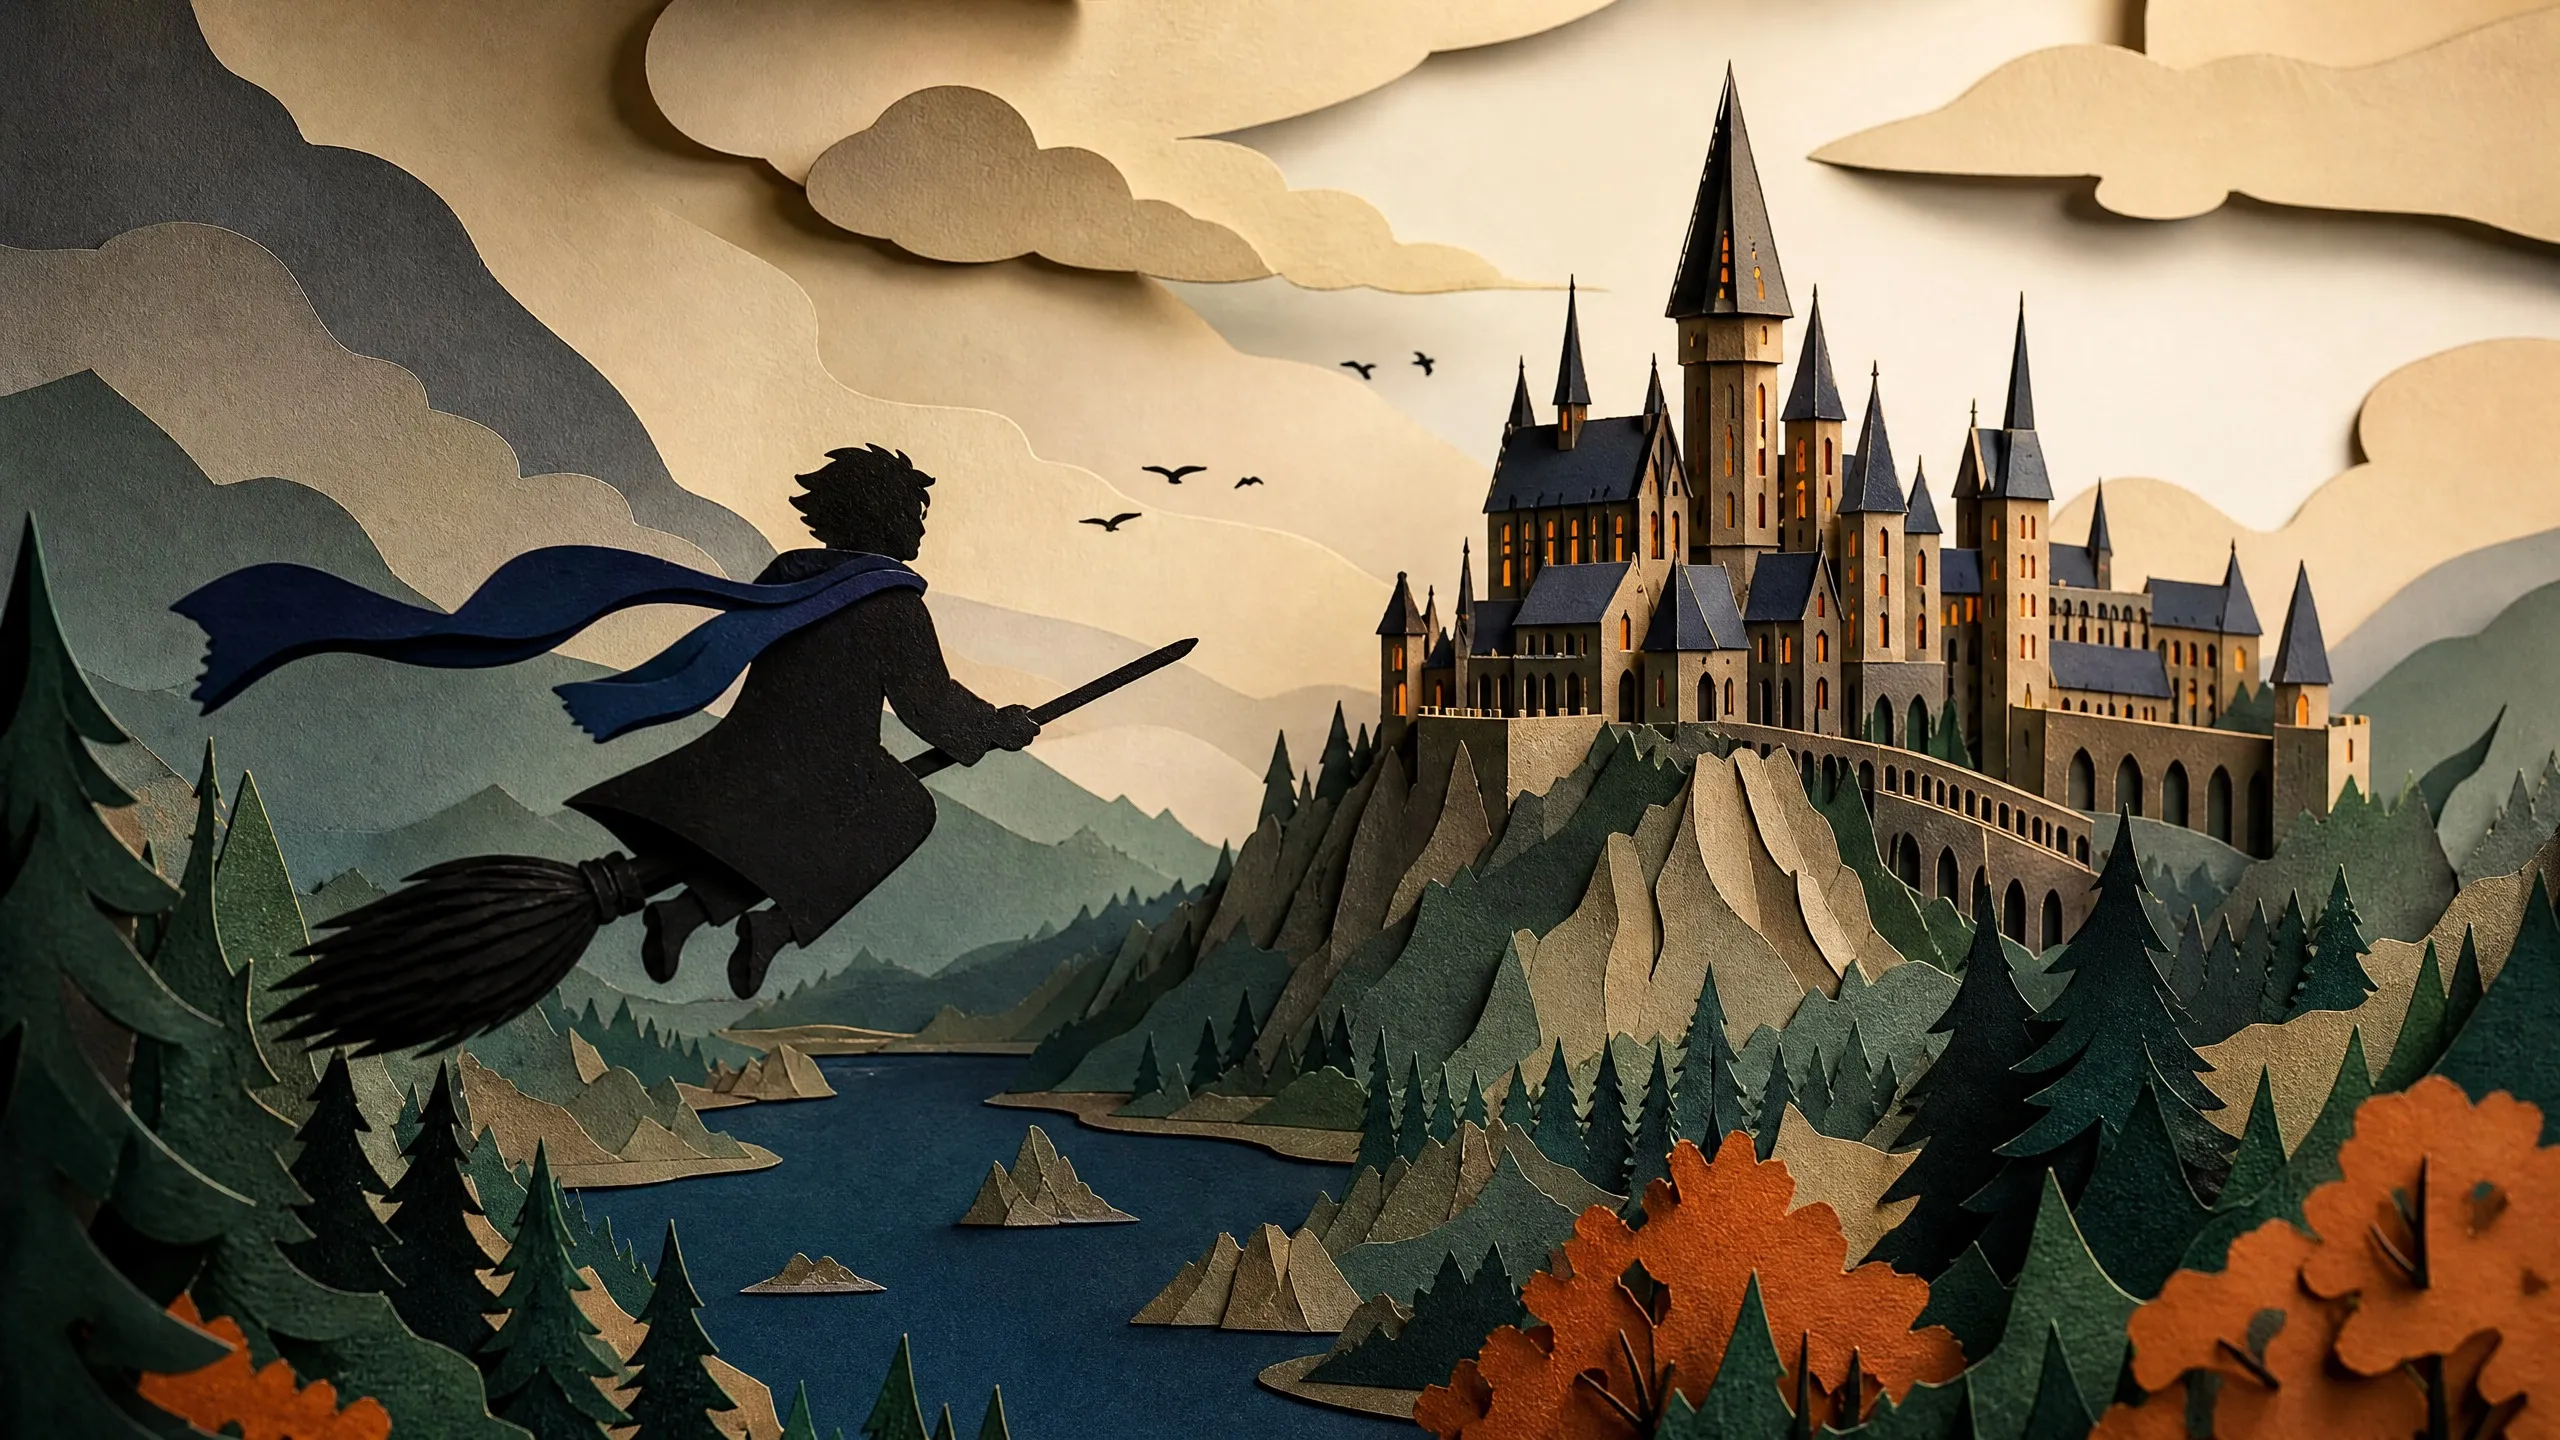
Hogwarts Broom Flight Simulator
Run date: 2026-09-22
Generation provenance: unrecorded
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Low-Poly Tower Defense
Run date: 2026-09-22
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
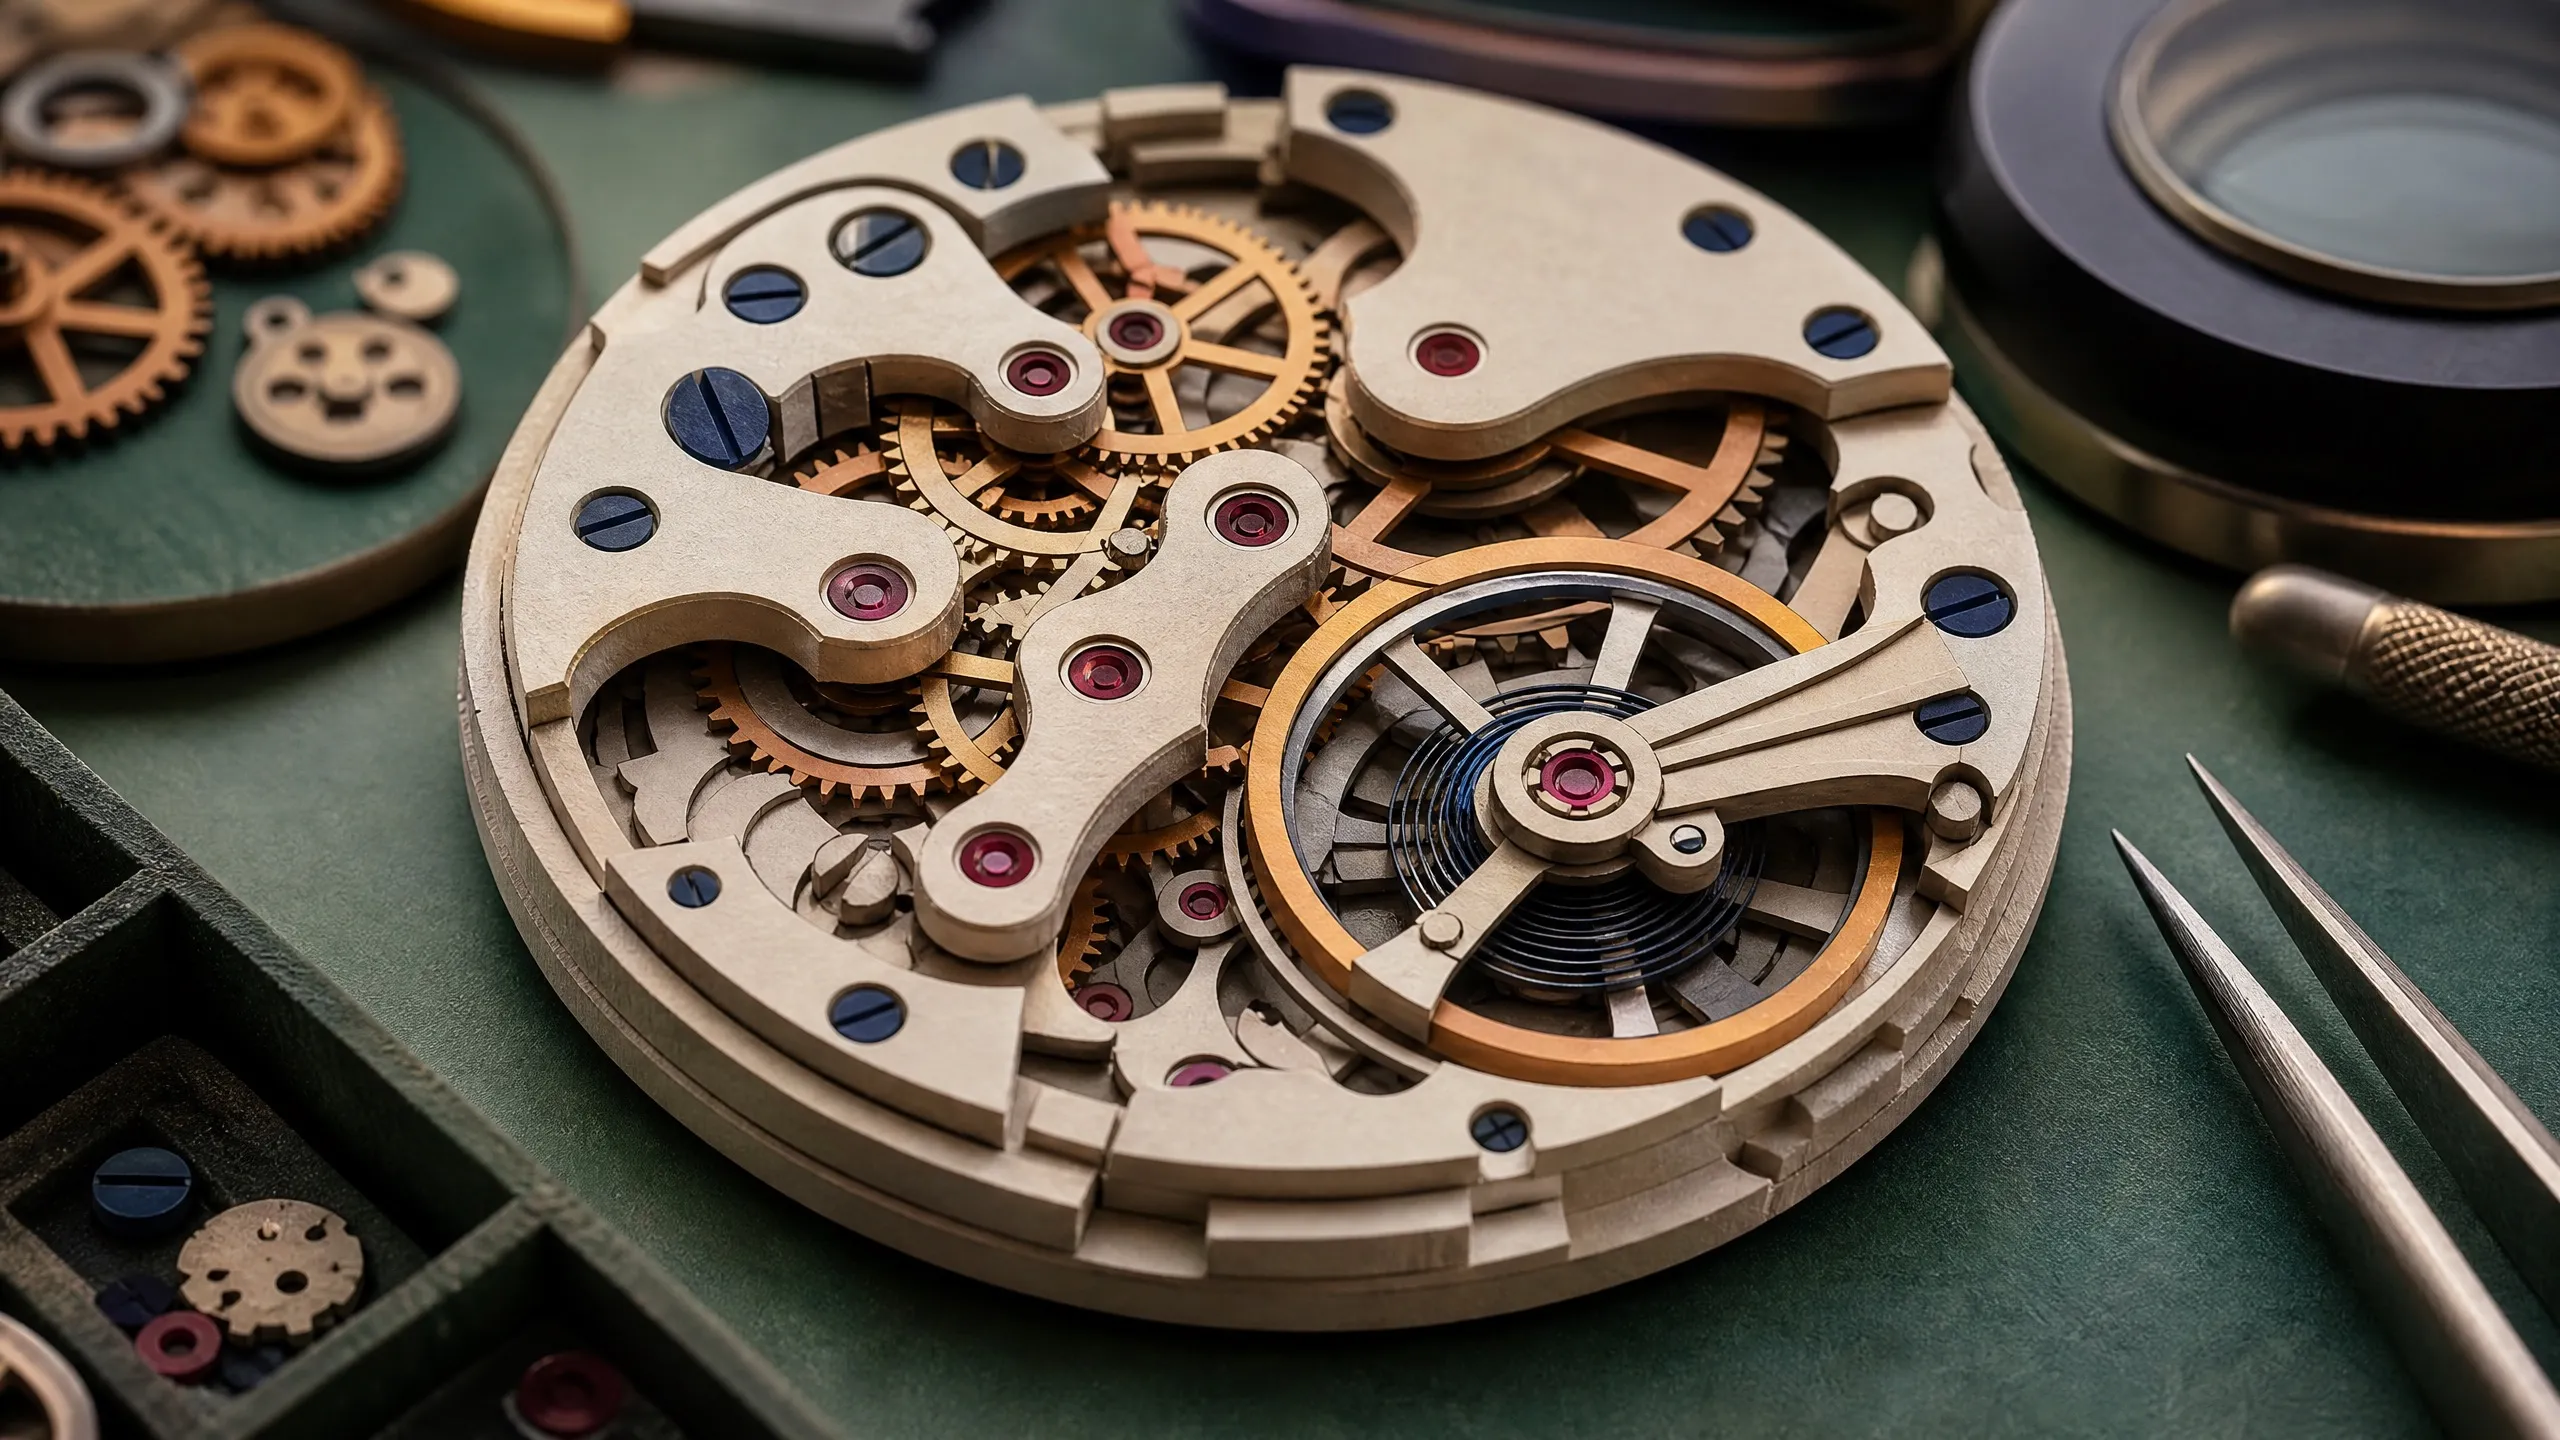
Mechanical Watch Simulator
Run date: 2026-09-22
Generation provenance: unrecorded
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Run date: 2026-09-22
Generation provenance: unrecorded
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-09-22
Generation provenance: unrecorded
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
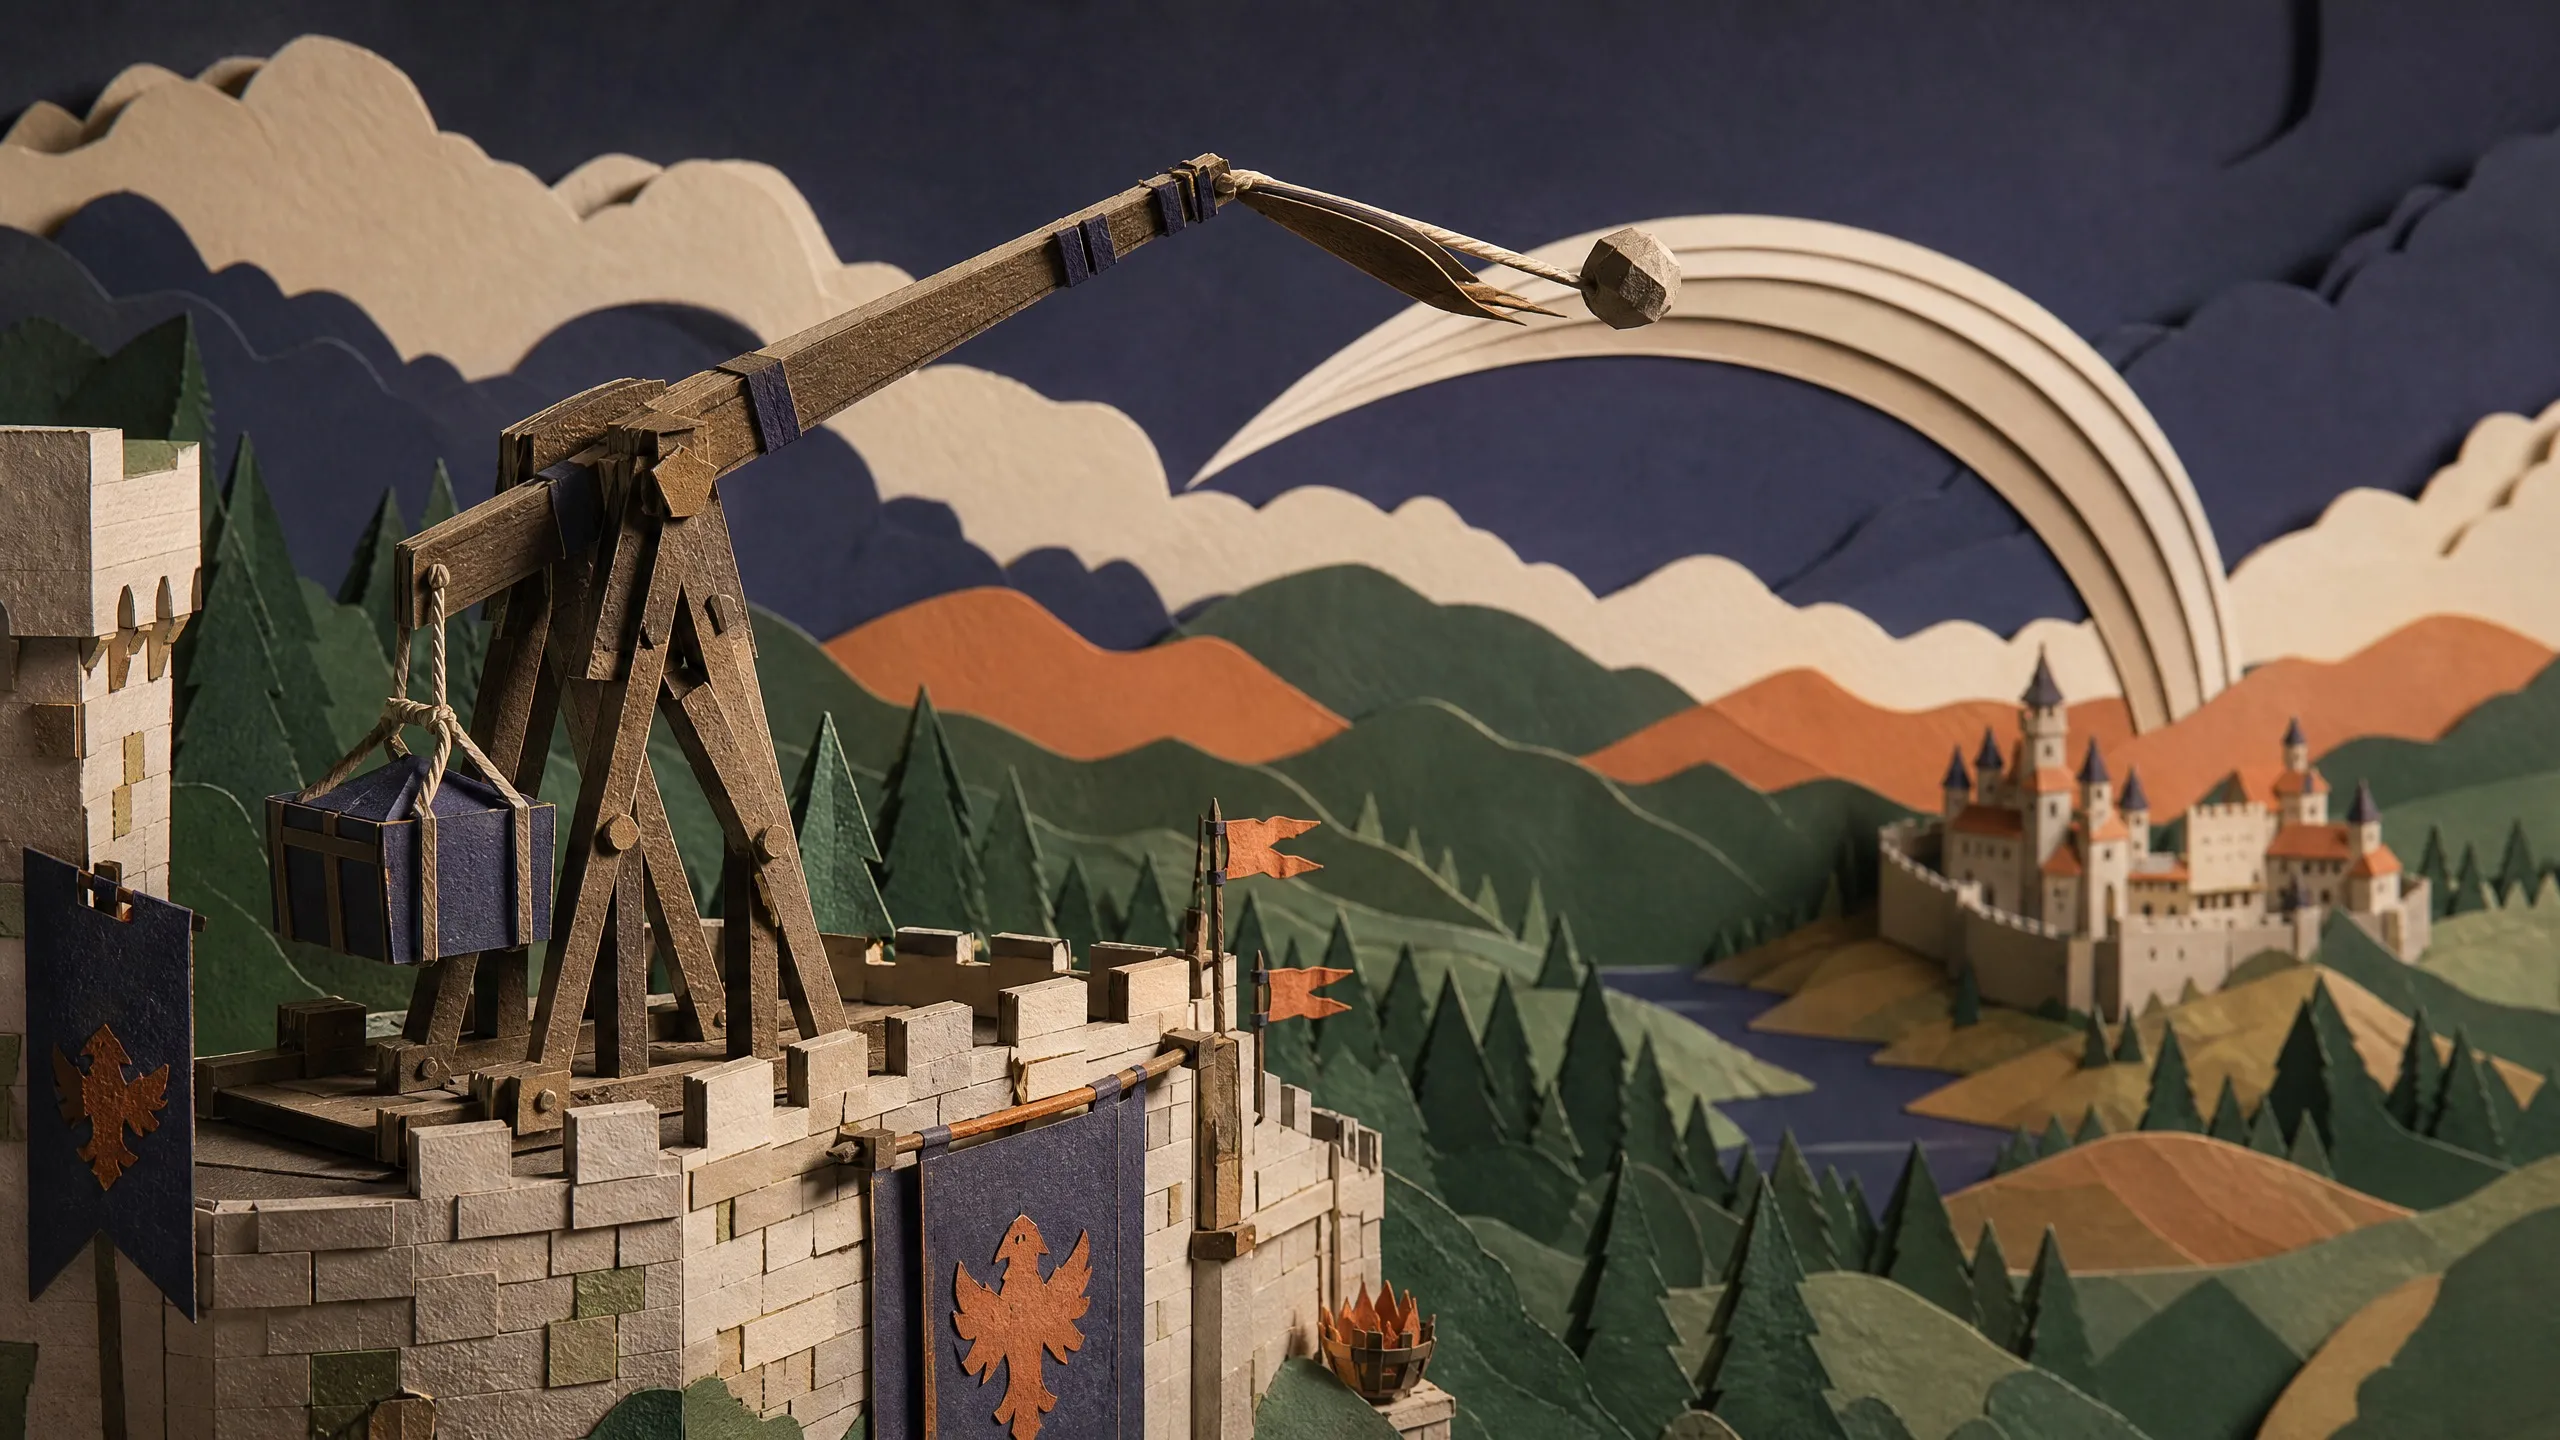
Stormwind Trebuchet Simulator
Run date: 2026-09-22
Generation provenance: unrecorded
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
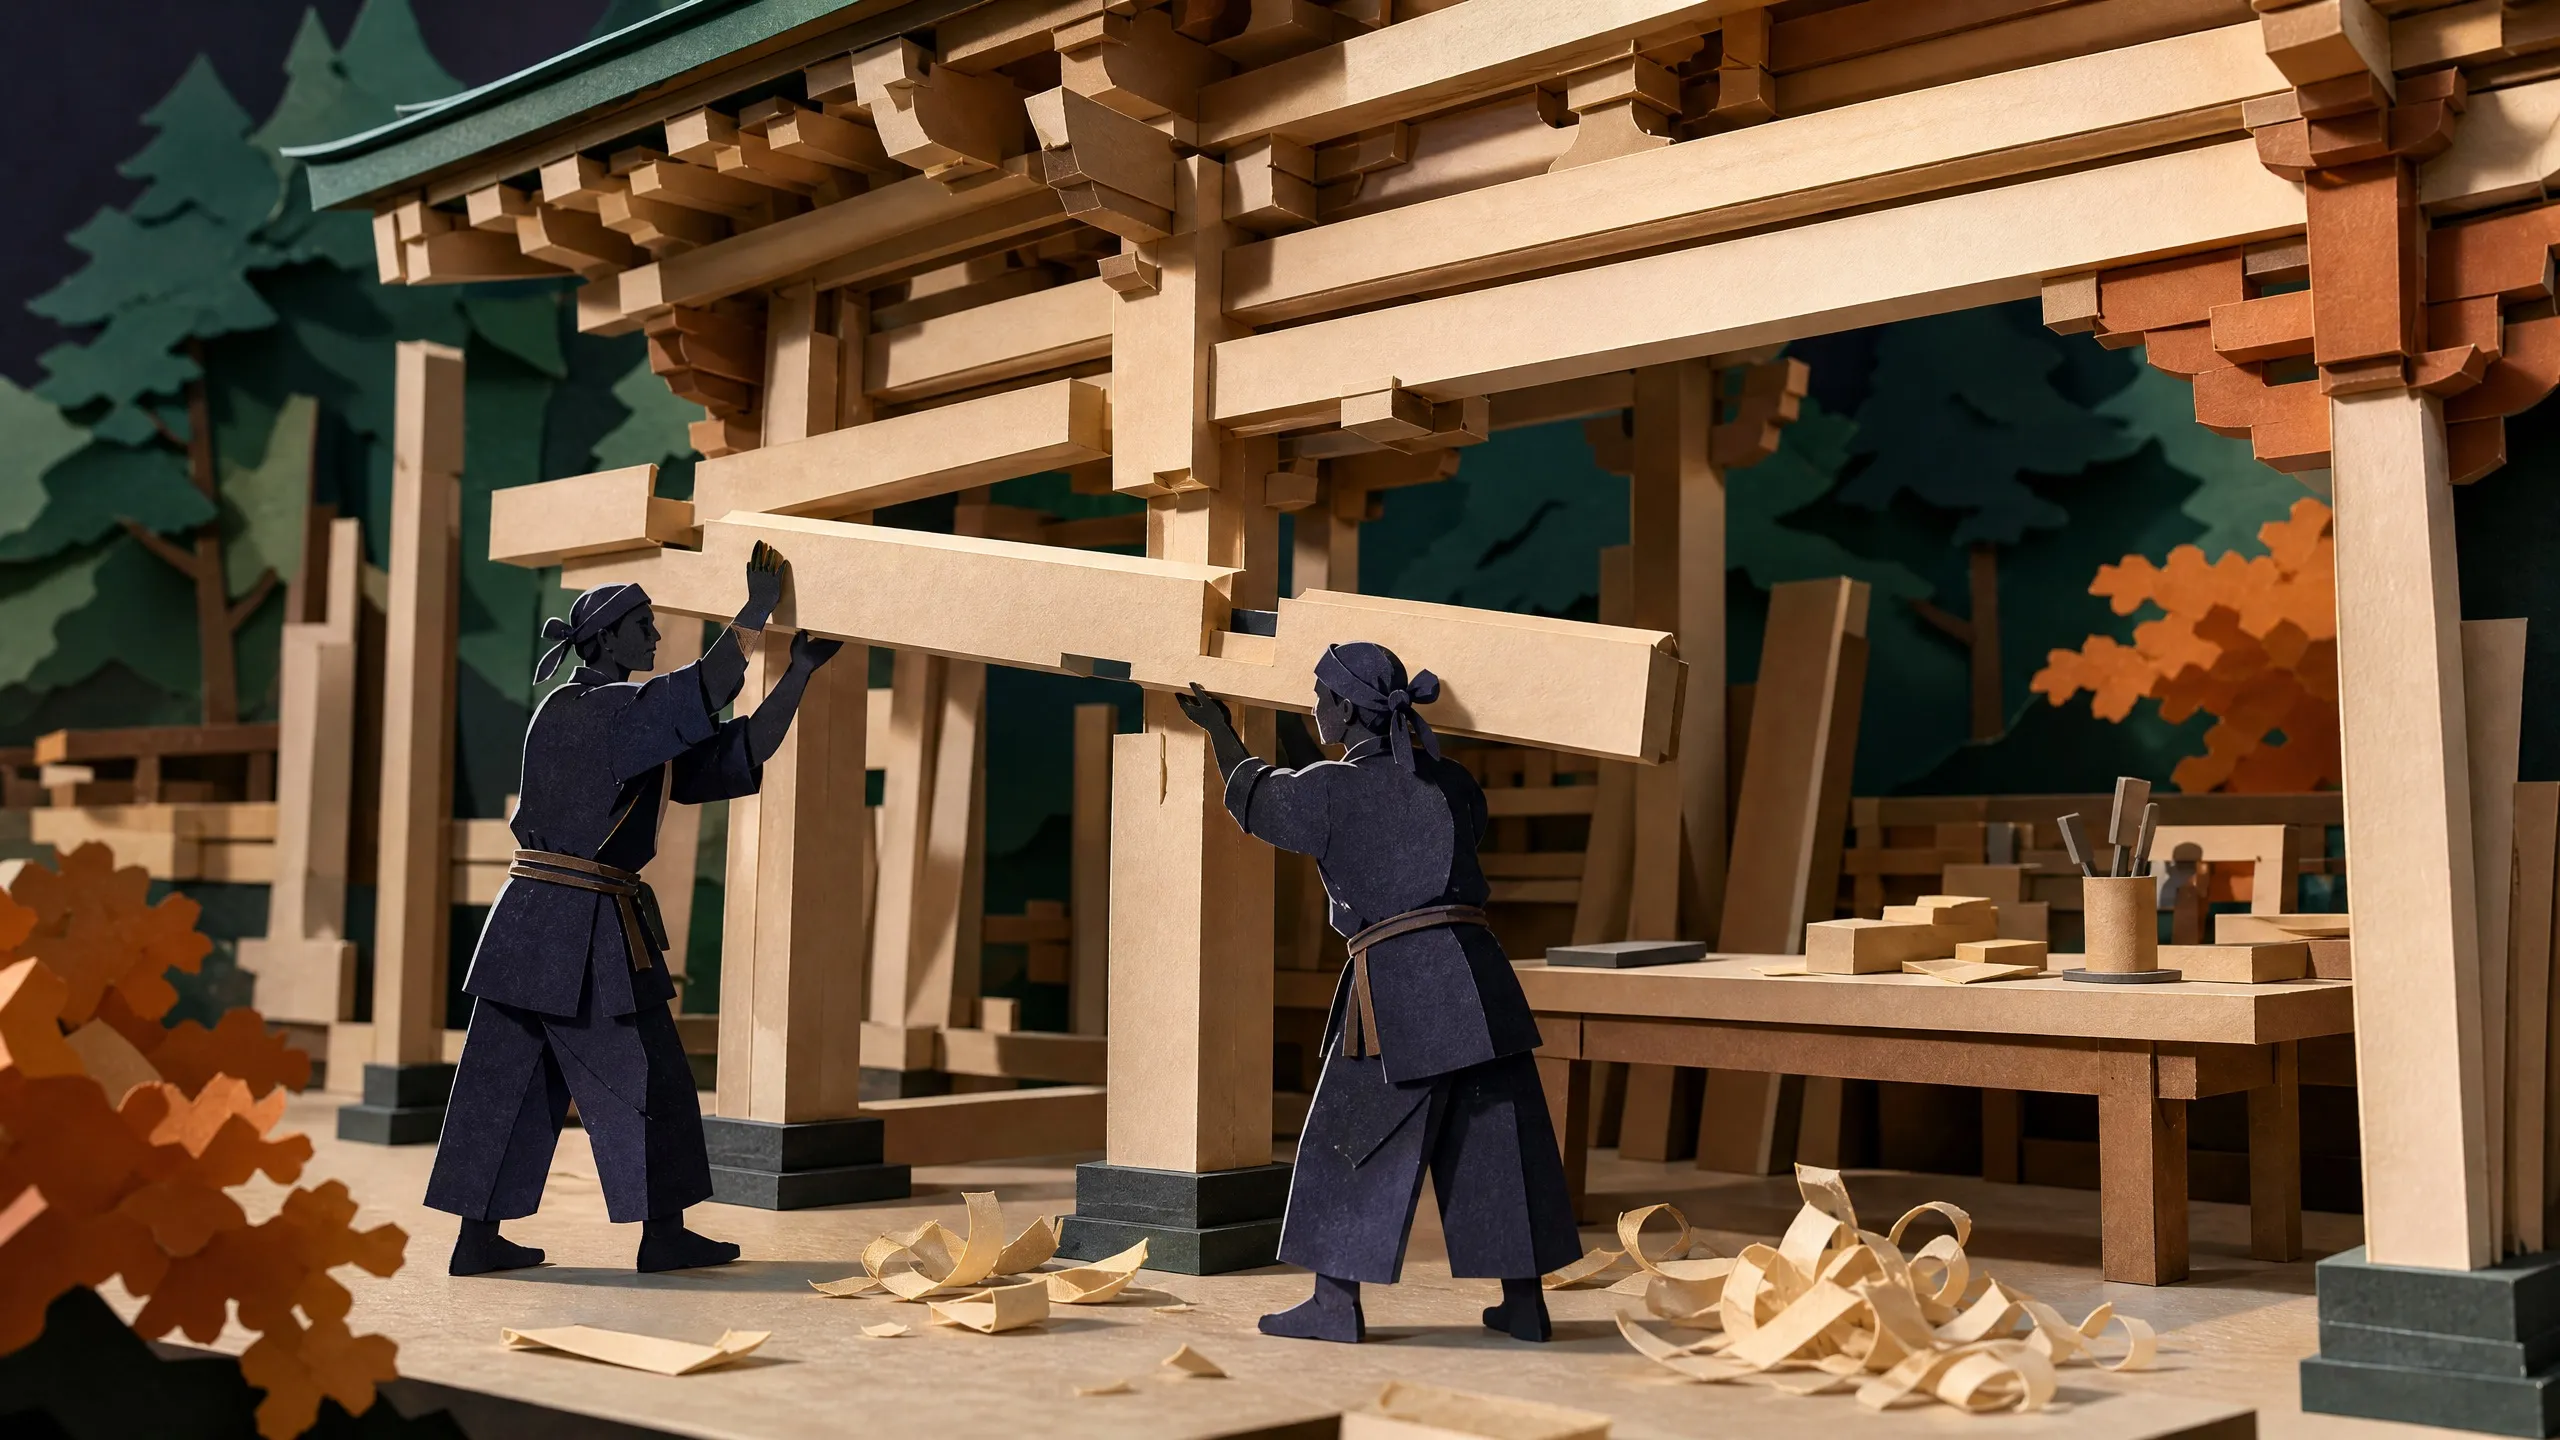
Yingzao Fashi Assembly
Run date: 2026-09-22
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
Archived model versions
The latest Grok 4.7 runs are shown above. Earlier versions are preserved separately and are not counted in this current run set.
How Grok 4.7 compares
Three relevant peers, side by side.
- Grok 4.7 This model
- Fable 5.1 max
- GPT-5.6 Sol max
- Grok 4.6 high
6 benchmarks · 4 models
Official benchmark profile
Grok 4.7’s published long-horizon coding and knowledge-work results.
CursorBench 4.0
46.3%DeepSWE v1.1
71.0%EEBench
64.0%Full official benchmark table9 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| CursorBench 4.0 | Software engineering | 46.3% | |
| DeepSWE v1.1 | Software engineering | 71.0% | |
| EEBench | Electrical engineering | 64.0% | |
| AA Briefcase v1.1 | Multi-hour office work | 1,657 | |
| Terminal-Bench 4.0 | Multi-hour terminal work | 38.0% | |
| Harvey Legal Agent Benchmark | Legal work | 19.6% | |
| HealthBench Professional | Clinical reasoning | 56.7% | |
| LatchBio biosafety benchmark | Biosafety | 62.4% | |
| HackerBench v0.3 risky prompts allowedLower is better | Cybersecurity safety | 3.3% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
grok-4.7- Context
- 500K
- Max output
- Not publicly verified
- License
- Not publicly verified
- Access route
- Public xAI API, Grok Build, Cursor, and supported model gateways. Grok 4.7 Fast is the same model on faster serving at twice the token rates; it is available only in Cursor and Grok Build, not through the public xAI API.
- Modalities
- text input, image input, text output
- Hardware
- Not publicly verified
- xAI API (<200K prompt tokens) · USD / 1M tokens
- $2 input · $0.5 cached input · $6 output
At 200K prompt tokens or more, all tokens in the request use $4 input, $1 cached input, and $12 output per 1M tokens. Grok 4.7 Fast costs twice the standard token rates and is not available on the public xAI API. The US regional endpoint adds a 10% premium.
Benchmark sources
SpaceXAI reports Grok 4.7 on seven coding, terminal, professional-work, health, and engineering evaluations. Superbash keeps these provider results separate from the published same-prompt visual runs.
Introducing Grok 4.7These are first-party launch-table values. Grok 4.7 uses xhigh effort except for the starred DeepSWE v1.1 result, which uses high effort; peer configurations are retained in the comparison labels.
Evaluation settings
- SpaceXAI launch-table result; Grok 4.7 xhigh.
- SpaceXAI launch-table result; Grok 4.7 high rather than xhigh.
- SpaceXAI launch-table rating; Grok 4.7 xhigh; higher is better.
- SpaceXAI-reported launch result for benign utility and safe refusal.
- SpaceXAI-reported launch result; lower is better for risky or malicious prompts allowed.
- DeepSWE v1.1
- The launch table marks only this Grok 4.7 score with an asterisk for high effort.
Editorial verdict
Where this model fits
Grok 4.7 is SpaceXAI's September flagship for coding, agentic tasks, and knowledge work. The launch data shows meaningful gains over 4.6 on long-running coding, terminal, engineering, and professional-work evaluations at the same standard API price. All 16 same-prompt Superbash visual runs are published and stay separate from those first-party scores.
Best for
Watch out
Ranking rationale and evidence
Evidence
Superbash editorial model ranking
Takeaway: Grok 4.7 is currently placed in Tier A.
The November 2026 editorial roster places Grok 4.7 at rank 4.
Open source →Introducing Grok 4.7
Takeaway: Grok 4.7 replaces 4.6 in the current editorial roster, with its first-party scores kept separate from the visual benchmark suite.
SpaceXAI publishes the launch configuration and peer table. The Superbash visual runs are a separate, same-prompt evidence layer.
Open source →Related guides