Xai
Grok 4.5
Version 4.5 benchmark runs across the shared Superbash visual prompts.
API pricing
USD per million tokens · xAI API (<200K input tokens)- Input
- $2
- Output
- $6
- Cached input
- $0.3
- Context window
- 500K
Inspect the original visual runs
Open the generated scene to test it, or compare that prompt with another model.
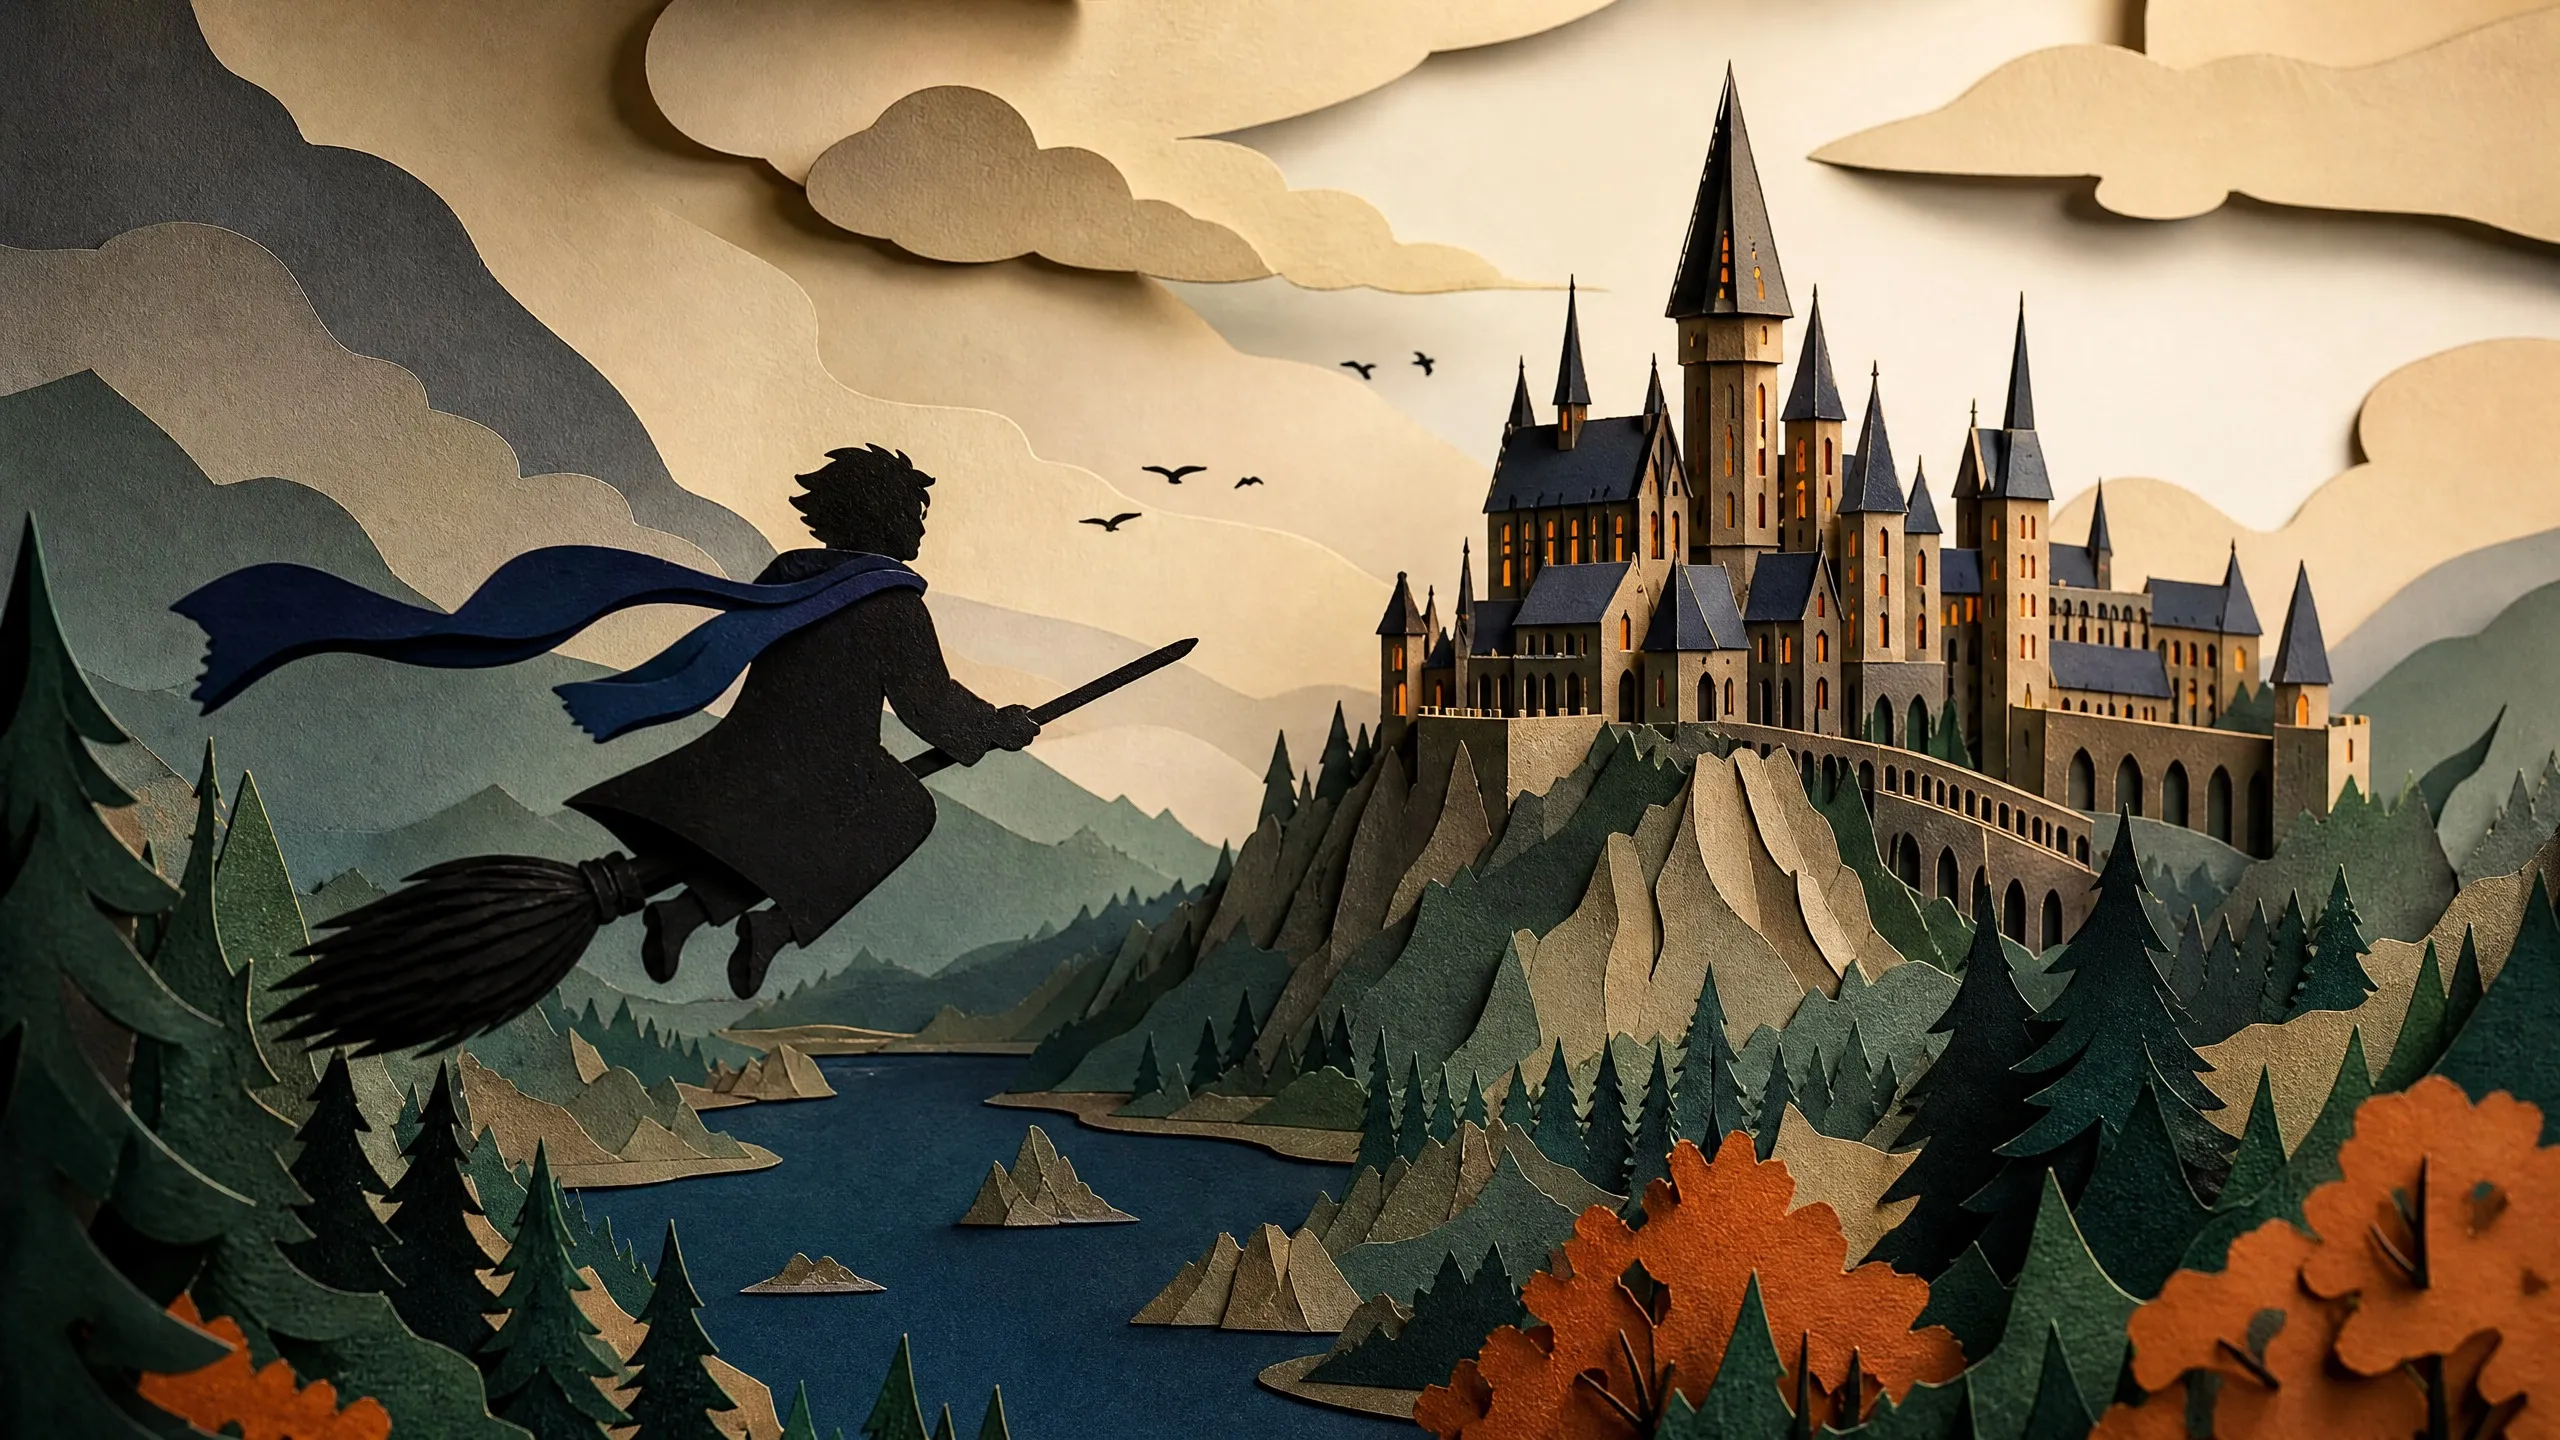
Hogwarts Broom Flight Simulator
Run date: 2026-07-09
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
Official benchmark profile
Published scores outside our visual tests
SpaceXAI sourceJuly 2026Source report →
DeepSWE 1.0
62.0%DeepSWE 1.1
53.0%SWE Marathon
29.0%Full official benchmark table6 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| DeepSWE 1.0 | Coding | 62.0% | |
| DeepSWE 1.1 | Coding | 53.0% | |
| SWE Marathon | Long-horizon coding | 29.0% | |
| SWE Bench Pro output tokens | Efficiency | 15,954 avg. | |
| Output-token efficiency | Efficiency | 4.2x fewer than Opus 4.8 | |
| Serving speed | Latency | 80 TPS |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Superseded in this ranking
- API model ID
grok-4.5- Context
- 500K
- Max output
- Not publicly verified
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- xAI API (<200K input tokens) · USD / 1M tokens
- $2 input · $0.3 cached input · $6 output
At 200K input tokens or more, all tokens in the request use $4 input, $0.6 cached input, and $12 output per 1M tokens.
Benchmark sources
xAI describes Grok 4.5 as a coding, agentic-task, and knowledge-work model. xAI publishes different benchmark rows than OpenAI/Anthropic, so only direct source comparisons are shown.
Introducing Grok 4.5Evaluation settings
- xAI reported software-engineering benchmark.
- xAI reported long-horizon coding benchmark.
- Average output tokens on SWE Bench Pro tasks.
- xAI comparison on SWE Bench Pro tasks.
- Reported generation speed.
- Output-token efficiency
- xAI compares Grok 4.5 against Opus 4.8 max on SWE Bench Pro tasks.