
Z.ai
GLM 5.3 Flash
An A-tier efficiency build: the full 16-prompt visual set delivered at a fraction of frontier cost.
API pricing
USD per million tokens · Z.ai API promotional rate- Input
- $0.075
- Output
- $0.25
- Cached input
- $0.015
- Context window
- 1M
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-08-28
Specialist test · evaluated separately
Generation provenance: unrecorded
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Run date: 2026-08-28
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
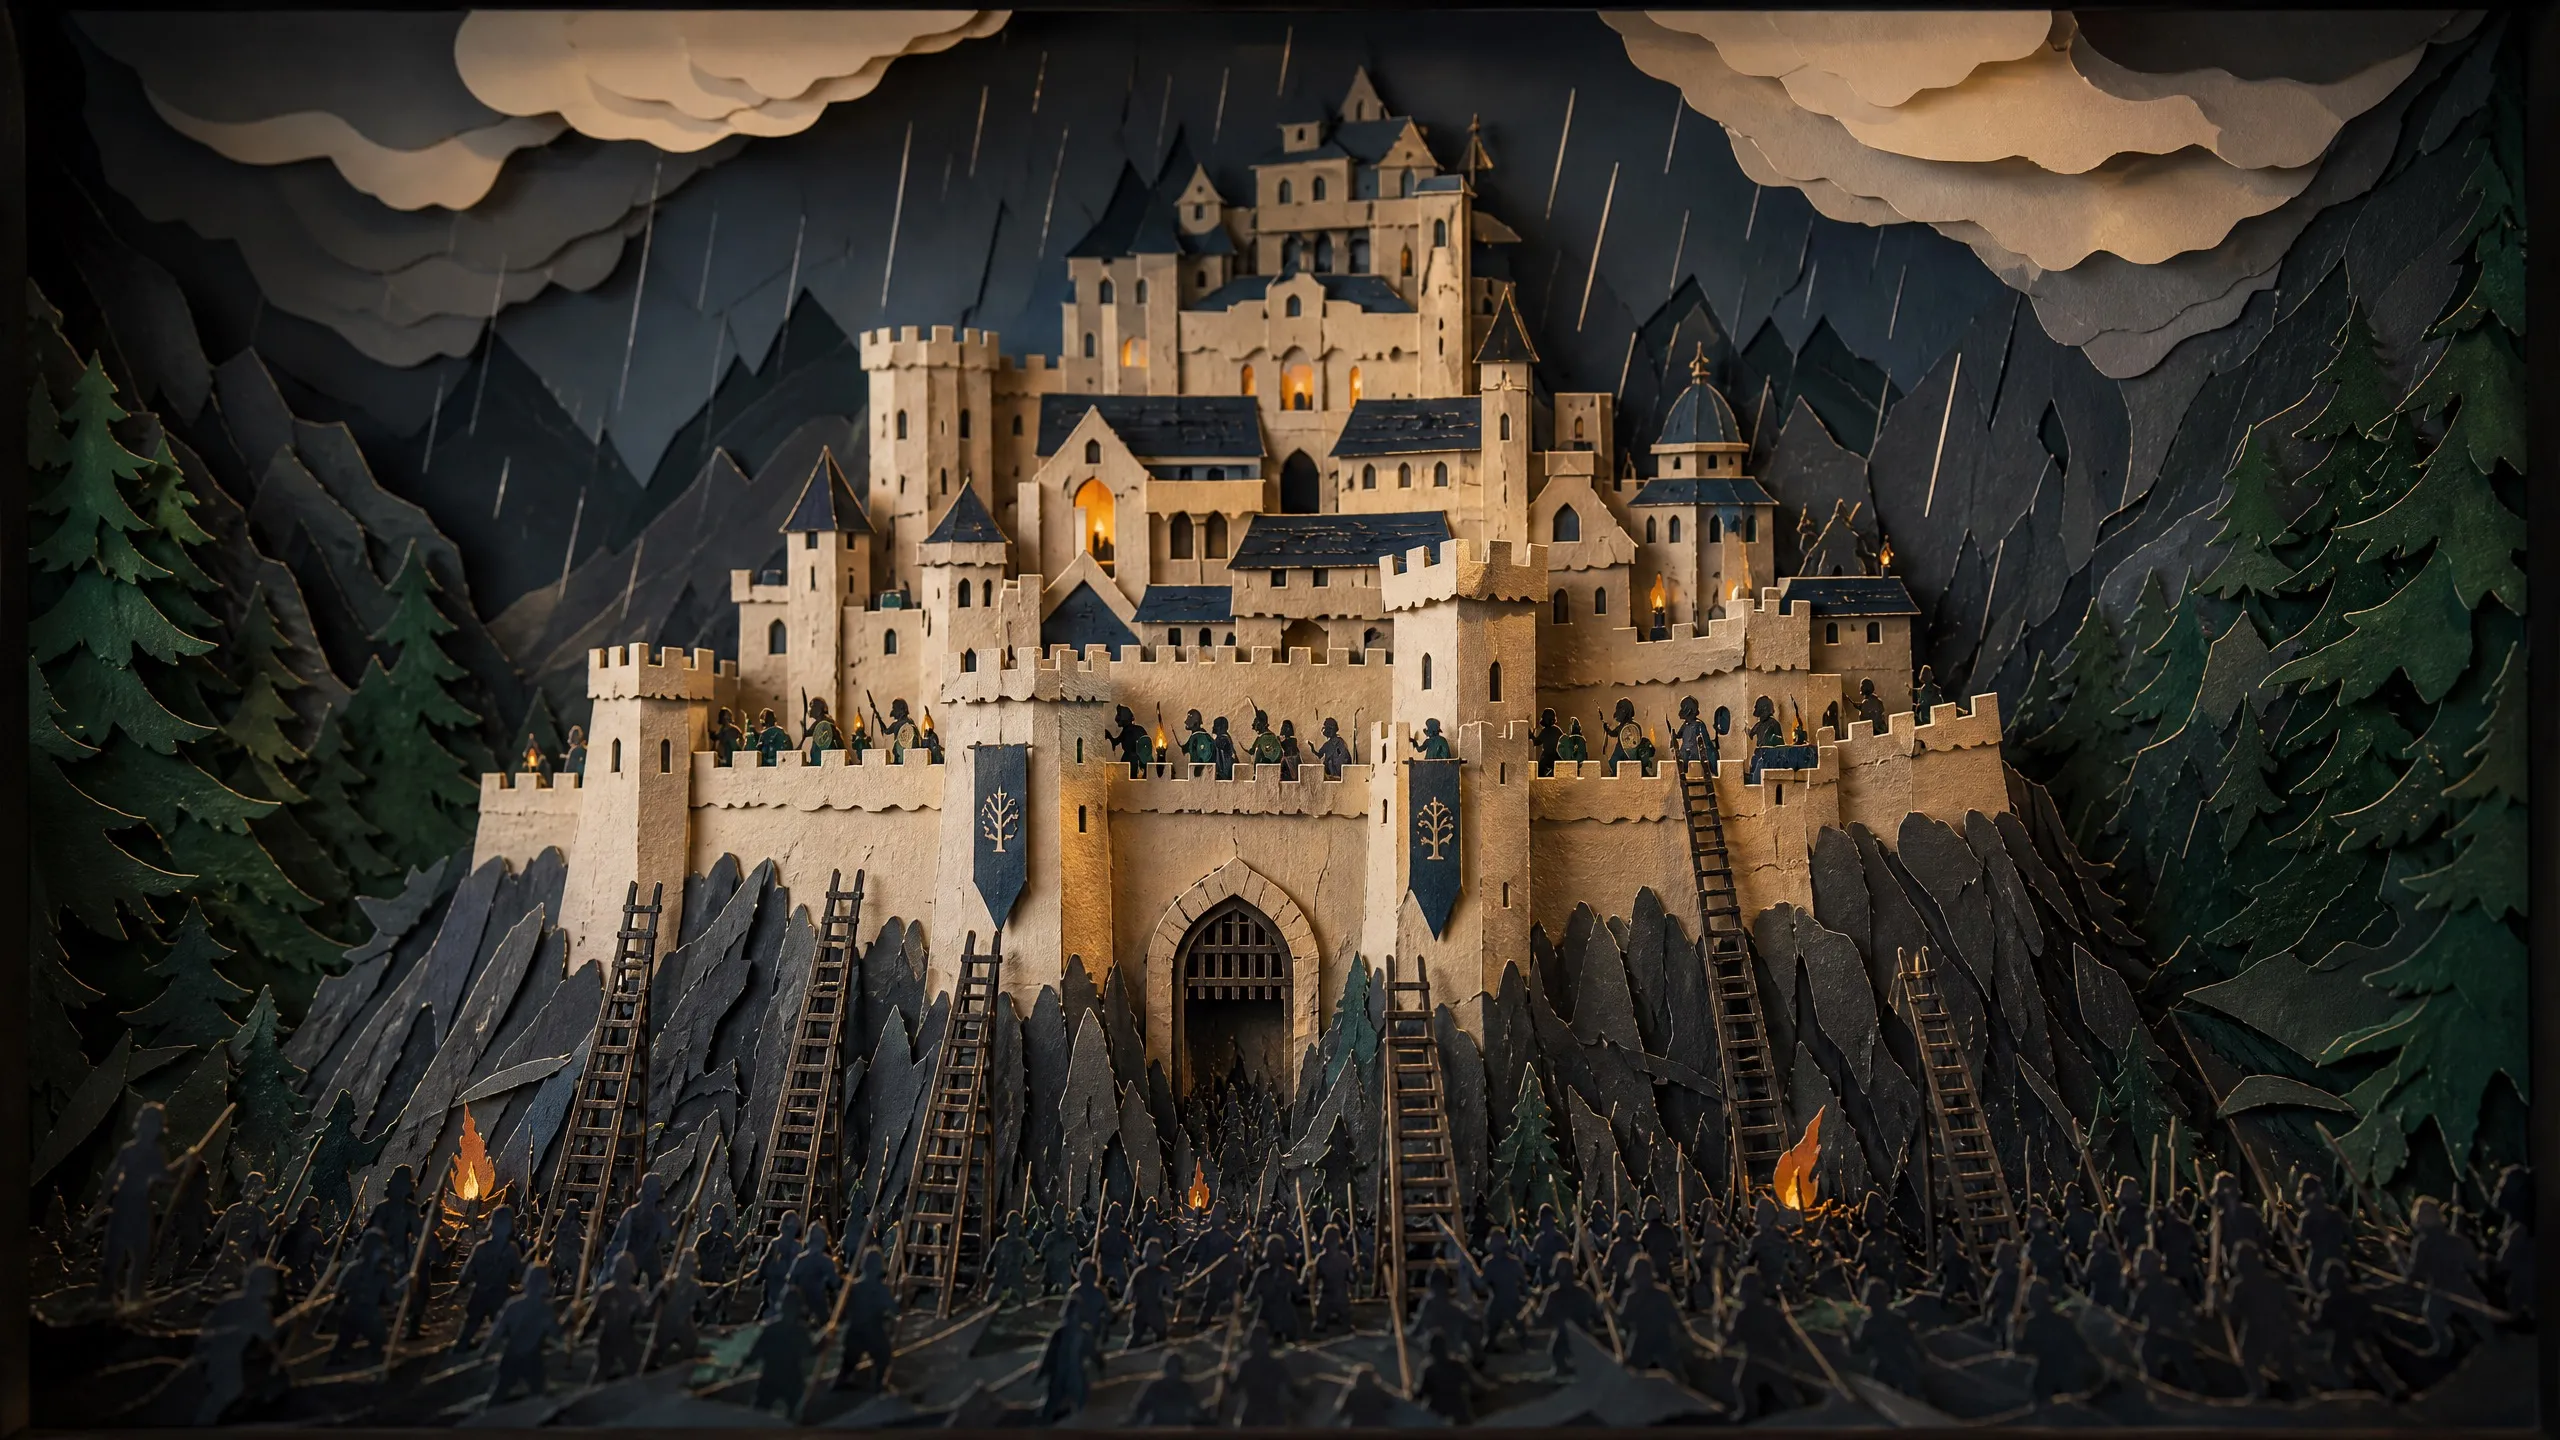
Helm's Deep
Run date: 2026-08-27
Generation provenance: unrecorded
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
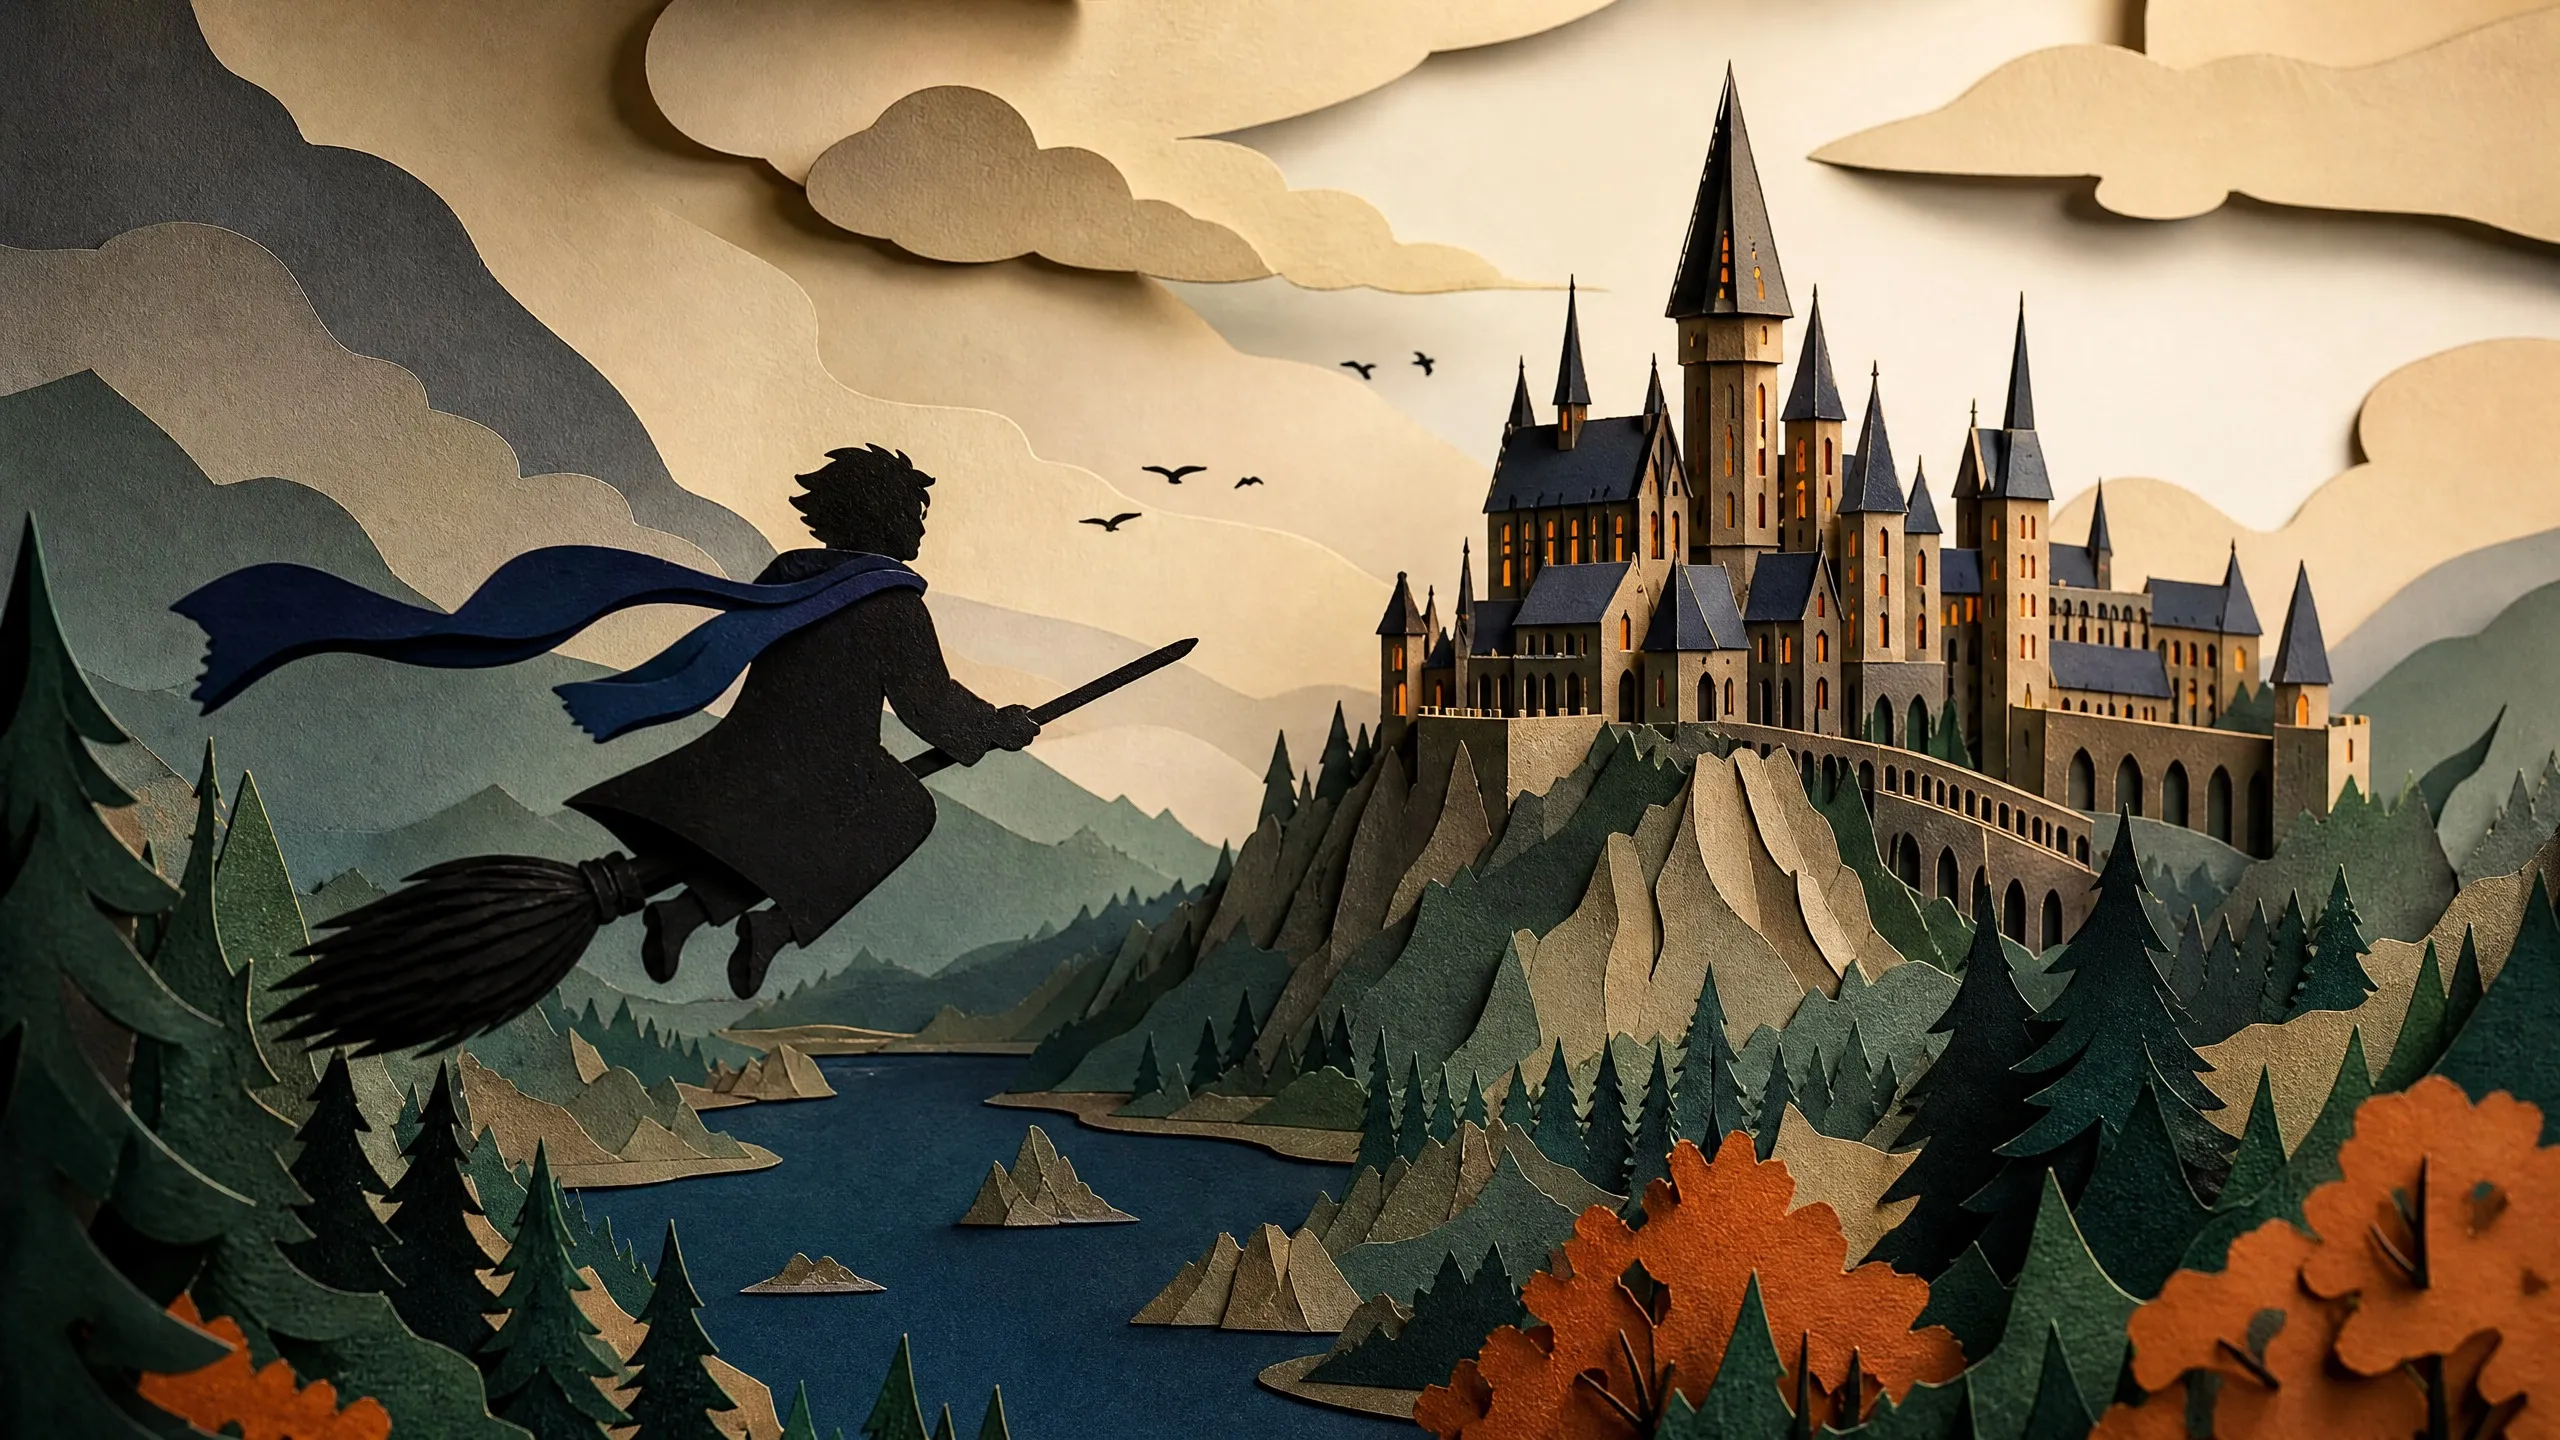
Hogwarts Broom Flight Simulator
Run date: 2026-08-27
Generation provenance: unrecorded
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Low-Poly Tower Defense
Run date: 2026-08-28
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
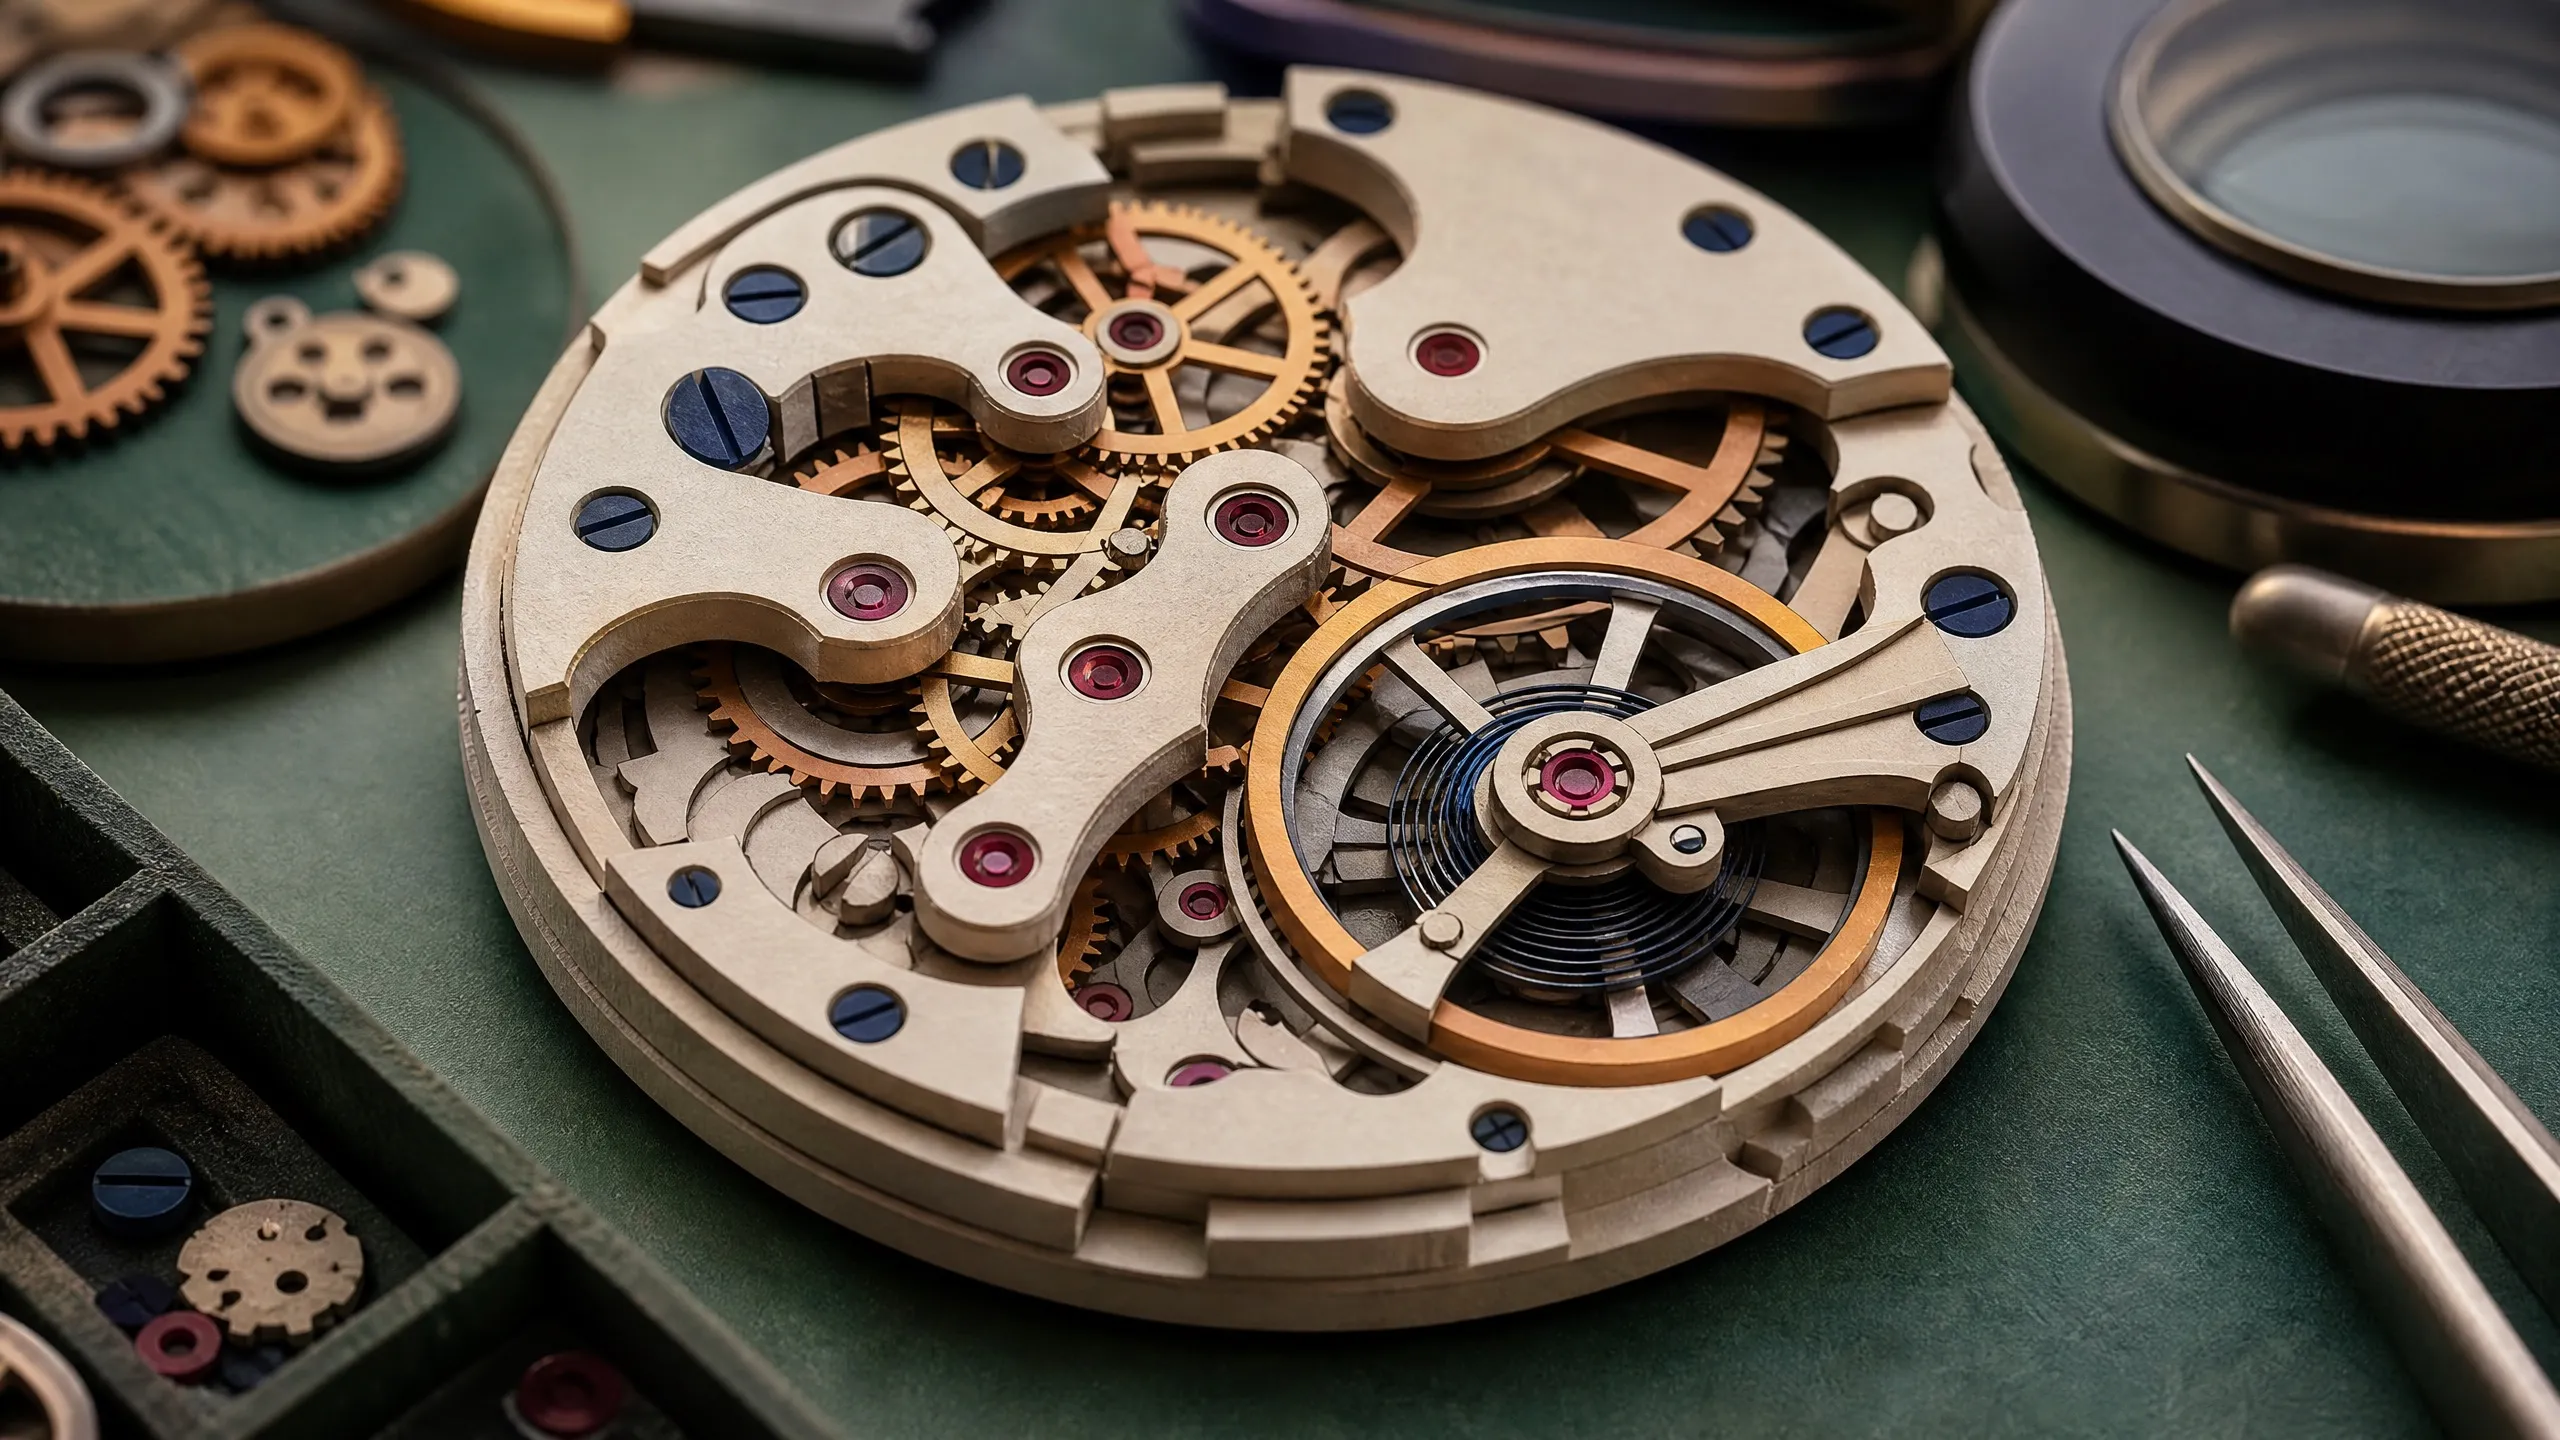
Mechanical Watch Simulator
Run date: 2026-08-27
Generation provenance: unrecorded
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Run date: 2026-08-28
Generation provenance: unrecorded
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-08-27
Generation provenance: unrecorded
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
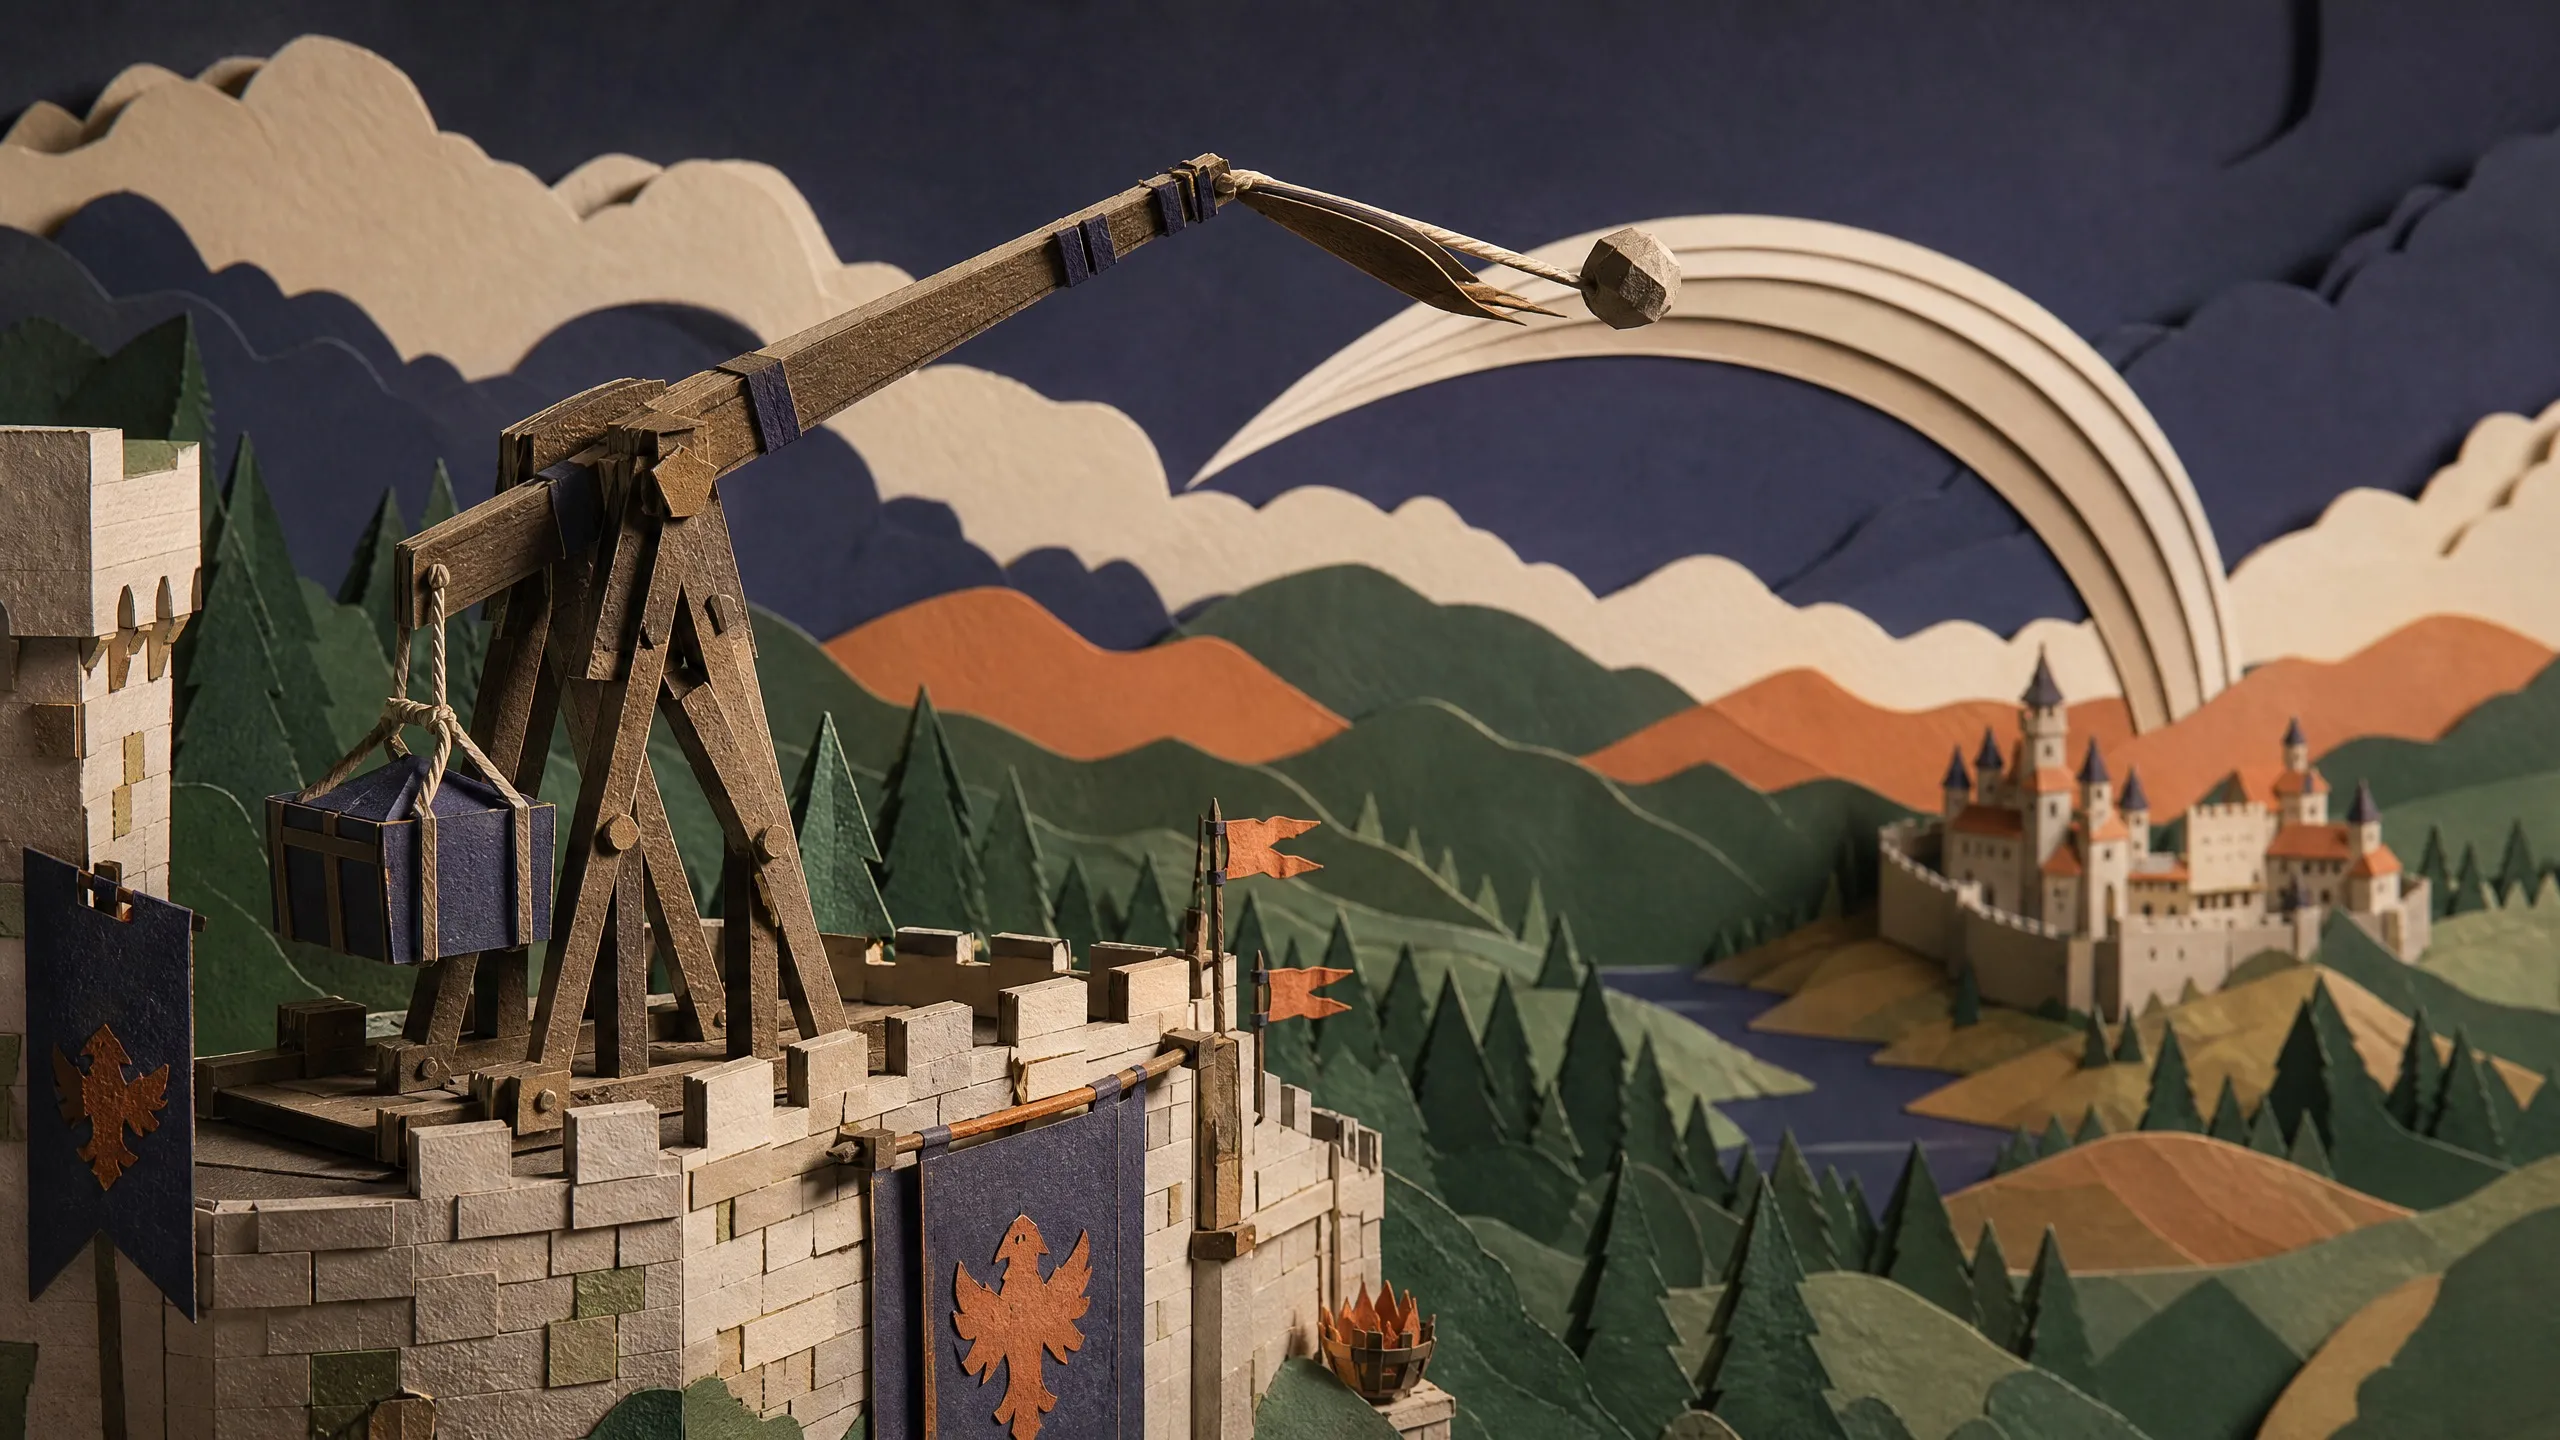
Stormwind Trebuchet Simulator
Run date: 2026-08-27
Generation provenance: unrecorded
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
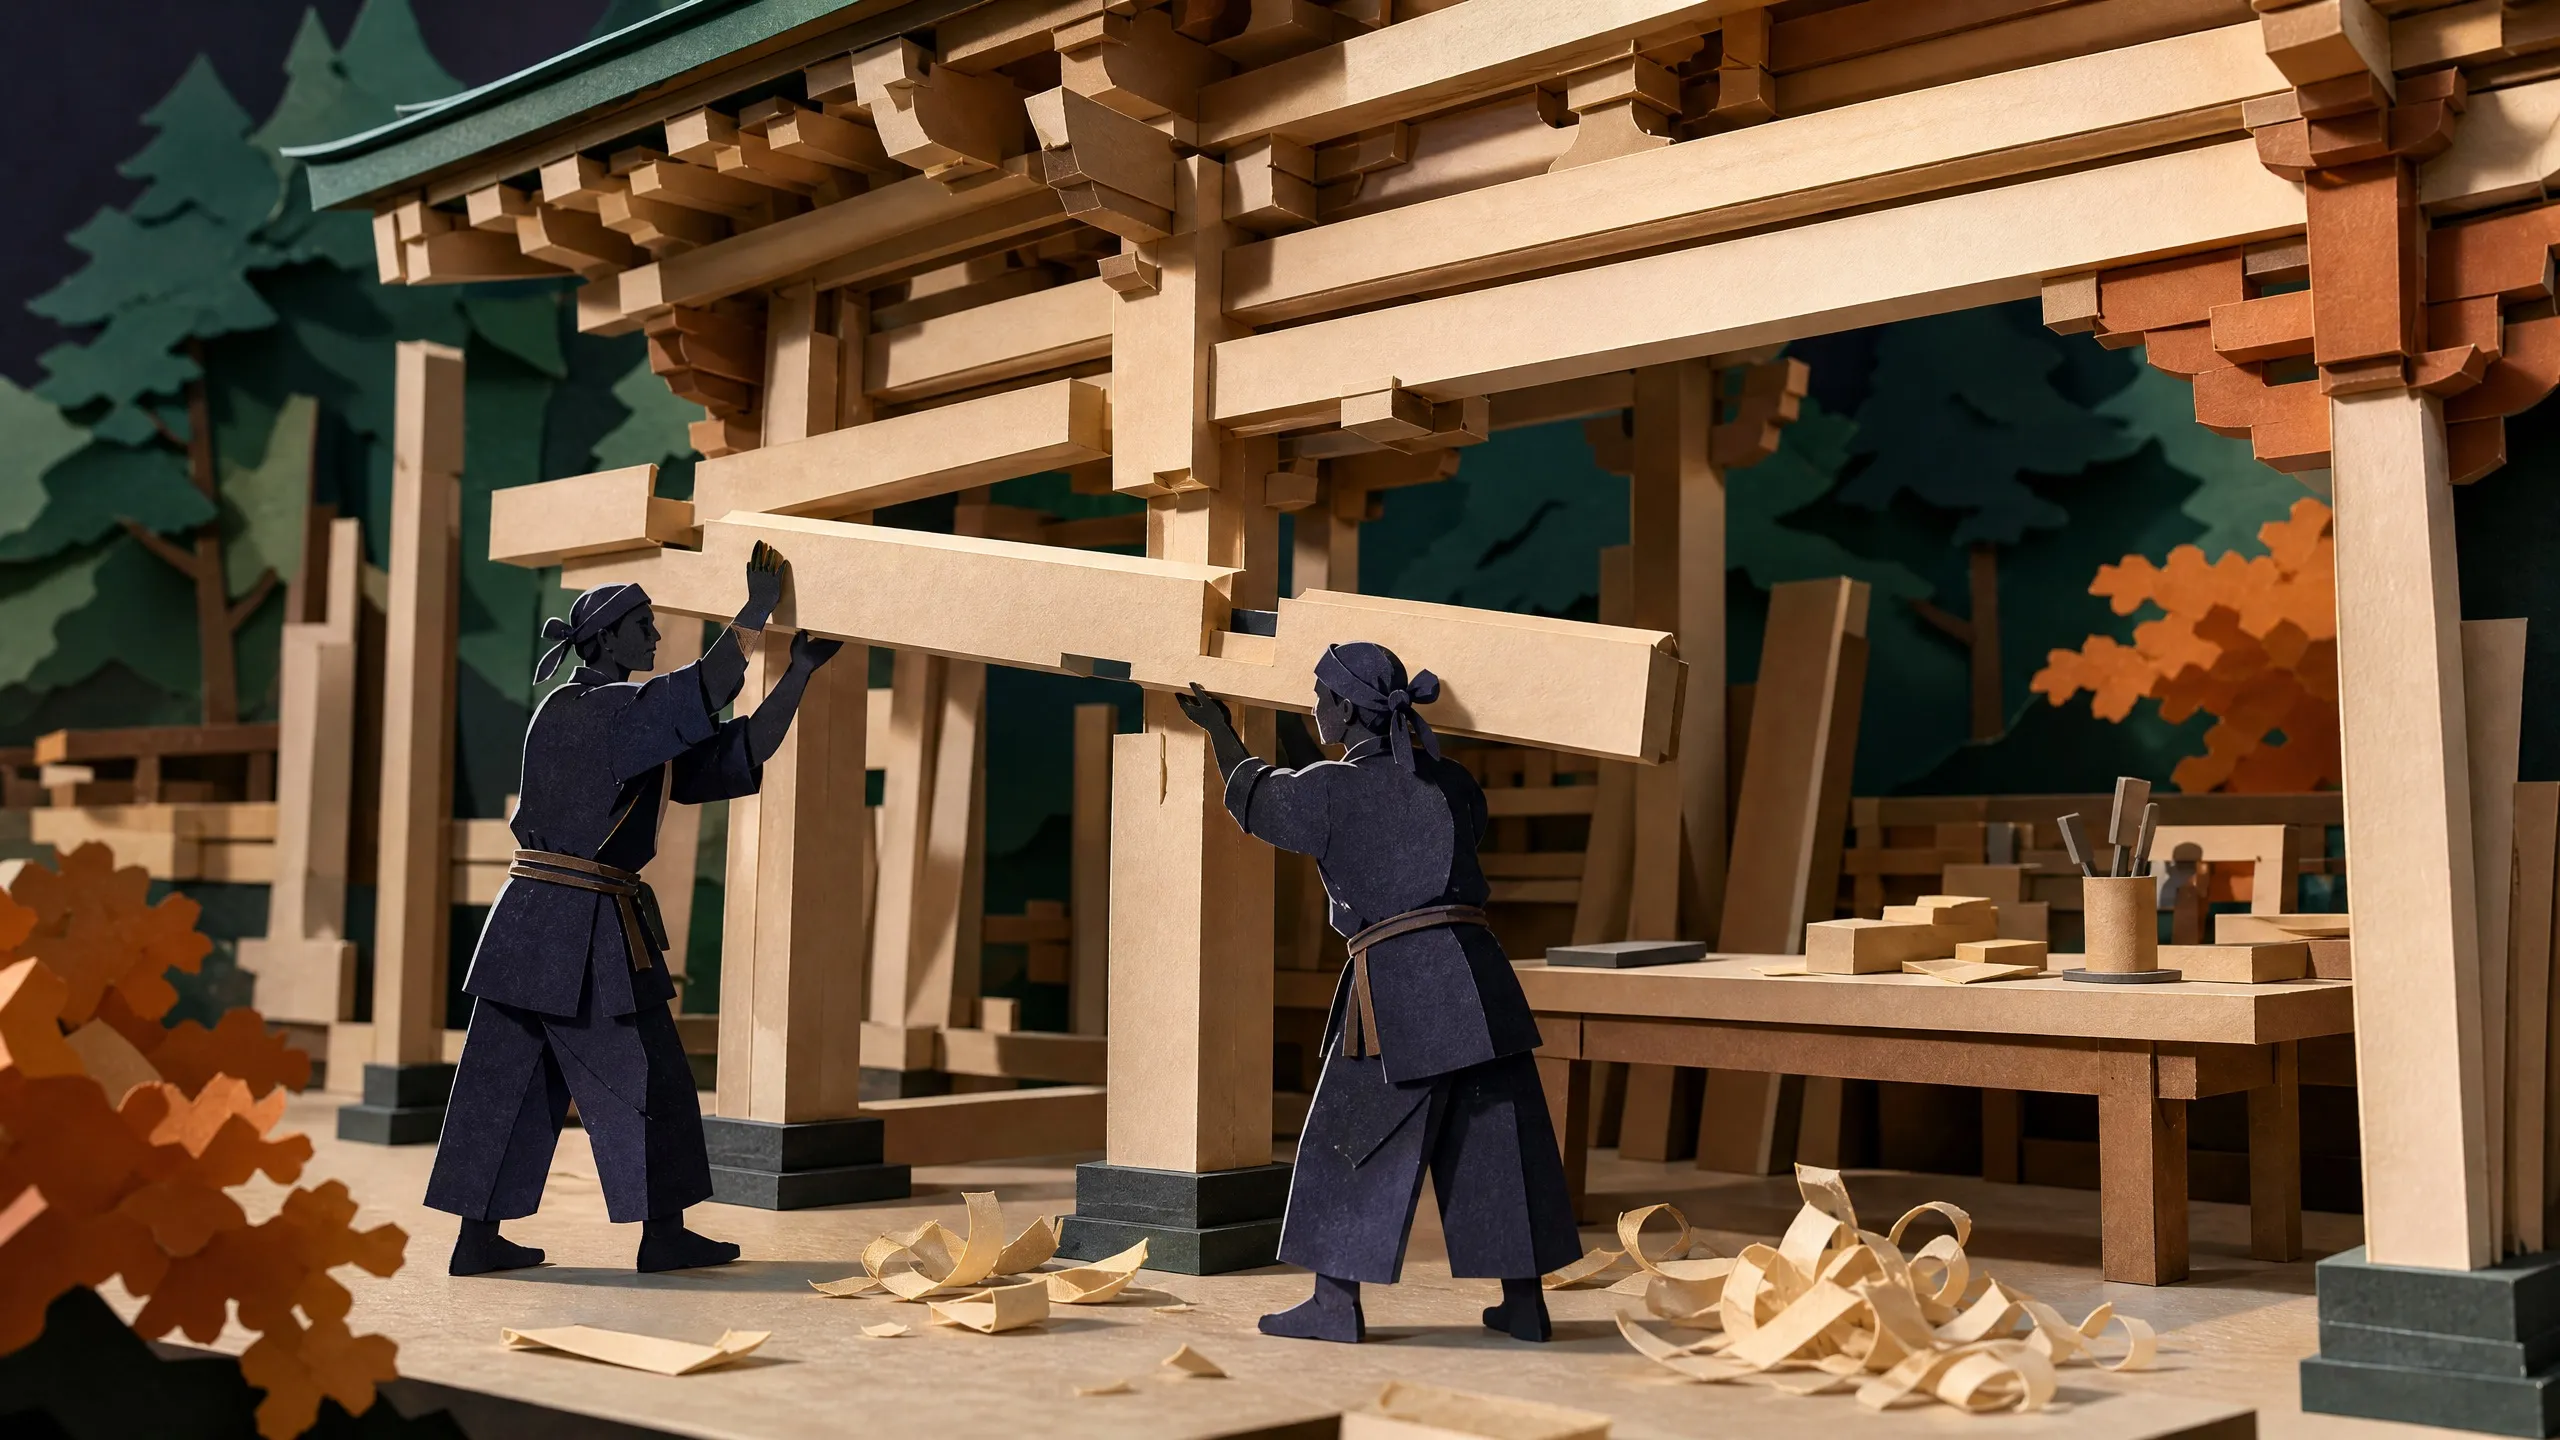
Yingzao Fashi Assembly
Run date: 2026-08-27
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How GLM 5.3 Flash compares
Three relevant peers, side by side.
- GLM 5.3 Flash This model
- GLM 5.2
- GPT-5.6 Sol
- Kimi K3
1 benchmarks · 4 models
Official benchmark profile
GLM-5.3-Flash efficiency-tier coding and agent results.
DeepSWE v1.1
63.4%AutomationBench
48.8%Z.ai Code Bench v1.0
29.0%Full official benchmark table6 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| DeepSWE v1.1 | Coding | 63.4% | |
| AutomationBench | Agentic work | 48.8% | |
| Z.ai Code Bench v1.0 | Coding | 29.0% | |
| Artificial Analysis Intelligence Index v4.1.1 | Composite intelligence | 57 | |
| GPQA Diamond | Academic reasoning | 87.5% | |
| TAU-Bench | Tool use | 80.7% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
glm-5.3-flash- Context
- 1M
- Max output
- 131K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- Z.ai API promotional rate · USD / 1M tokens
- $0.075 input · $0.015 cached input · $0.25 output
Official 50% promotion through September 9, 2026 at 24:00 UTC+8. List rates are $0.15 input, $0.03 cached input, and $0.50 output per 1M tokens. Cached-input storage is currently free for a limited time.
Benchmark sources
Z.ai positions GLM-5.3-Flash as the efficiency variant of GLM-5.3: a 320B-parameter open-weight model (18B activated) with hybrid sparse-plus-linear attention, native text, image, and video input, and roughly one-tenth the list price of frontier APIs. Z.ai reports it approaches Claude Opus 4.8 across six coding and agentic benchmarks.
GLM-5.3-FlashGLM-5.3-Flash is fully available on the GLM Coding Plan with three times the GLM-5.3 quota, and is listed by multiple third-party inference providers.
Evaluation settings
- Z.ai launch result; GLM-5.2 scored 46.2% in the same comparison.
- Z.ai launch result; GLM-5.2 scored 26.2% in the same comparison.
- Claude Code 2.1.207 harness at maximum reasoning effort; Claude Opus 4.8 scored 29.5% on the same harness.
- Z.ai-reported score at a discounted $0.045 per task, which Z.ai says pushes the cost-quality Pareto frontier.
- Highest provider-reported OpenRouter result (GMICloud); other providers reported 84.3–84.5%.
- Highest provider-reported OpenRouter result (NovitaAI); the Z.ai direct endpoint reported 77.3%.
Editorial verdict
Where this model fits
GLM 5.3 Flash is Z.ai's efficiency variant of GLM 5.3: a 320B-parameter open-weight model (18B activated) with native text, image, and video input at roughly a tenth of frontier list price. Independent builder agents completed all sixteen Superbash visual prompts in one series, every artifact validating and running, and Z.ai reports coding results approaching Claude Opus 4.8.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: GLM 5.3 Flash is currently placed in Tier A.
The November 2026 editorial roster places GLM 5.3 Flash at rank 8.
Open source →GLM-5.3-Flash
Takeaway: Use GLM 5.3 Flash for cost-conscious coding work, then review the output.
The provider page documents the hybrid sparse-plus-linear architecture, multimodal input, and Coding Plan availability with three times the GLM-5.3 quota.
Open source →Related guides