
OpenAI
GPT-6 Sol
A-tier choice for reviewed build work, supported by ten published prompt-only Superbash visual runs.
API pricing
USD per million tokens · OpenAI API Standard (≤272K input tokens)- Input
- $2
- Output
- $10
- Cached input
- $0.2
- Context window
- 1.05M
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-09-23
Specialist test · evaluated separately
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.
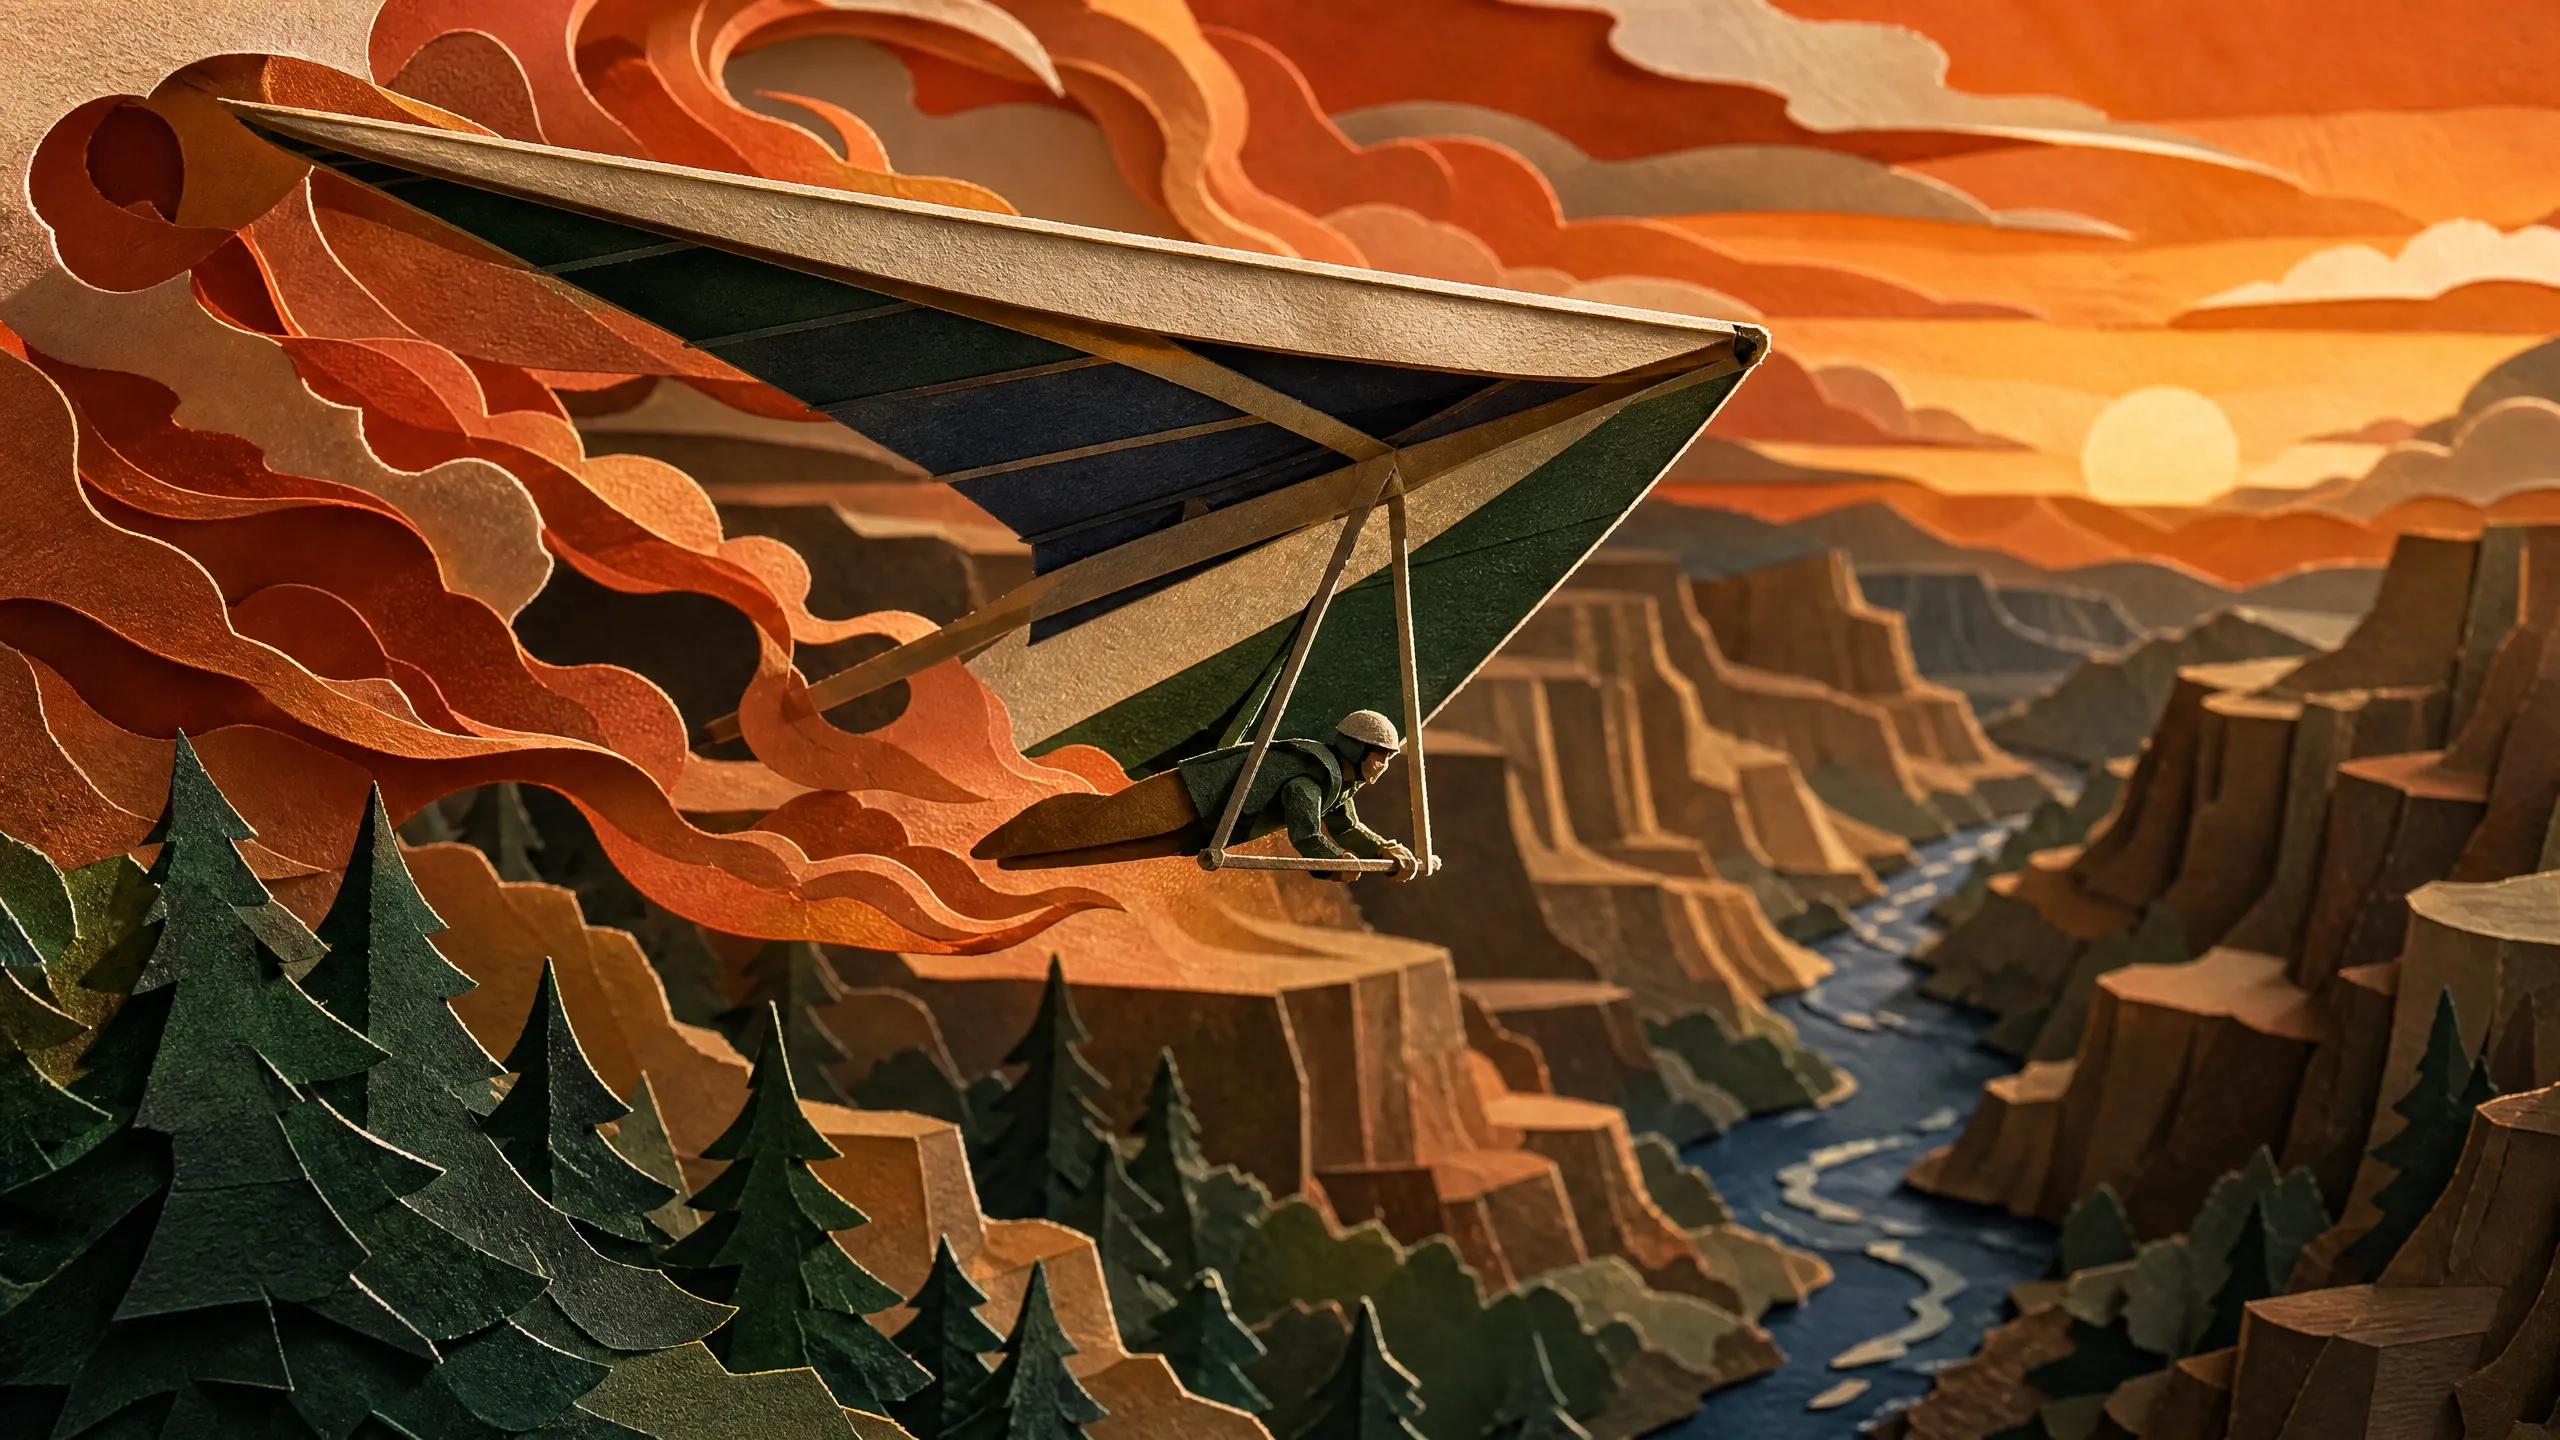
Ember Glider
Run date: 2026-09-23
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
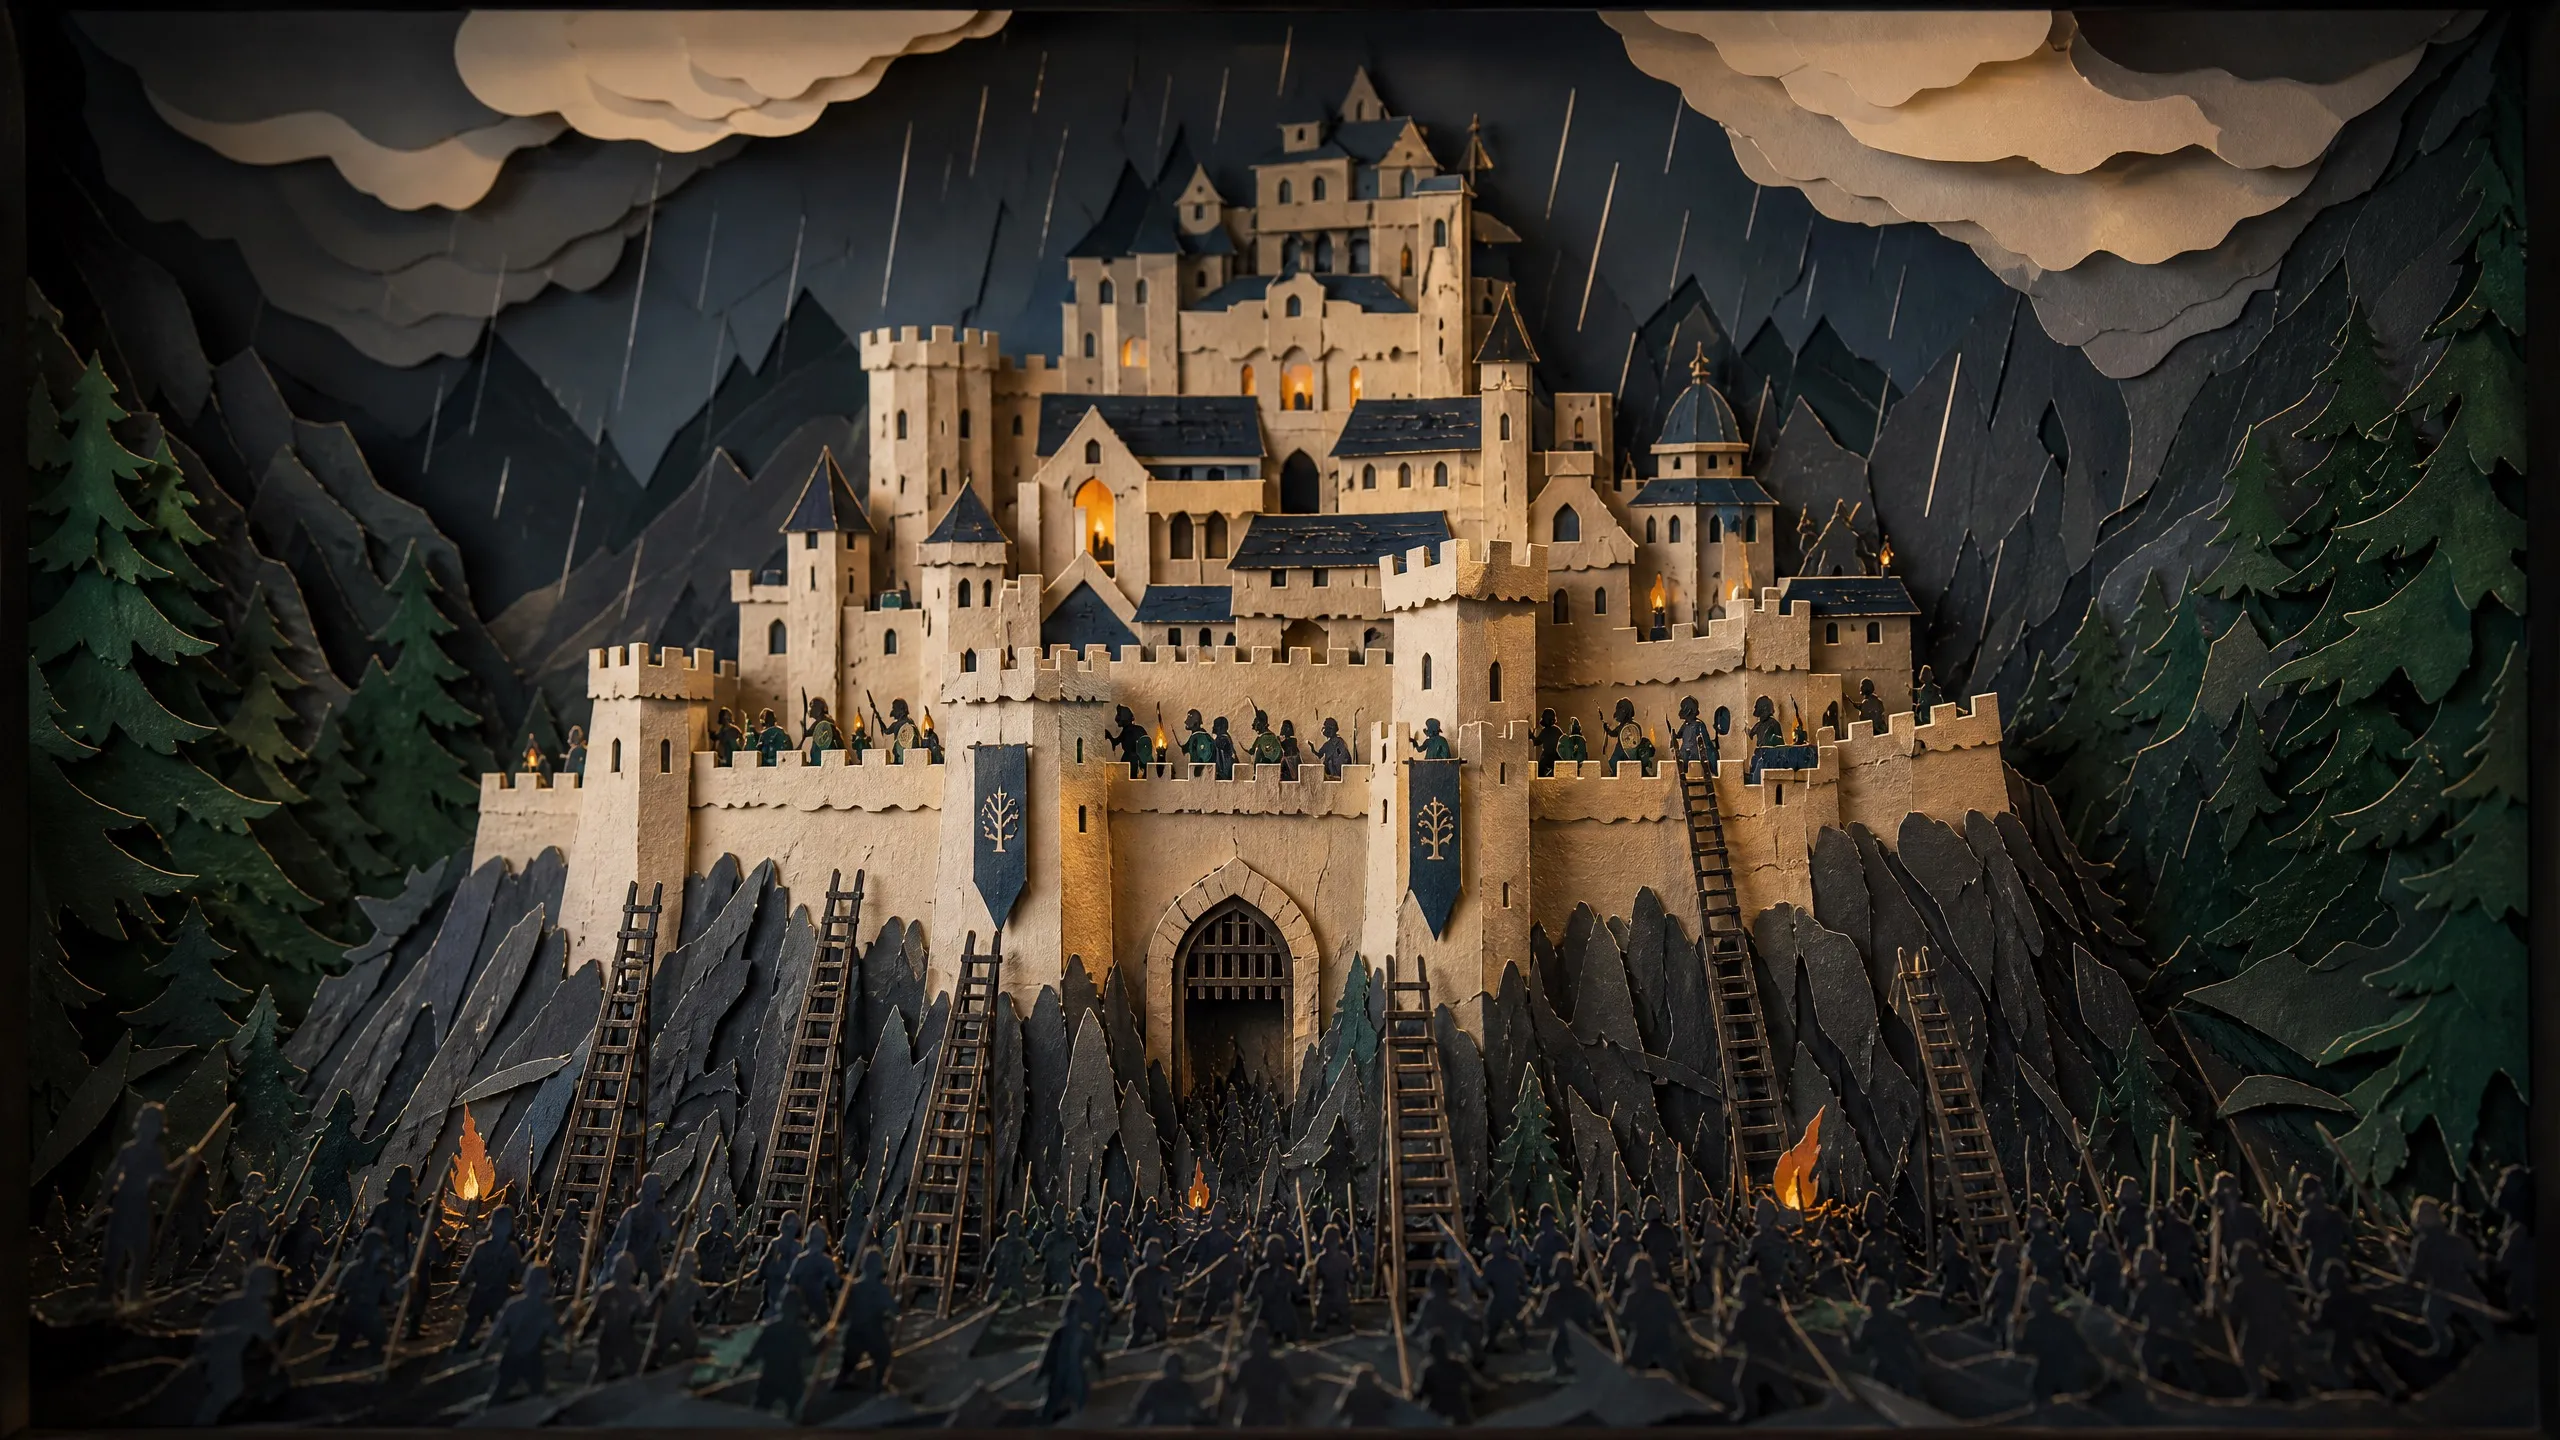
Helm's Deep
Run date: 2026-09-23
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
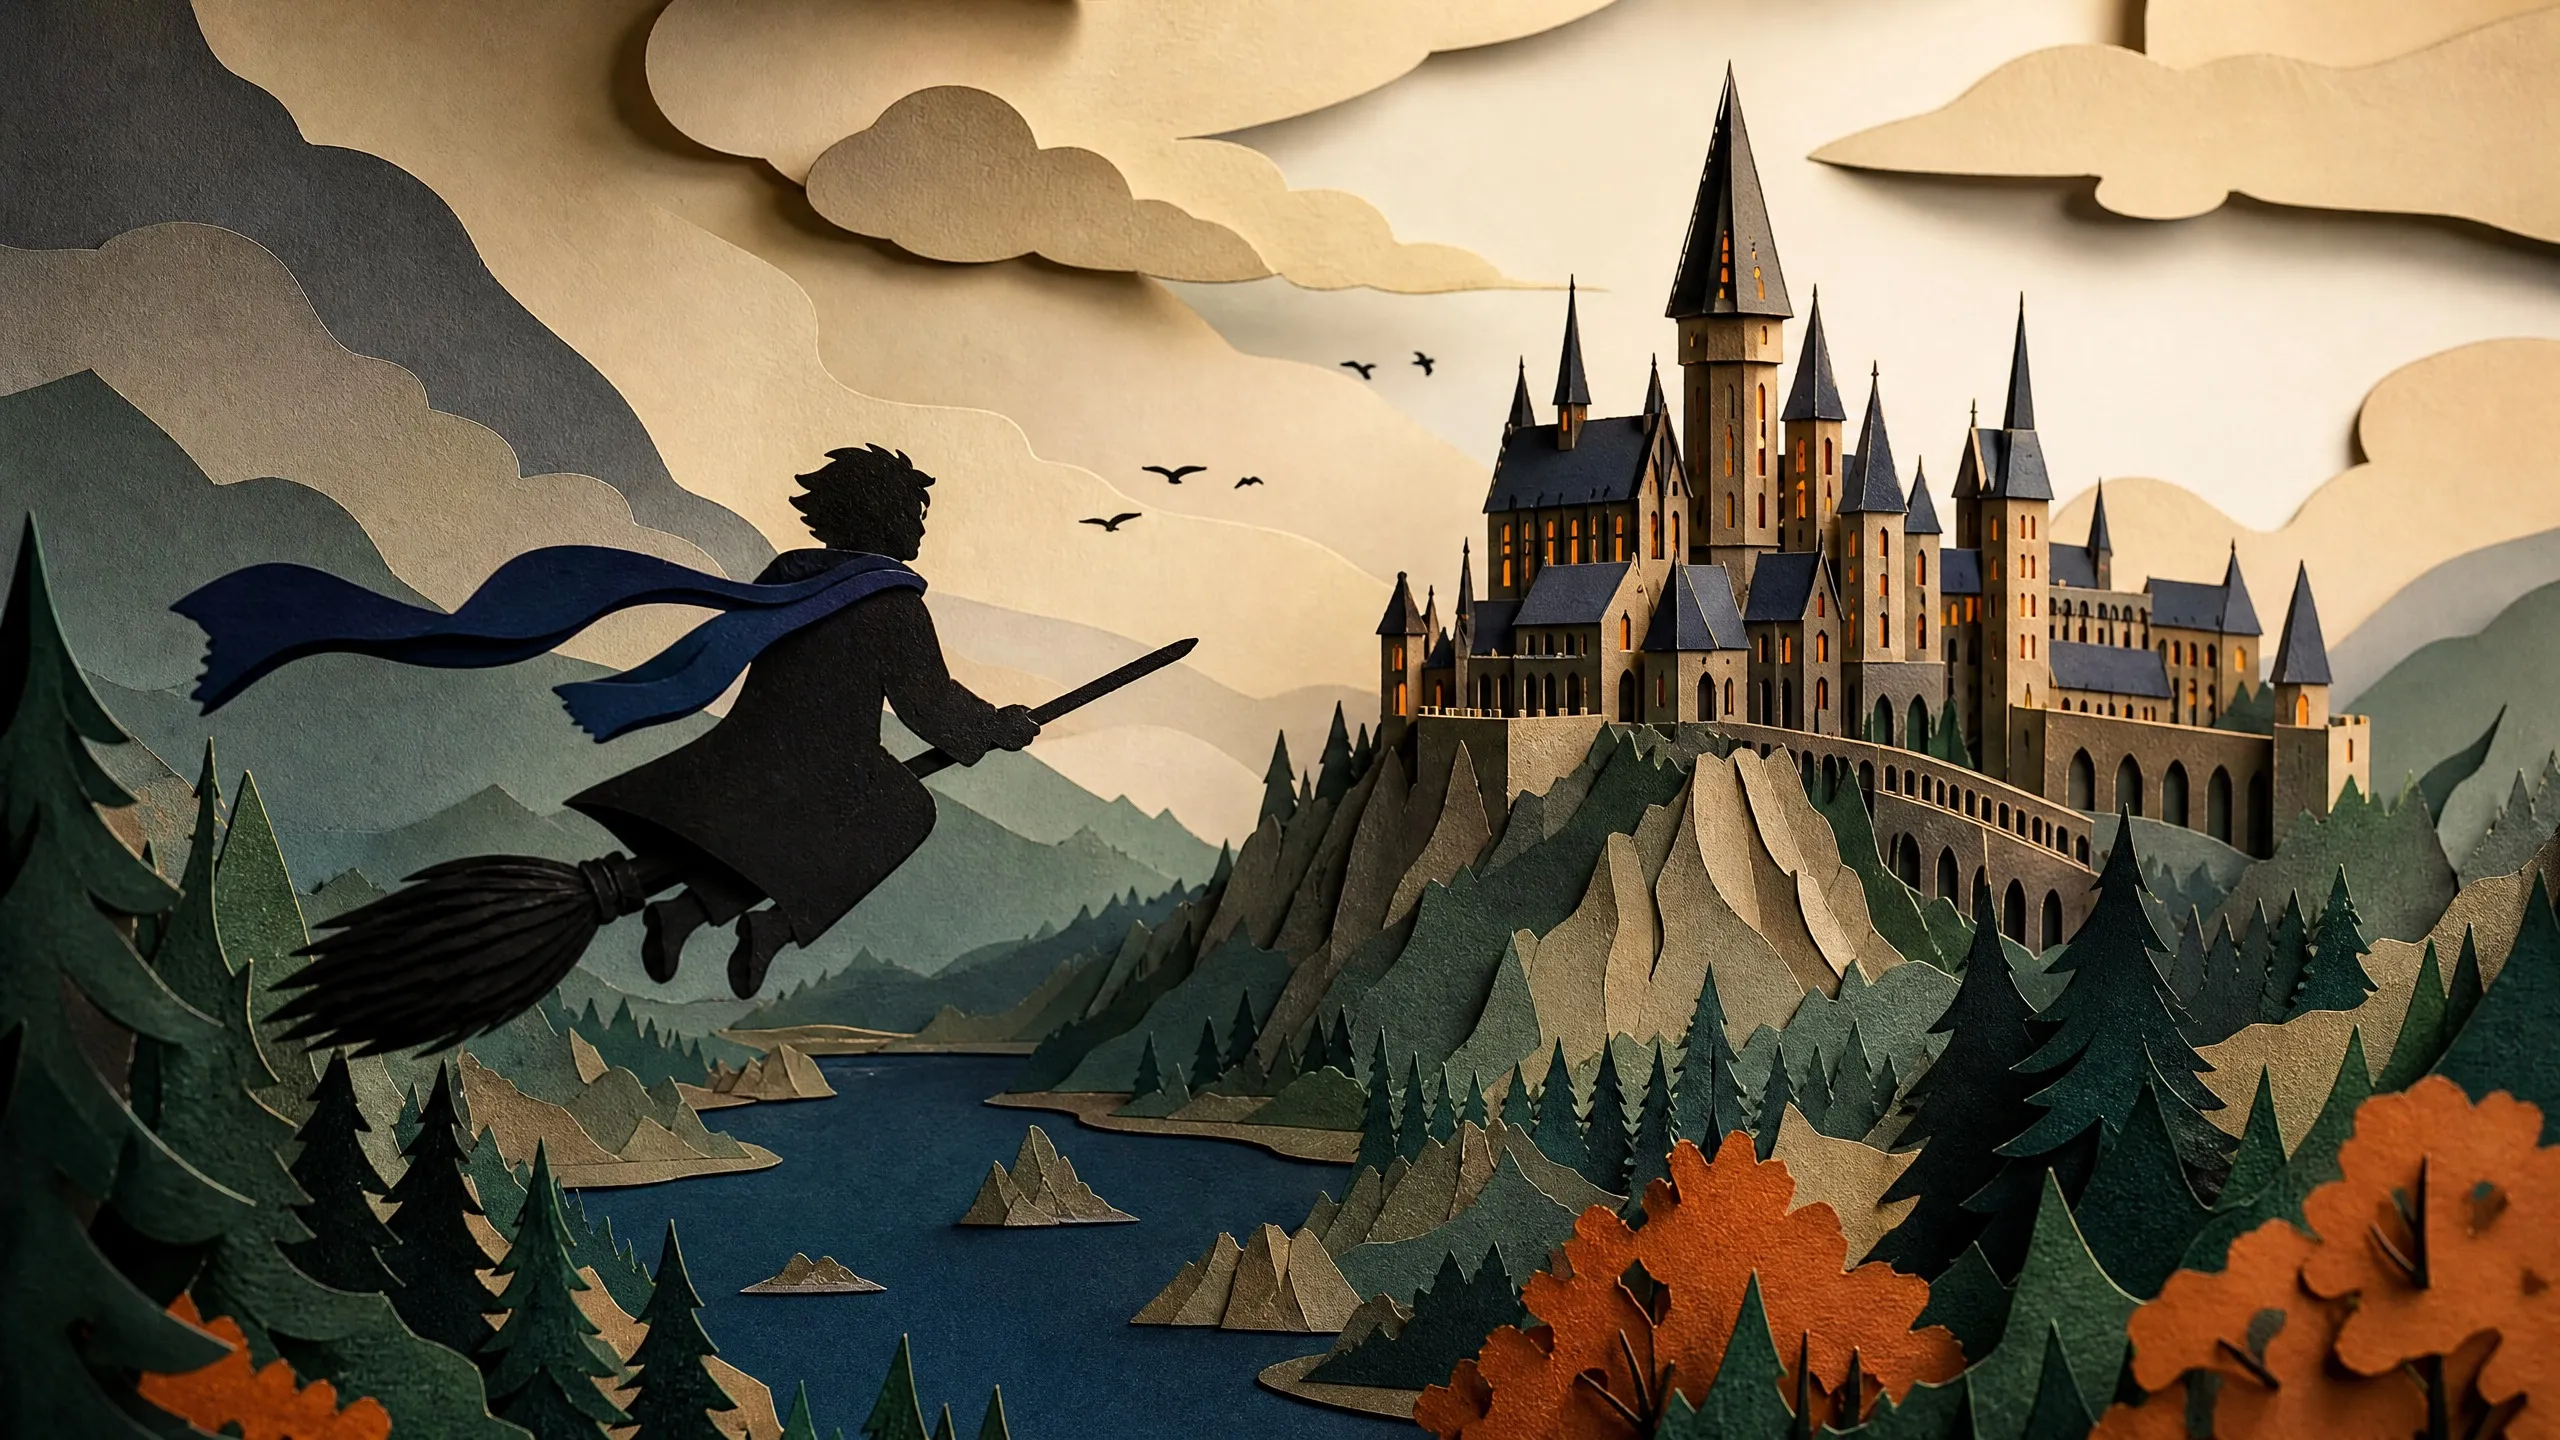
Hogwarts Broom Flight Simulator
Run date: 2026-09-23
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
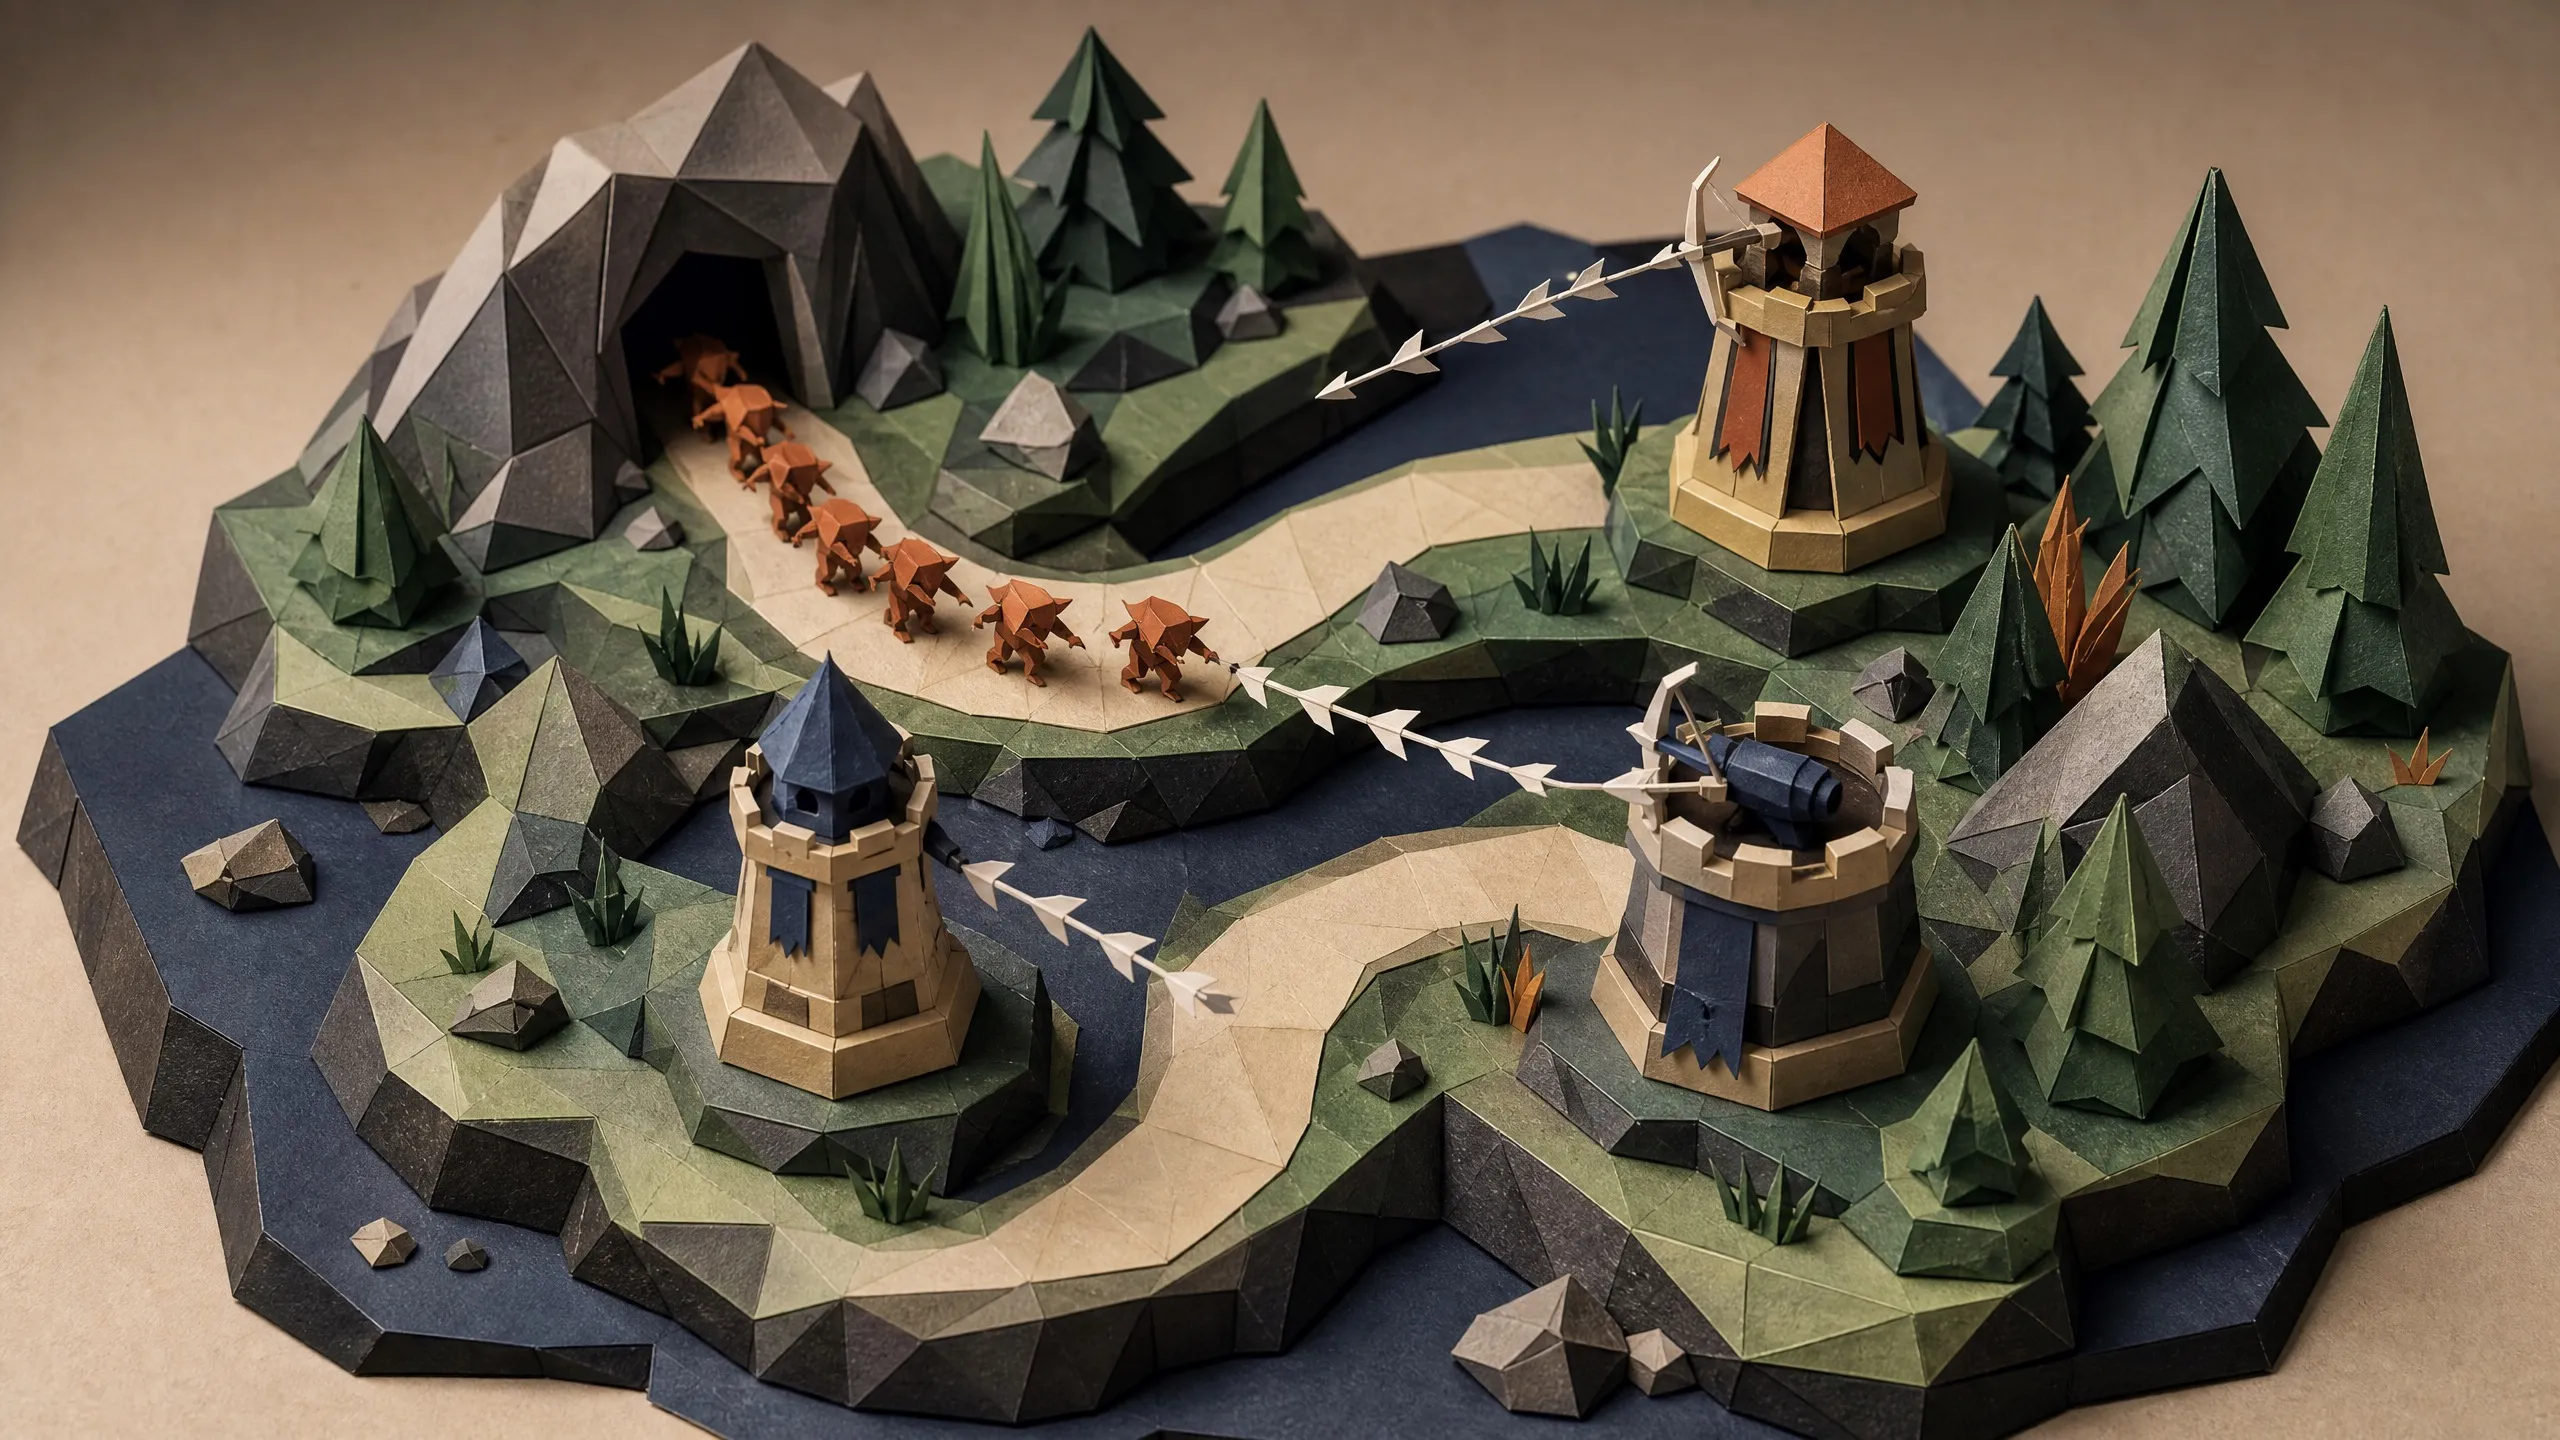
Low-Poly Tower Defense
Run date: 2026-09-23
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
Mechanical Watch Simulator
Run date: 2026-09-23
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.
Neon Drift
Run date: 2026-09-23
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-09-23
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
Stormwind Trebuchet Simulator
Run date: 2026-09-23
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
Yingzao Fashi Assembly
Run date: 2026-09-23
Specialist test · evaluated separately
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Local benchmark run
Prompt-only runs on the active visual suite
Sources, pricing details and methodology
Run identity
Model specifications
- Status
- Available in this Codex session
- Codex model ID
gpt-6-sol- Run date
- September 23, 2026
- Access route
- OpenAI API and Codex. The September 23 visual runs selected Sol in Codex; listed API prices are not measured run costs.
Above 272K input tokens, the full request costs $4 input, $0.40 cached input, $5 cache write, and $15 output per 1M tokens. Batch, Flex, Fast mode, and regional pricing differ.
Benchmark sources
Each active benchmark was assigned to a separate GPT-6 Sol subagent. Its original prompt was the sole creative brief; no reference implementation or other model output was supplied.
GPT-6 Sol prompt-only visual benchmark runThese are inspectable local artifacts, not a numeric score or provider benchmark. Individual validation reports describe the checks performed and any limitations.
Editorial verdict
Where this model fits
GPT-6 Sol has ten published Superbash visual runs from fresh, separately assigned Codex agents. Each has an artifact, manifest, and validation record. A tier is an editorial routing choice for practical build work; these runs are not a normalized model score or proof of production quality.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: GPT-6 Sol is currently placed in Tier A.
The September 2026 editorial roster places GPT-6 Sol at rank 5.
Open source →Superbash visual benchmark suite: GPT-6 Sol
Takeaway: Ten prompt-only Sol runs are published with manifests and validation records.
The methodology describes local run separation and checks; it does not turn the artifacts into a comparative score.
Open source →Related guides