
OpenAI
GPT-5.6 Terra
The practical A-tier daily driver for routine delivery work.
API pricing
USD per million tokens · OpenAI API Standard (≤272K input tokens)- Input
- $2
- Output
- $12
- Cached input
- $0.2
- Context window
- 1.05M
Try the visual runs
Open the generated scene to test it, or compare that prompt with another model.
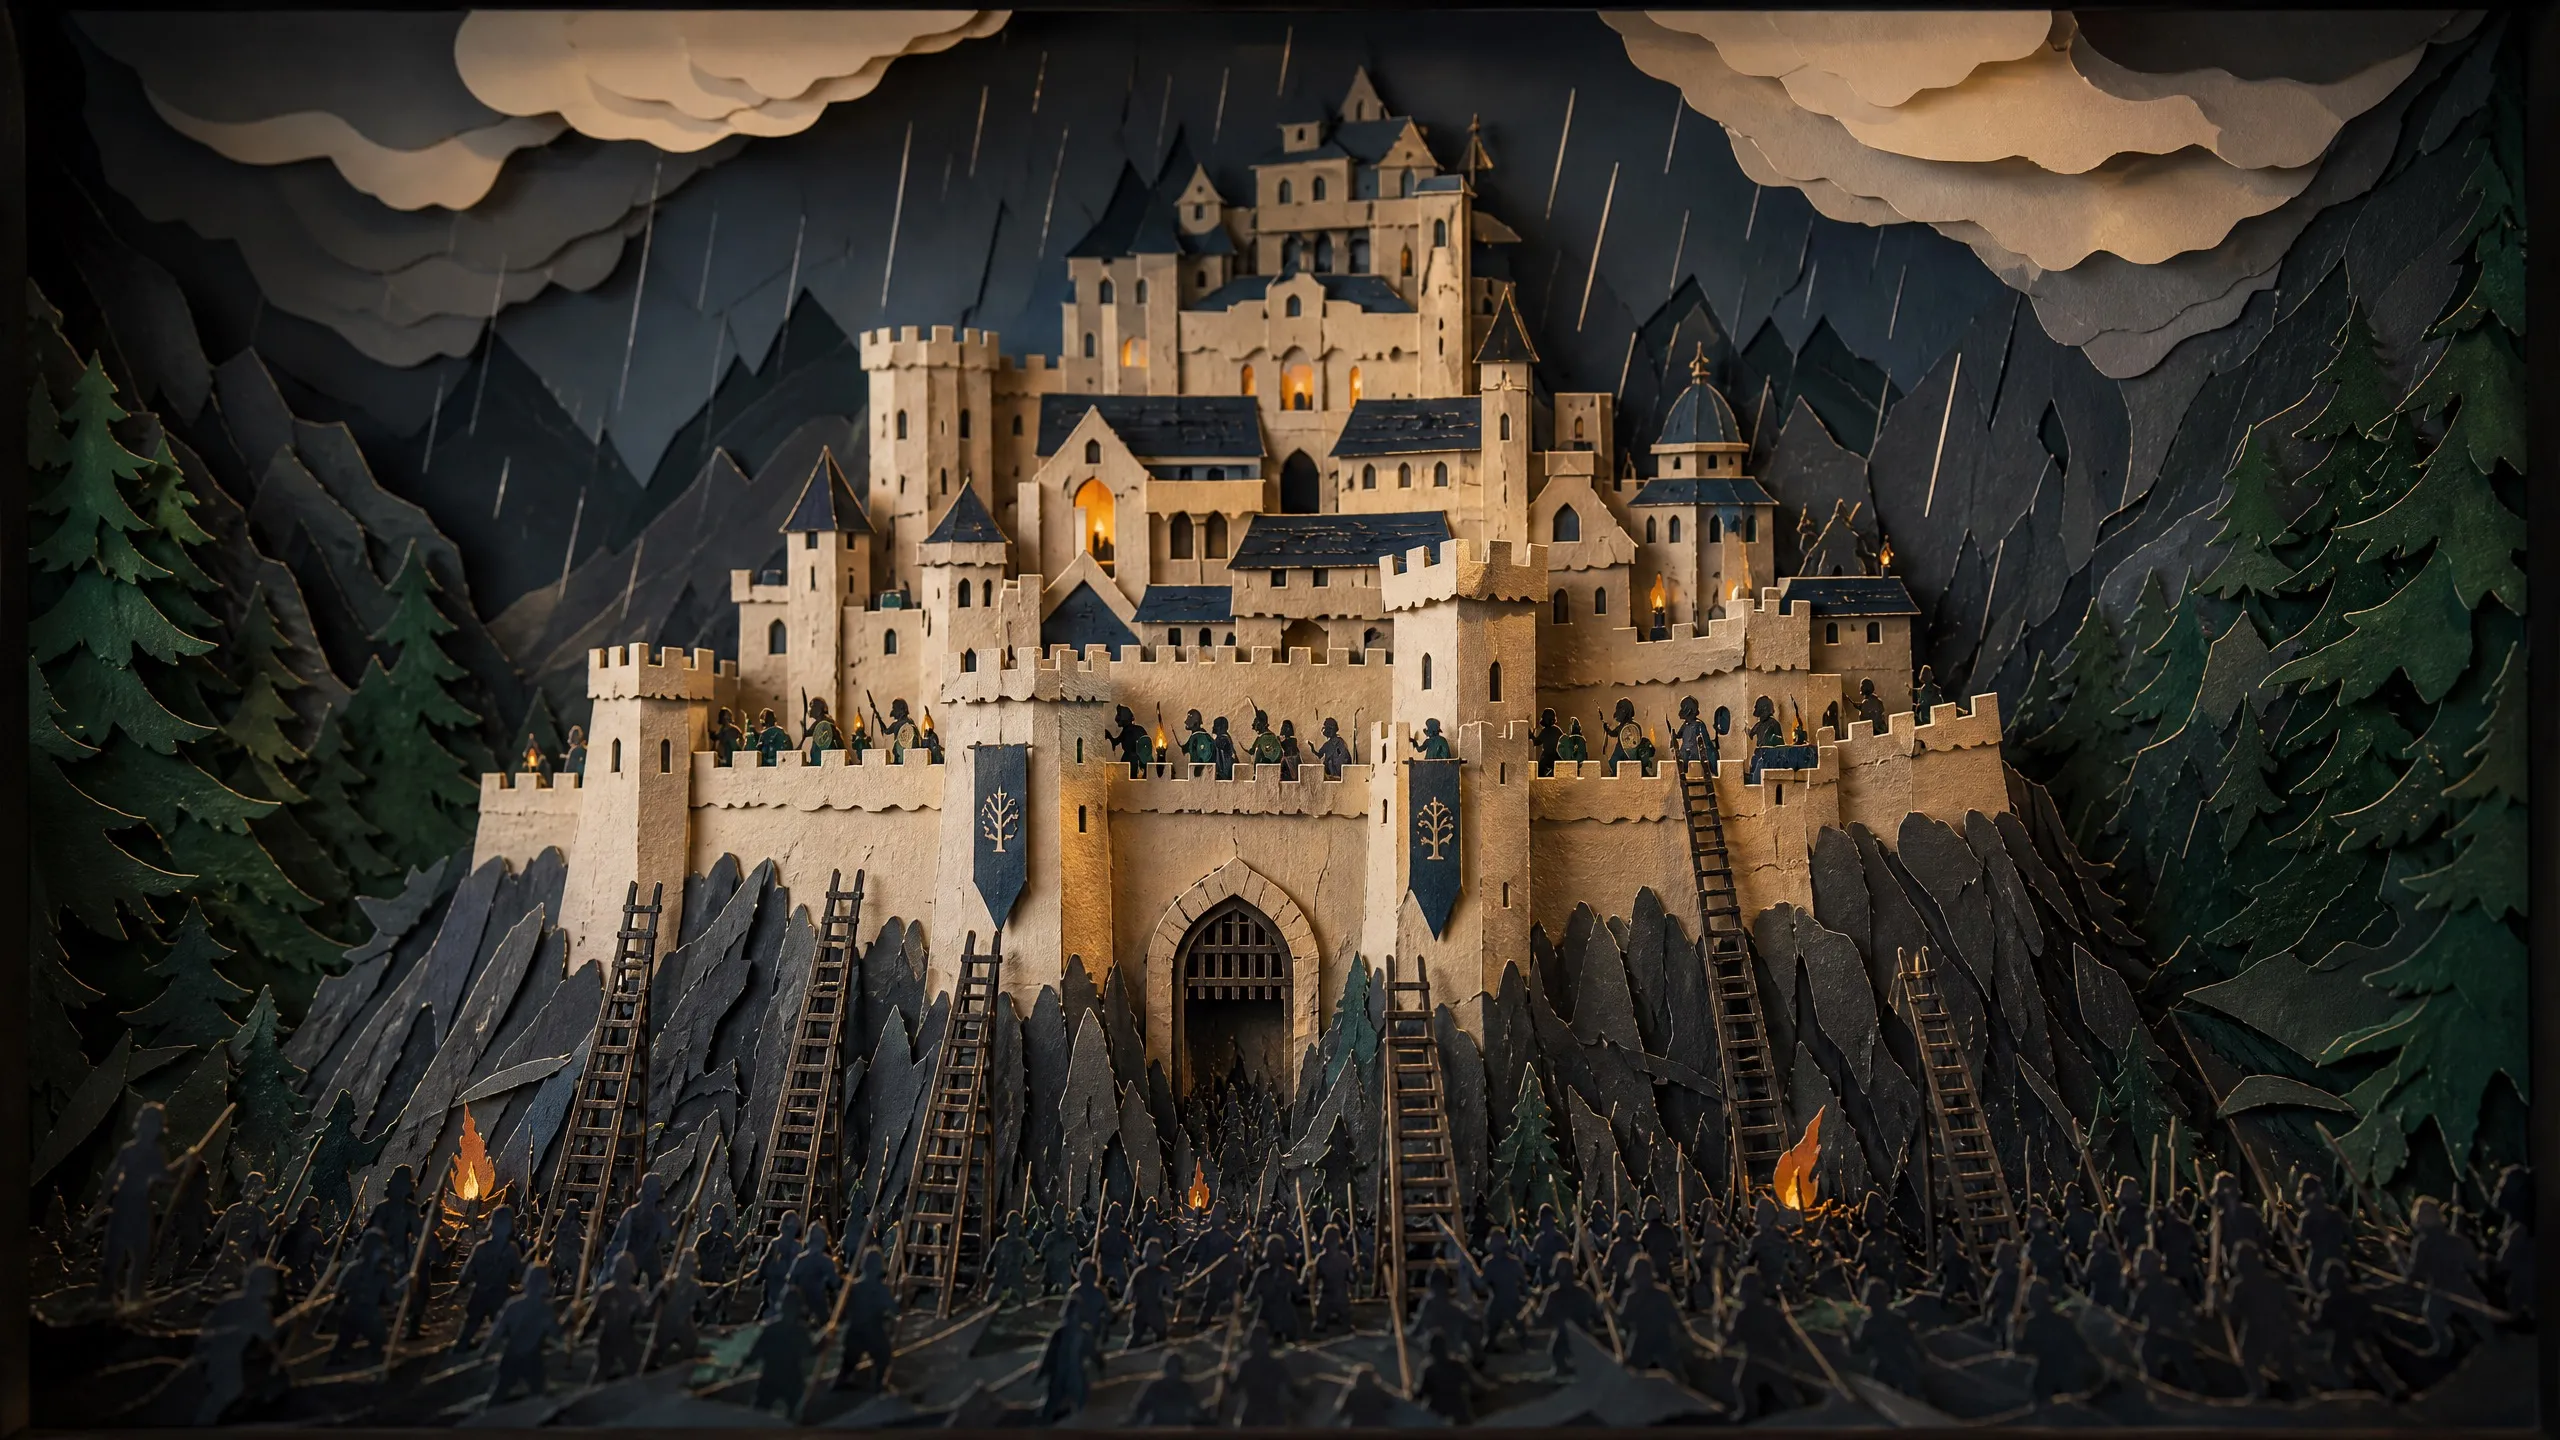
Helm's Deep
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
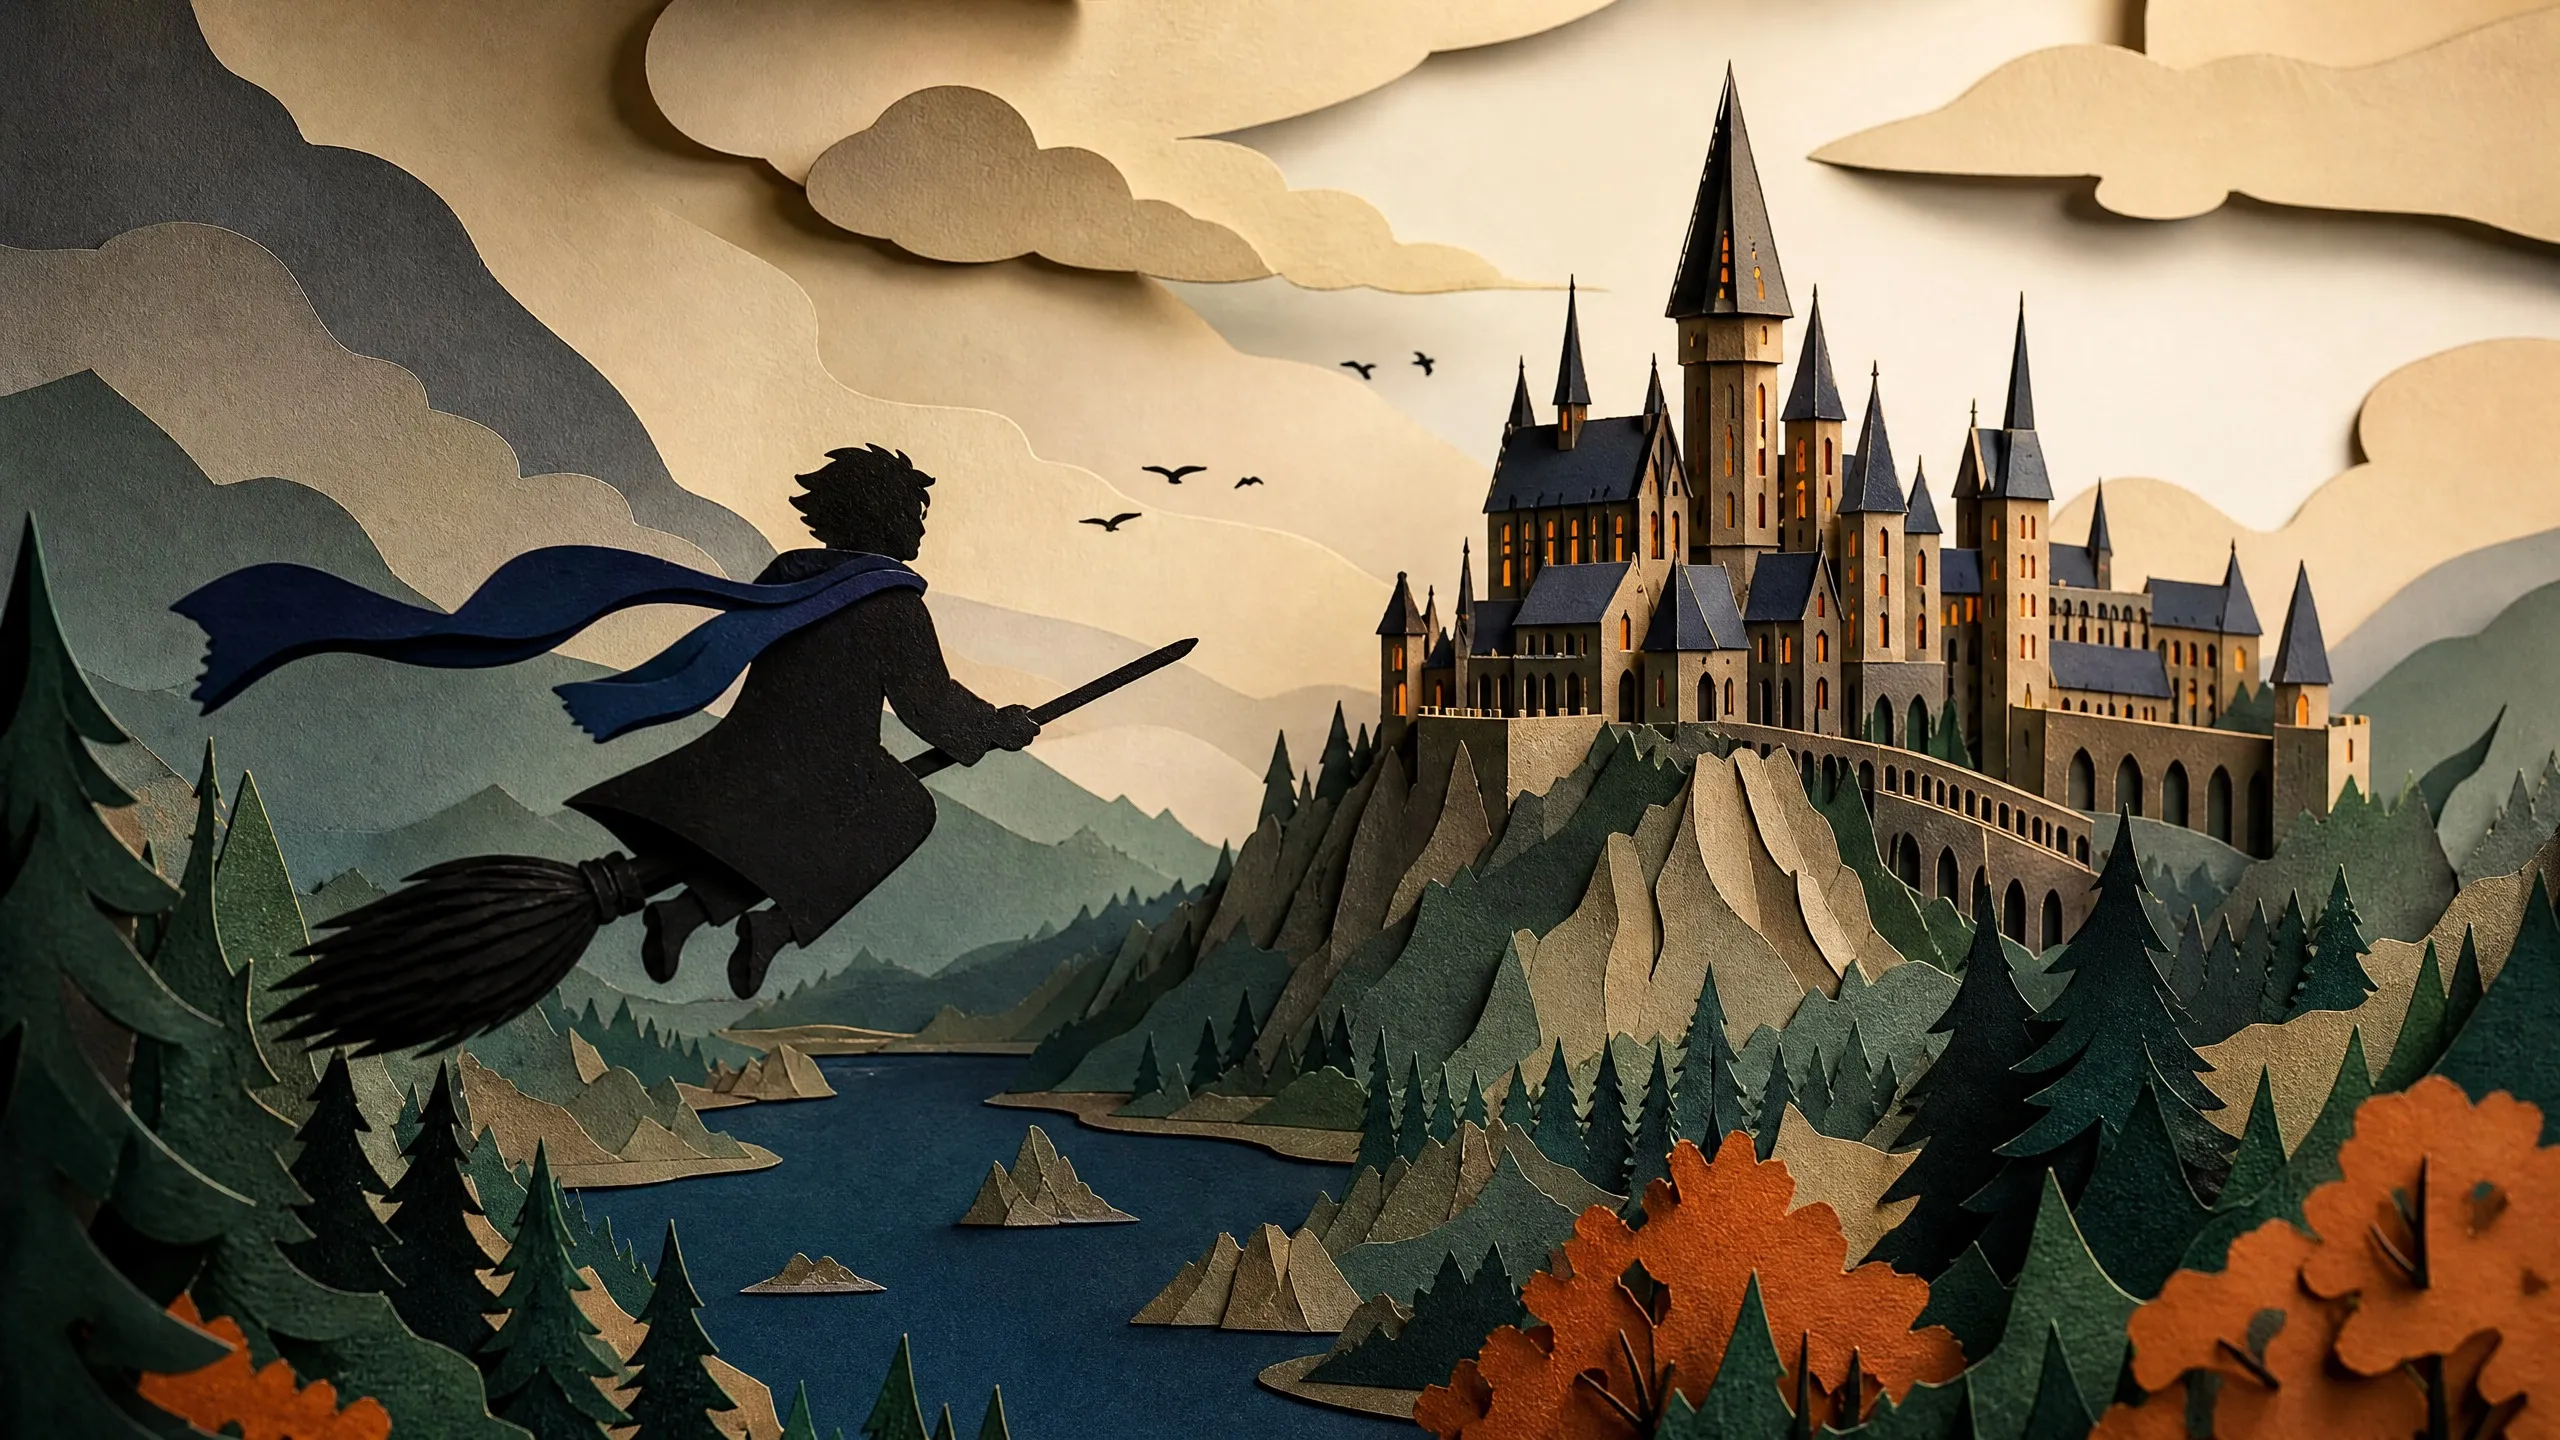
Hogwarts Broom Flight Simulator
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Jabberwock
Dark fantasy encounter testing creature design, forest mood, and narrative staging.

Low Poly World
Stylized island build testing composition, color, and low-poly worldbuilding.

Office Life
Workplace vignette testing everyday scene logic, objects, and believable office detail.

Petri Dish
Microscopic ecosystem testing organic forms, scientific clarity, and cellular detail.

Universe Simulator
Cosmic system testing orbital structure, glowing bodies, scale, and simulation readability.

Vice City
Neon coastal city testing vehicles, architecture, atmosphere, and dense urban layout.
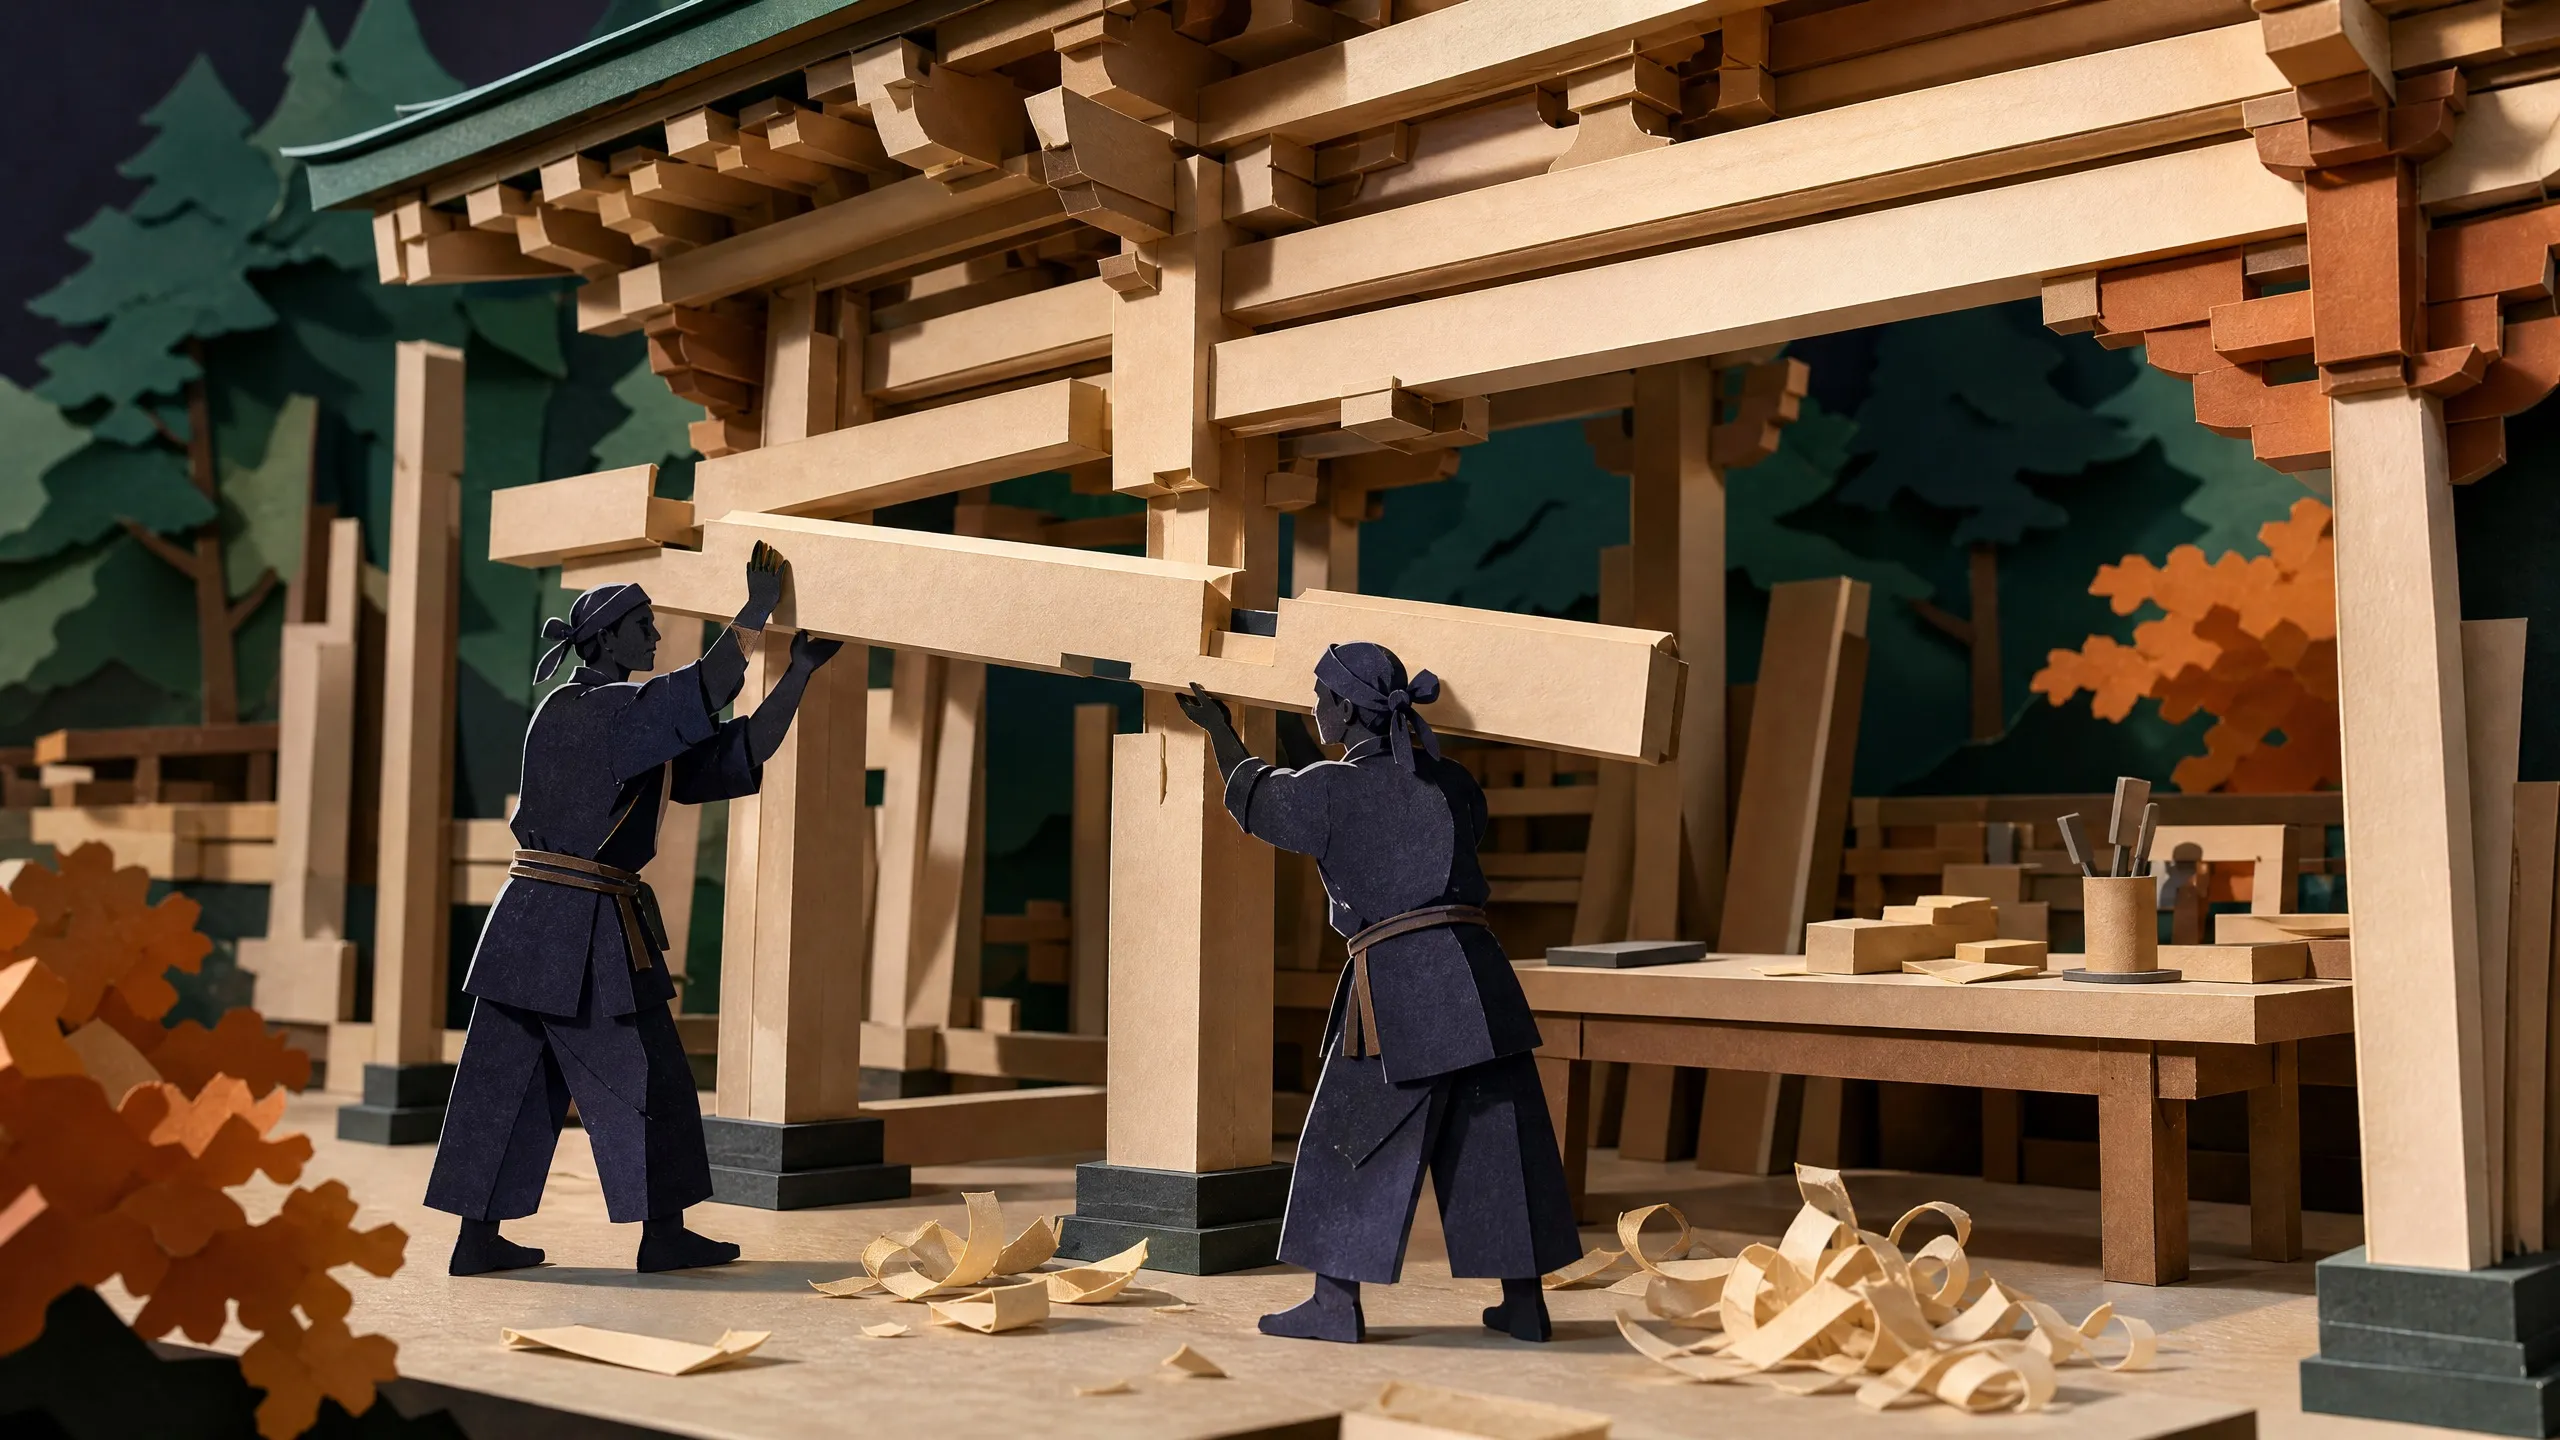
Yingzao Fashi Assembly
Timber assembly scene testing structure, joinery, construction order, and material clarity.
How GPT-5.6 Terra compares
Three relevant peers, side by side.
- GPT-5.6 Terra This model
- Claude Opus 4.8
- GPT-5.5
- GPT-5.6 Luna
6 benchmarks · 4 models
Official benchmark profile
Published scores outside our visual tests
SWE-bench Pro
63.4%Terminal-Bench 2.1
87.4%OSWorld 2.0
50.2%Full official benchmark table9 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| SWE-bench Pro | Coding | 63.4% | |
| Terminal-Bench 2.1 | Agentic coding | 87.4% | |
| OSWorld 2.0 | Computer use | 50.2% | |
| BrowseComp | Tool use | 87.5% | |
| BenchCAD | Computer-aided design | 62.3% | |
| BenchCAD with Python tool | Tool use | 78.2% | |
| GPQA Diamond | Academic reasoning | 92.9% | |
| FrontierMath Tier 1-3 v2 | Math | 84.9% | |
| FrontierMath Tier 4 v2 | Math | 68.3% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
gpt-5.6-terra- Context
- 1.05M
- Max output
- 128K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- OpenAI API Standard (≤272K input tokens) · USD / 1M tokens
- $2 input · $0.2 cached input · $2.5 cache write · $12 output
Above 272K input tokens, the full request costs $4 input, $0.4 cached input, $5 cache write, and $18 output per 1M tokens. Batch, Flex, Fast mode, and regional pricing differ.
Benchmark sources
OpenAI positions Terra as the capable lower-cost GPT-5.6 option. These rows use the shared GPT-5.6 comparison table so the scores line up against Sol, Luna, GPT-5.5, Claude, and Gemini where published.
GPT-5.6: Frontier intelligence that scales with your ambitionEvaluation settings
- Shared OpenAI GPT-5.6 comparison table.
- High-effort computer-use comparison table.
- High-effort browsing-agent comparison table.
- Vision2Code score without Python tool.
- Vision2Code score with Python tool.
- Shared reasoning benchmark table.
Editorial verdict
Where this model fits
GPT-5.6 Terra is the team’s A-tier default for more mundane implementation work. It costs less than GPT-5.5, and low-reasoning Terra is useful enough that the team rarely needs to fall back to Luna.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: GPT-5.6 Terra is currently placed in Tier A.
The September 2026 editorial roster places GPT-5.6 Terra at rank 6.
Open source →Related guides