OpenAI
GPT-5.5
Version 5.5 benchmark runs across the shared Superbash visual prompts.
API pricing
USD per million tokens · OpenAI API Standard (≤272K input tokens)- Input
- $5
- Output
- $30
- Cached input
- $0.5
- Context window
- 1.05M
Inspect the original visual runs
Open the generated scene to test it, or compare that prompt with another model.
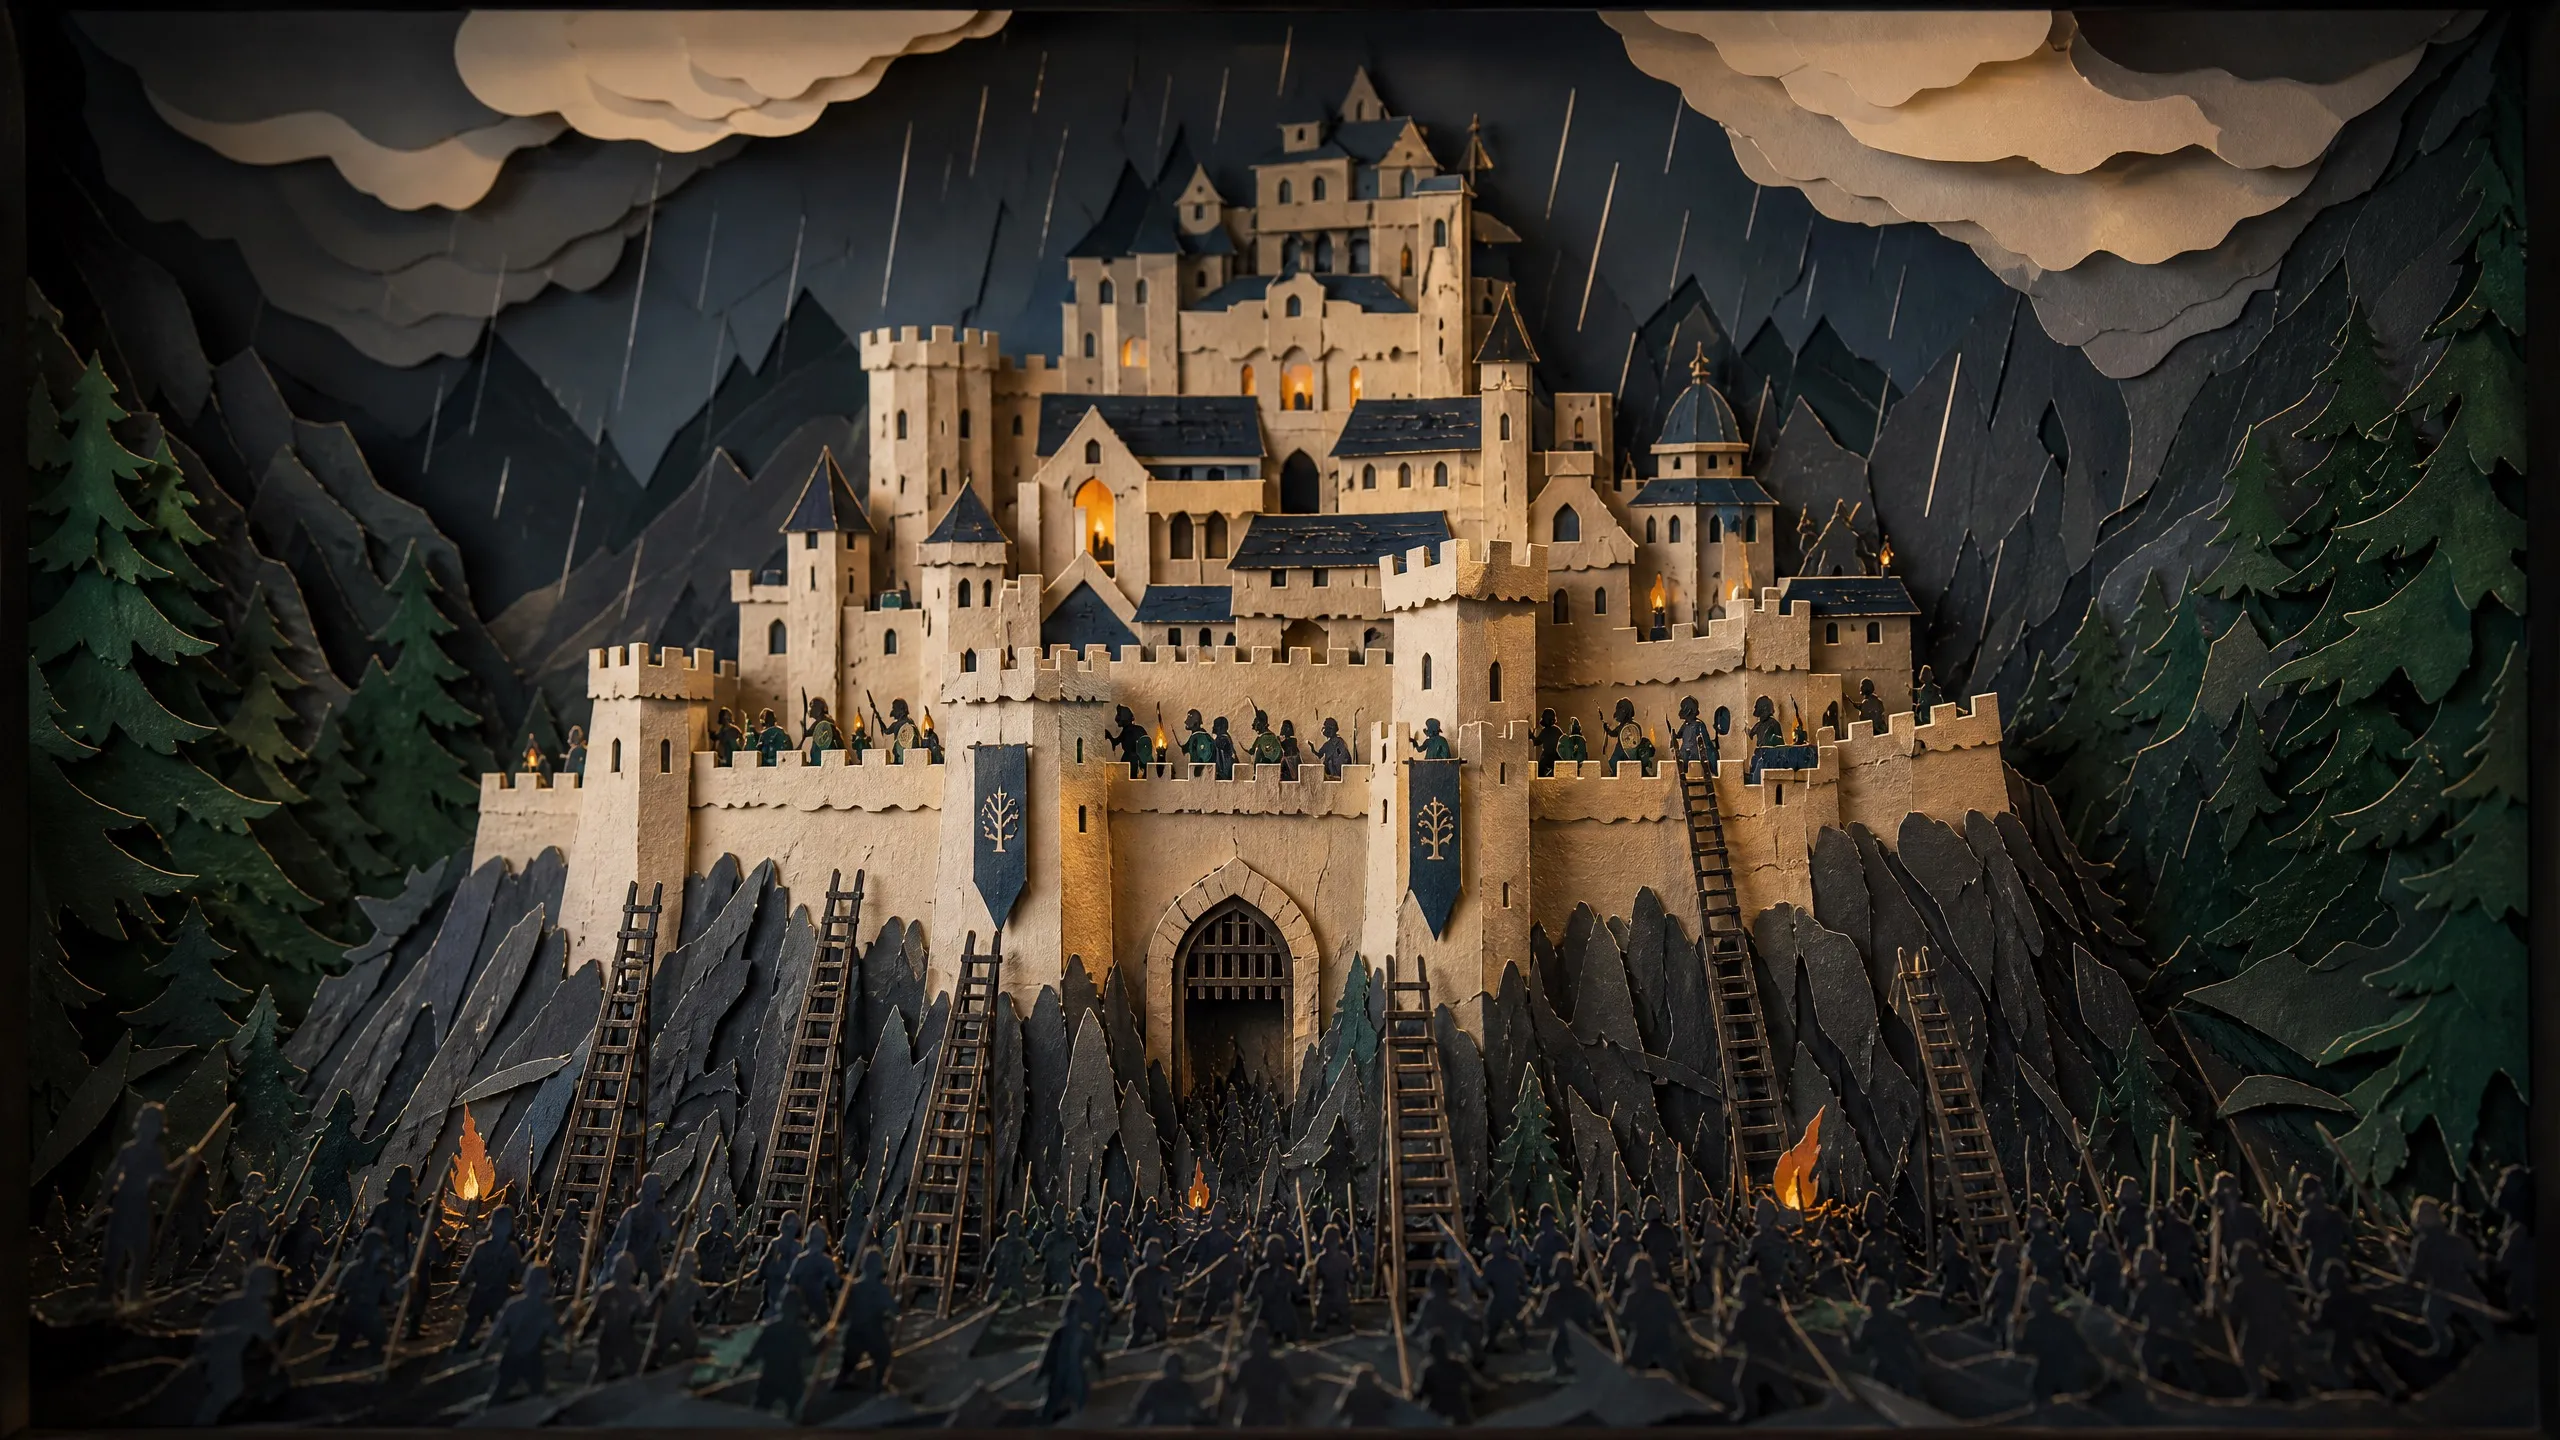
Helm's Deep
Run date: 2026-07-16
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
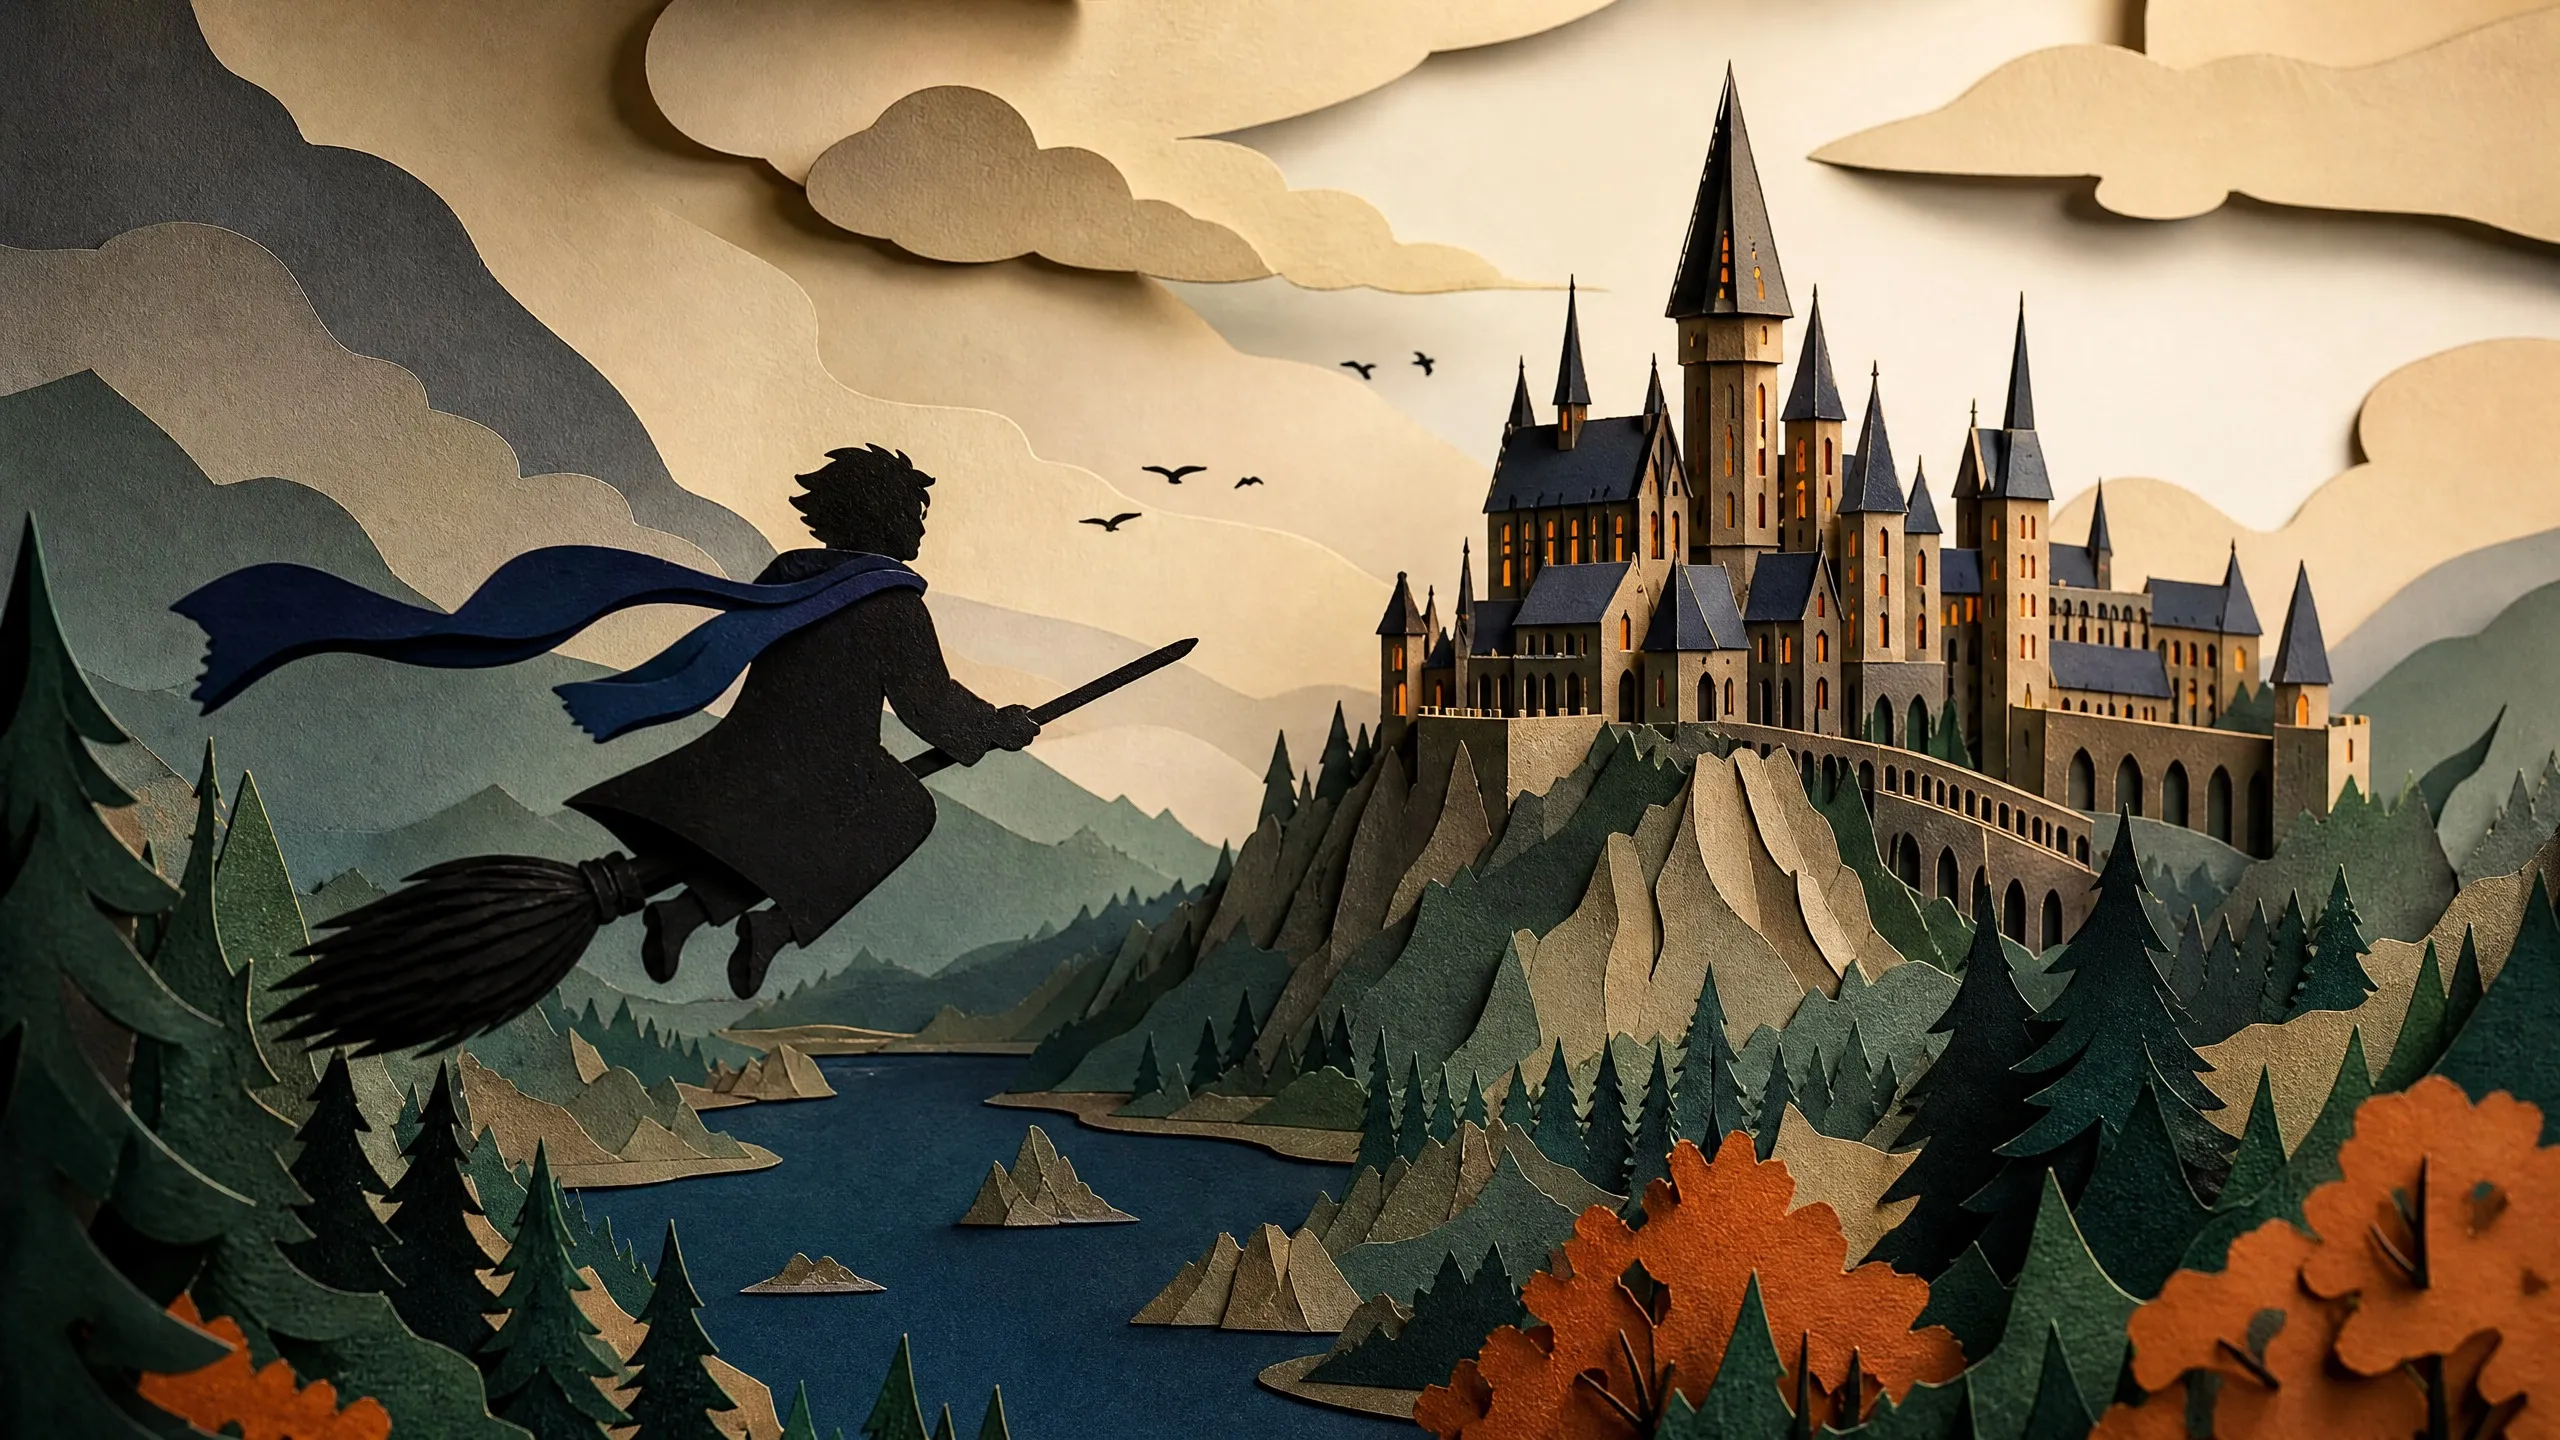
Hogwarts Broom Flight Simulator
Run date: 2026-07-09
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
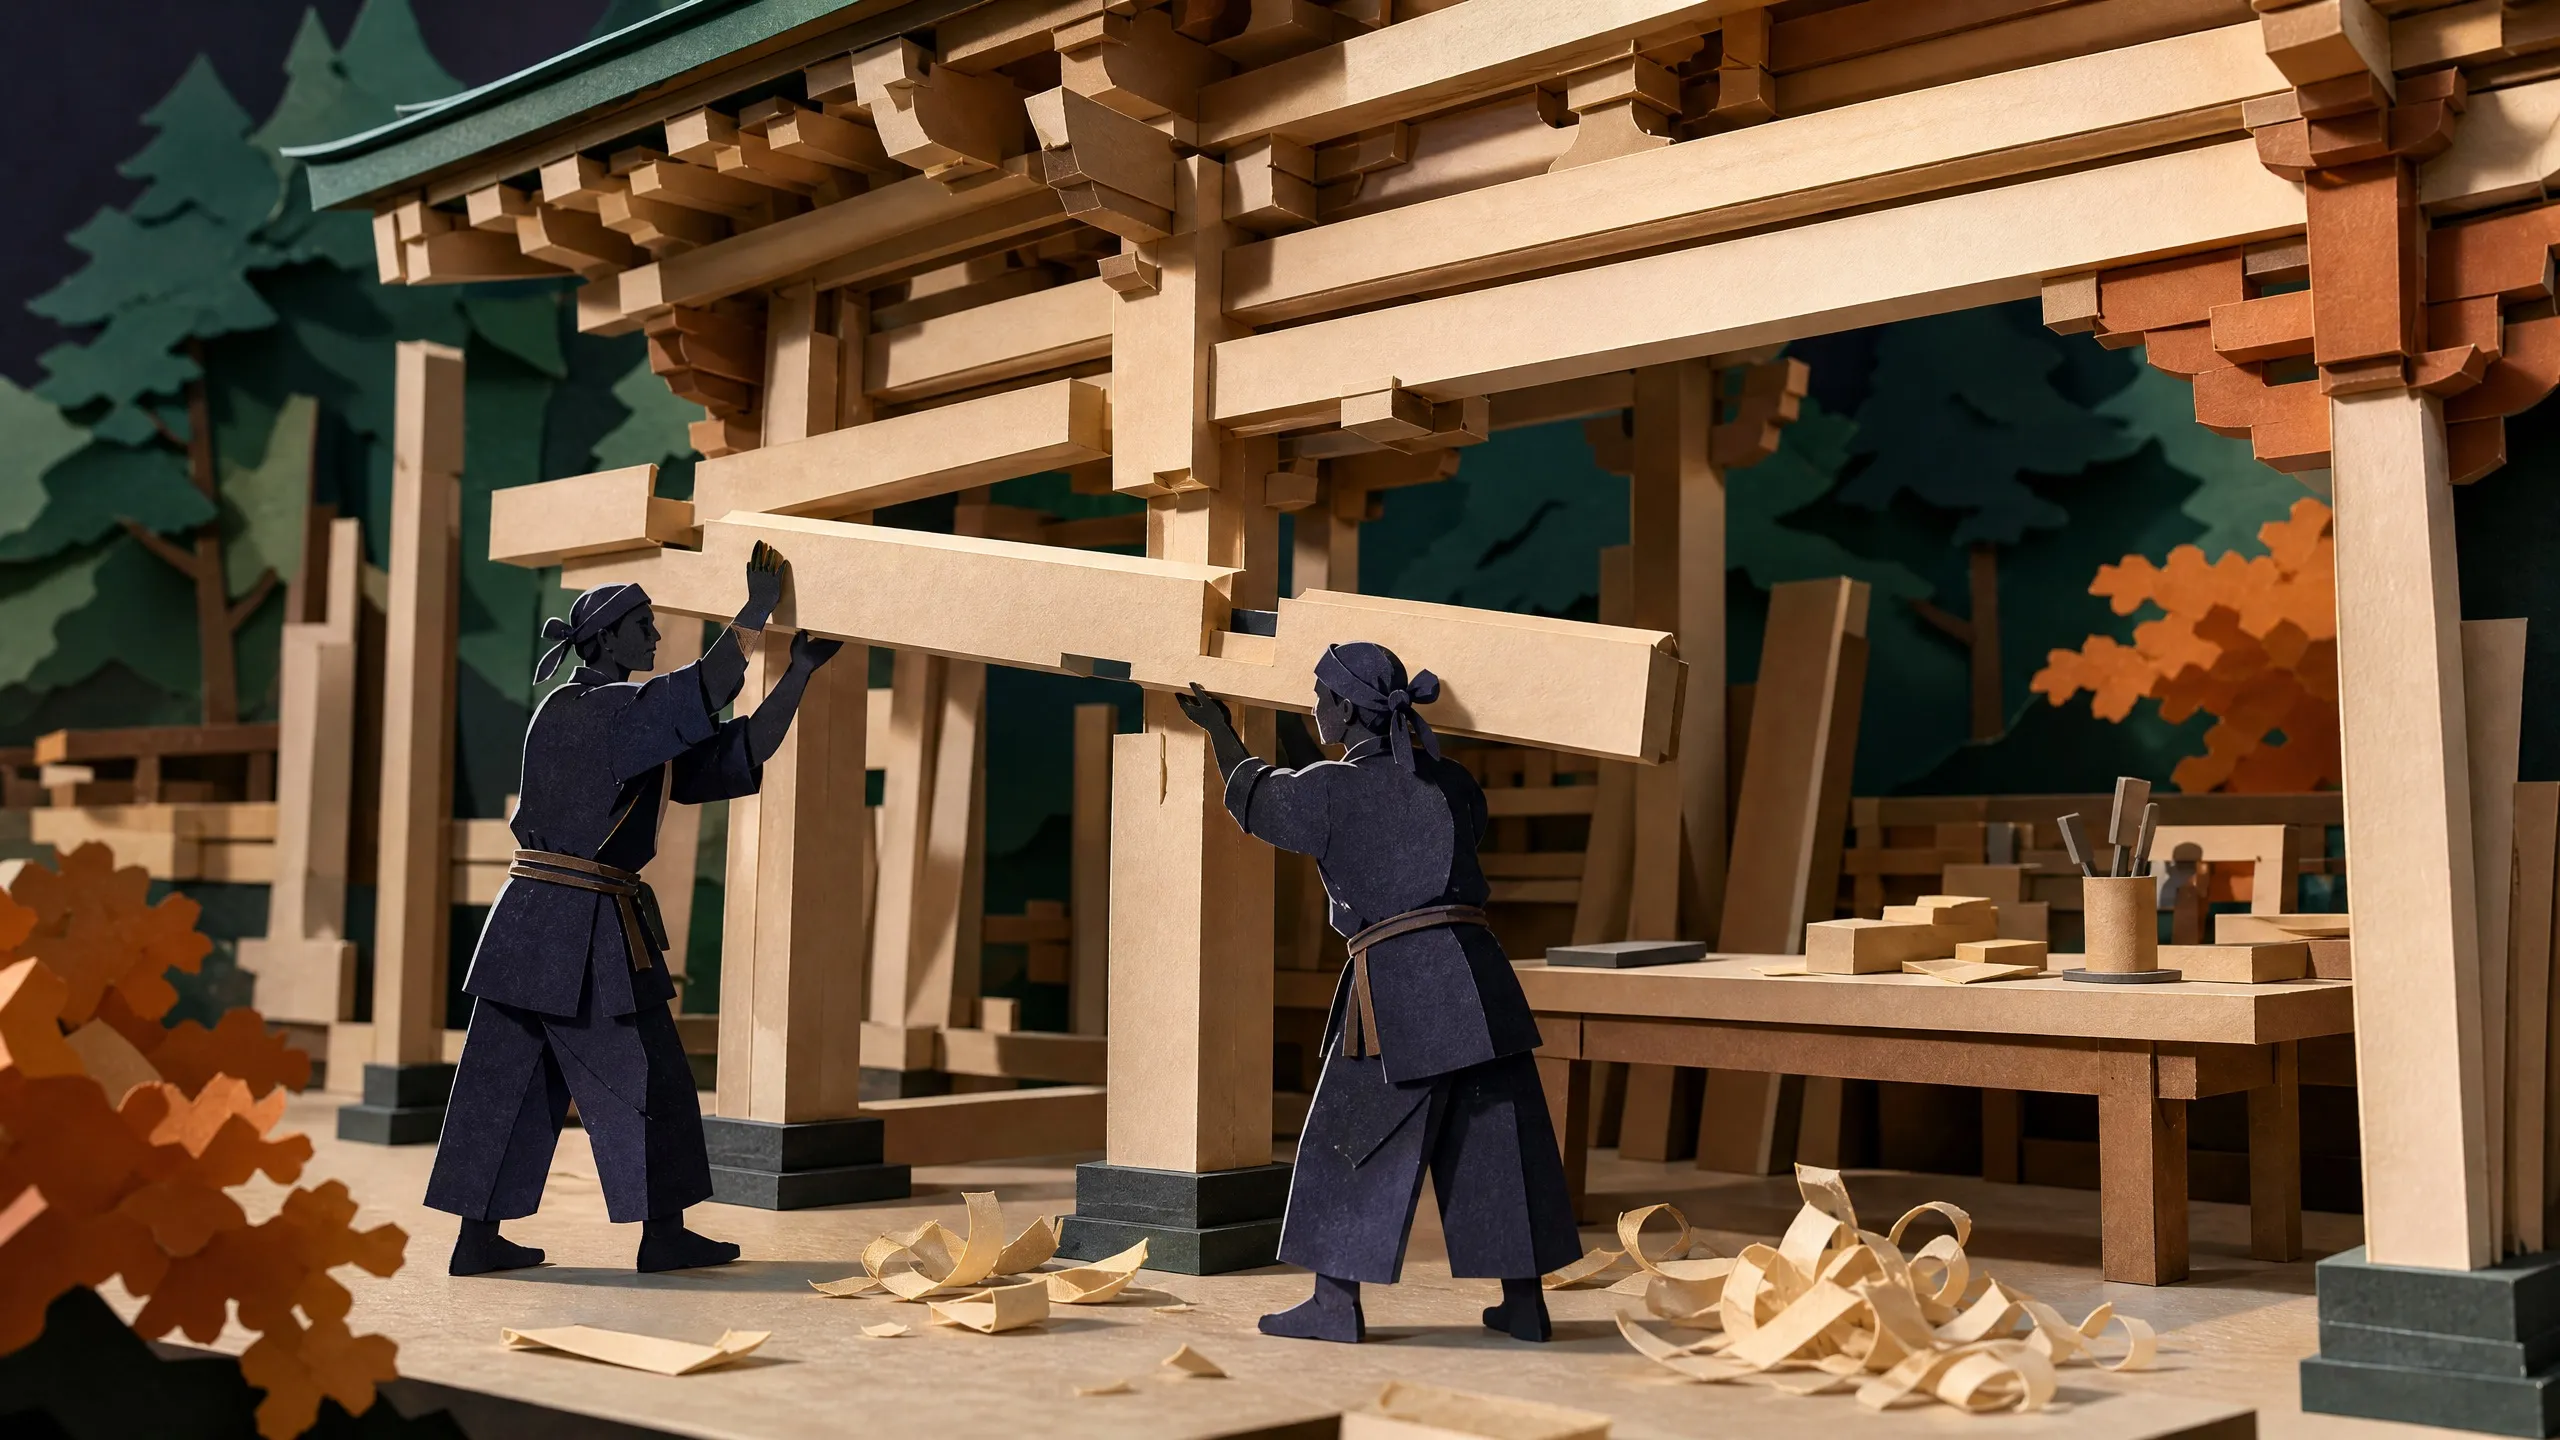
Yingzao Fashi Assembly
Run date: 2026-07-16
Specialist test · evaluated separately
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How GPT-5.5 compares
Three relevant peers, side by side.
- GPT-5.5 This model
- Claude Opus 4.8
- GPT-5.6 Luna
- GPT-5.6 Sol
6 benchmarks · 4 models
Official benchmark profile
Published scores outside our visual tests
SWE-bench Pro
58.6%Terminal-Bench 2.1
85.6%OSWorld 2.0
47.5%Full official benchmark table12 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| SWE-bench Pro | Coding | 58.6% | |
| Terminal-Bench 2.1 | Agentic coding | 85.6% | |
| OSWorld 2.0 | Computer use | 47.5% | |
| OSWorld-Verified | Computer use | 78.7% | |
| BrowseComp | Tool use | 84.4% | |
| BenchCAD | Computer-aided design | 44.4% | |
| BenchCAD with Python tool | Tool use | 59.4% | |
| GPQA Diamond | Academic reasoning | 93.6% | |
| FrontierMath Tier 1-3 v2 | Math | 85.3% | |
| FrontierMath Tier 4 v2 | Math | 72.5% | |
| GDPval | Professional work | 84.9% | |
| CyberGym | Cybersecurity | 81.8% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Superseded in this ranking
- API model ID
gpt-5.5- Context
- 1.05M
- Max output
- 128K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- OpenAI API Standard (≤272K input tokens) · USD / 1M tokens
- $5 input · $0.5 cached input · $30 output
Above 272K input tokens, input is $10 and output is $45 per 1M tokens for the full session. Regional processing adds 10%.
Benchmark sources
GPT-5.5 rows combine OpenAI’s launch benchmarks with shared GPT-5.6 comparison rows where those make the score directly comparable to newer models.
Introducing GPT-5.5Evaluation settings
- OpenAI GPT-5.5 launch score; the GPT-5.6 shared comparison table reports 59.4% on its comparison run.
- Shared GPT-5.6 comparison table.
- OpenAI GPT-5.5 launch score.
- Shared GPT-5.6 comparison table and GPT-5.5 launch result.
- Vision2Code score without Python tool from the shared GPT-5.6 table.
- Vision2Code score with Python tool from the shared GPT-5.6 table.
- OpenAI science reasoning result and shared GPT-5.6 table.