Xai
Grok 4.6
Version 4.6 benchmark runs across the shared Superbash visual prompts.
API pricing
USD per million tokens · xAI API (<200K input tokens)- Input
- $2
- Output
- $6
- Cached input
- $0.5
- Context window
- 500K
Inspect the original visual runs
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-08-14
Specialist test · evaluated separately
Generation provenance: unrecorded
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Run date: 2026-08-14
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
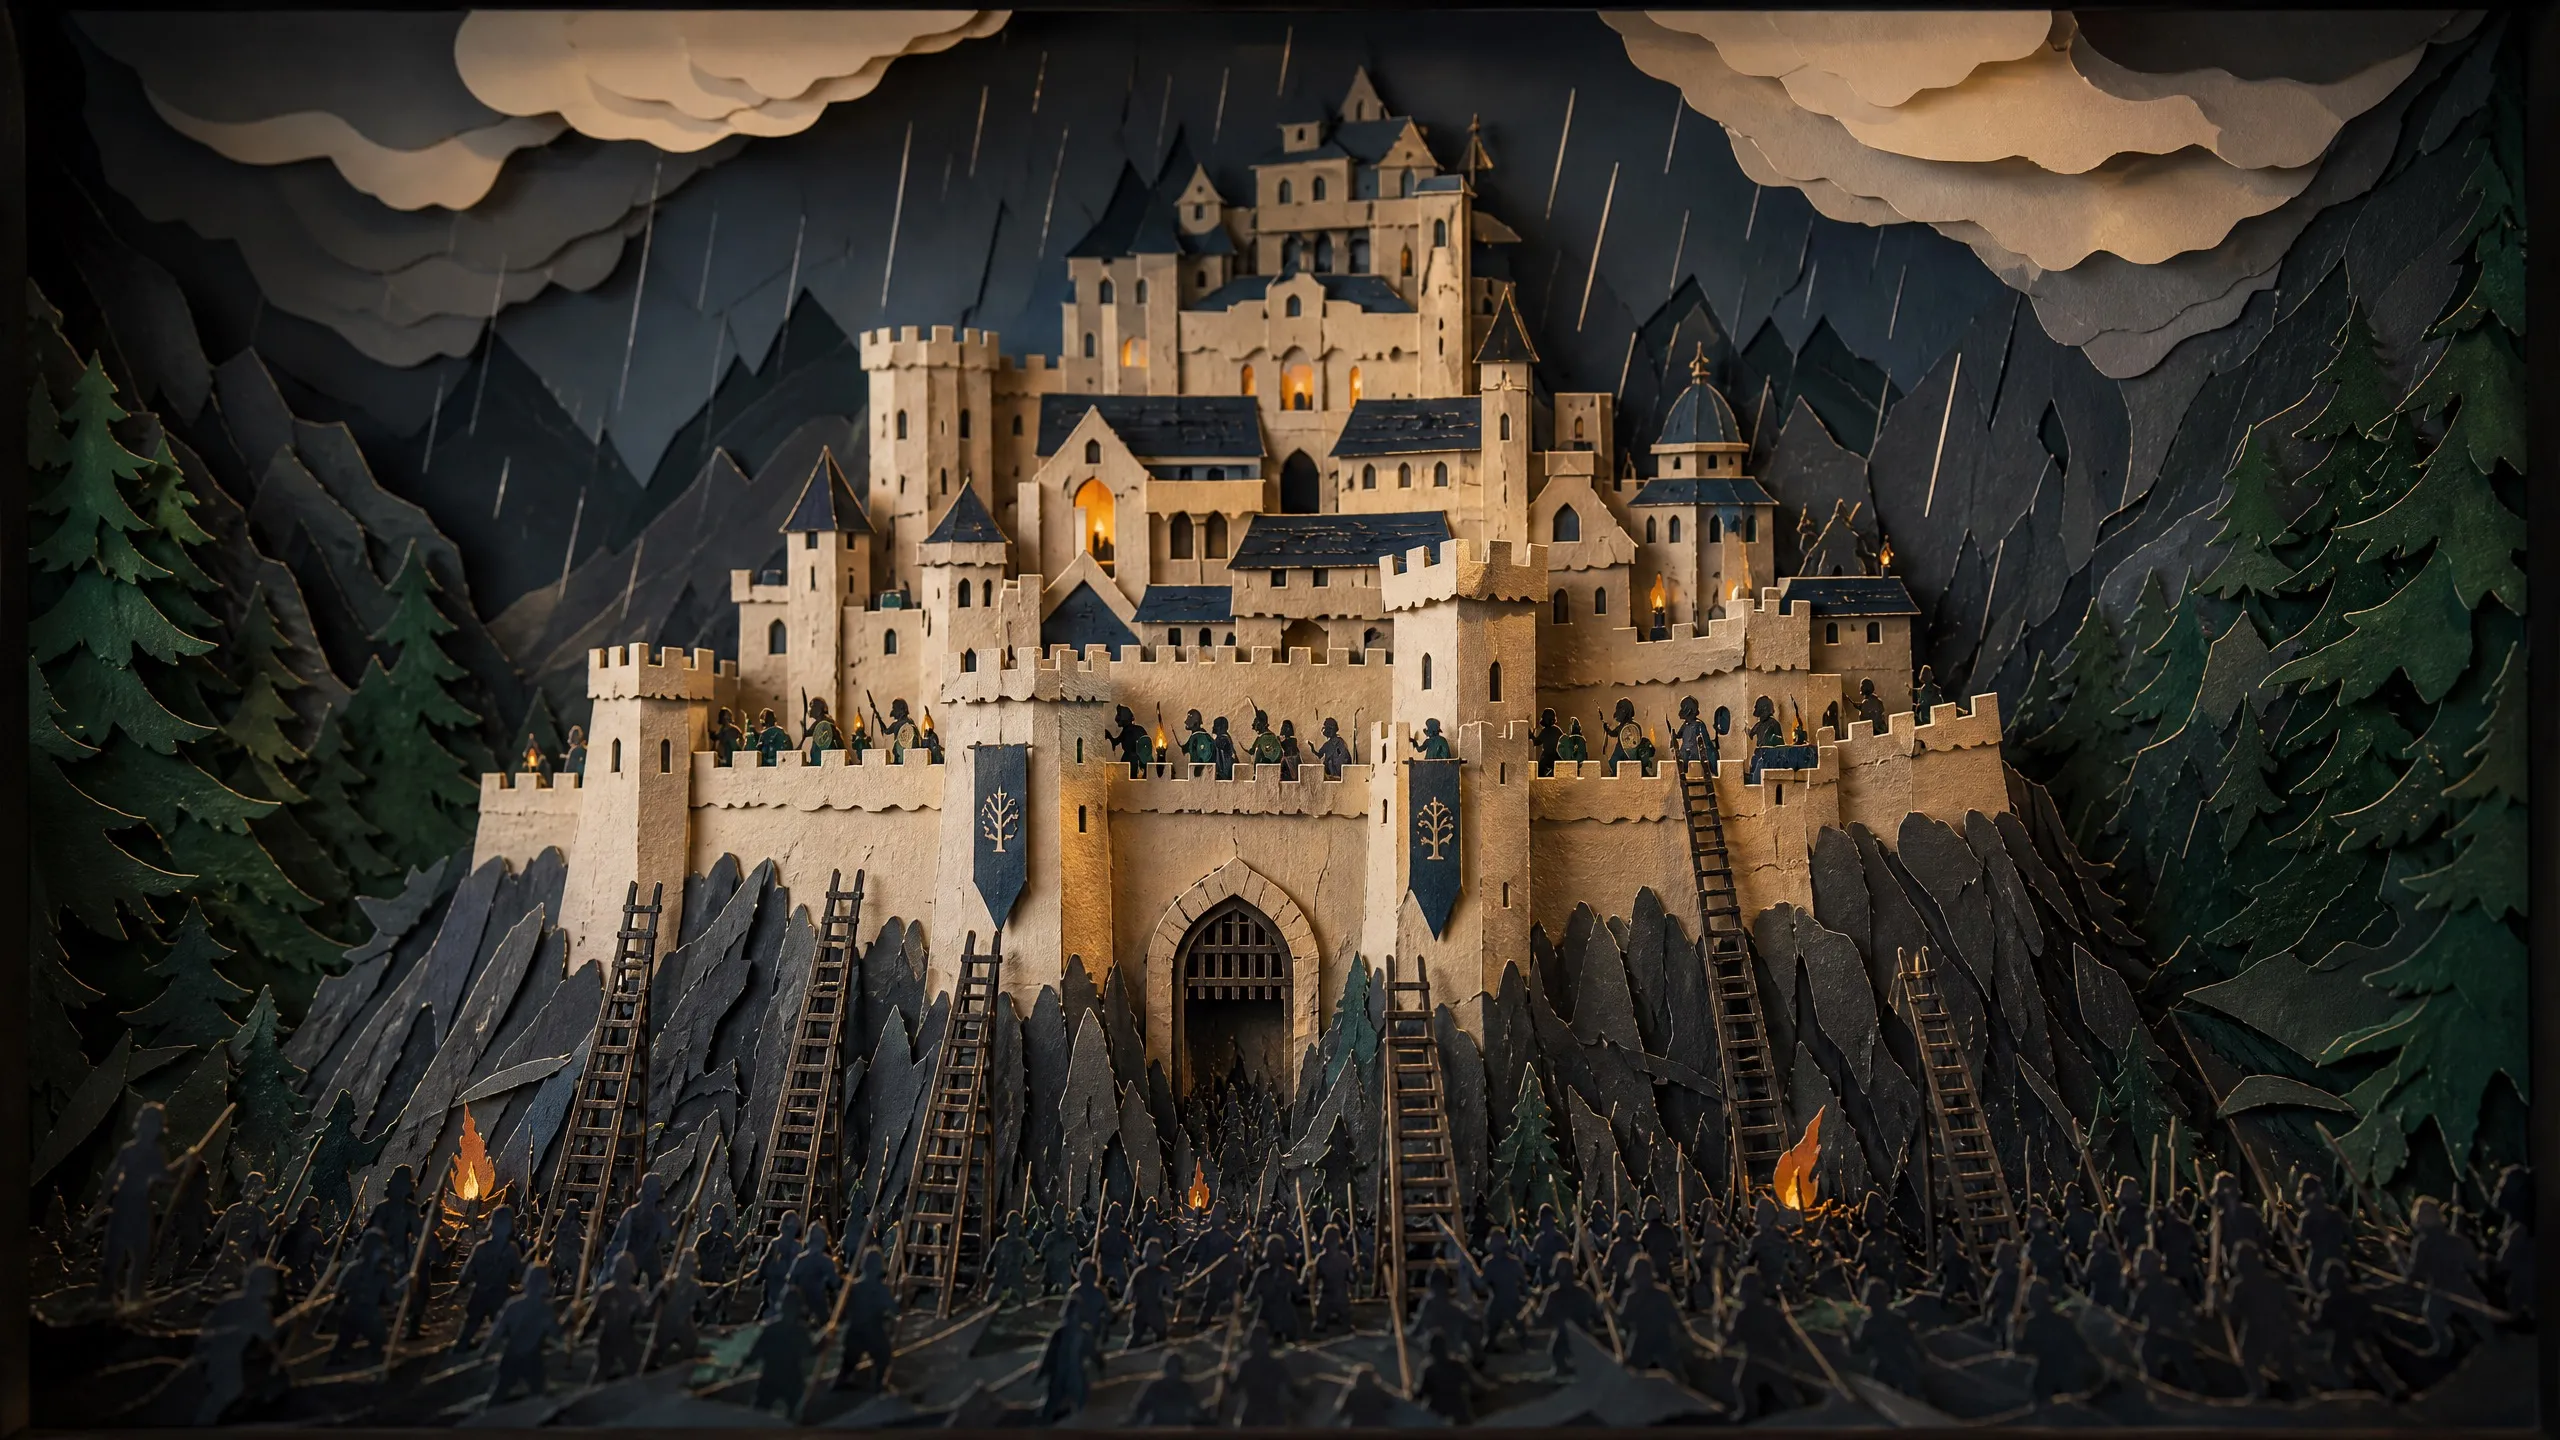
Helm's Deep
Run date: 2026-08-14
Generation provenance: unrecorded
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
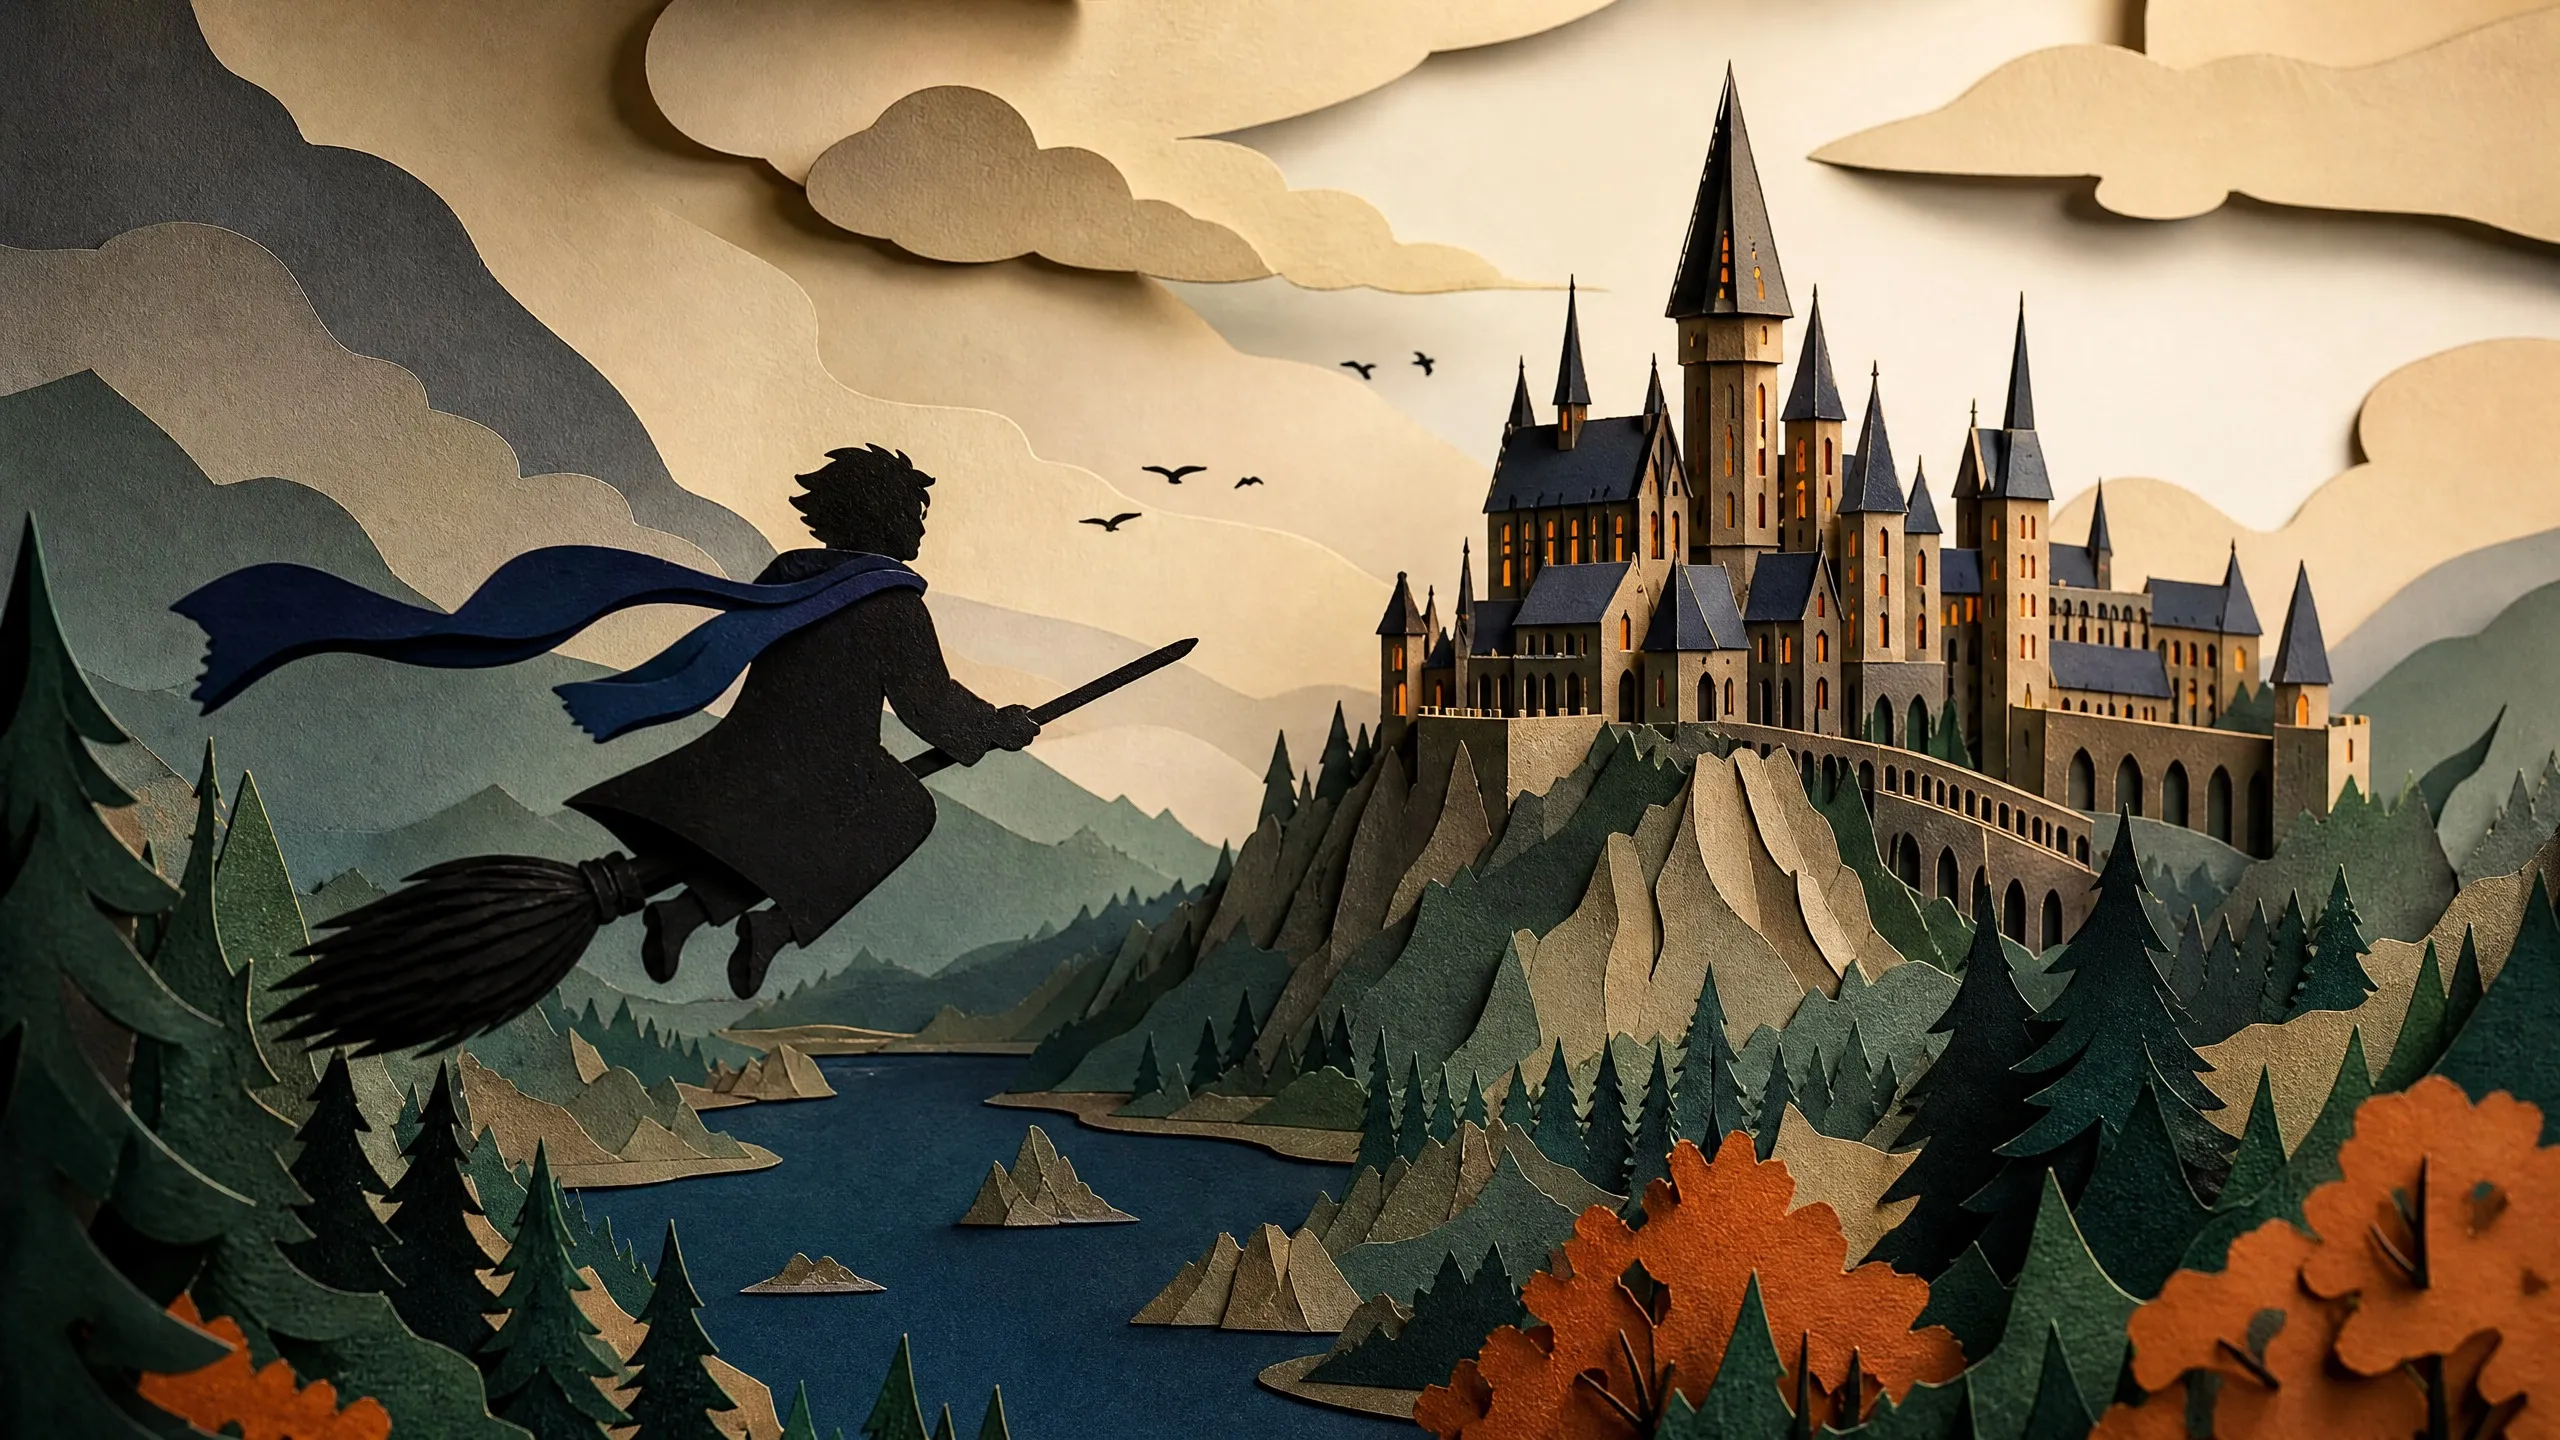
Hogwarts Broom Flight Simulator
Run date: 2026-08-14
Generation provenance: unrecorded
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Low-Poly Tower Defense
Run date: 2026-08-14
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
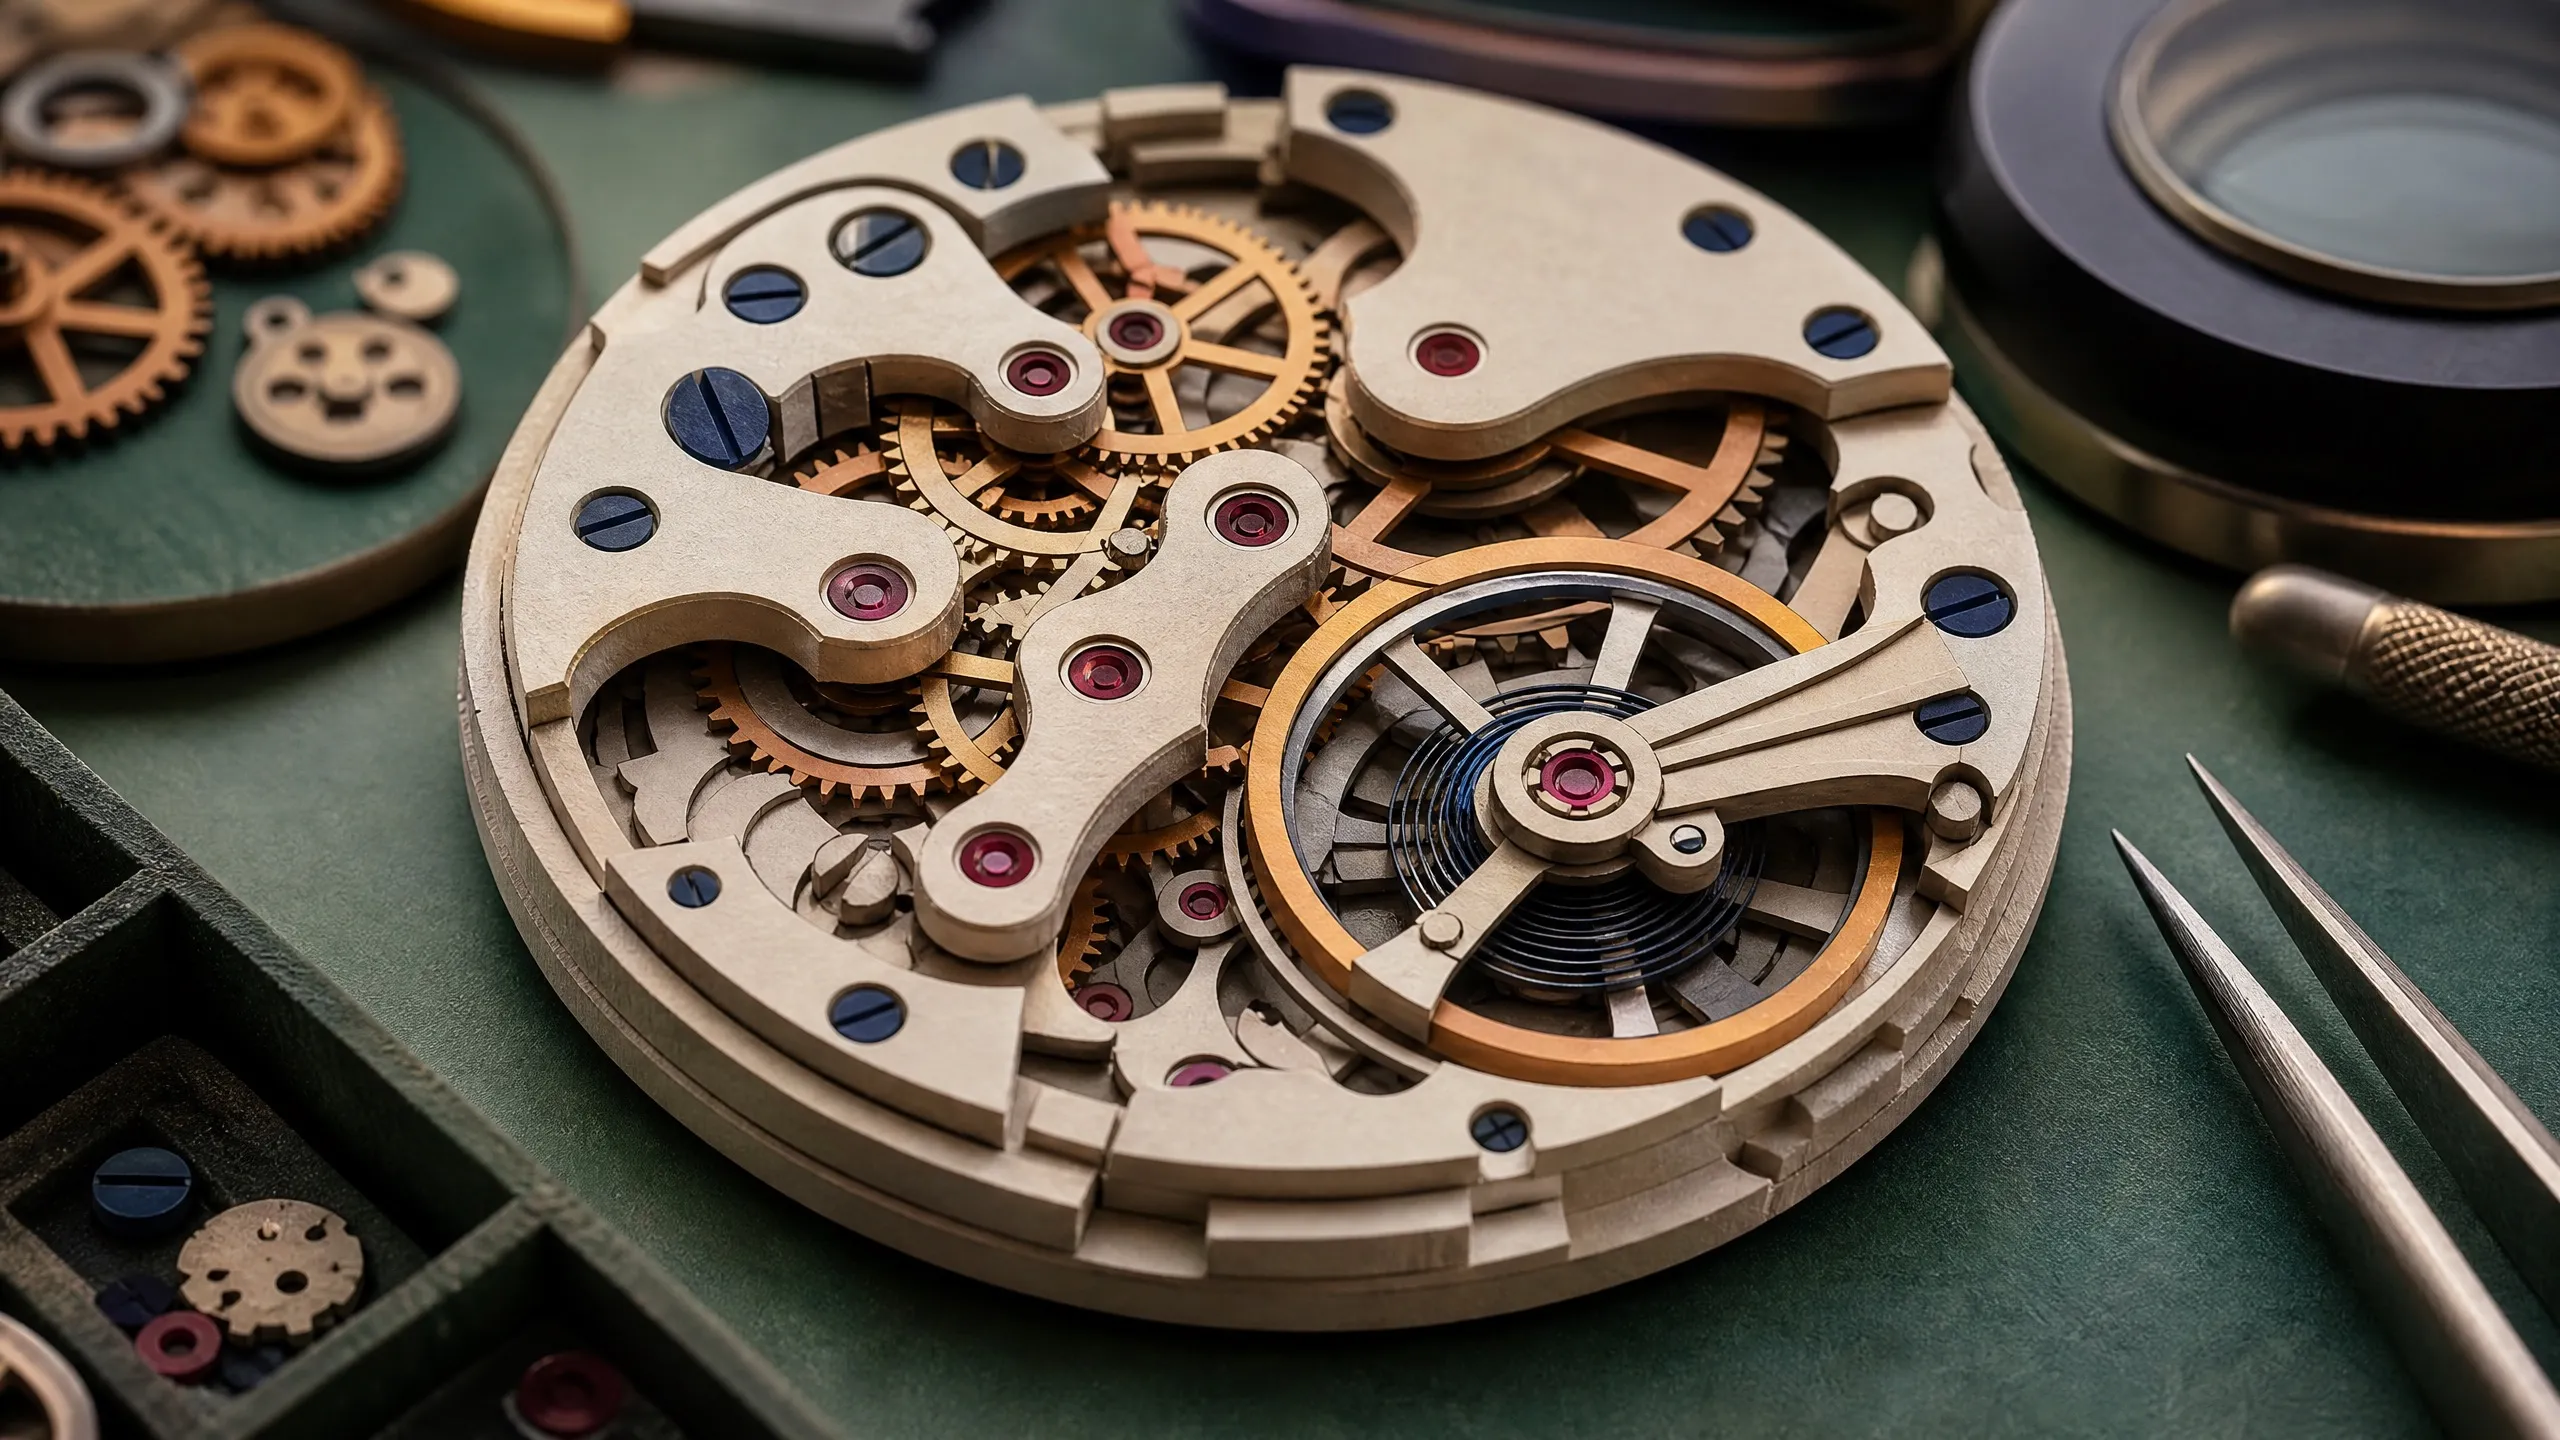
Mechanical Watch Simulator
Run date: 2026-08-14
Generation provenance: unrecorded
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Run date: 2026-08-14
Generation provenance: unrecorded
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-08-14
Generation provenance: unrecorded
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
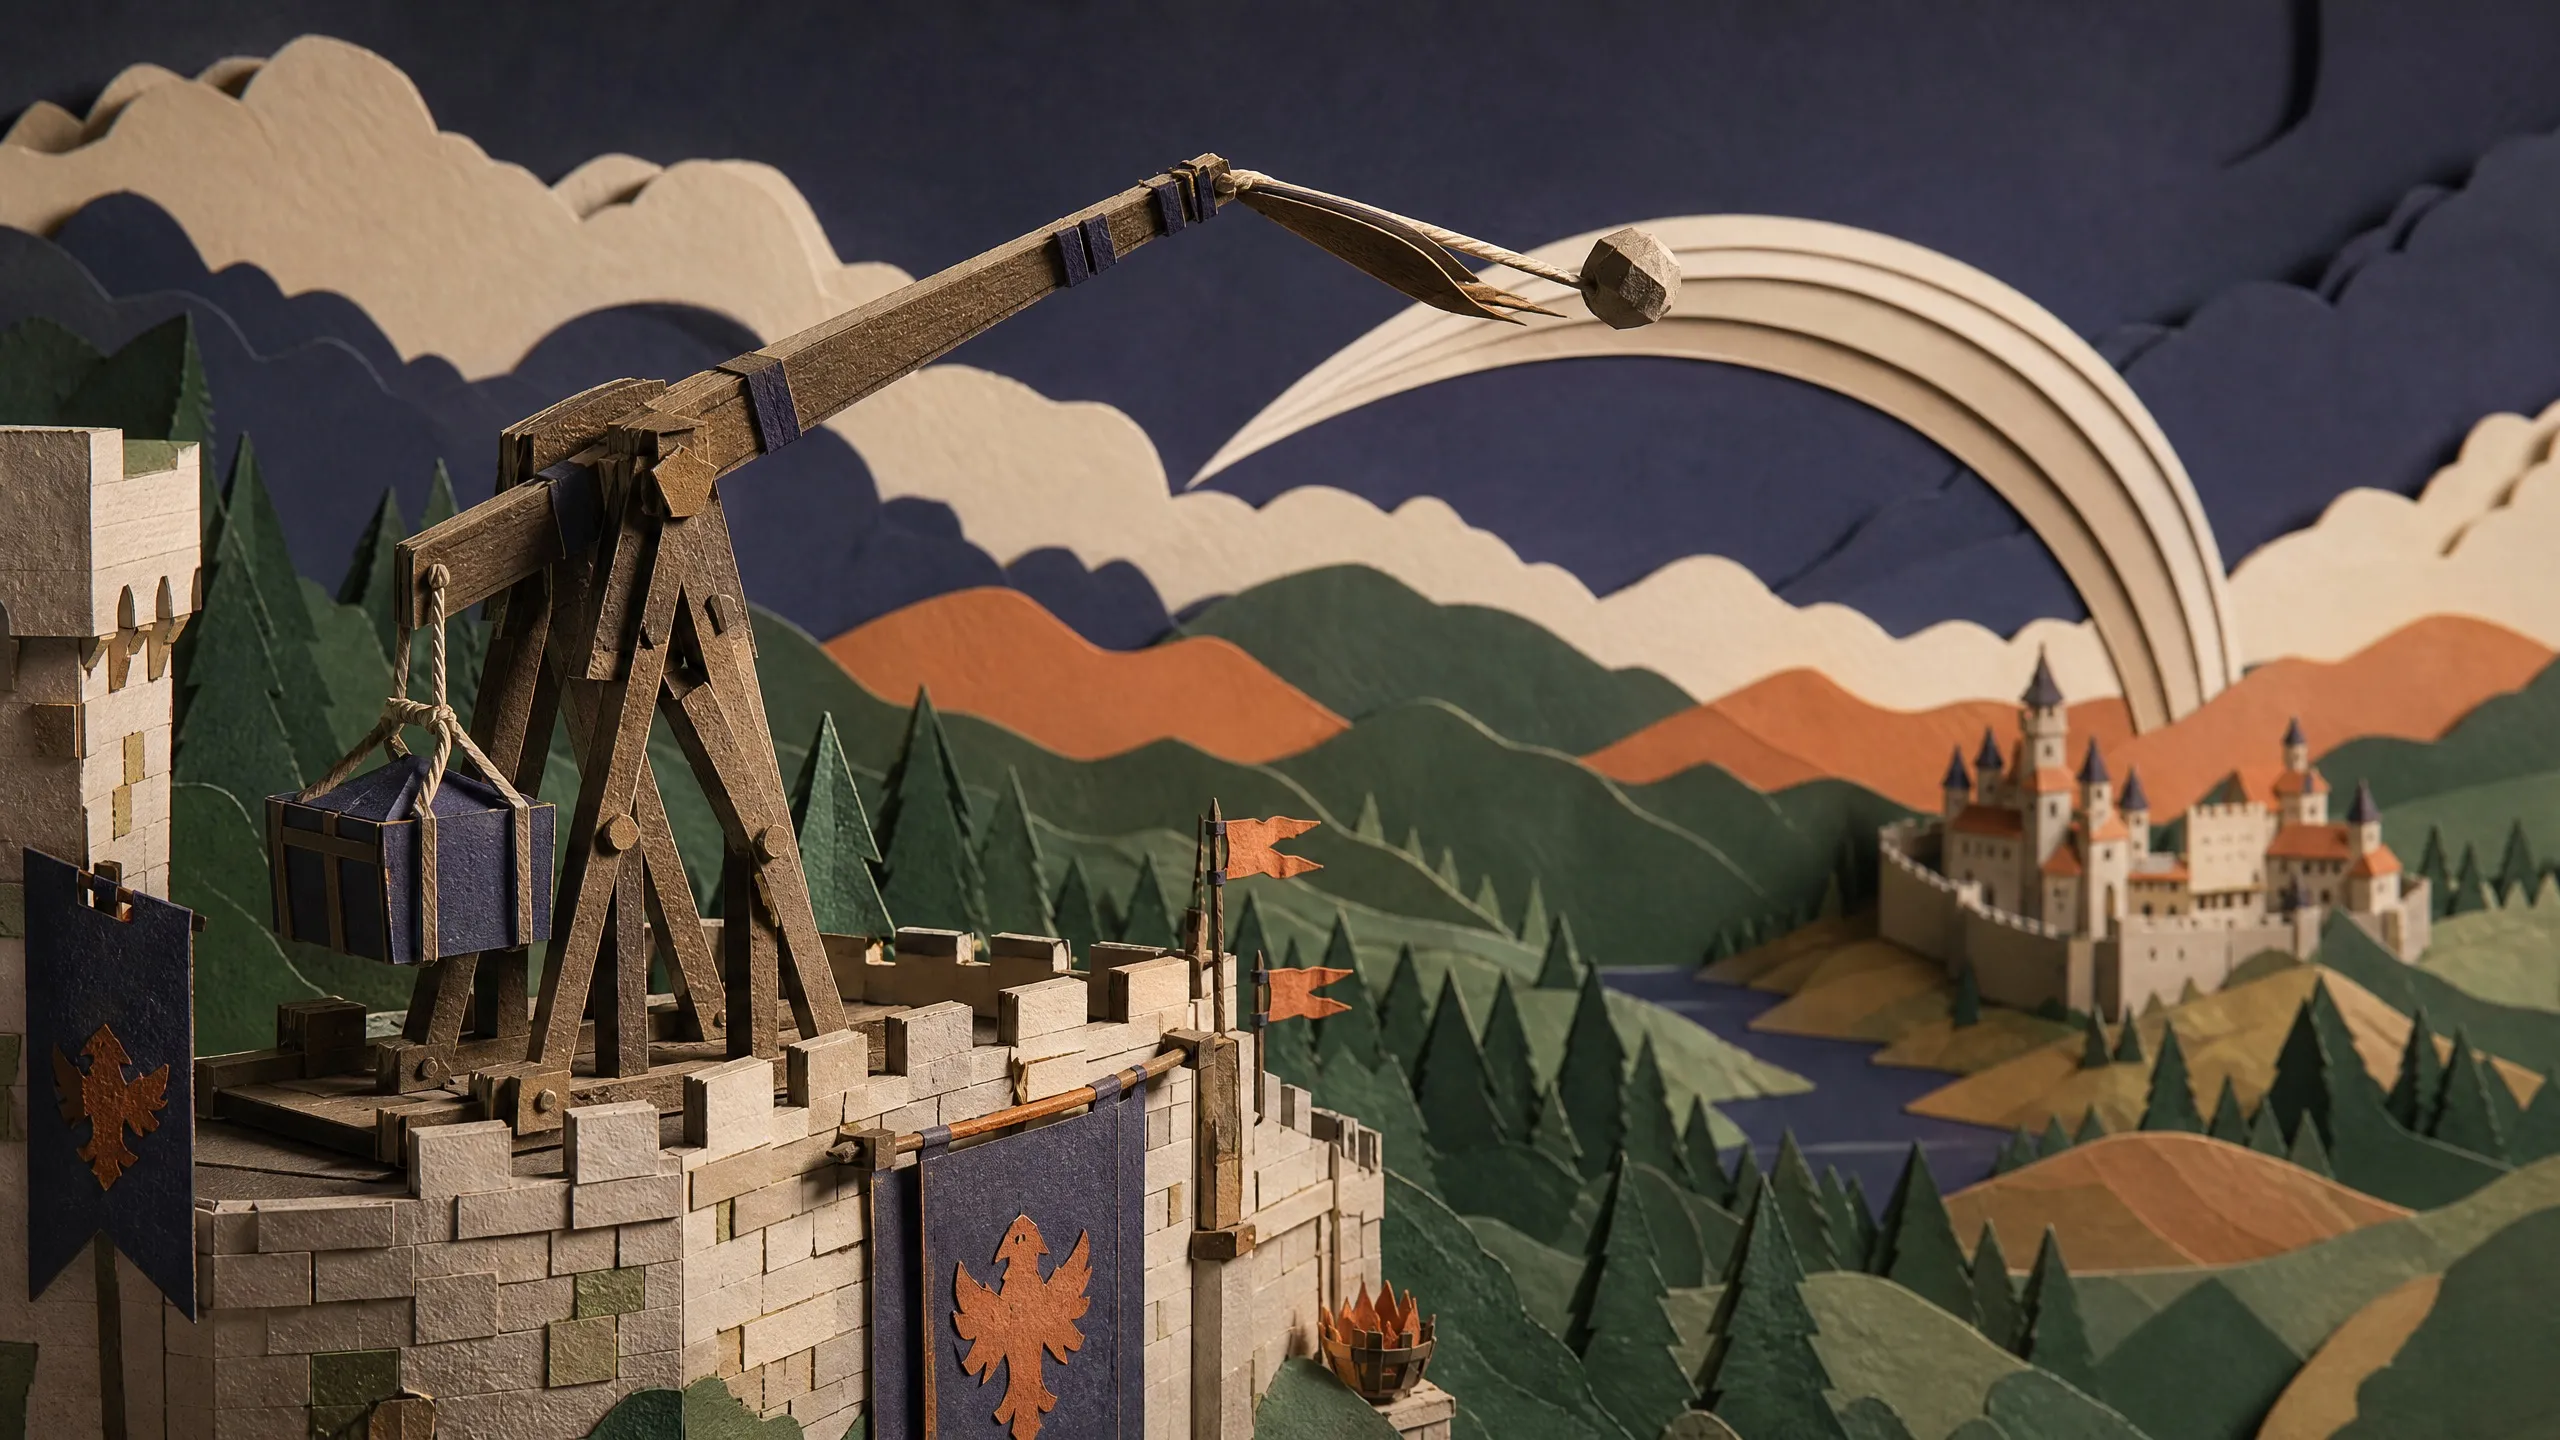
Stormwind Trebuchet Simulator
Run date: 2026-08-14
Generation provenance: unrecorded
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
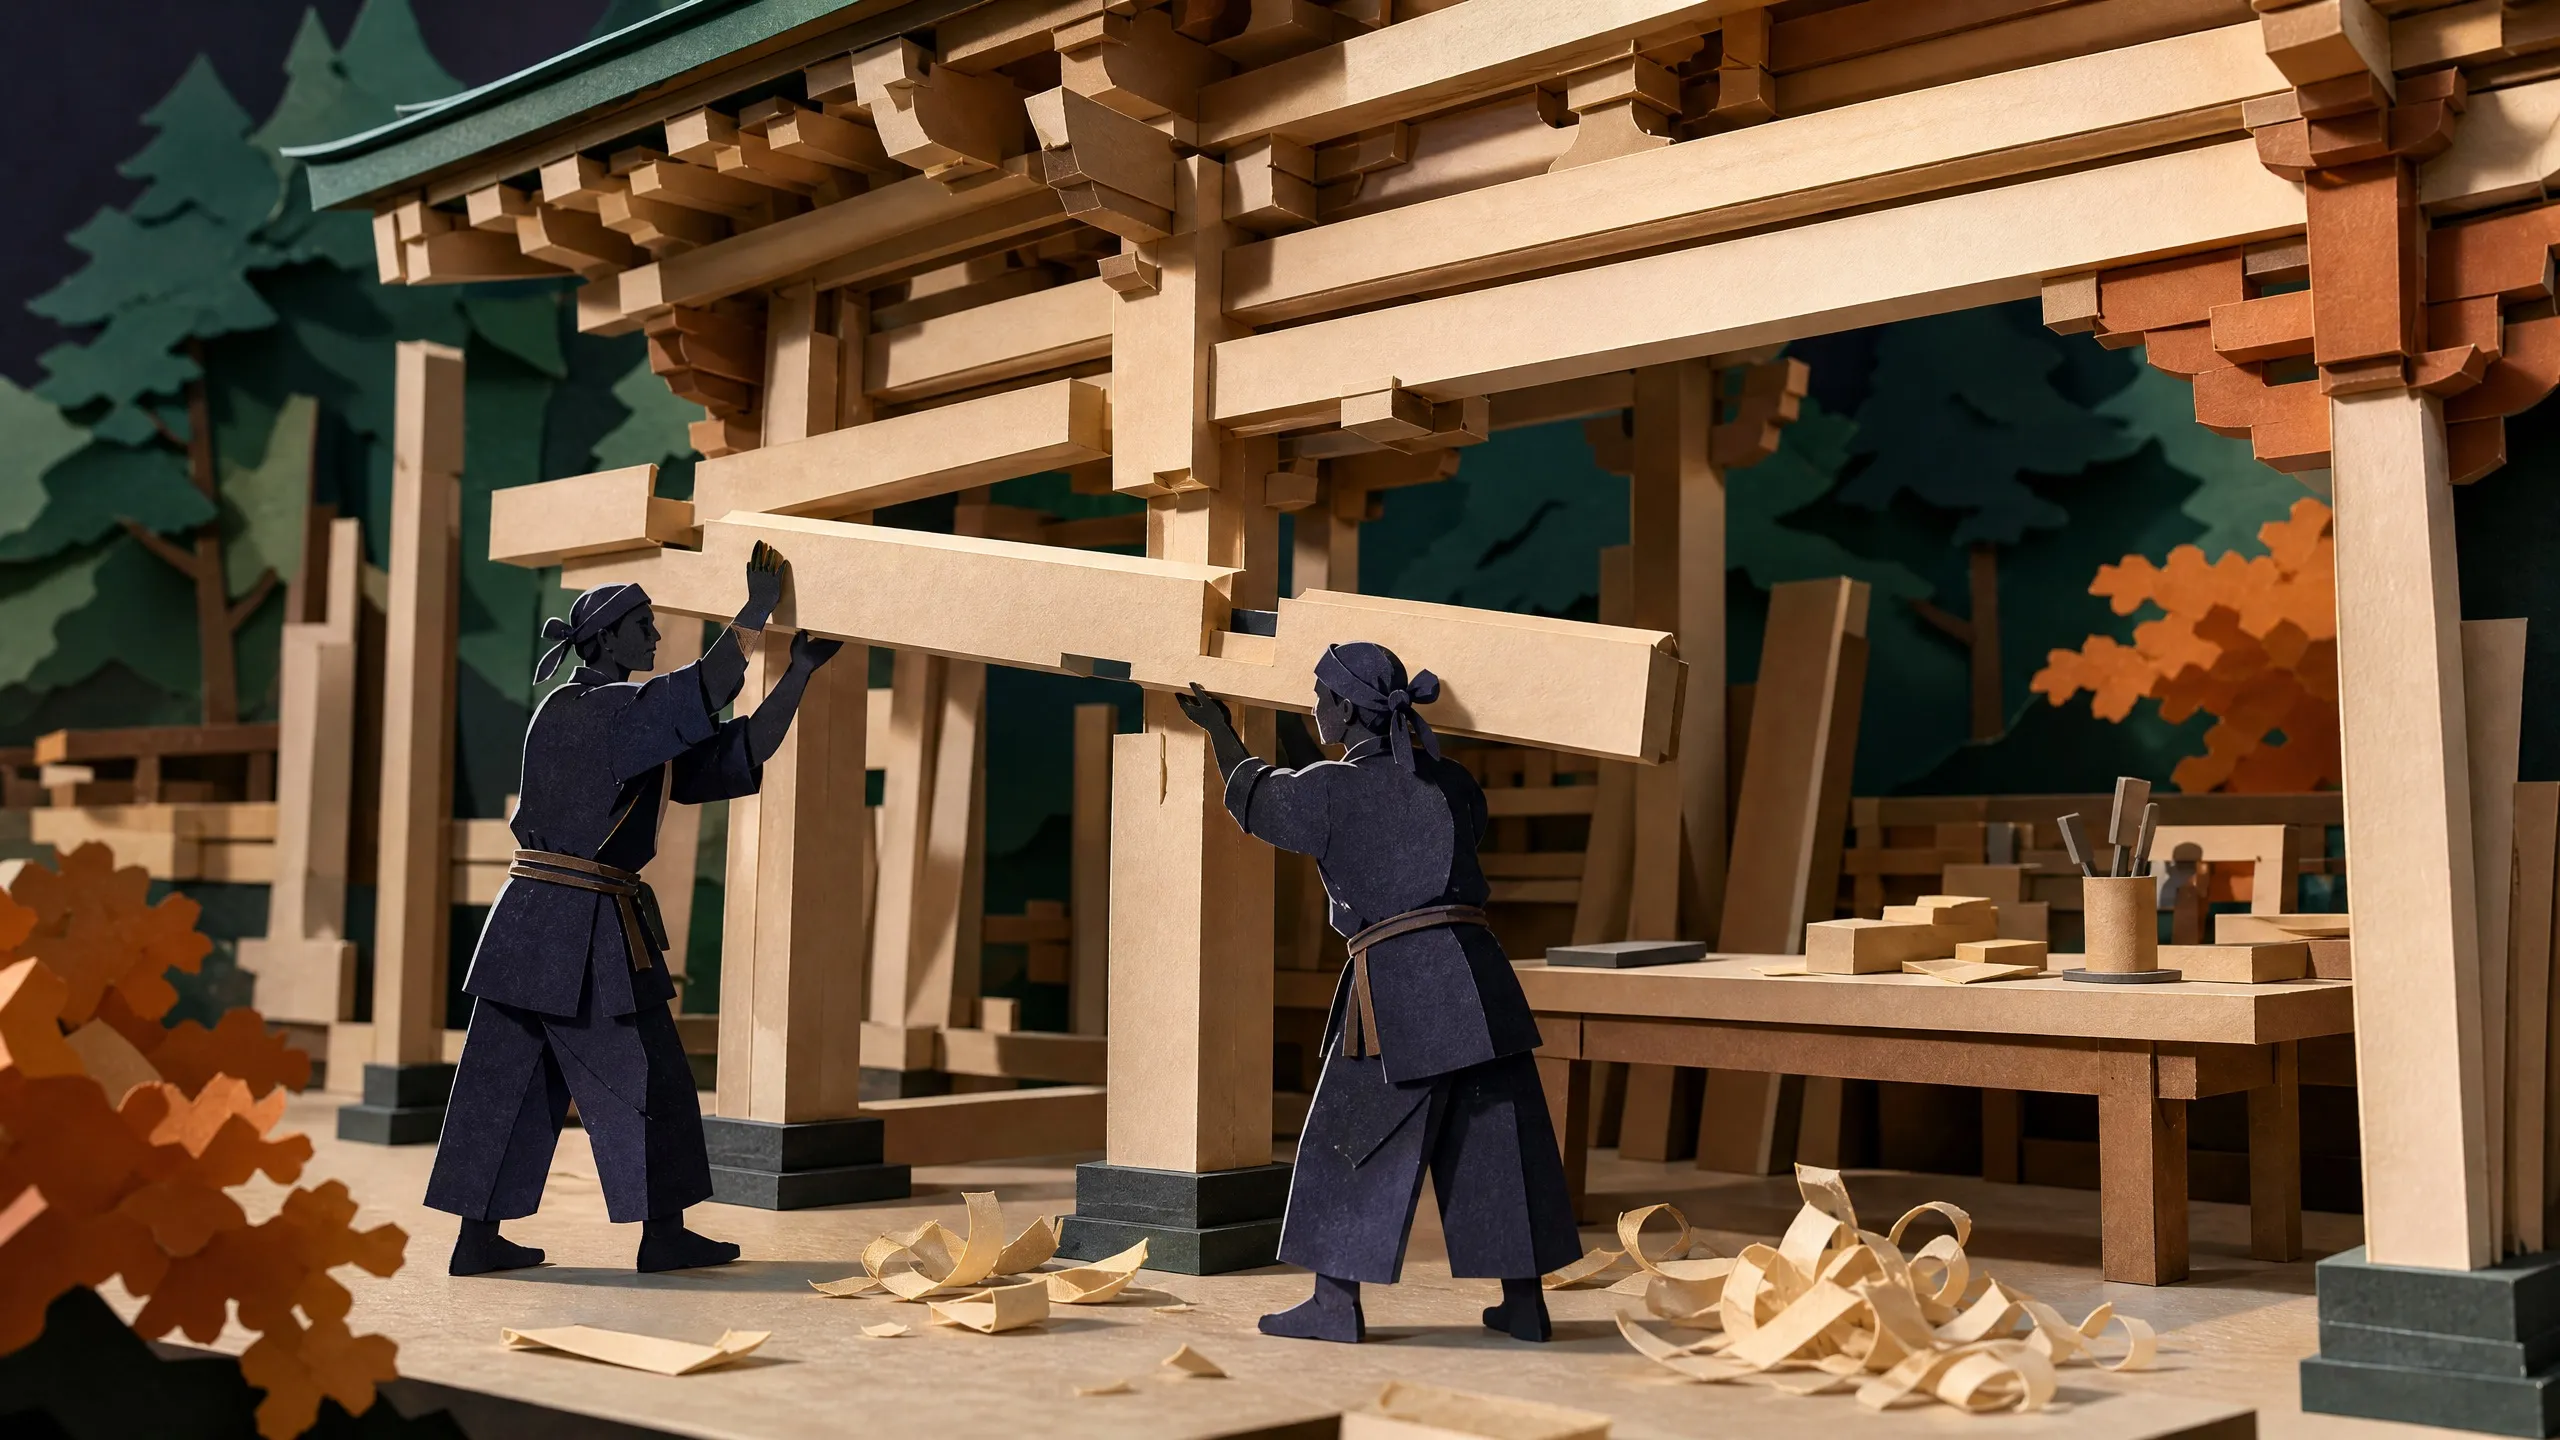
Yingzao Fashi Assembly
Run date: 2026-08-14
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How Grok 4.6 compares
Three relevant peers, side by side.
- Grok 4.6 This model
- Fable 5 Max
- Grok 4.5
- GPT-5.6 Sol
6 benchmarks · 4 models
Official benchmark profile
Grok 4.6’s published agentic coding and knowledge-work results.
AA Intelligence Index
61GDPVal-AA v2
1753CursorBench v3.2
69.9%Full official benchmark table10 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| AA Intelligence Index | Composite capability | 61 | |
| GDPVal-AA v2 | Knowledge work | 1753 | |
| CursorBench v3.2 | Agentic coding | 69.9% | |
| DeepSWE v1.1 | Software engineering | 65.9% | |
| FrontierCode v1.1 (Extended) | Long-horizon coding | 61.3% | |
| Terminal-Bench v3.0 | Command-line agents | 26.0% | |
| APEX-Agents | Agent reliability | 57.5% | |
| APEX-SWE | Software engineering | 56.4% | |
| AA-Briefcase | Knowledge work | 1577 | |
| Harvey LAB (Vals) | Legal work | 15.8% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Superseded in this ranking
- API model ID
grok-4.6- Context
- 500K
- Max output
- Not publicly verified
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- xAI API (<200K input tokens) · USD / 1M tokens
- $2 input · $0.5 cached input · $6 output
At 200K input tokens or more, all tokens in the request use $4 input, $1 cached input, and $12 output per 1M tokens.
Benchmark sources
xAI reports Grok 4.6 on a mix of composite, knowledge-work, and agentic-coding evaluations. The rows below retain xAI’s exact benchmark labels and only compare the named configurations in the same launch table.
Introducing Grok 4.6These are xAI-reported launch-table values. Compare configurations and effort modes before treating cross-provider rows as like-for-like.
Evaluation settings
- xAI launch-table result; the index aggregates nine benchmarks.
- xAI launch-table rating; higher is better.
- xAI launch-table result for the named CursorBench configuration.
- xAI launch-table result for its DeepSWE v1.1 setup.
- xAI launch-table result for the Extended variant.
- xAI launch-table result. This newer benchmark is not interchangeable with Terminal-Bench 2.x results elsewhere on the site.
- xAI launch-table result for the named APEX-Agents evaluation.
- xAI launch-table result for the named APEX-SWE evaluation.
- xAI launch-table result for the Harvey LAB Vals evaluation.