Cursor
Composer 2.5
Version 2.5 benchmark runs across the shared Superbash visual prompts.
API pricing
USD per million tokens · Cursor Standard mode- Input
- $0.5
- Output
- $2.5
- Cached input
- $0.2
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.
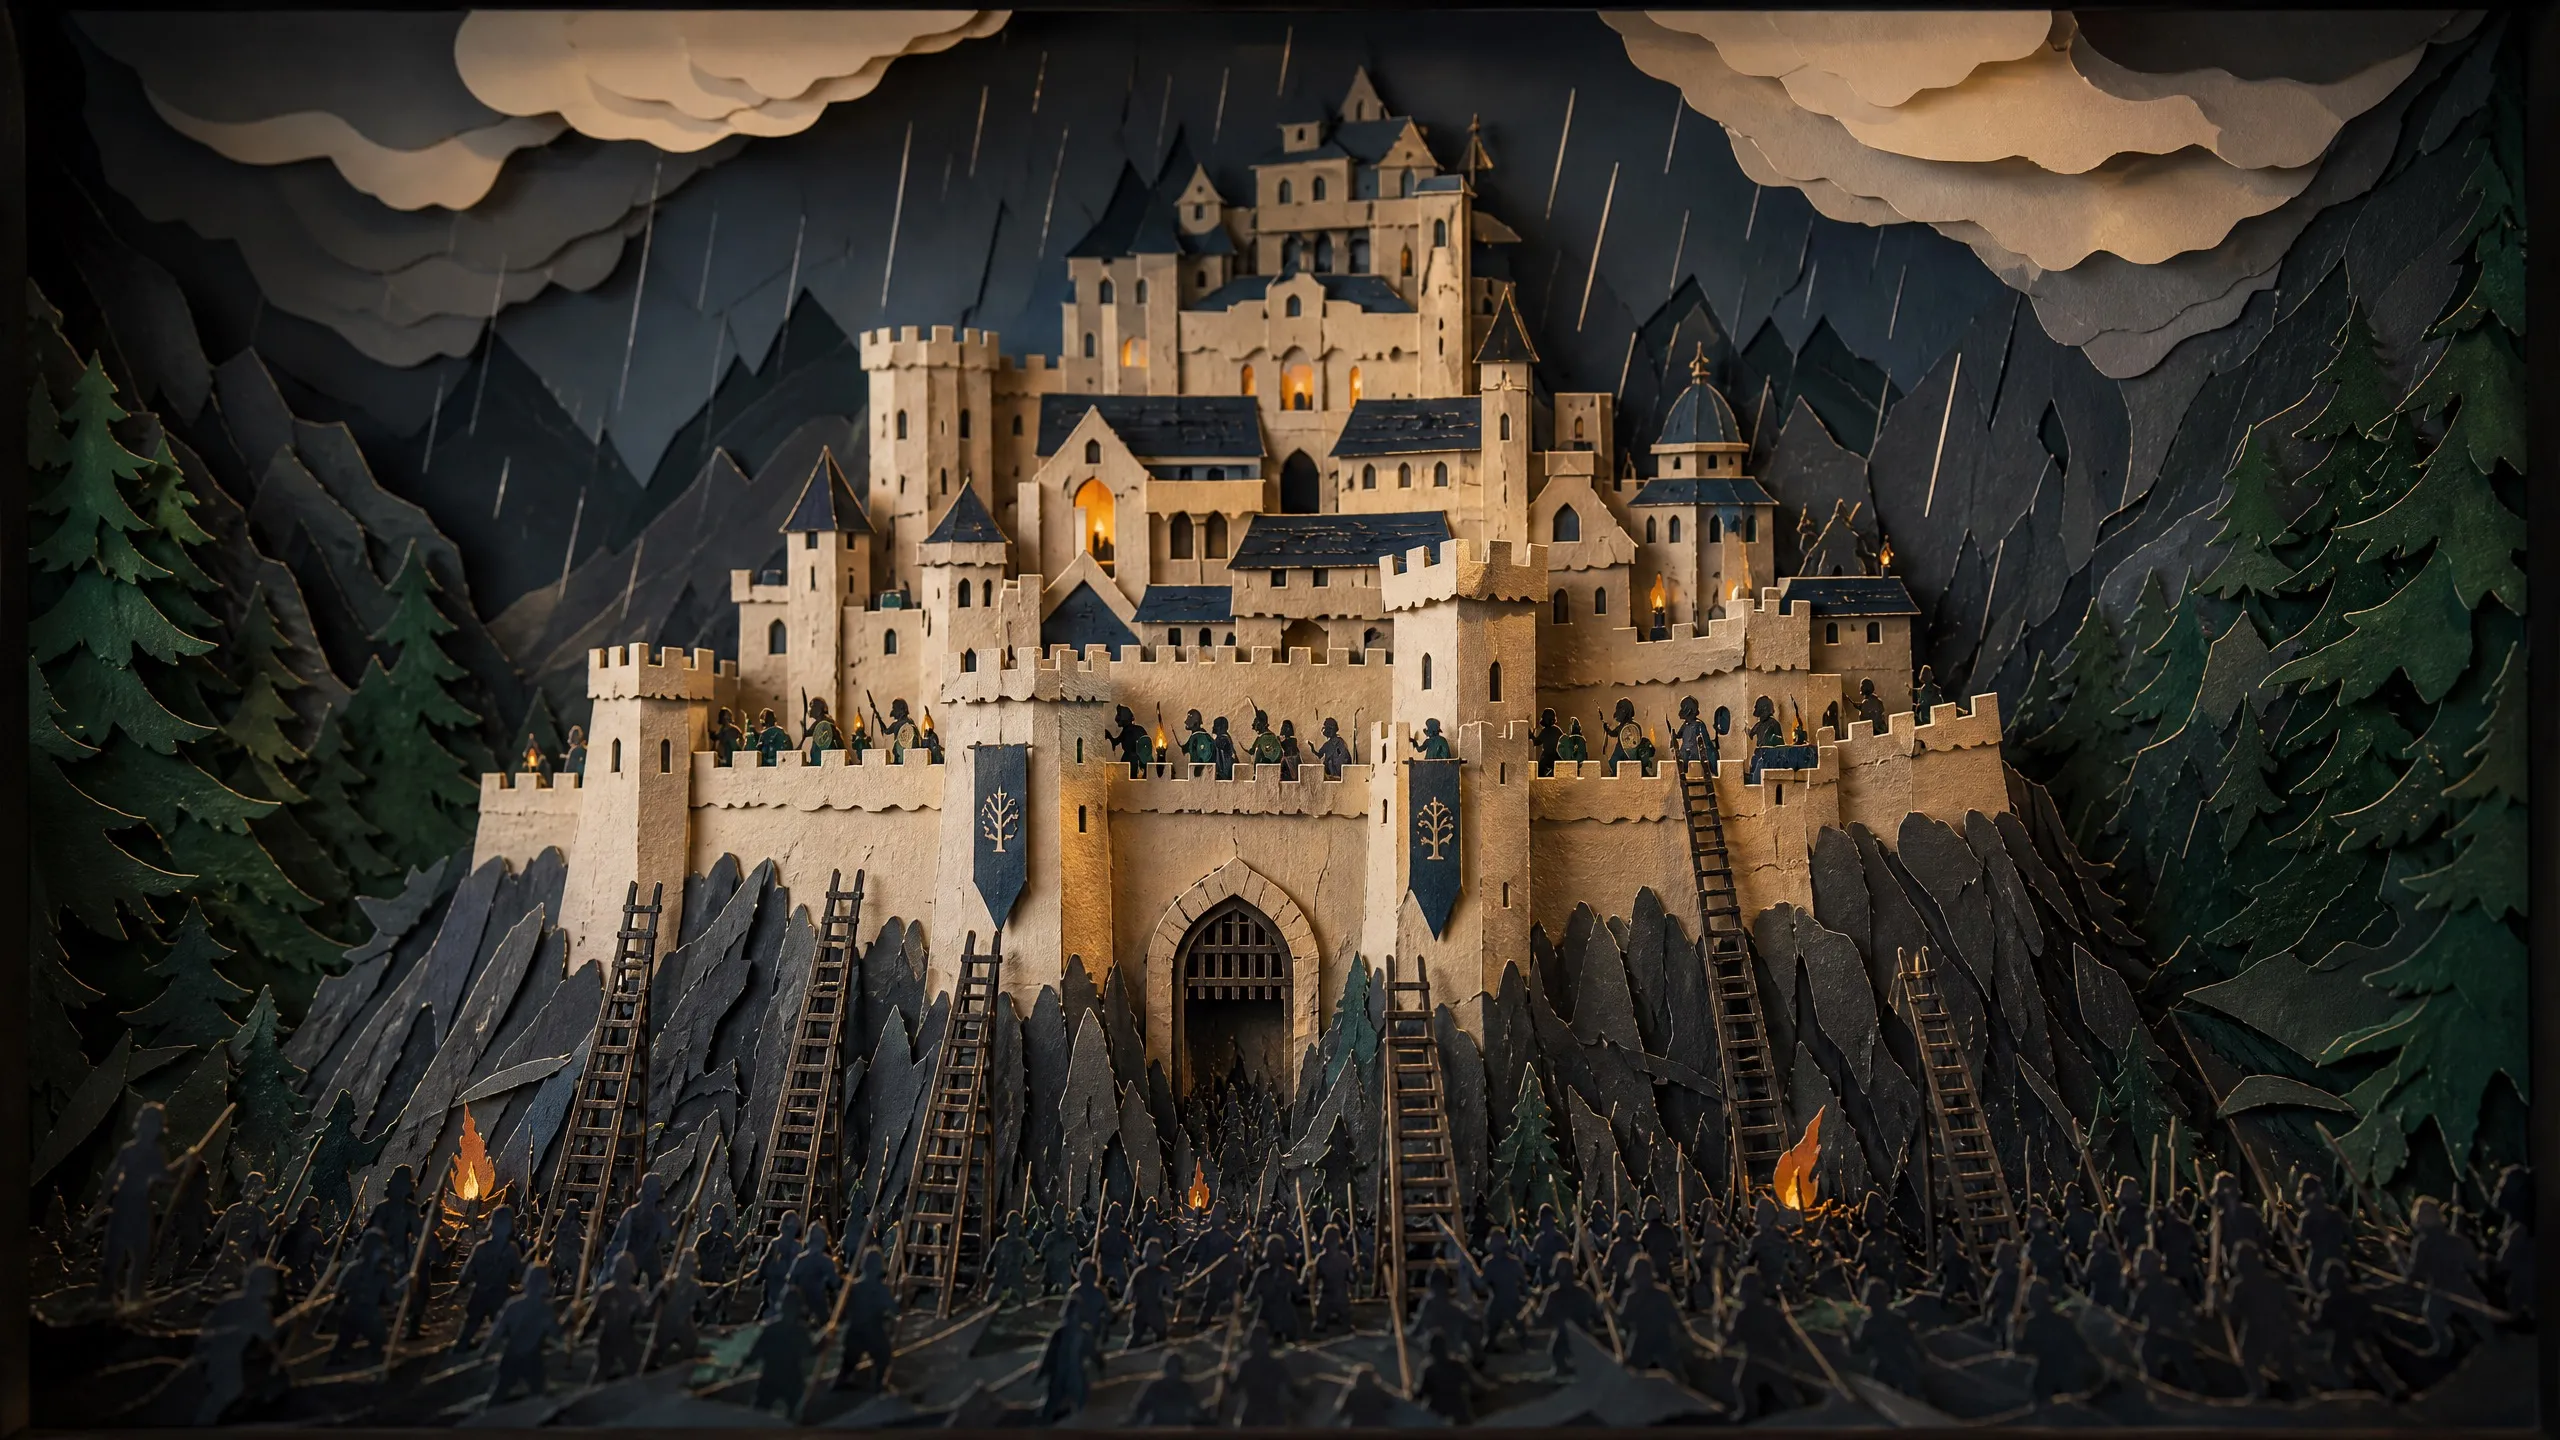
Helm's Deep
Run date: 2026-07-22
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
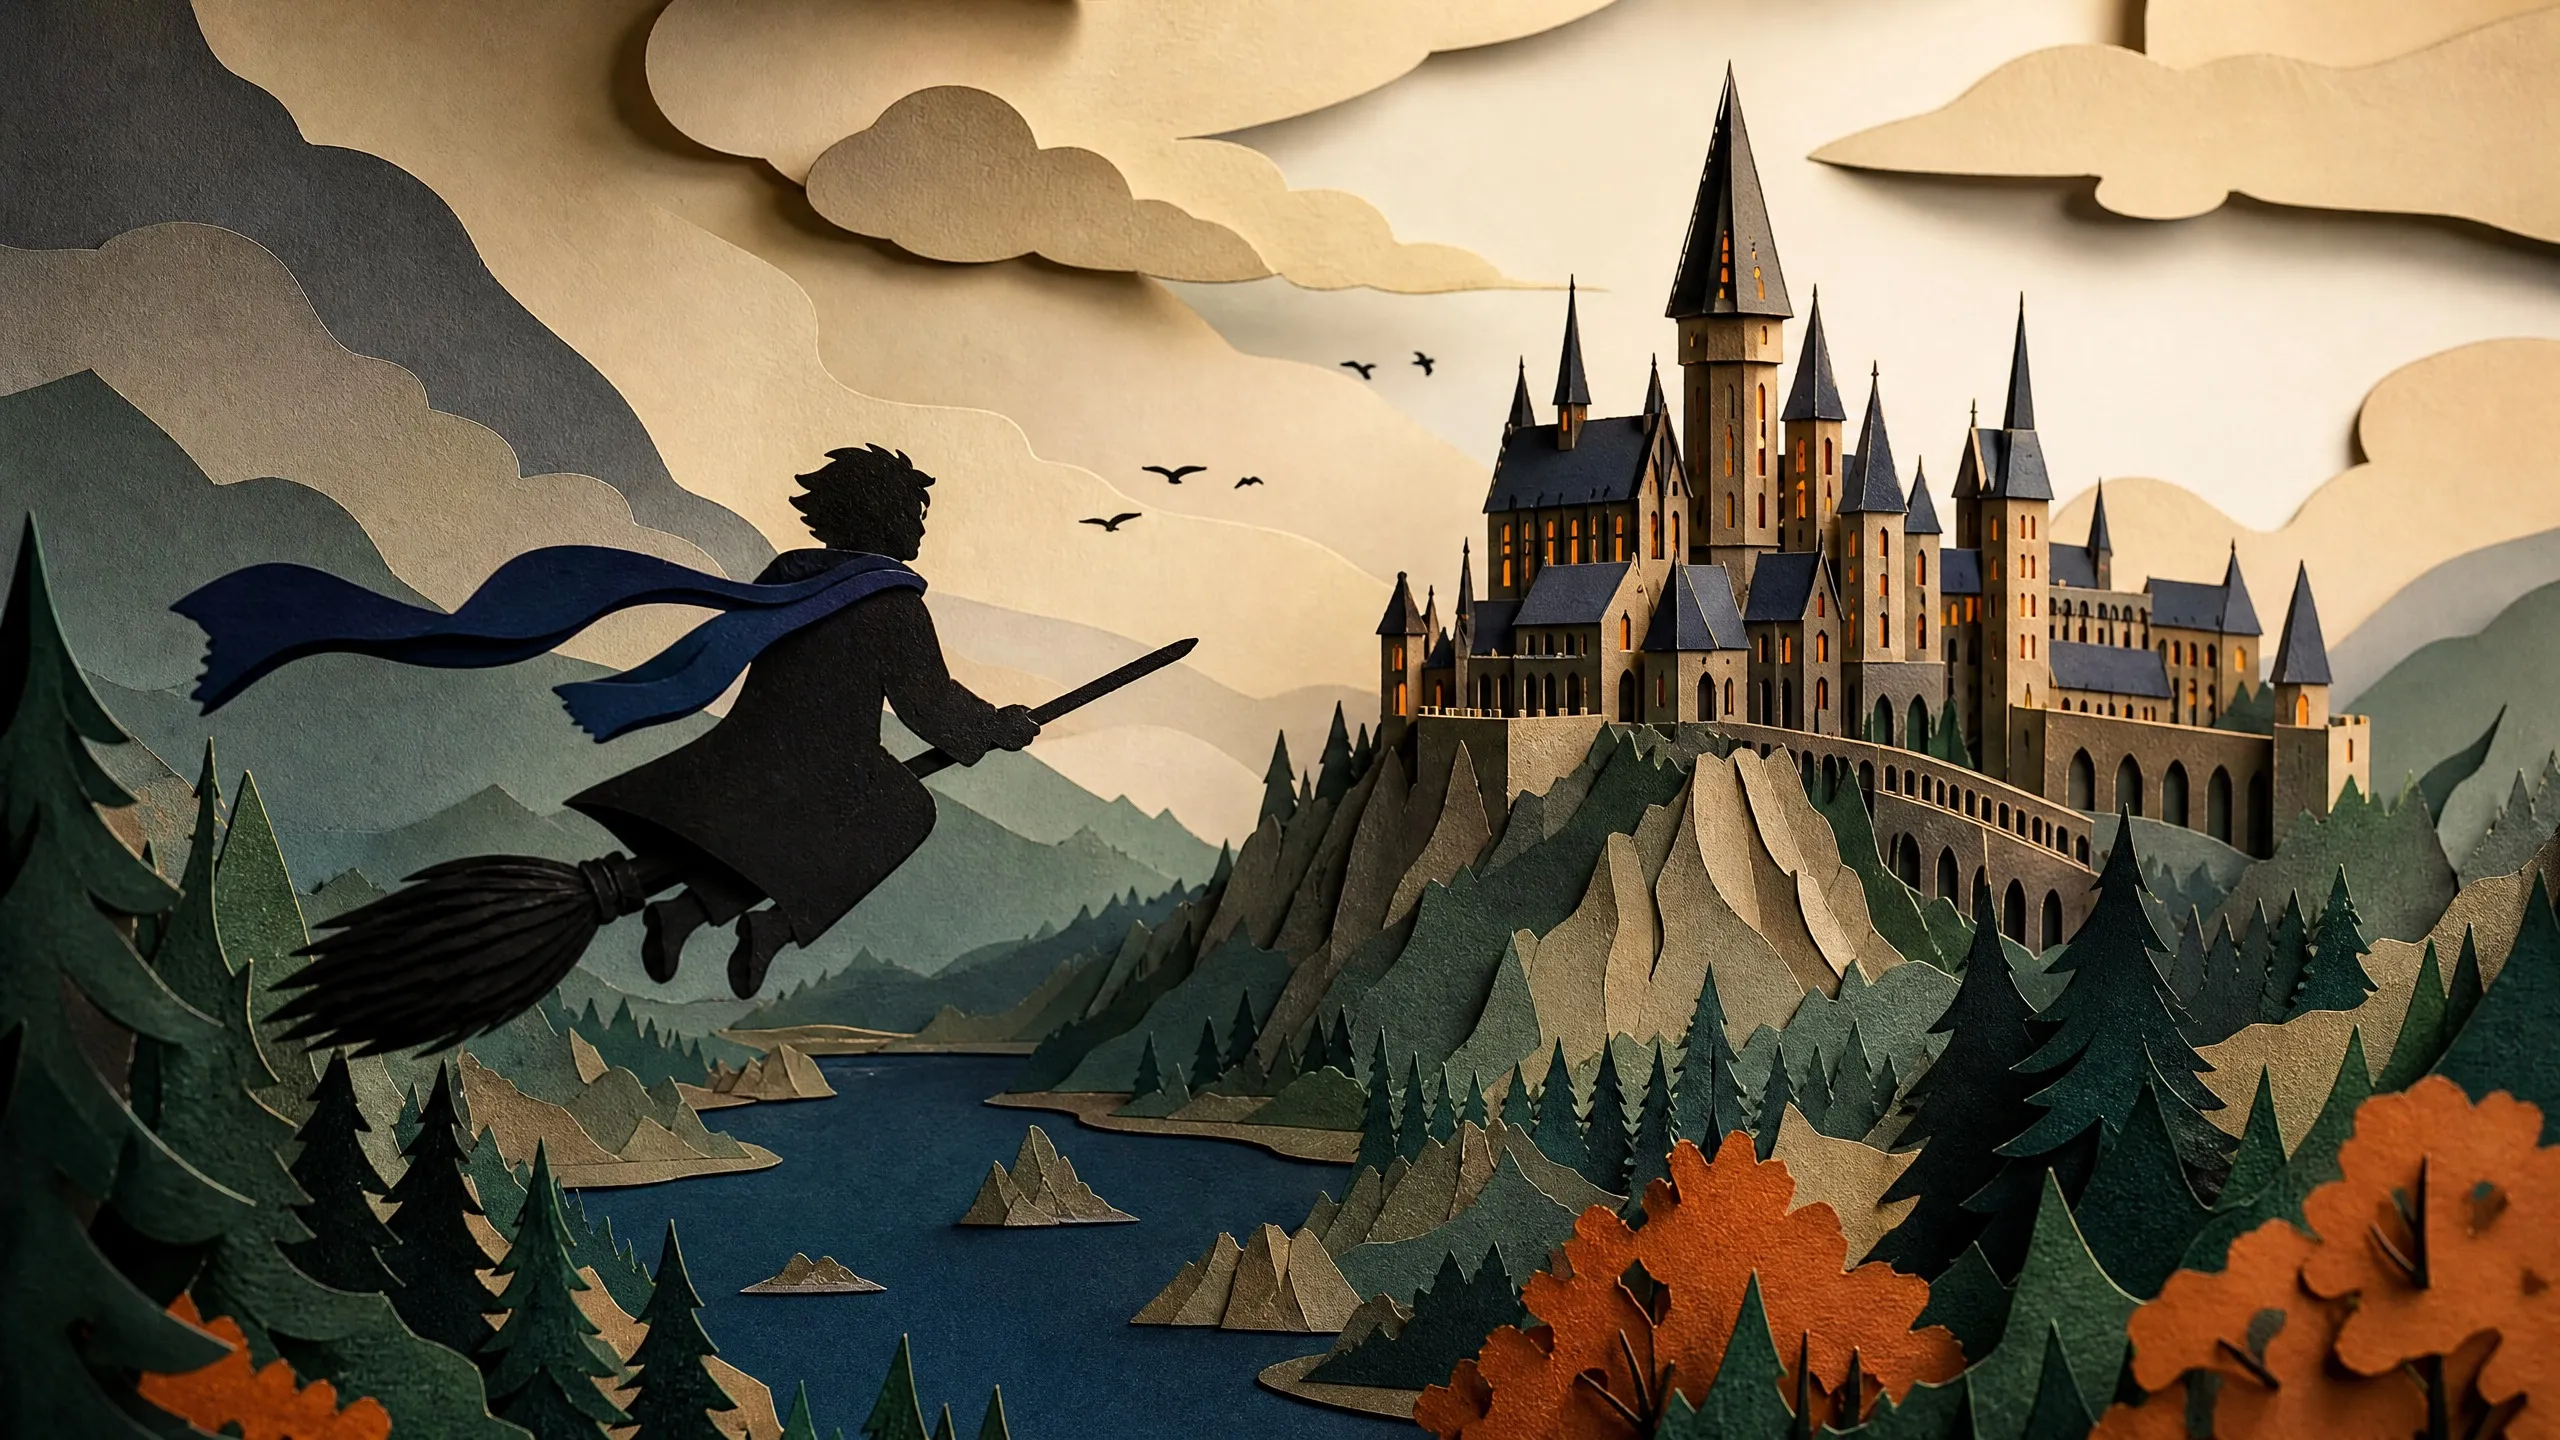
Hogwarts Broom Flight Simulator
Run date: 2026-07-22
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
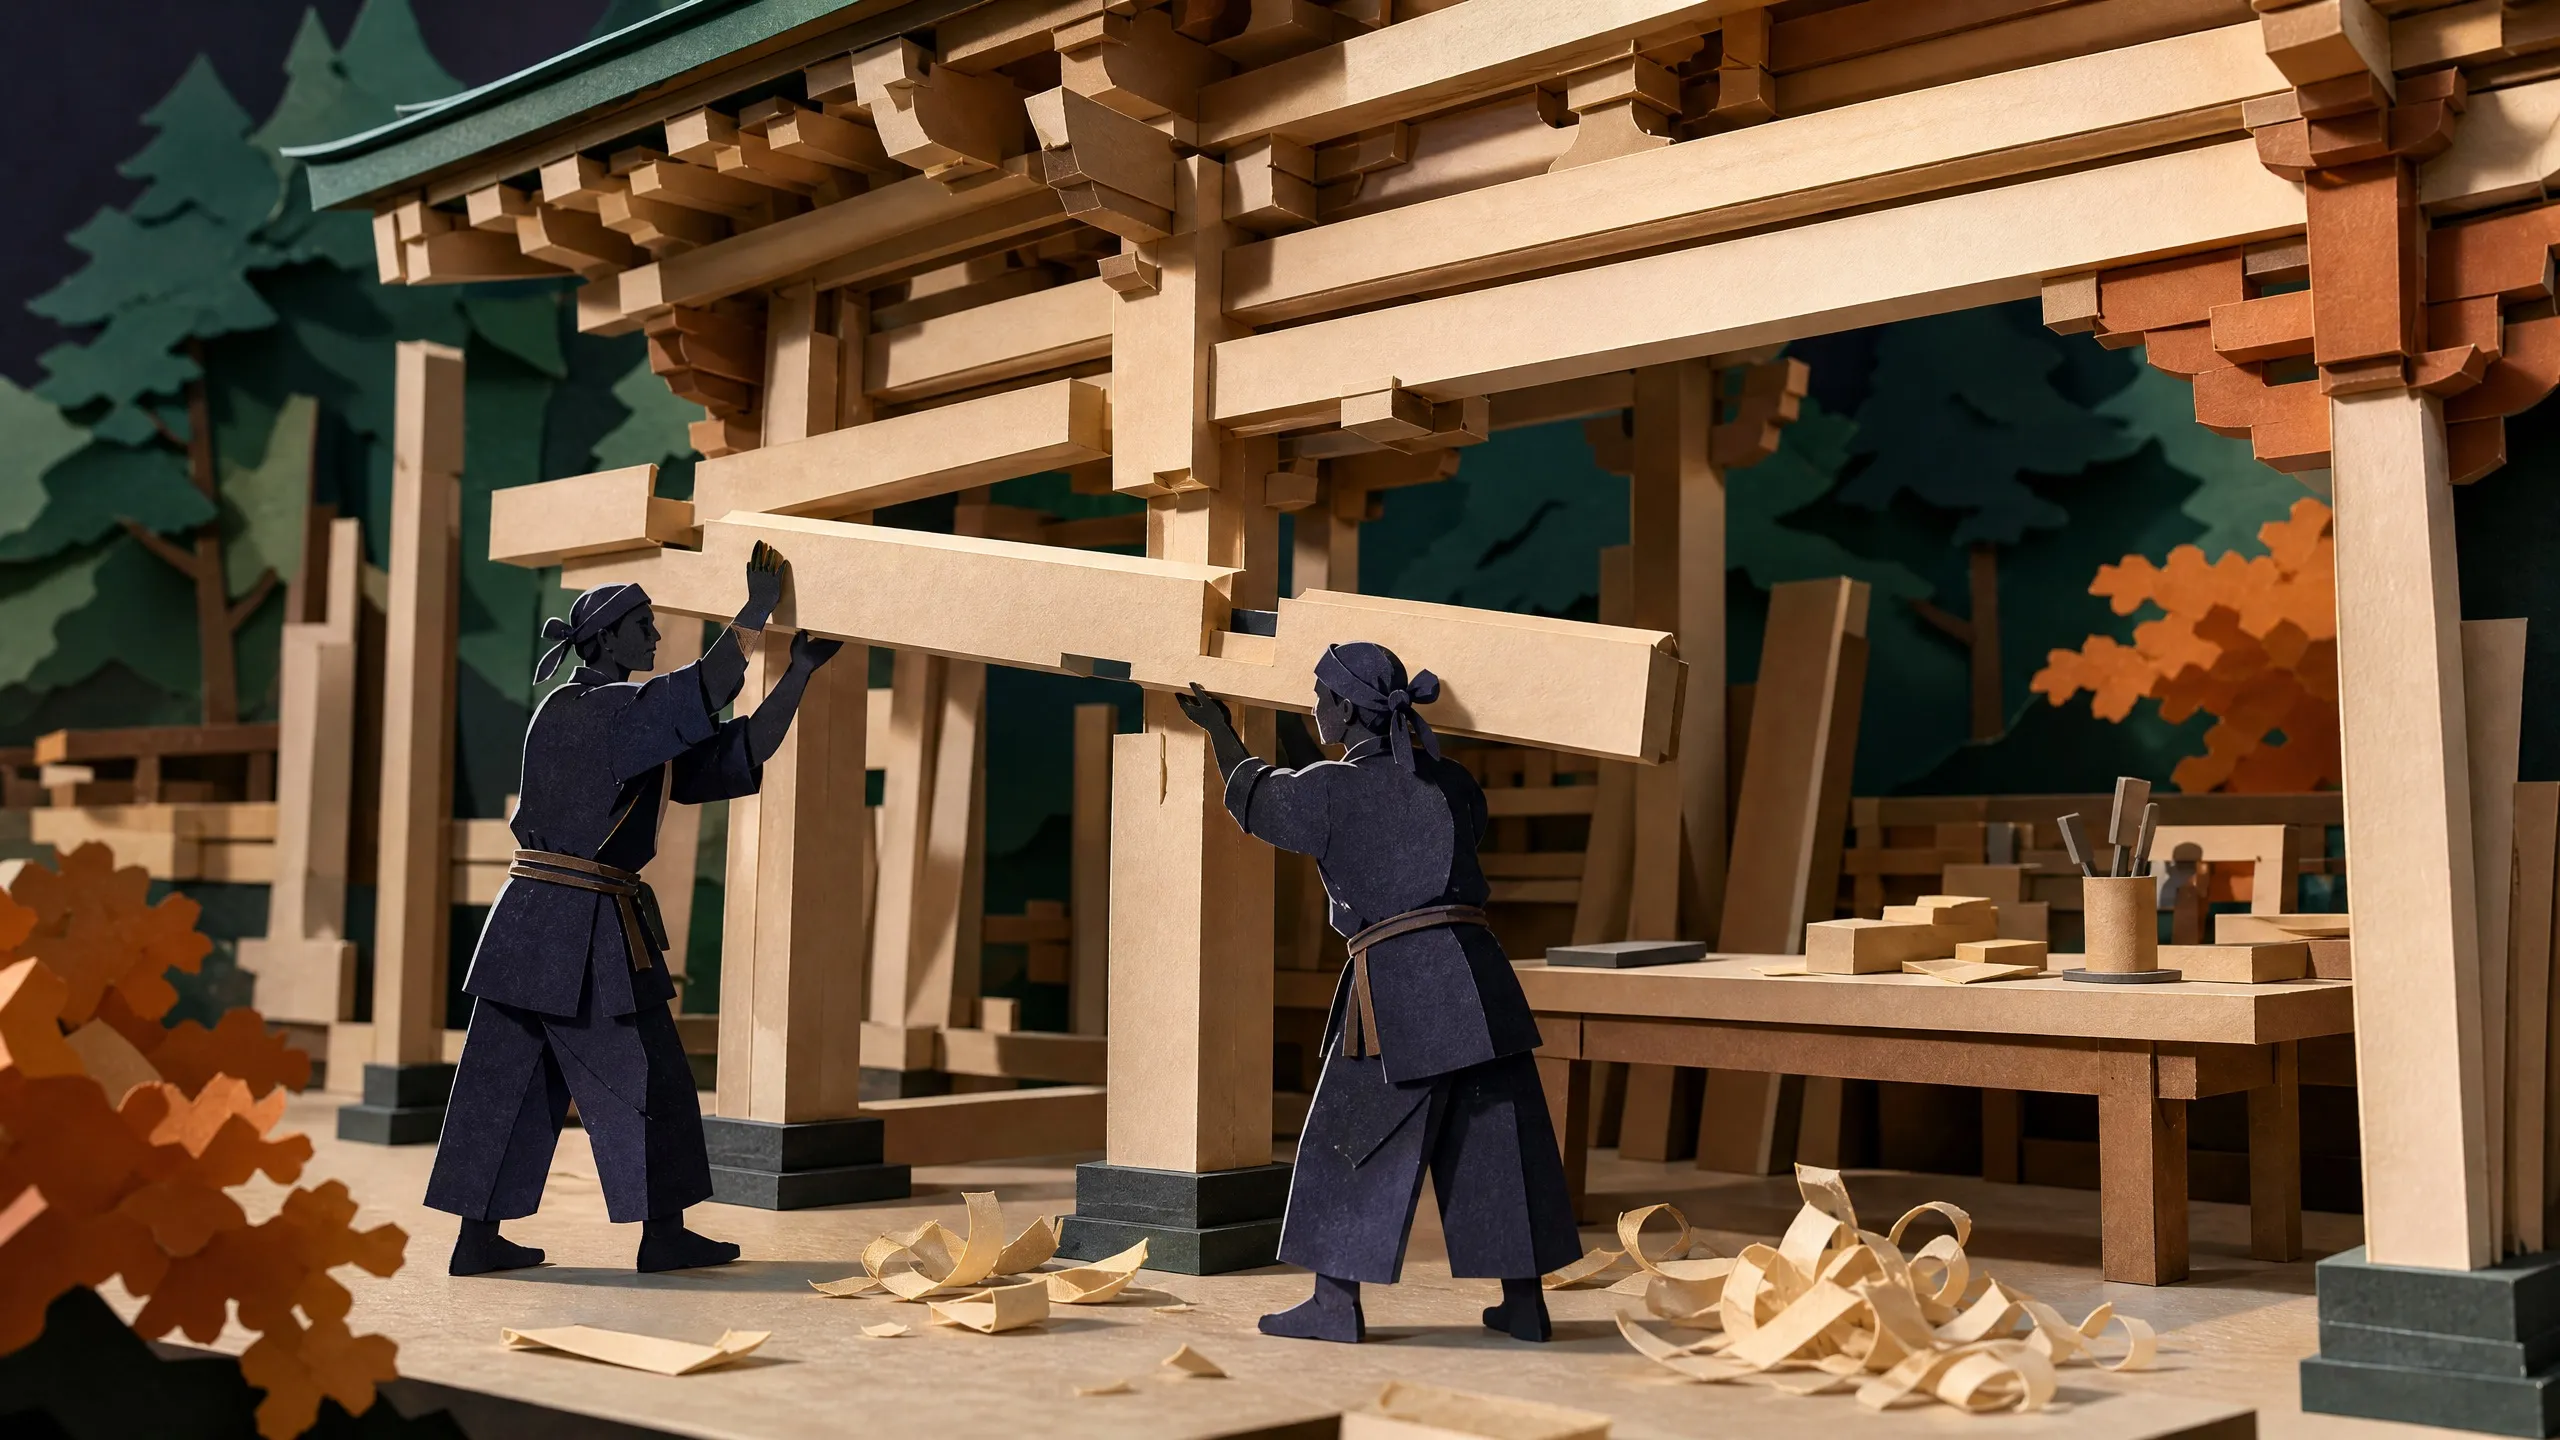
Yingzao Fashi Assembly
Run date: 2026-07-22
Specialist test · evaluated separately
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How Composer 2.5 compares
Three relevant peers, side by side.
- Composer 2.5 This model
- Composer 2
- Claude Opus 4.7
- GPT-5.5
3 benchmarks · 4 models
Official benchmark profile
How Composer 2.5 performs on coding benchmarks.
Terminal-Bench 2.0
69.3%SWE-bench Multilingual
79.8%CursorBench v3.1 harder tasks
63.2%Full official benchmark table3 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| Terminal-Bench 2.0 | Agentic coding | 69.3% | |
| SWE-bench Multilingual | Multilingual coding | 79.8% | |
| CursorBench v3.1 harder tasks | Hard agentic coding | 63.2% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
- Not publicly verified
- Context
- Not publicly verified
- Max output
- Not publicly verified
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- Cursor Standard mode · USD / 1M tokens
- $0.5 input · $0.2 cached input · $2.5 output
Fast mode costs $3 input, $0.50 cached input, and $15 output per 1M tokens. These are model usage rates inside Cursor, not a standalone public API or subscription price.
Benchmark sources
Cursor continued training Kimi K2.5 for Composer 2.5 and reports gains over Composer 2 across agentic, multilingual, and harder coding tasks. The release table publishes three scores.
Composer 2.5 product pageEvaluation settings
- Cursor release-table result; no Composer effort label or detailed harness setting is published.
- Cursor release-table result; no Composer effort label is published.
- Cursor's own harder-task benchmark; no Composer effort label is published.
- CursorBench v3.1 harder tasks
- Cursor marks the comparison figures for Opus 4.7 and GPT-5.5 as self-reported.