Tencent Hy Team
Tencent Hy4 preview
Version preview benchmark runs across the shared Superbash visual prompts.
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.
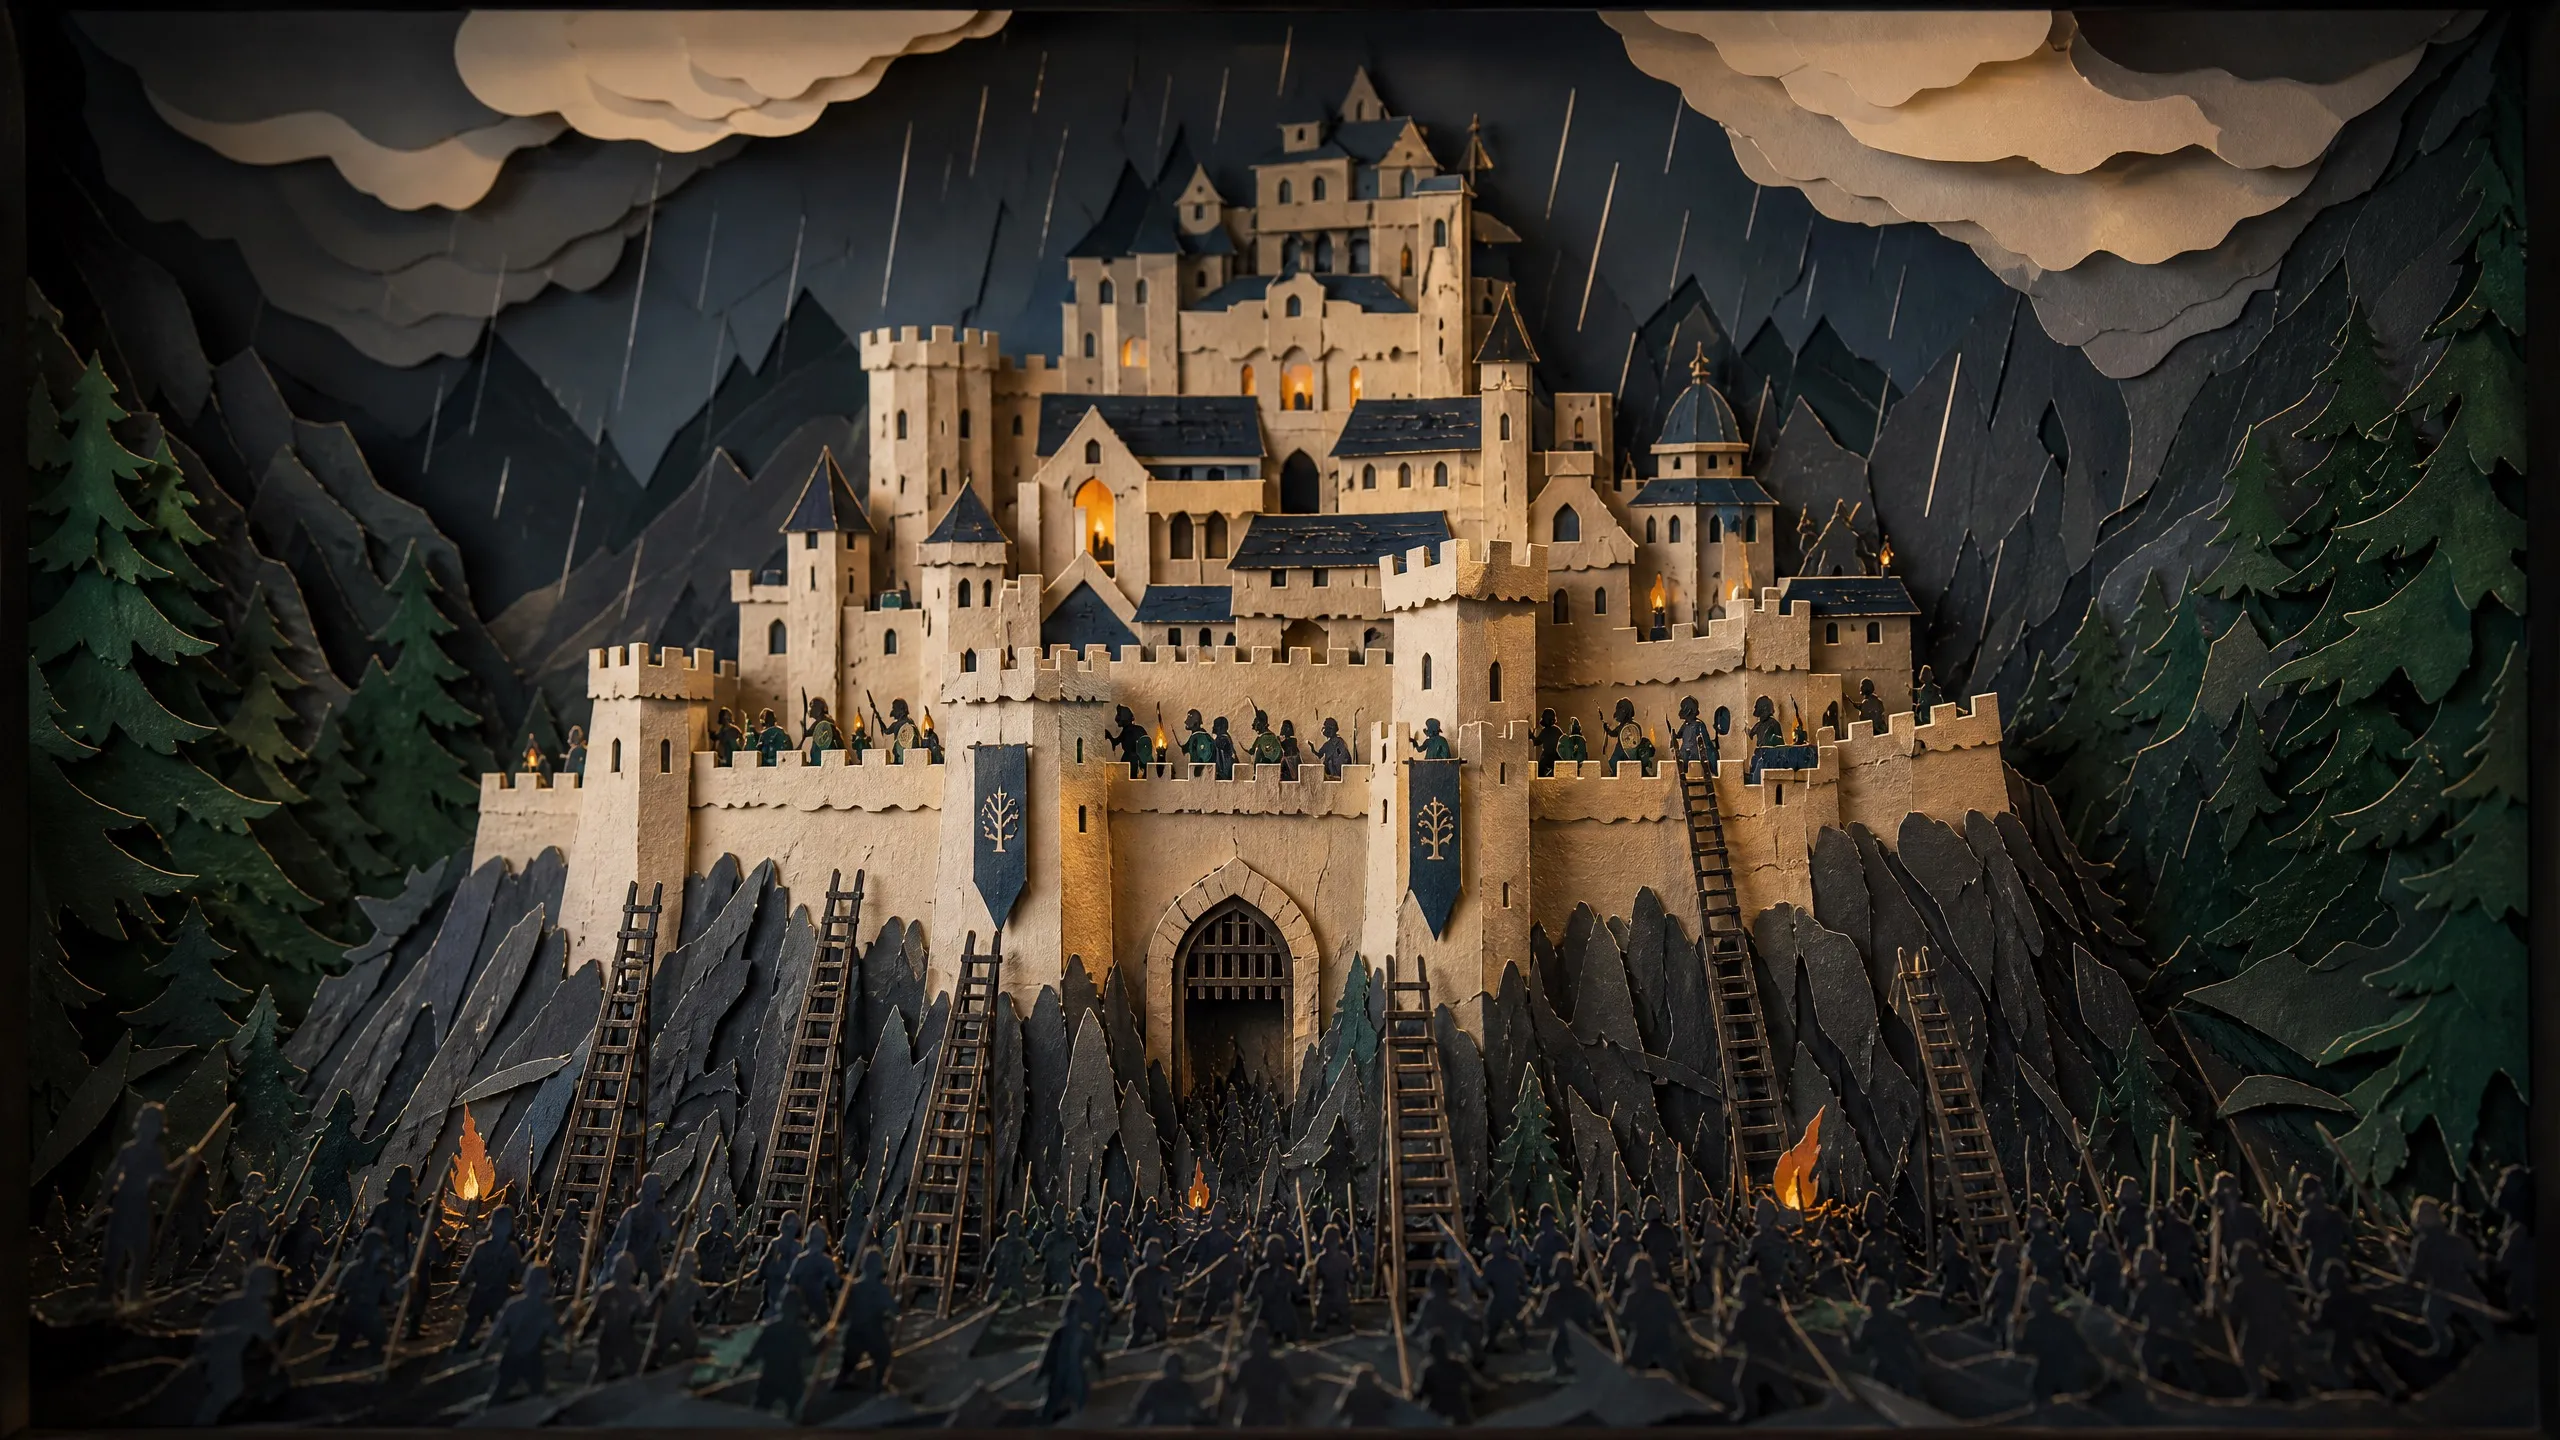
Helm's Deep
Run date: 2026-09-03
Generation provenance: unrecorded
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
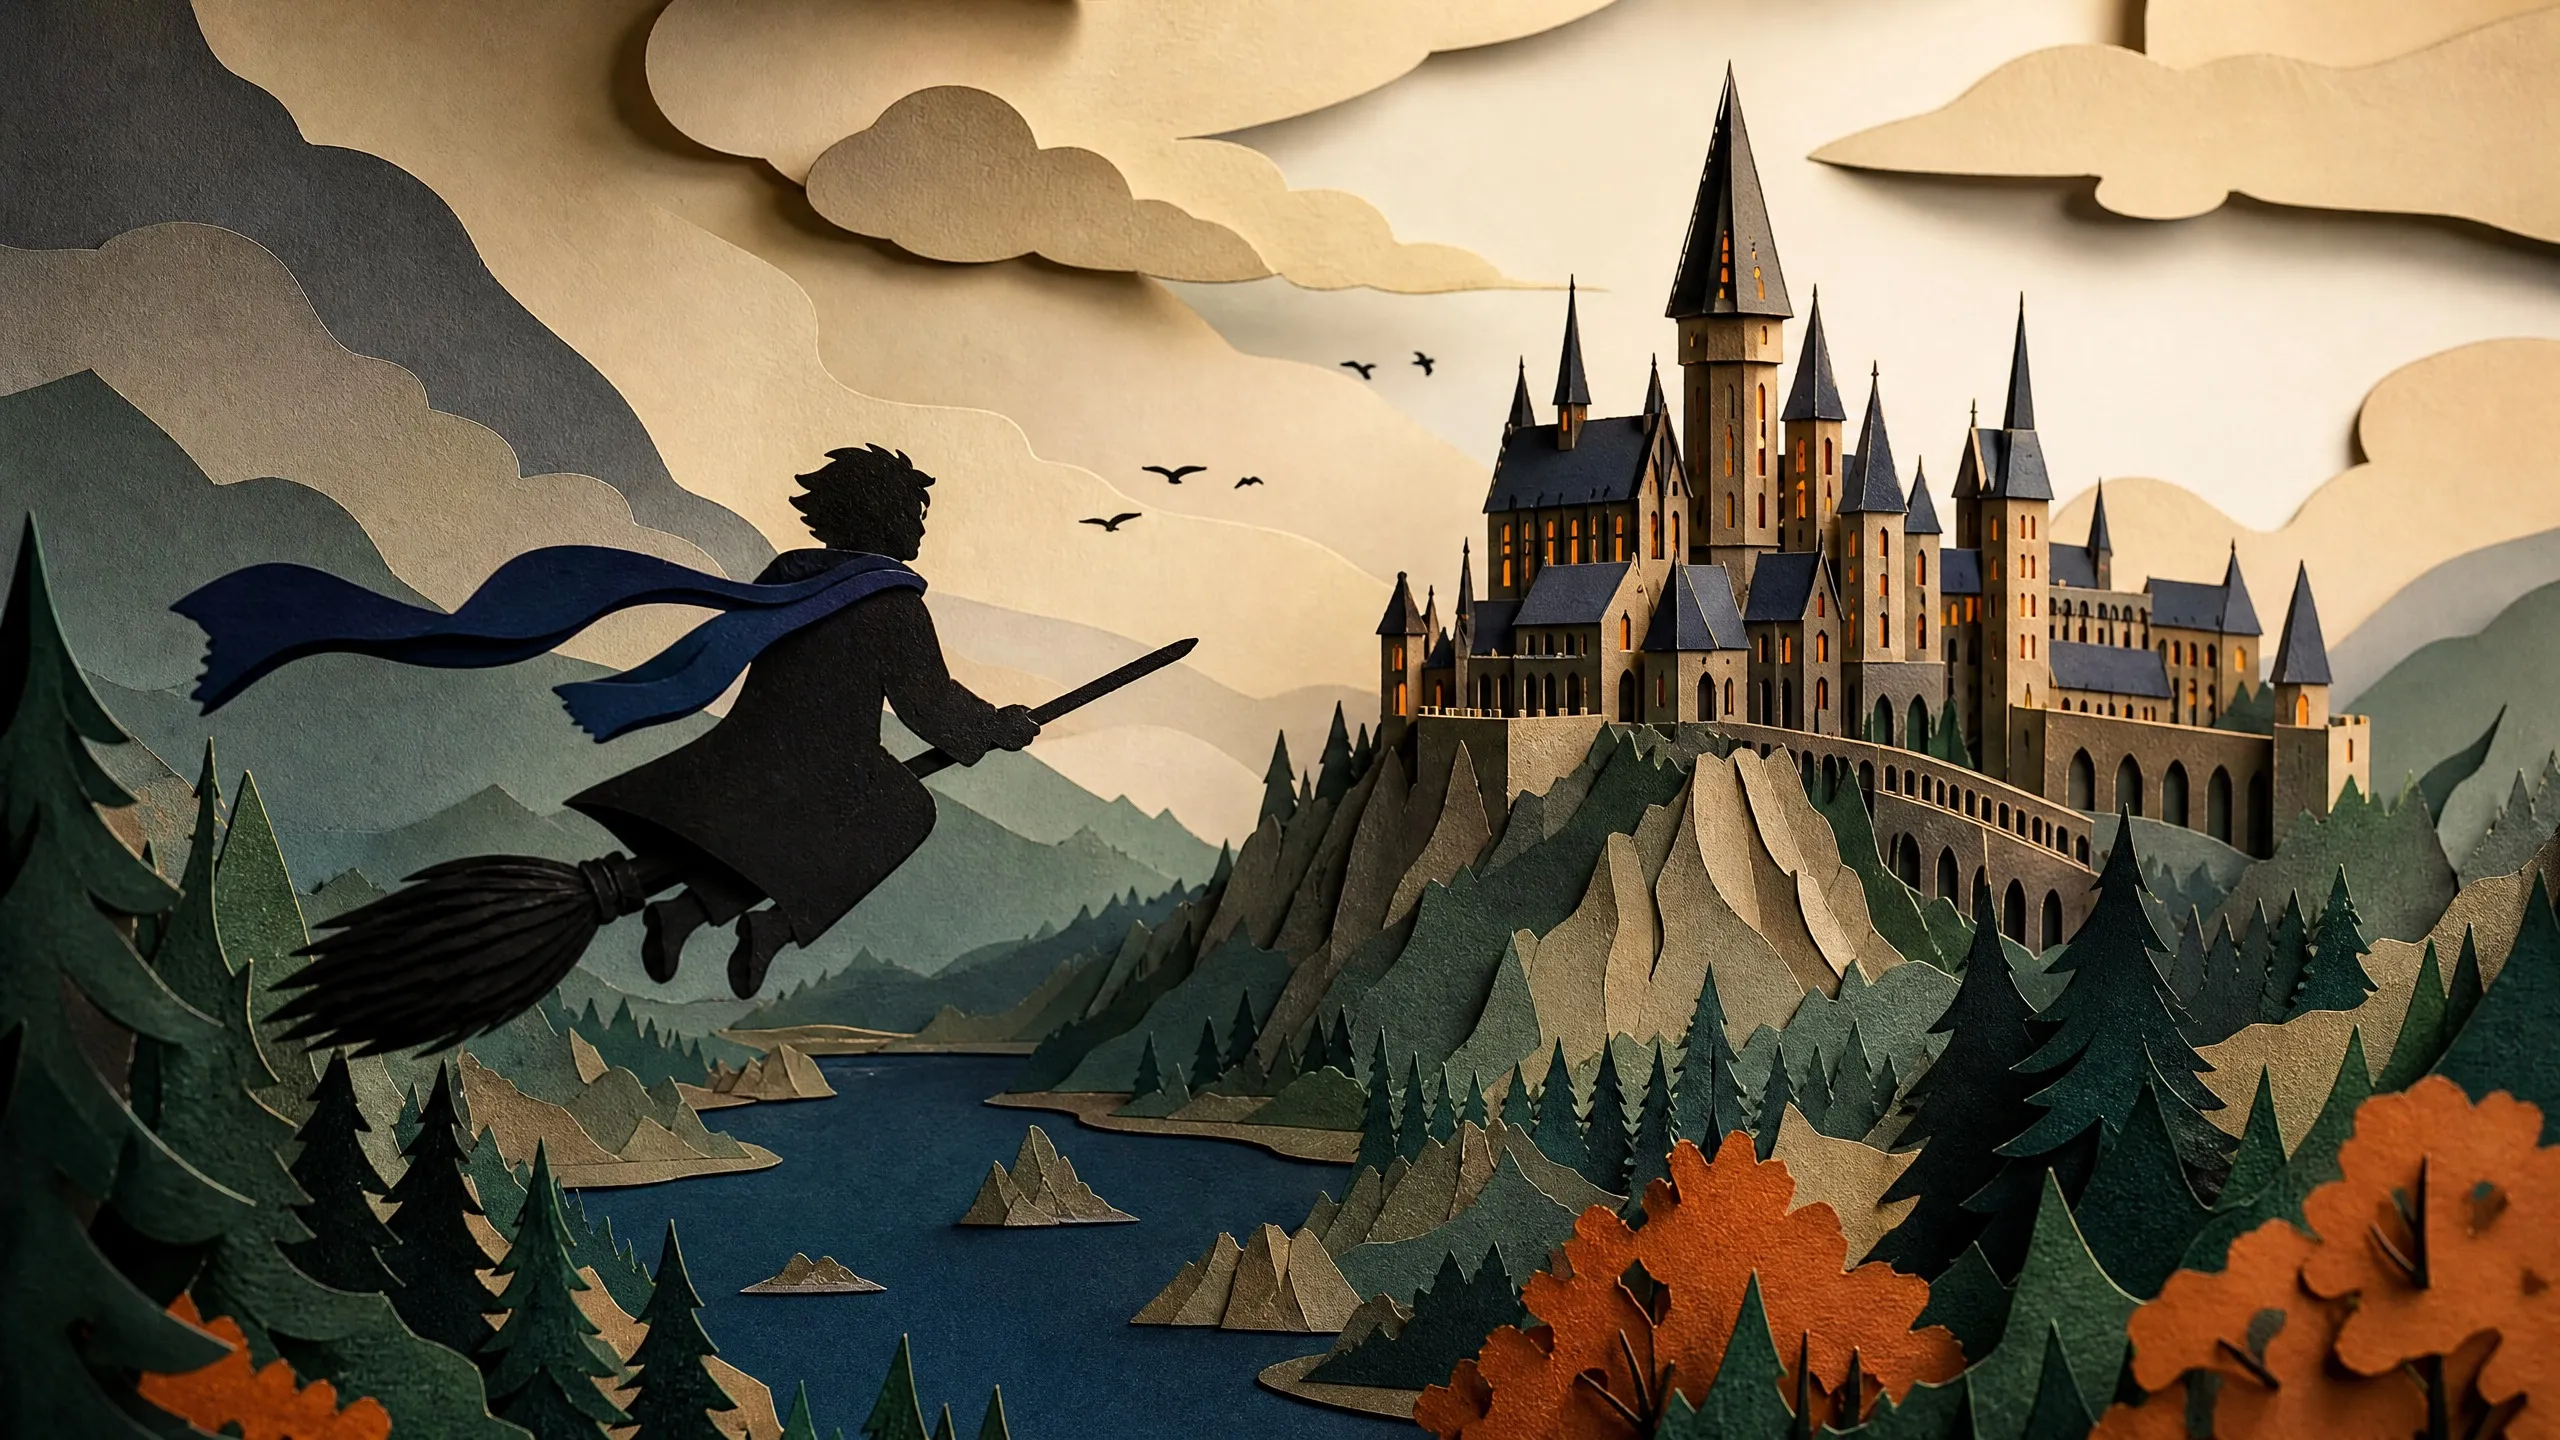
Hogwarts Broom Flight Simulator
Run date: 2026-09-03
Generation provenance: unrecorded
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
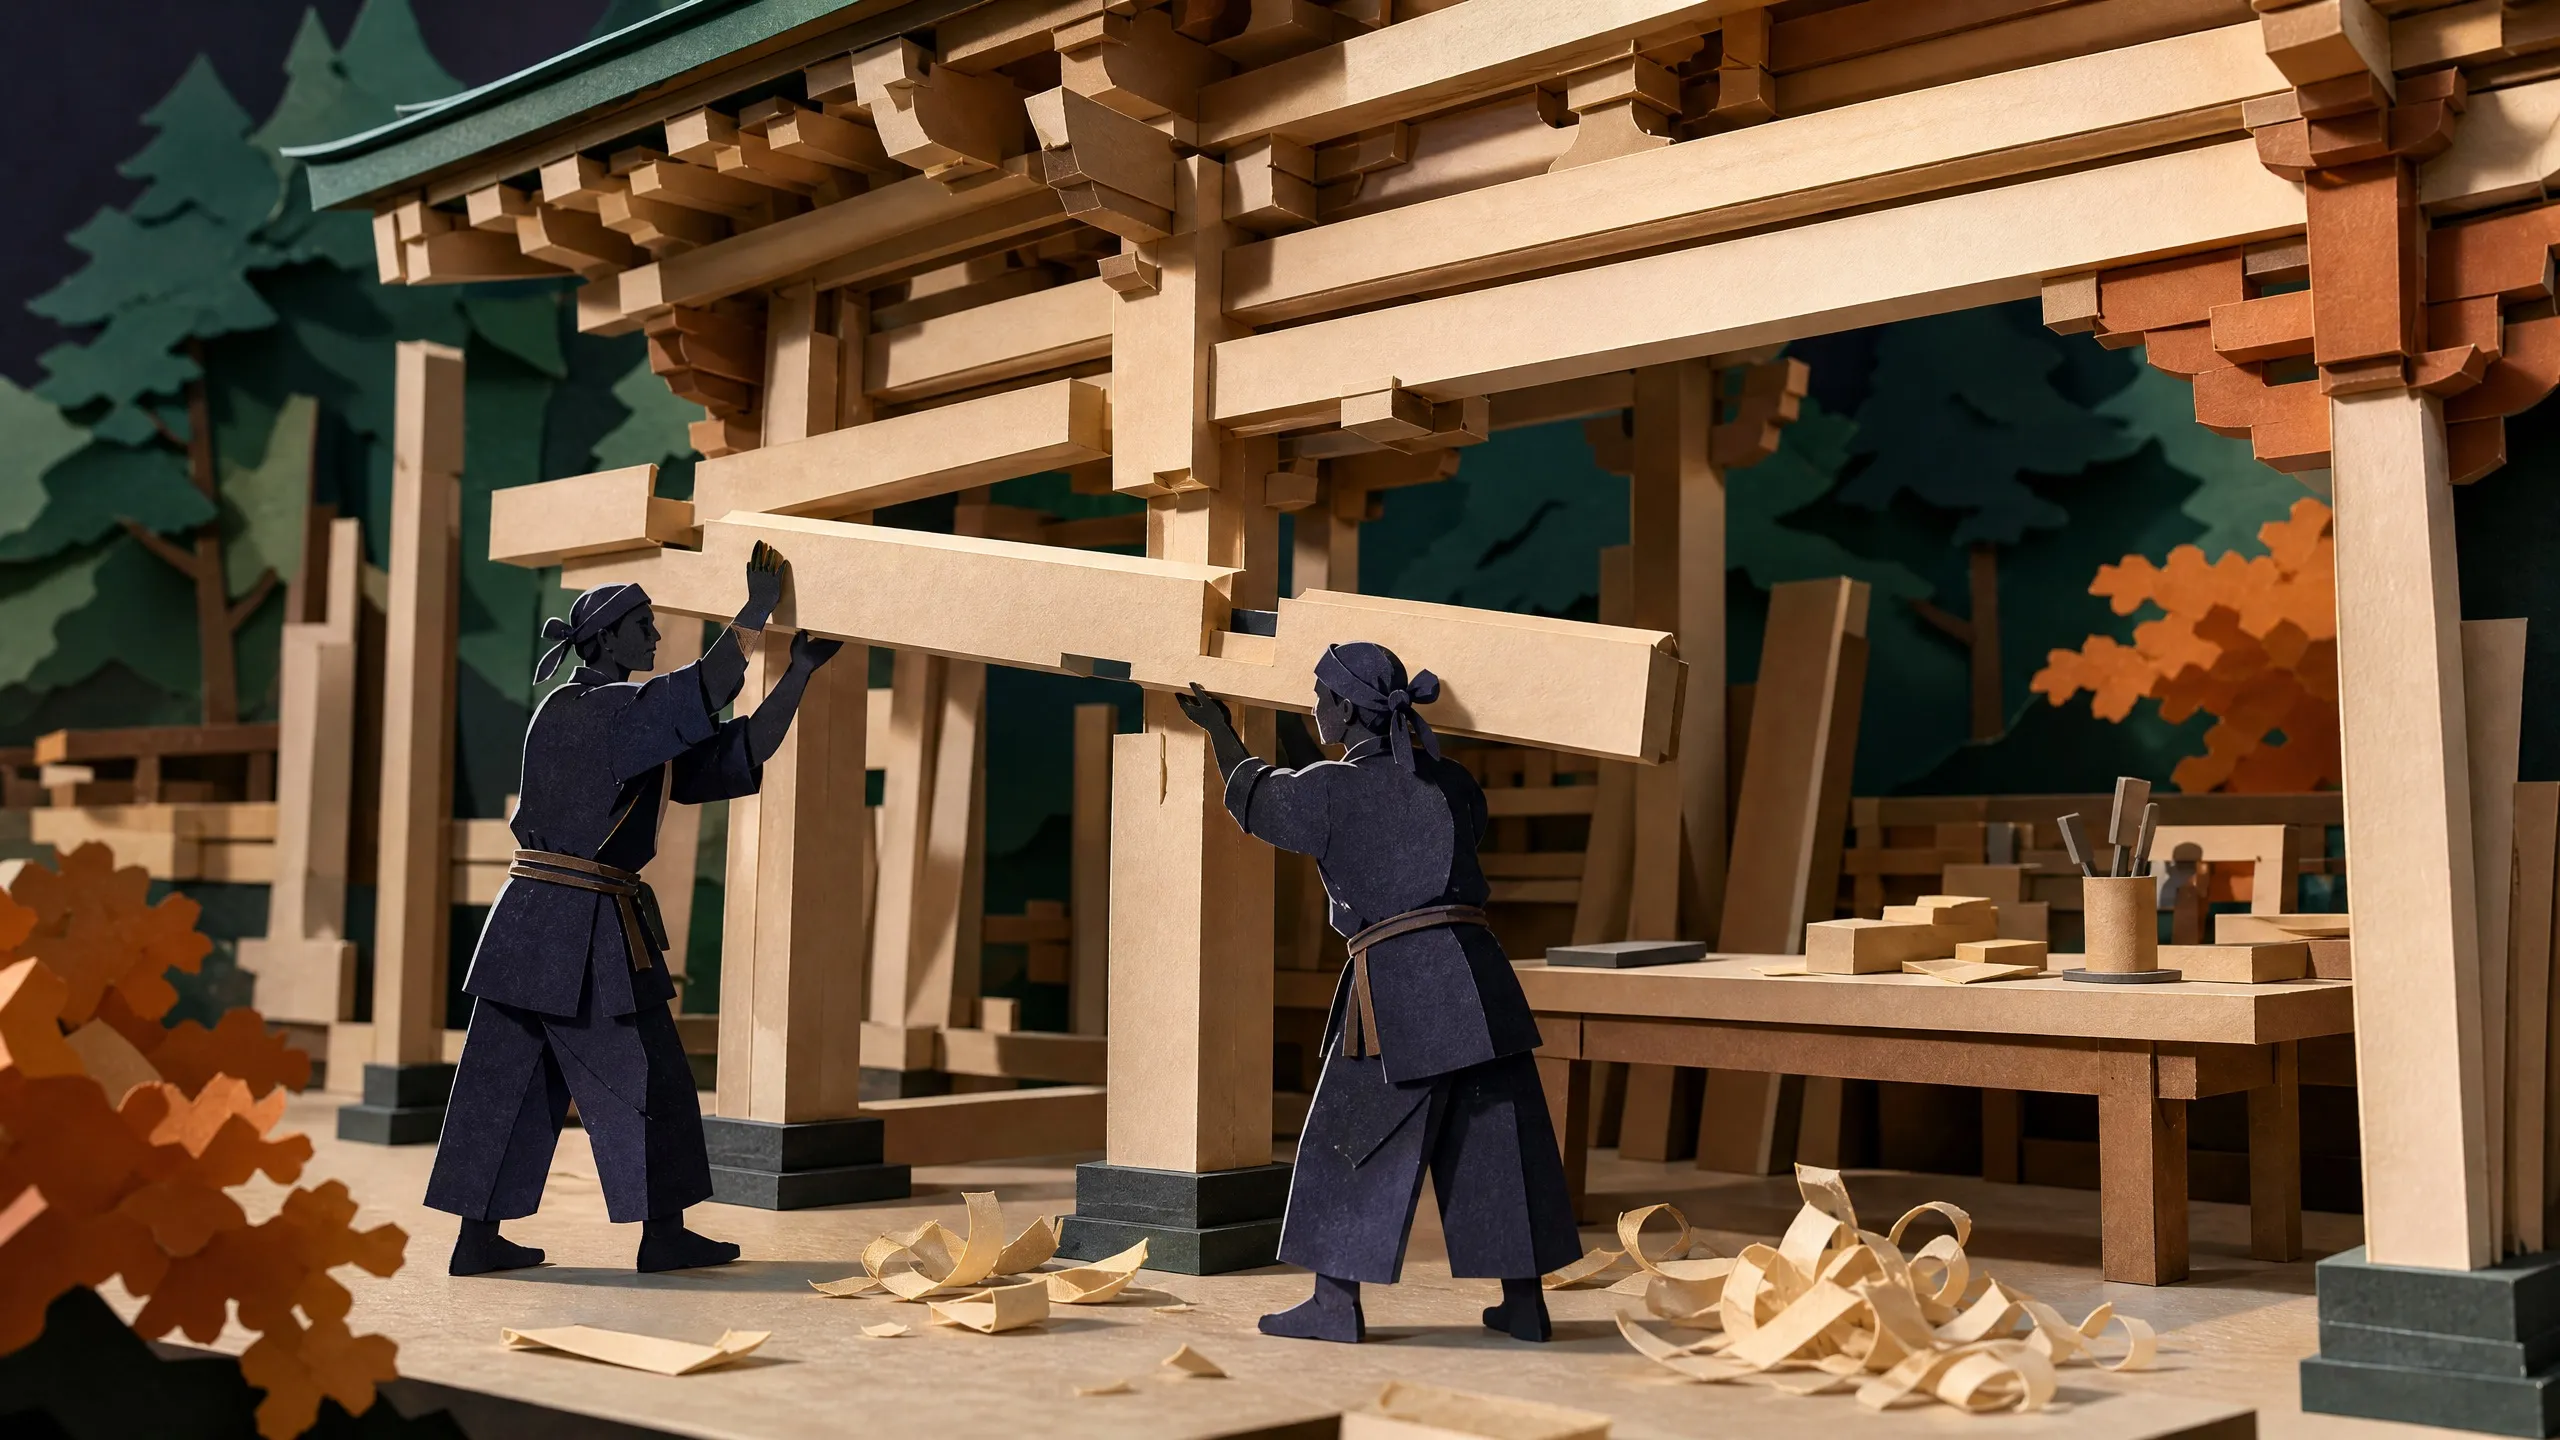
Yingzao Fashi Assembly
Run date: 2026-09-04
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
Official benchmark profile
A blind internal expert comparison, stated in prose; the standard benchmark tables are published as images.
Blind expert side-by-side
2.99 averageFull official benchmark table1 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| Blind expert side-by-side | Engineering work | 2.99 average |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Preview / limited access
- API model ID
hy4-preview- Context
- 1M
- Max output
- Not publicly verified
- License
- Apache-2.0
- Access route
- Self-hosted only; no hosted Hugging Face Inference Provider was listed at check.
- Modalities
- text generation; unknown: image, audio, and video input/output
- Hardware
- Vendor FP8 vLLM/SGLang recipe uses tensor parallelism of 8; minimum GPU/VRAM and cost are not verified.
- API price · USD / 1M tokens
- Not publicly verified
Benchmark sources
Tencent describes Hy4 preview as a 770B-total, 49B-active MoE with a 1M-token context window released under Apache-2.0. It claims gains in software engineering, office and analysis, game development, and scientific research. Every figure below is a Tencent claim measured under Tencent’s own setup, not an independent reproduction.
Hy4 preview model cardTencent publishes the Hy4 preview benchmark tables and appendix as images, so no machine-readable scores exist to restate here. The card also lists no hosted inference route.
Evaluation settings
- 163 internal Tencent experts rated model outputs on 203 engineering tasks, scored out of 3. Against GLM 5.3 the split was 46.8% wins / 12.8% ties / 40.4% losses; against Kimi K3 it was 51.2% wins / 7.9% ties / 40.9% losses. Tencent characterises both margins as slight.