
Z.ai
GLM 5.3
A B-tier builder with a complete visual benchmark suite that still benefits from close review.
API pricing
USD per million tokens · Z.ai API- Input
- $1.4
- Output
- $4.4
- Cached input
- $0.26
- Context window
- 1M
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-08-17
Specialist test · evaluated separately
Generation provenance: unrecorded
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Run date: 2026-08-17
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
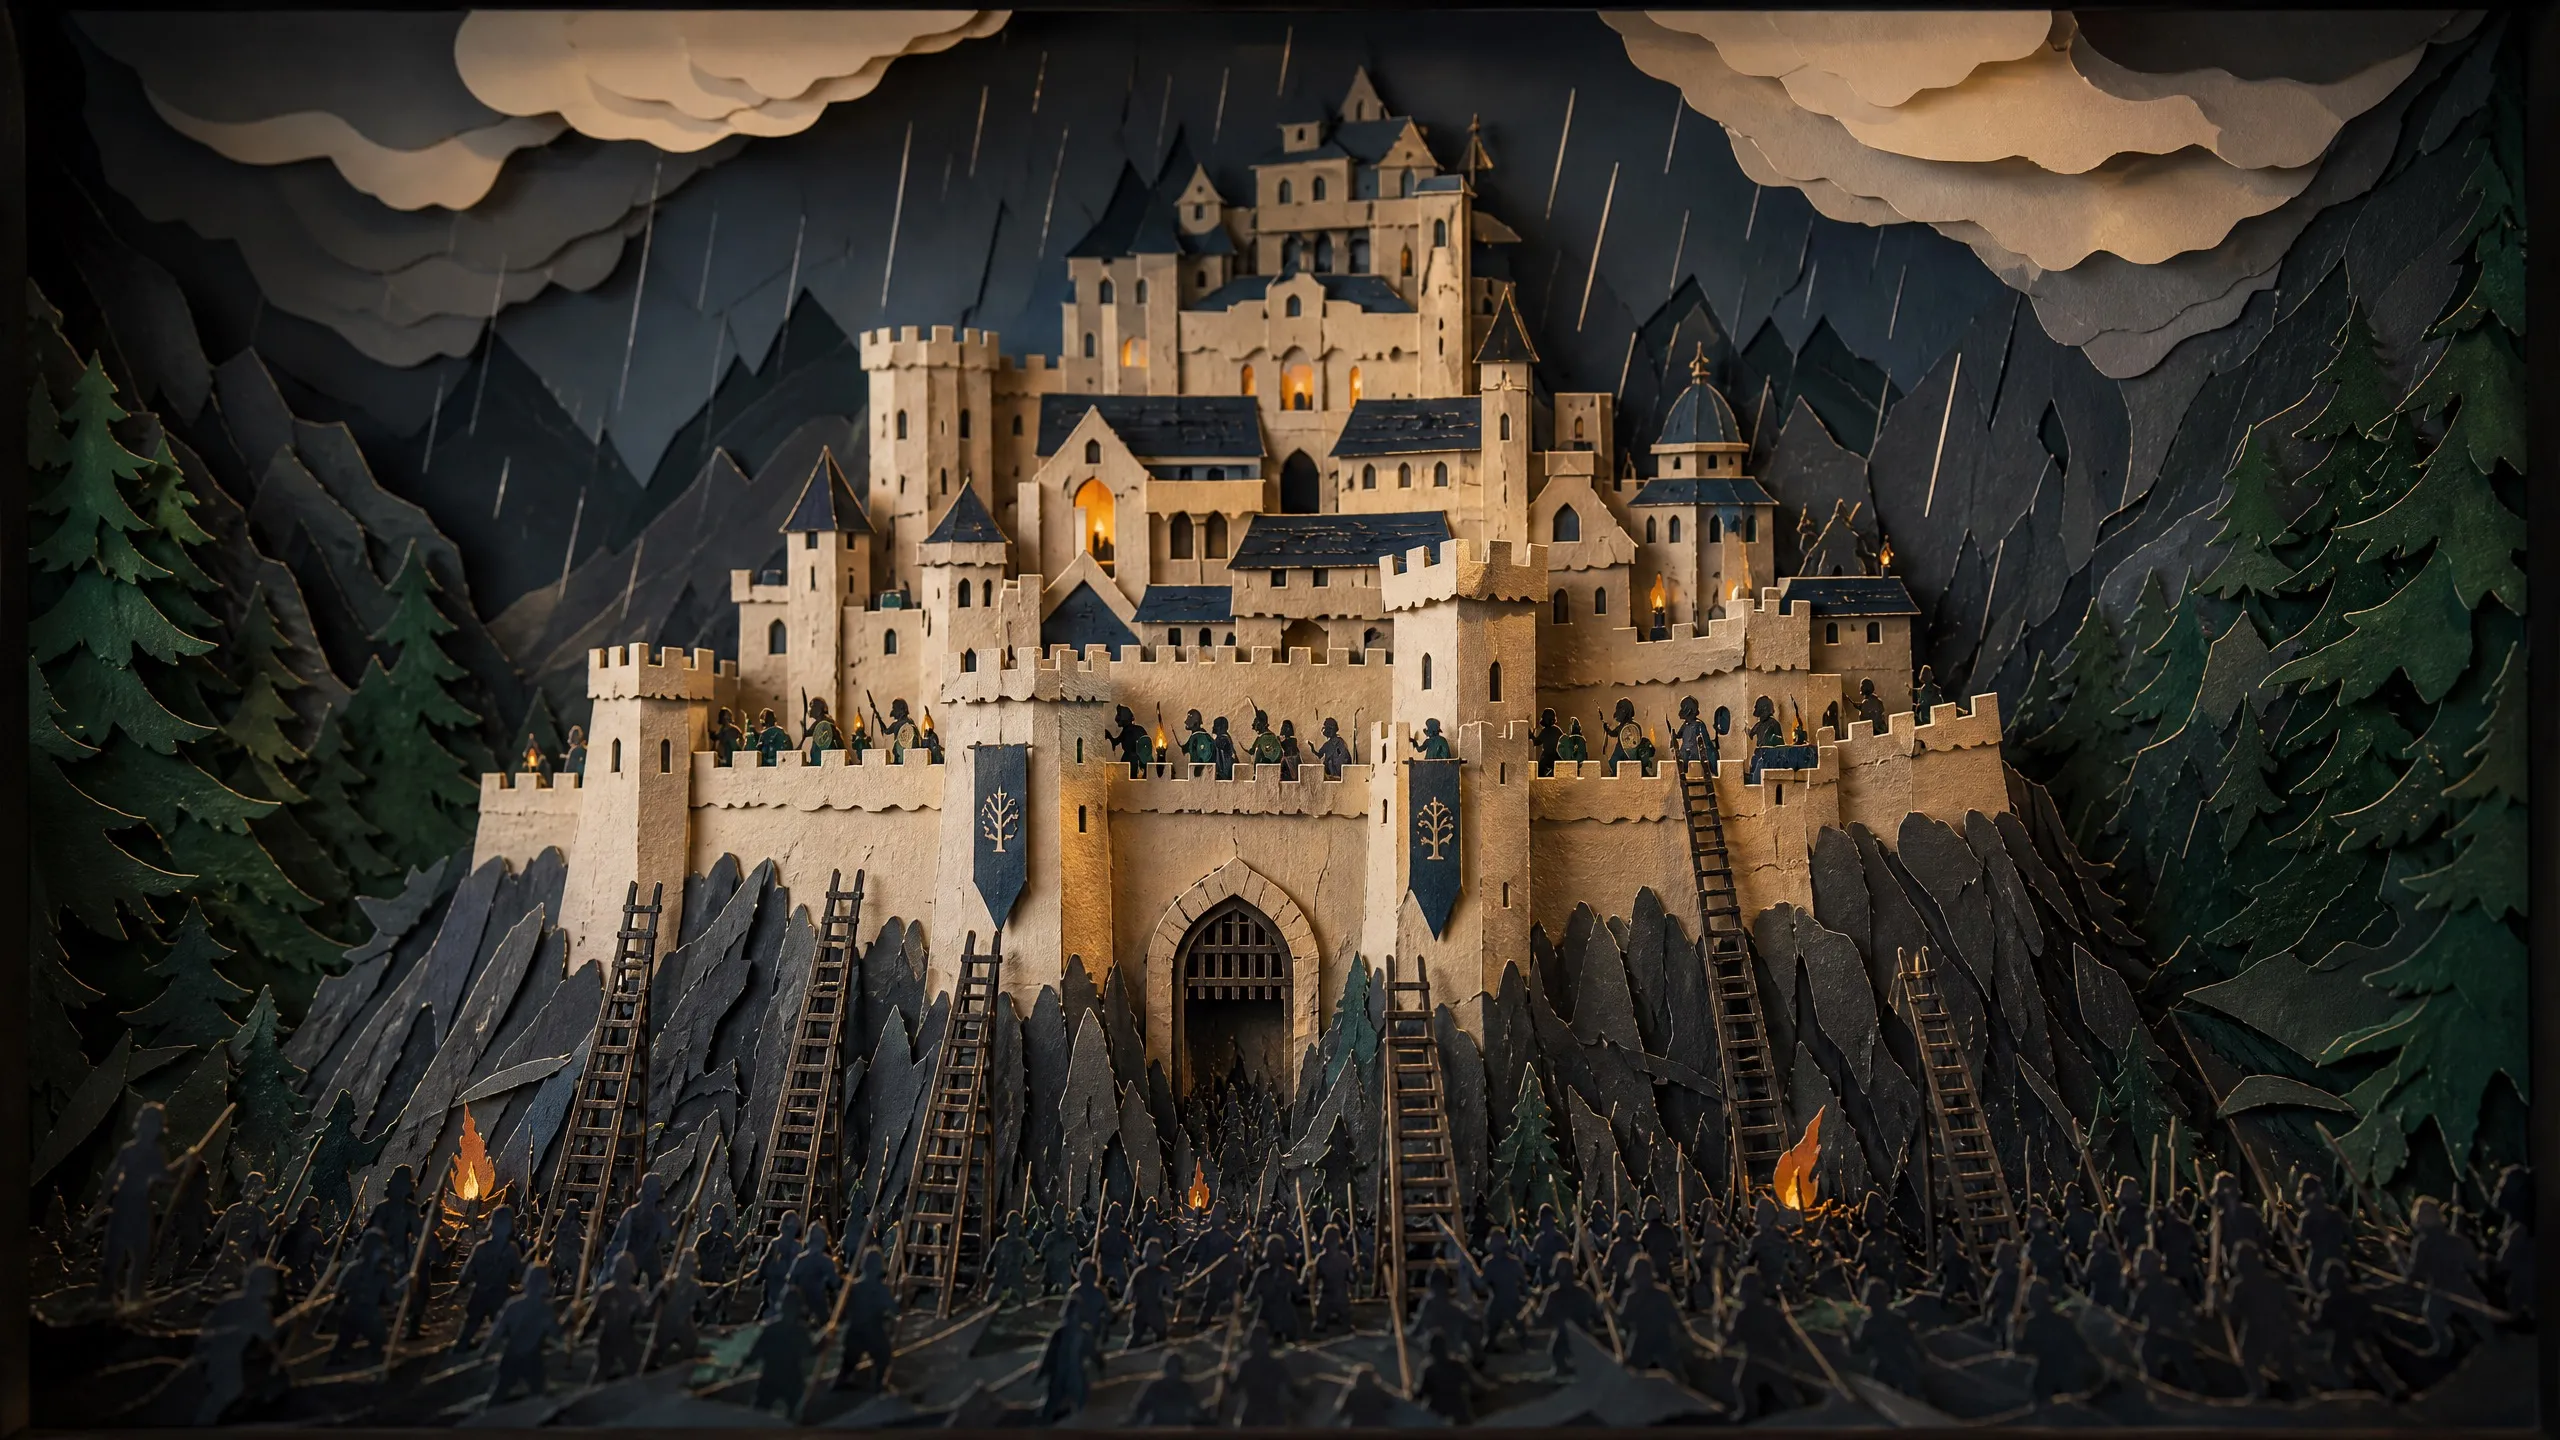
Helm's Deep
Run date: 2026-08-17
Generation provenance: unrecorded
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
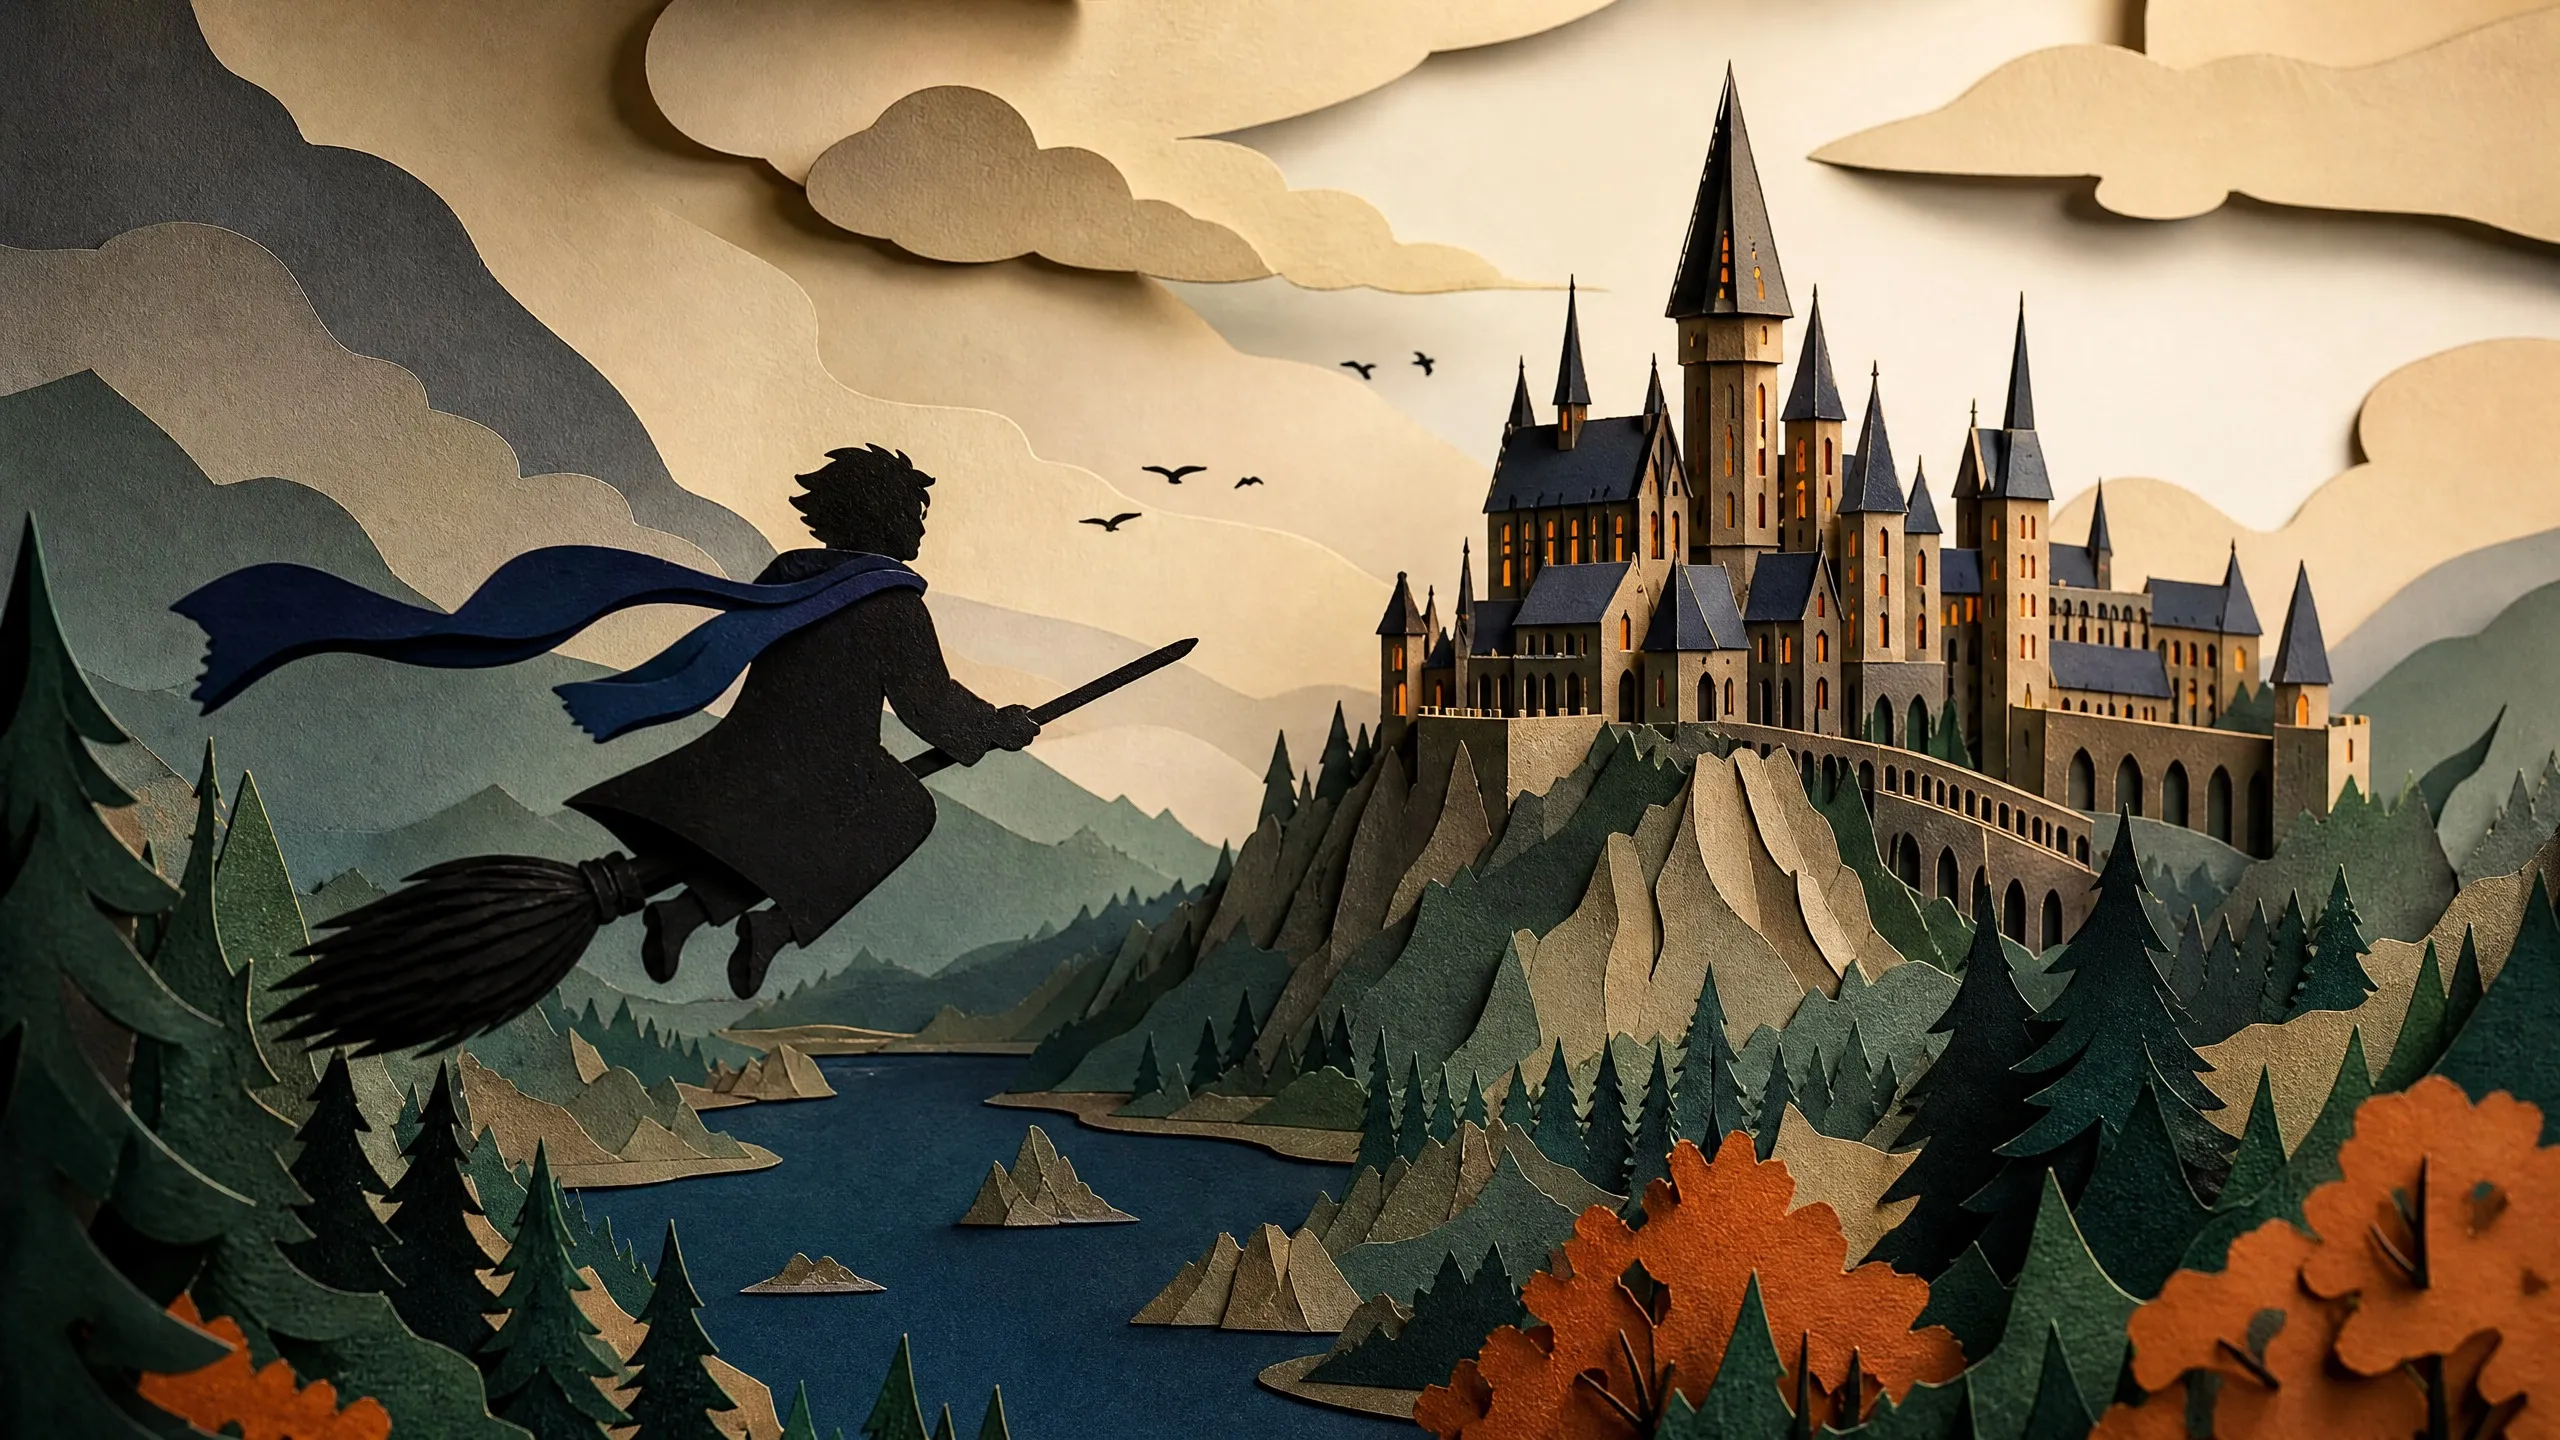
Hogwarts Broom Flight Simulator
Run date: 2026-08-17
Generation provenance: unrecorded
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Low-Poly Tower Defense
Run date: 2026-08-17
Generation provenance: unrecorded
Superbench 2.1 returning brief · original 1.x run protocol
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
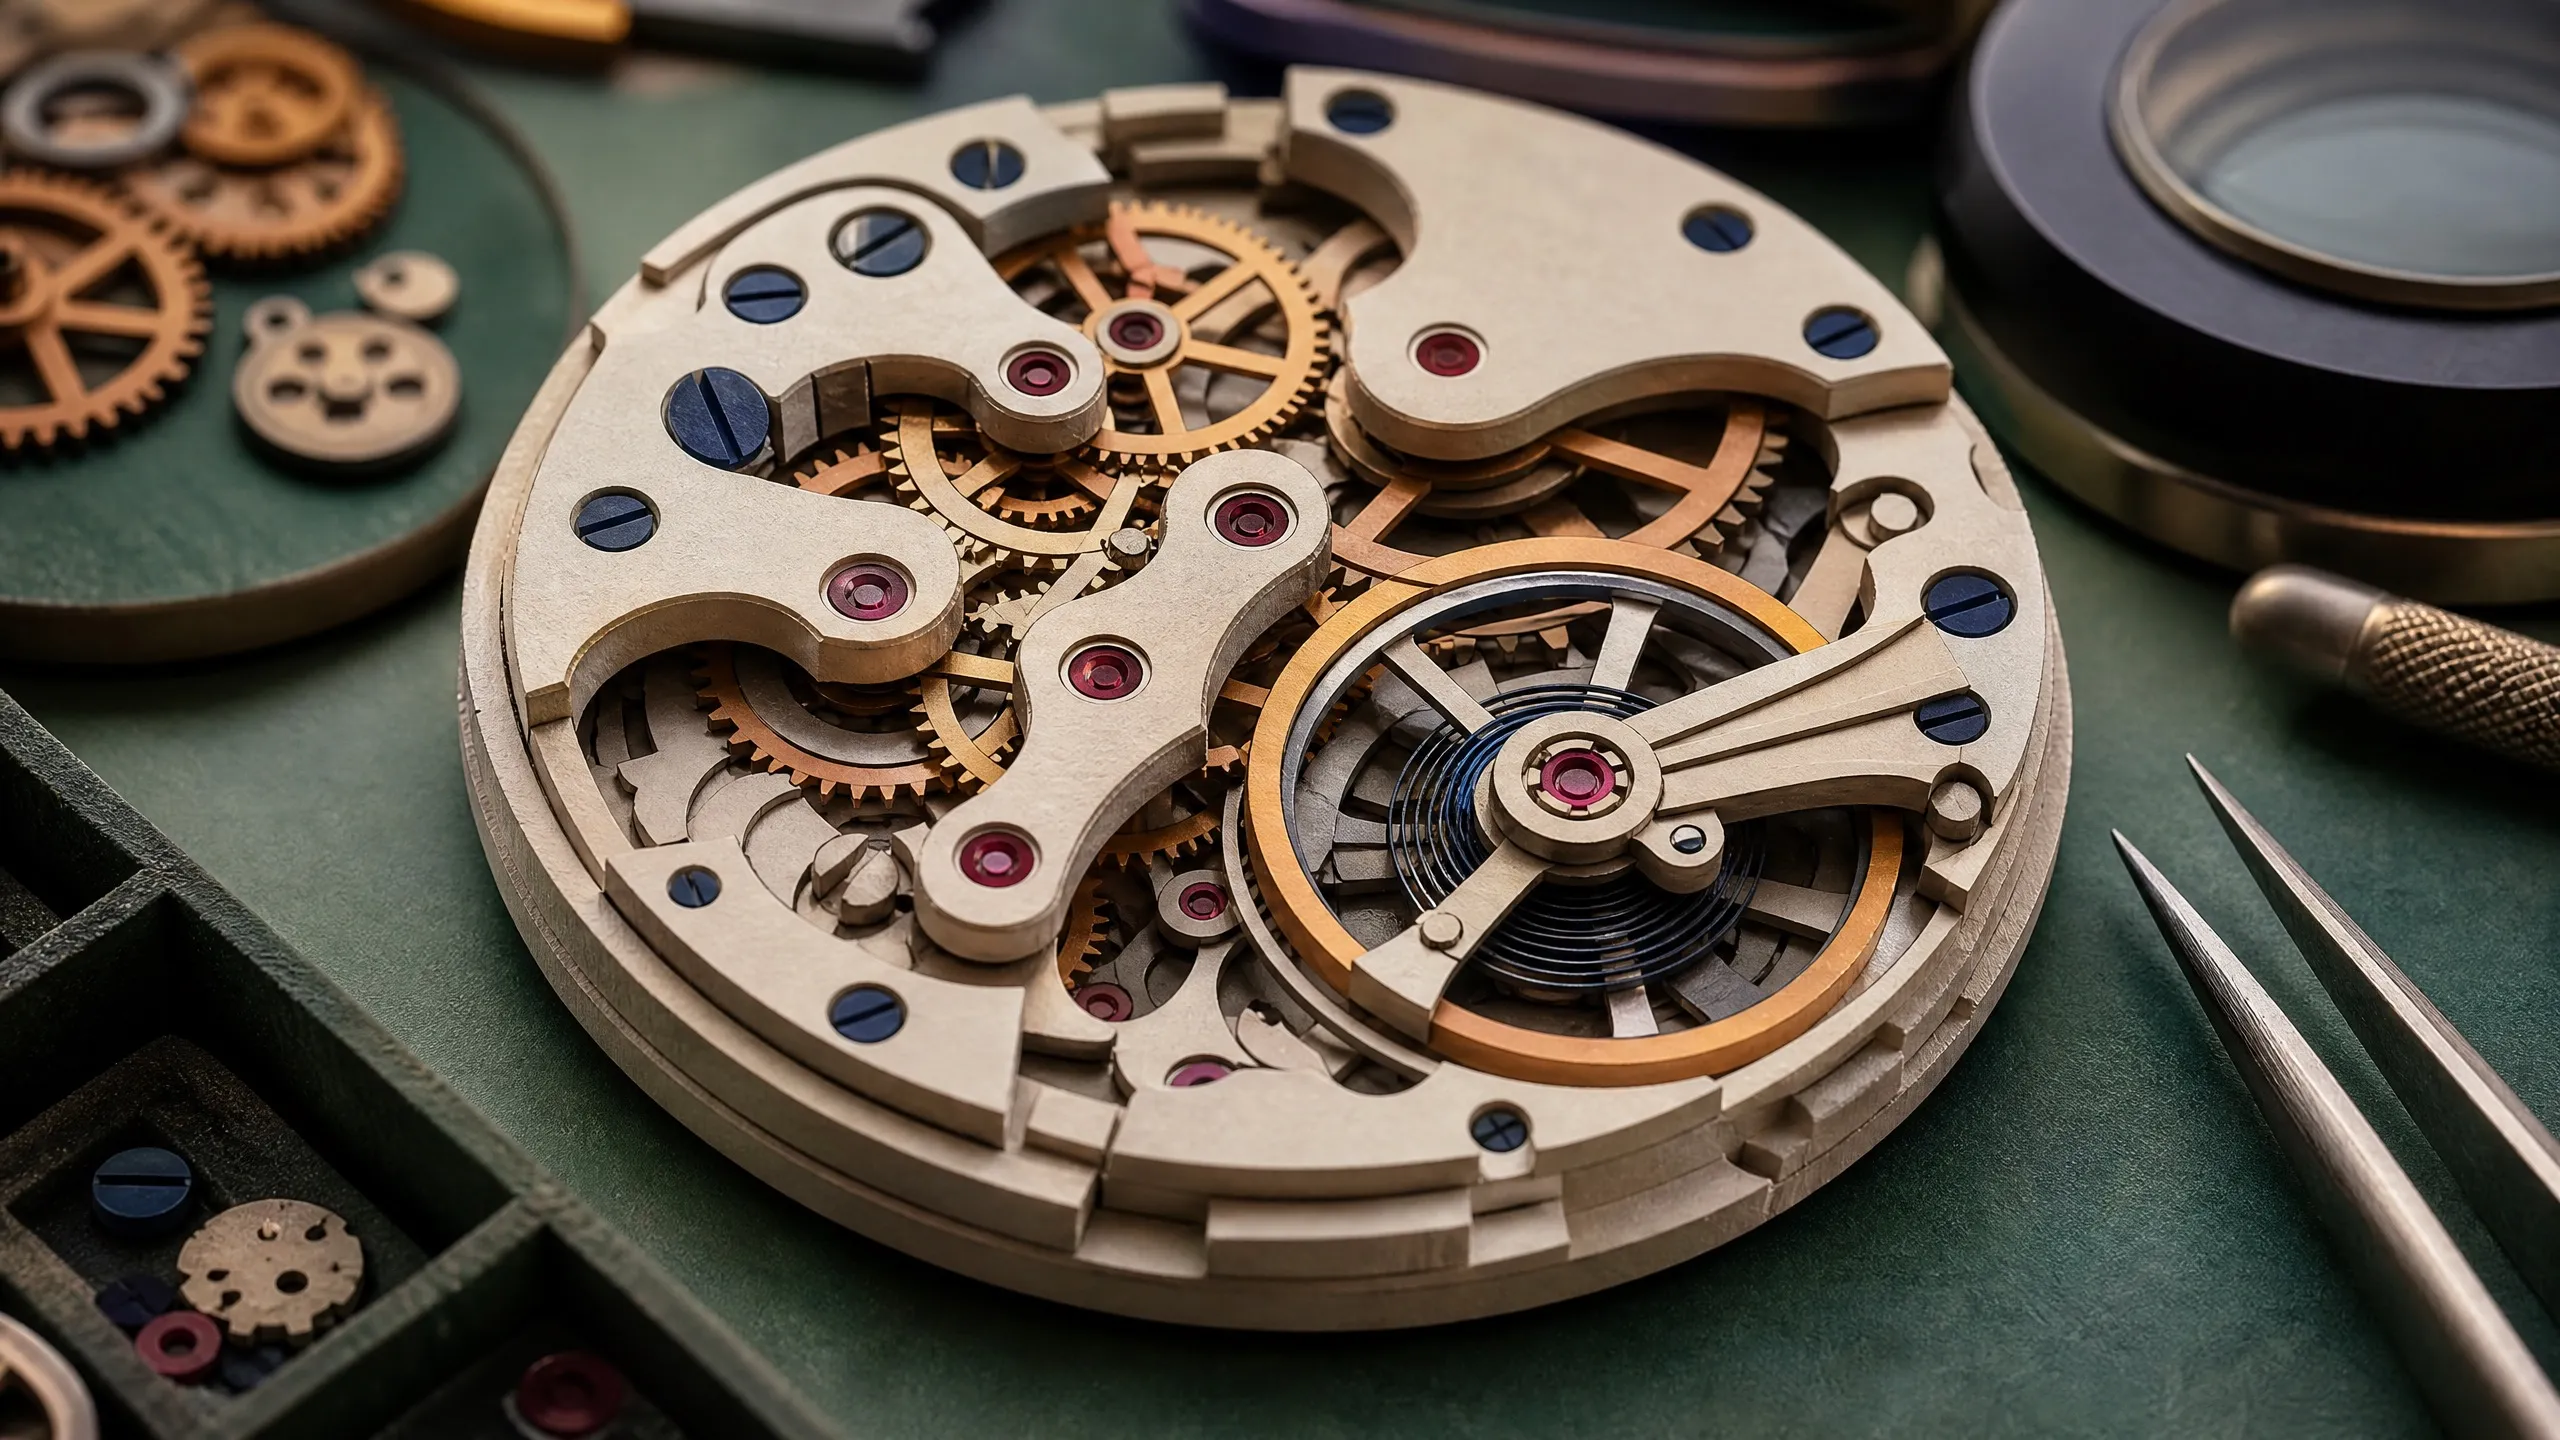
Mechanical Watch Simulator
Run date: 2026-08-17
Generation provenance: unrecorded
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Run date: 2026-08-17
Generation provenance: unrecorded
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-08-17
Generation provenance: unrecorded
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
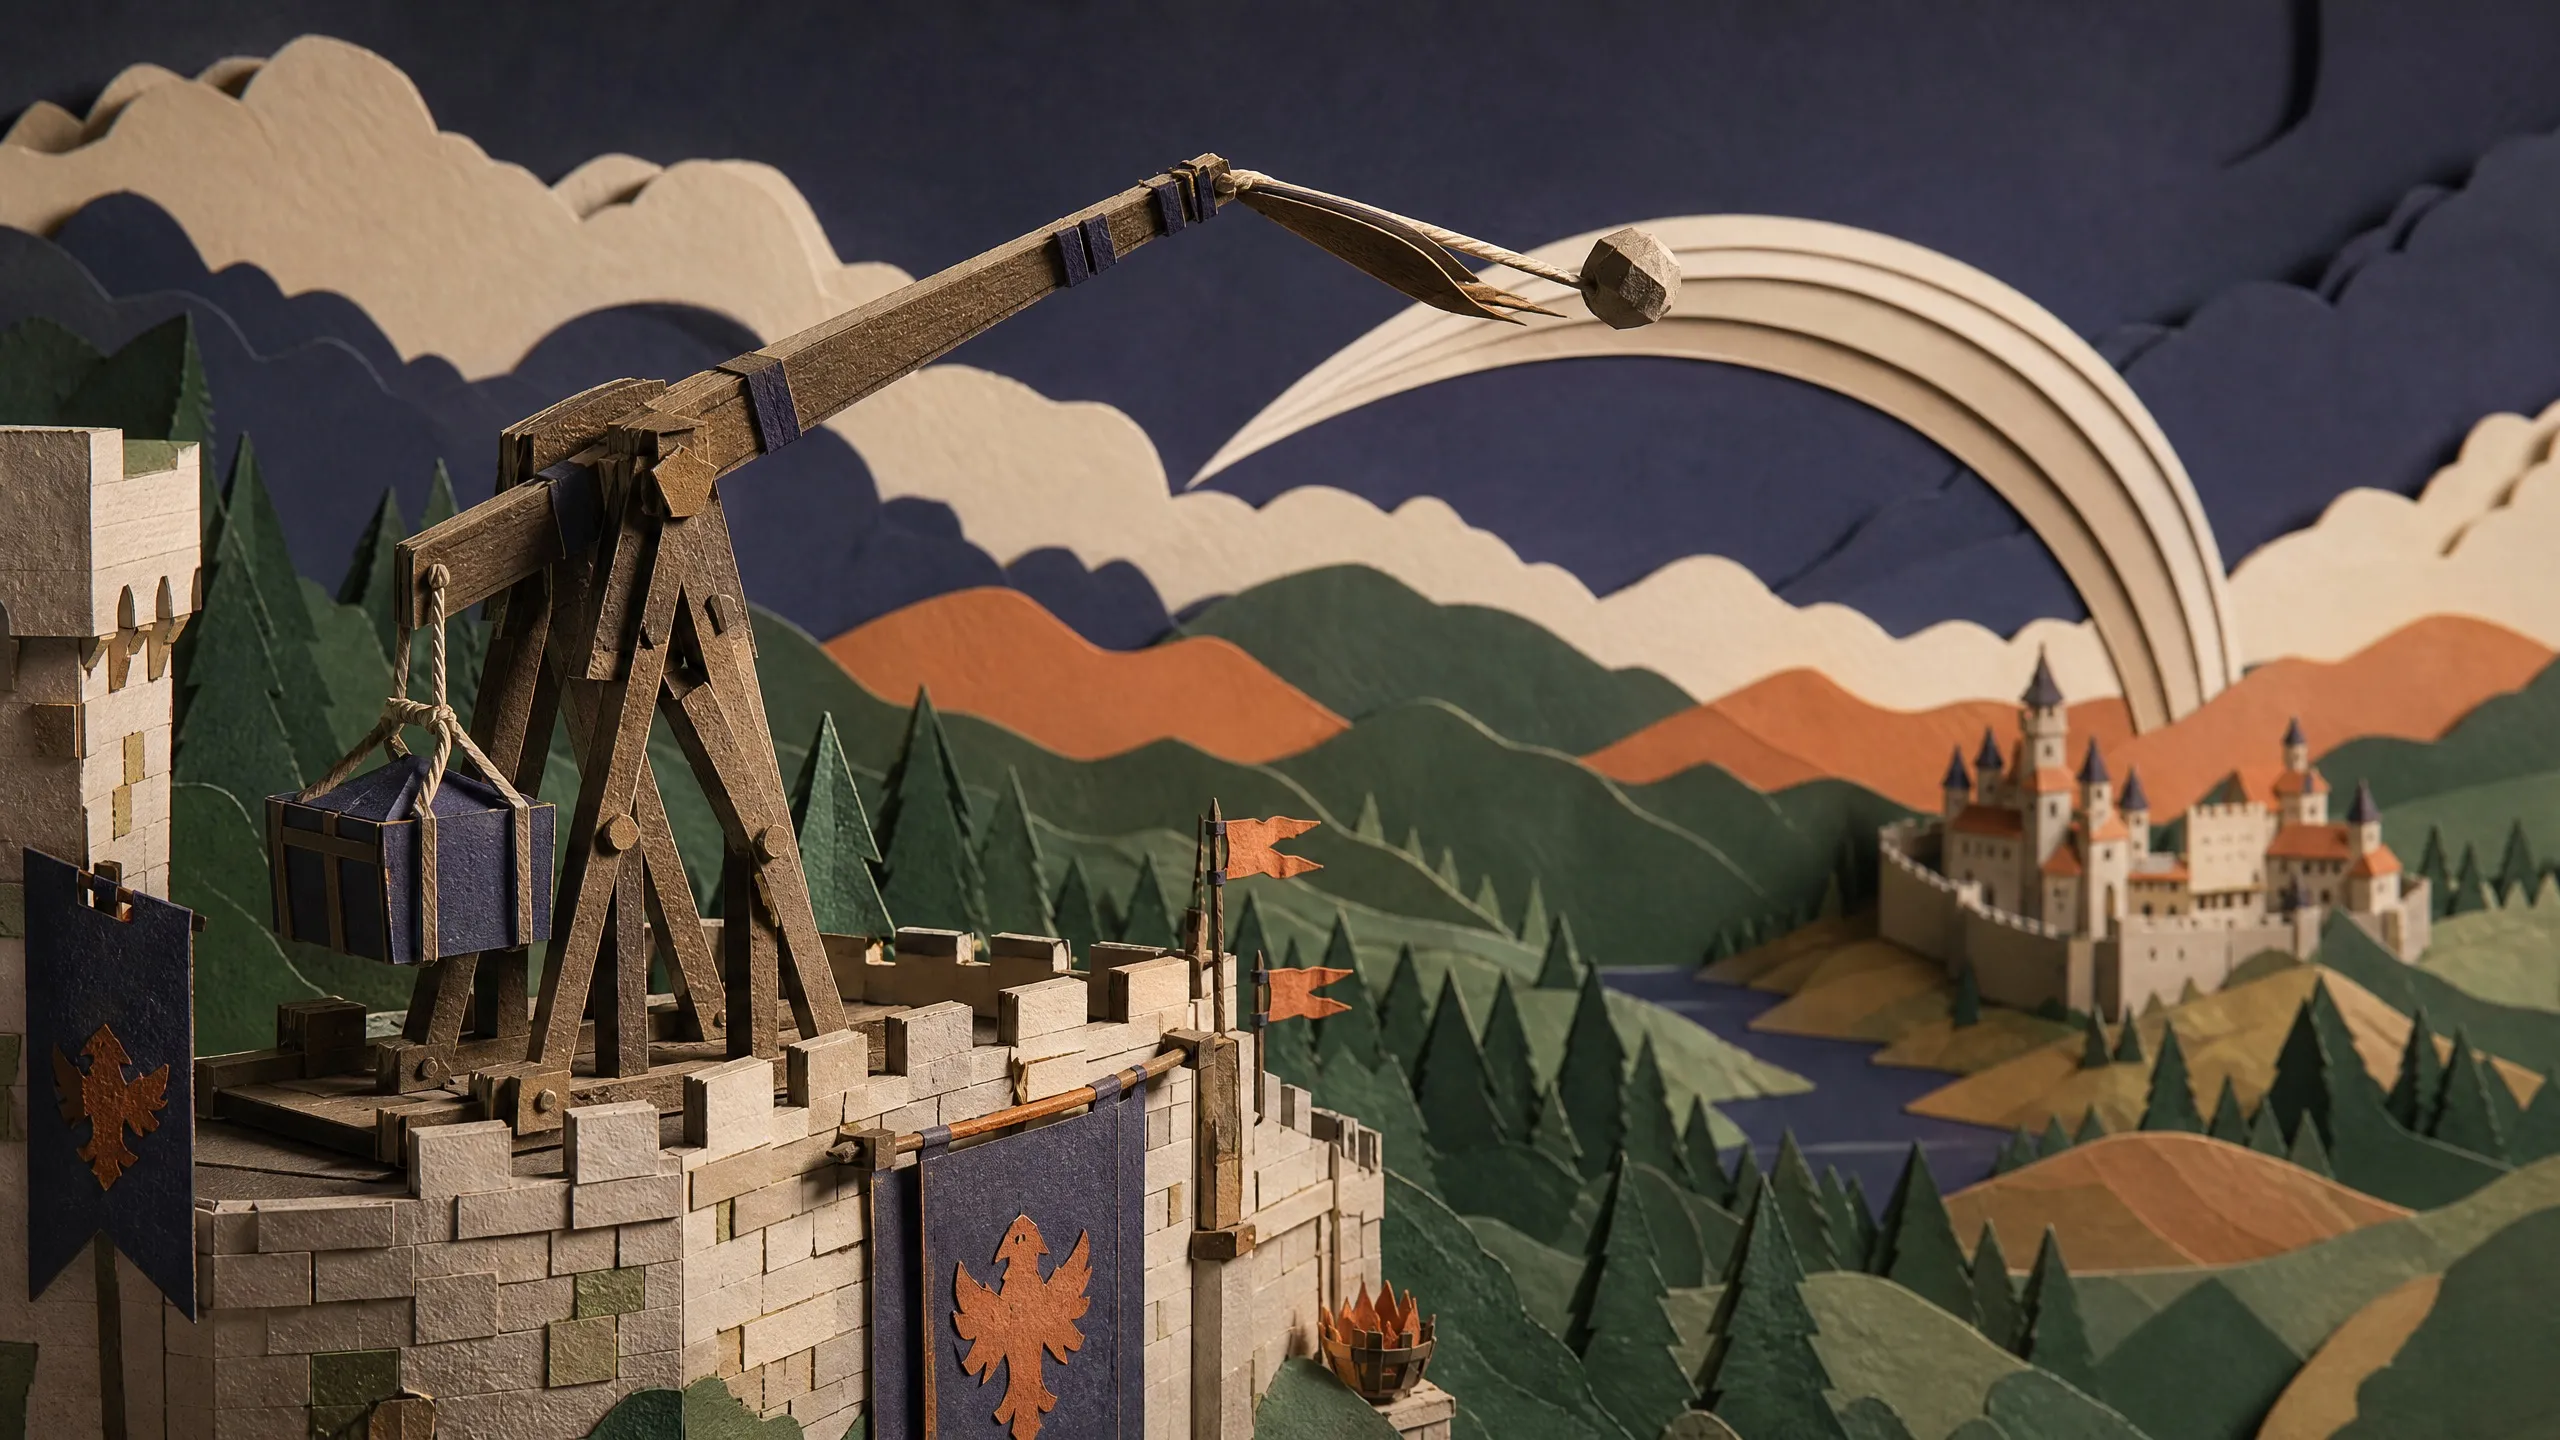
Stormwind Trebuchet Simulator
Run date: 2026-08-17
Generation provenance: unrecorded
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
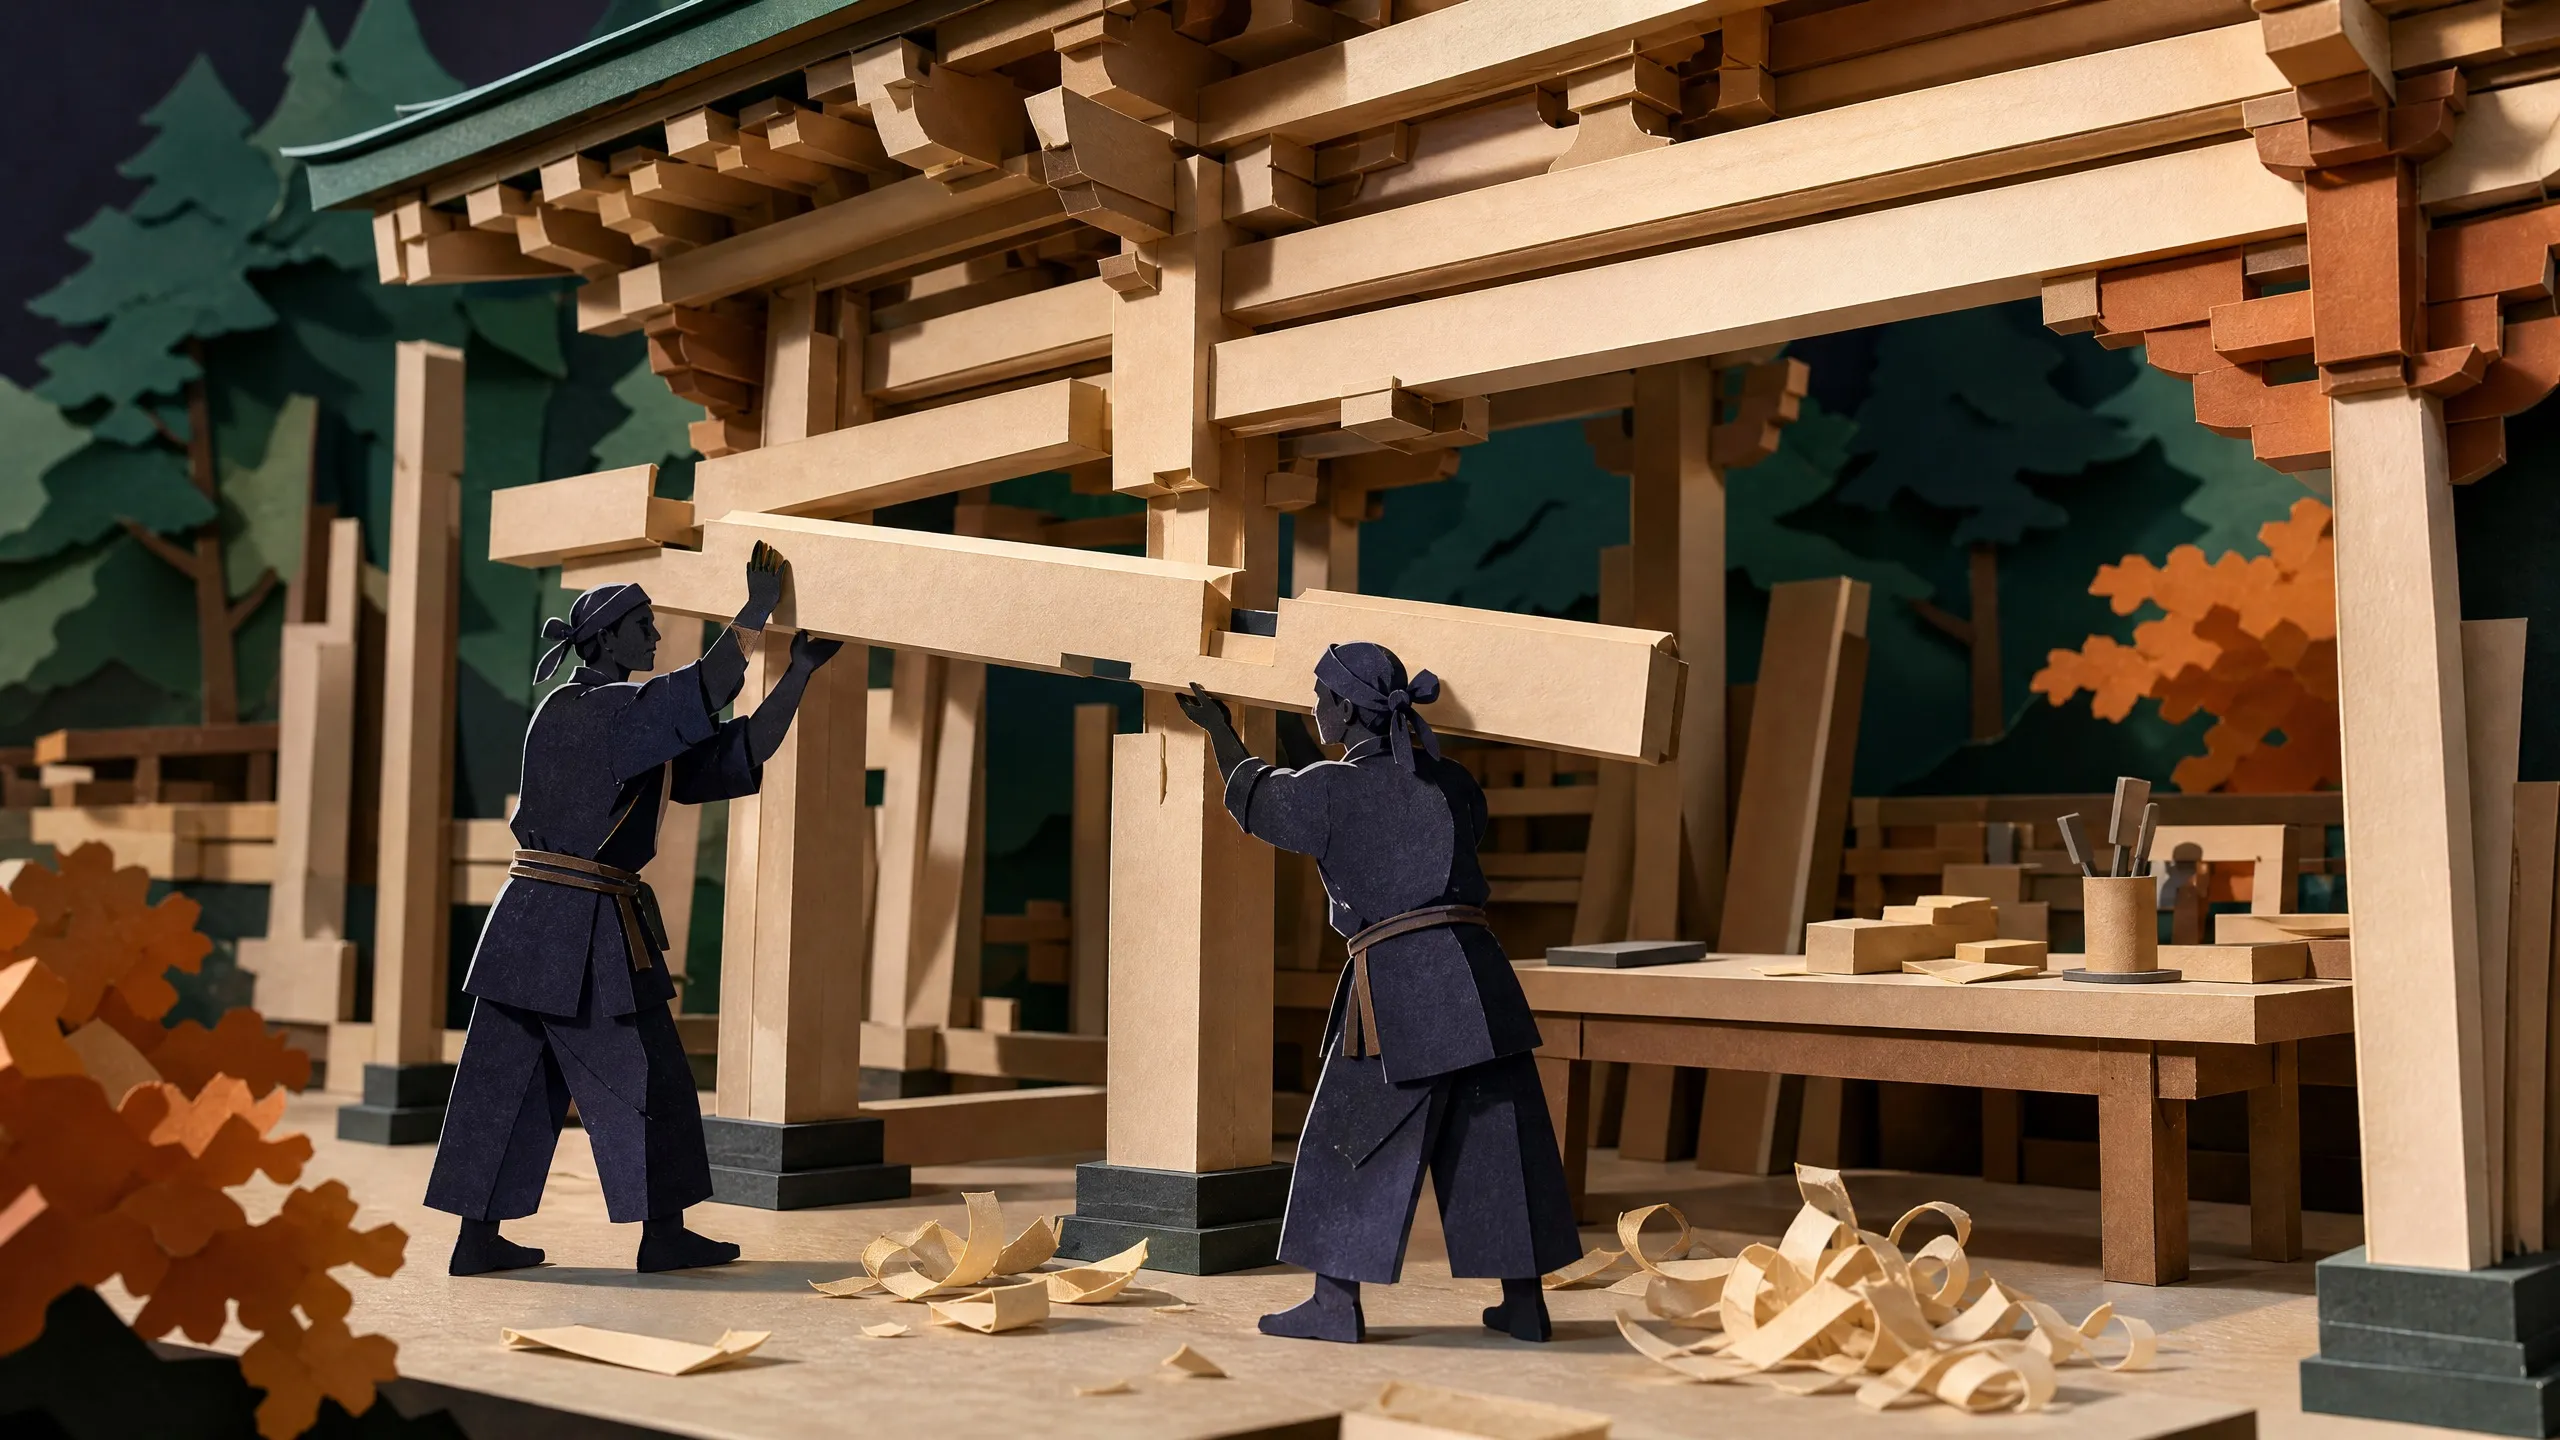
Yingzao Fashi Assembly
Run date: 2026-08-17
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How GLM 5.3 compares
2 peers with published comparison scores.
- GLM 5.3 This model
- Claude Mythos 5
- GPT-5.6 Sol
1 benchmarks · 3 models
Official benchmark profile
GLM-5.3 coding, agent, and cybersecurity results.
Terminal-Bench 3.0
28.3%DeepSWE v1.1
66.9%Agents’ Last Exam (CLI)
28.5%Full official benchmark table6 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| Terminal-Bench 3.0 | Agentic coding | 28.3% | |
| DeepSWE v1.1 | Coding | 66.9% | |
| Agents’ Last Exam (CLI) | Terminal agents | 28.5% | |
| GDPval-AA v2 | Professional work | 1769 Elo | |
| CyberGym | Cybersecurity | 84.5% | |
| ExploitBench | Cybersecurity | 54.4% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Preview / limited access
- API model ID
- Not publicly verified
- Context
- 1M
- Max output
- 128K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- Z.ai API · USD / 1M tokens
- $1.4 input · $0.26 cached input · $4.4 output
Cached-input storage is currently free for a limited time.
Benchmark sources
Z.ai reports large gains over GLM-5.2 across coding, terminal-agent, and cybersecurity evaluations. These are vendor-reported launch results; the general GLM-5.3 API is still marked as coming soon.
Introducing GLM-5.3GLM-5.3 is available to GLM Coding Plan users. Z.ai says direct API access is coming soon.
Evaluation settings
- Z.ai launch result; GLM-5.2 scored 4.6% in the same comparison.
- Z.ai launch result; GLM-5.2 scored 46.2% in the same comparison.
- Z.ai launch result; GLM-5.2 scored 23.8% in the same comparison.
- Z.ai-reported Artificial Analysis occupational-work result.
- Z.ai launch result.
- Z.ai launch result; GLM-5.2 scored 24.4% in the same comparison.
Editorial verdict
Where this model fits
GLM 5.3 completed all 16 Superbash visual benchmarks in one local session; every artifact validates and runs. The first attempt stalled when the account hit its usage ceiling, but a lower-concurrency rerun completed the full set. B tier reflects its useful build coverage alongside the team's cost and access concerns; validation alone is not a quality score.
Best for
Watch out
Ranking rationale and evidence
Evidence
Superbash editorial model ranking
Takeaway: GLM 5.3 is currently placed in Tier B.
The November 2026 editorial roster places GLM 5.3 at rank 13.
Open source →Introducing GLM 5.3
Takeaway: Use GLM 5.3 for cost-conscious coding work after reviewing the output.
The model is currently available through Z.ai's Coding Plan; verify general API availability before building a direct integration.
Open source →Related guides