
Gemini 3.7 Flash
Fast, cheap, and surprisingly good for smaller UI builds.
API pricing
USD per million tokens · Gemini API Standard paid tier- Input
- $0.75
- Output
- $3.75
- Cached input
- $0.075
- Context window
- 1.05M
Try the visual runs
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
Helm's Deep
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
Hogwarts Broom Flight Simulator
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Jabberwock
Dark fantasy encounter testing creature design, forest mood, and narrative staging.

Low-Poly Tower Defense
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.

Low Poly World
Stylized island build testing composition, color, and low-poly worldbuilding.
Mechanical Watch Simulator
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Office Life
Workplace vignette testing everyday scene logic, objects, and believable office detail.

Petri Dish
Microscopic ecosystem testing organic forms, scientific clarity, and cellular detail.

Starfall Arena
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
Stormwind Trebuchet Simulator
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.

Universe Simulator
Cosmic system testing orbital structure, glowing bodies, scale, and simulation readability.

Vice City
Neon coastal city testing vehicles, architecture, atmosphere, and dense urban layout.
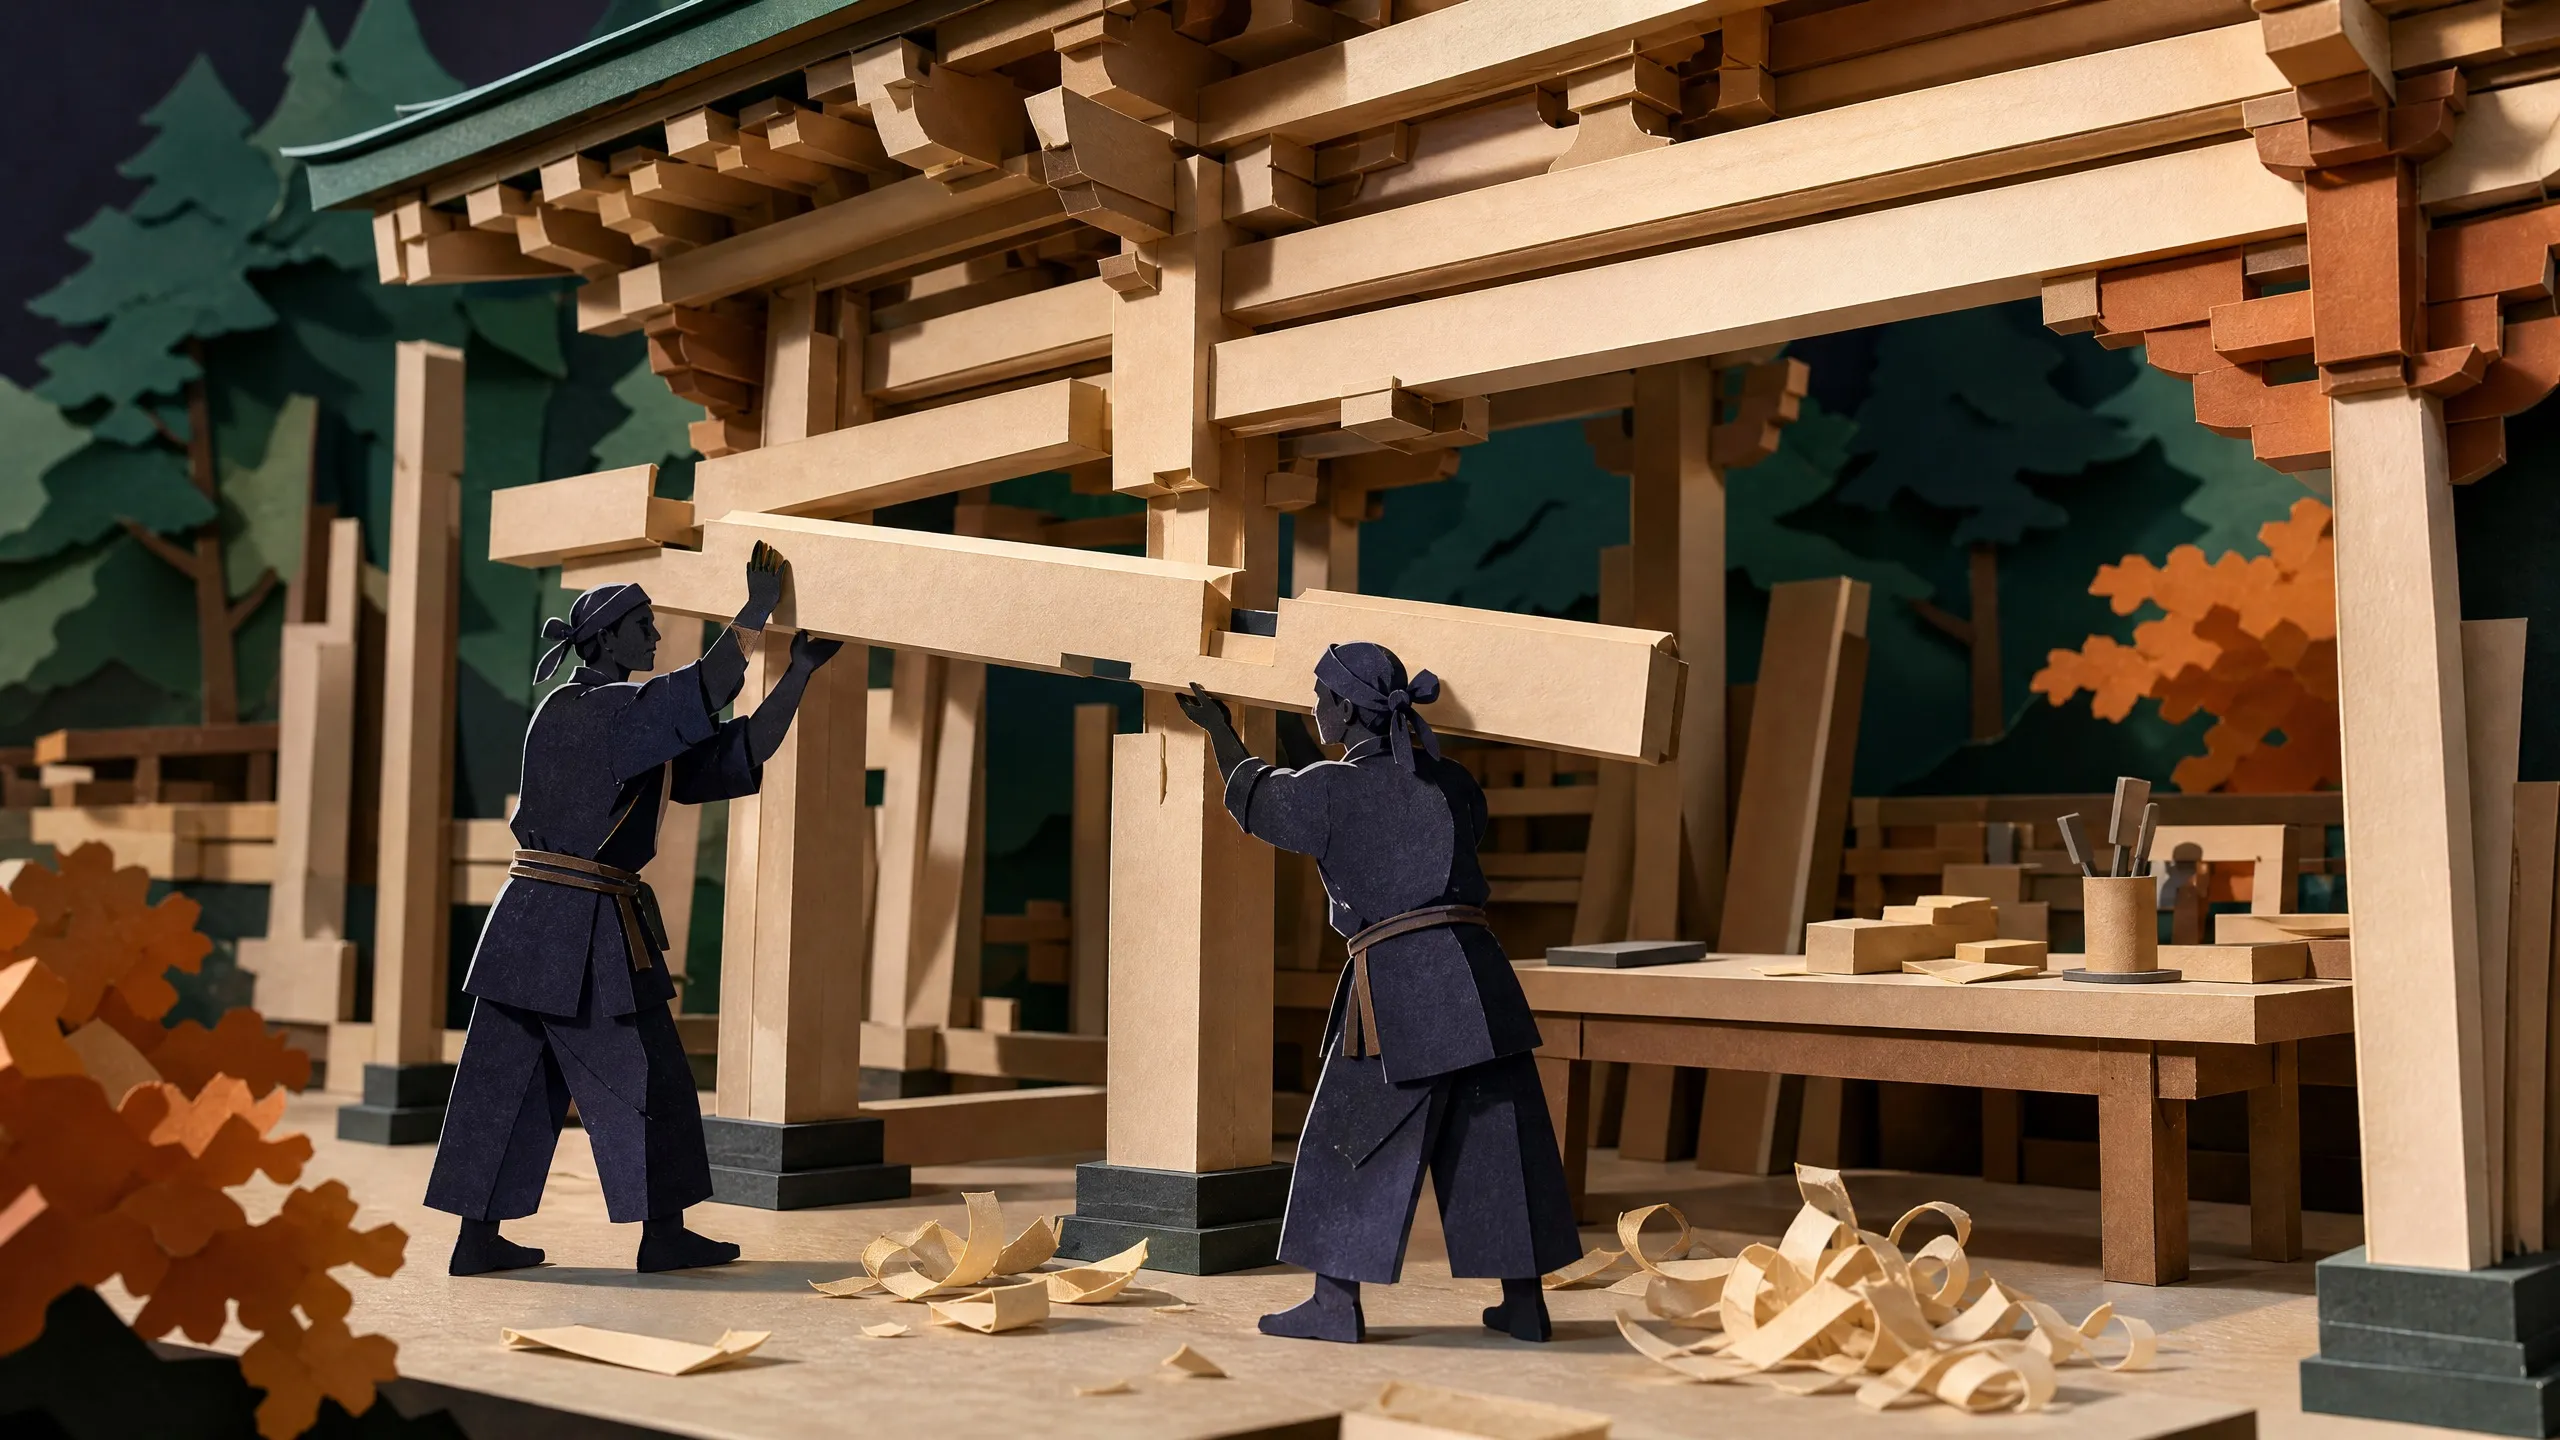
Yingzao Fashi Assembly
Timber assembly scene testing structure, joinery, construction order, and material clarity.
How Gemini 3.7 Flash compares
Three relevant peers, side by side.
- Gemini 3.7 Flash This model
- Gemini 3.6 Flash
- Claude Sonnet 5
- GPT-5.6 Terra
6 benchmarks · 4 models
Official benchmark profile
Google’s published Gemini 3.7 Flash coding, agent, multimodal, and research results.
Artificial Analysis Intelligence Index
56FrontierCode 1.1 Main
43.6%DeepSWE v1.1
65.3%Full official benchmark table20 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| Artificial Analysis Intelligence Index | Composite intelligence | 56 | |
| FrontierCode 1.1 Main | Production coding | 43.6% | |
| DeepSWE v1.1 | Long-horizon coding | 65.3% | |
| Code Arena | Web development | 1588 Elo | |
| Terminal-Bench 2.1 | Agentic coding | 85.8% | |
| Terminal-Bench 3.0 | General agent capabilities | 14.9% | |
| AutomationBench | Enterprise automation | 30.4% | |
| GDPVal-AA v2 | Knowledge work | 1525 Elo | |
| Harvey LAB-AA | Legal workflows | 90.7% | |
| GDP.pdf | Document reasoning | 34.0% | |
| CharXiv Reasoning — no tools | Chart reasoning | 84.5% | |
| CharXiv Reasoning — with tools | Tool-assisted chart reasoning | 88.7% | |
| LVBench | Long-video understanding | 85.4% | |
| GDM-MRCR v2 (8-needle) | Long context | 97.0% | |
| OSWorld 2.0 | Computer use | 47.9% | |
| Agent’s Last Exam | Desktop agents | 26.3% | |
| HLE-Verified | Expert reasoning | 53.6% | |
| BioMysteryBench — human-solvable | Bioinformatics reasoning | 87.1% | |
| BioMysteryBench — human-difficult | Bioinformatics reasoning | 43.5% | |
| LABBench2 | Biology research | 82.1% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
gemini-3.7-flash- Context
- 1.05M
- Max output
- 66K
- License
- Not publicly verified
- Access route
- Gemini app, Gemini Enterprise, Gemini Enterprise Agent Platform, Google AI Studio, Gemini API, and Google Antigravity.
- Modalities
- text input, image input, audio input, video input, PDF input, text output
- Hardware
- Not publicly verified
- Gemini API Standard paid tier · USD / 1M tokens
- $0.75 input · $0.075 cached input · $3.75 output
Introductory rates through December 31, 2026. From January 1, 2027: $1.50 input, $0.15 cached input, and $7.50 output per 1M tokens. Output includes thinking tokens. Cache storage costs $0.50 per 1M tokens per hour during 2026, then $1.00; grounding is billed separately.
Benchmark sources
Google’s August 2026 model card publishes exact-model results across coding, terminal agents, enterprise automation, document and video understanding, long context, computer use, and scientific reasoning. Each row below retains the score type and the material harness details from Google’s accompanying methodology.
Gemini 3.7 Flash Model CardGoogle says Gemini scores are pass@1 unless noted, use the exact gemini-3.7-flash API model ID with default sampling unless specified, and average multiple trials on smaller benchmarks. Competitor values are generally provider-reported; the methodology identifies exceptions.
Evaluation settings
- Composite model-intelligence score in Google’s August 2026 comparison table.
- Score from the official public FrontierCode leaderboard.
- Google-computed result using a mini-SWE-agent harness, LiteLLM 1.96, and high thinking.
- Elo rating from the official public Web Dev leaderboard.
- Google-computed result using the default Terminus 2 agent harness.
- Google-computed result using a mini-SWE-agent harness and LiteLLM 1.96; two tasks were modified for Google’s container environment.
- Private-set result sourced from the official public AutomationBench leaderboard.
- Elo rating sourced from the Artificial Analysis public leaderboard.
- Complex legal-workflow result sourced from the Artificial Analysis public leaderboard.
- Google-computed expert PDF document-comprehension result.
- Google-computed information-synthesis result without tools.
- Google-computed result with Google Search and code execution enabled.
- Google-computed result using 1,024 frames and no tools.
- Google-computed cumulative score at an average 128K-token context.
- Partial score, maxed over three single-attempt runs at 1080p with a 500-step cap, screenshot-only observation, and the official evaluator.
- Pass rate using the default ALE-Claw harness.
- Google-computed accuracy on the full 1,811-item verified set; 689 uncertain original HLE items were excluded.
- Google-computed result with a Linux terminal, bioinformatics tools, Python, R, and restricted-domain internet access.
- Harder split with the same terminal, bioinformatics, Python, R, and restricted-domain internet tools.
- Google-computed real-world biology result with a Linux terminal, bioinformatics tools, Python, R, and internet access.
Editorial verdict
Where this model fits
Gemini 3.7 Flash sits at the top of B tier. Speed and cost still make it useful for one-shot UI and mobile-friendly layouts, even though the team no longer sees Google as leading the overall model race.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: Gemini 3.7 Flash is currently placed in Tier B.
The September 2026 editorial roster places Gemini 3.7 Flash at rank 10.
Open source →Gemini 3.7 Flash model page
Takeaway: Use Gemini 3.7 Flash for fast UI generation, not oversized builds.
Google documents a stable one-million-token model with multimodal input, a 65,536-token output limit, and temporary 2026 pricing. Superbash still treats quota availability as an operational caveat.
Open source →Related guides