
OpenAI
GPT-6 Luna
B-tier option for bounded builds, with ten published visual runs and a documented context caveat.
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-09-23
Specialist test · evaluated separately
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.
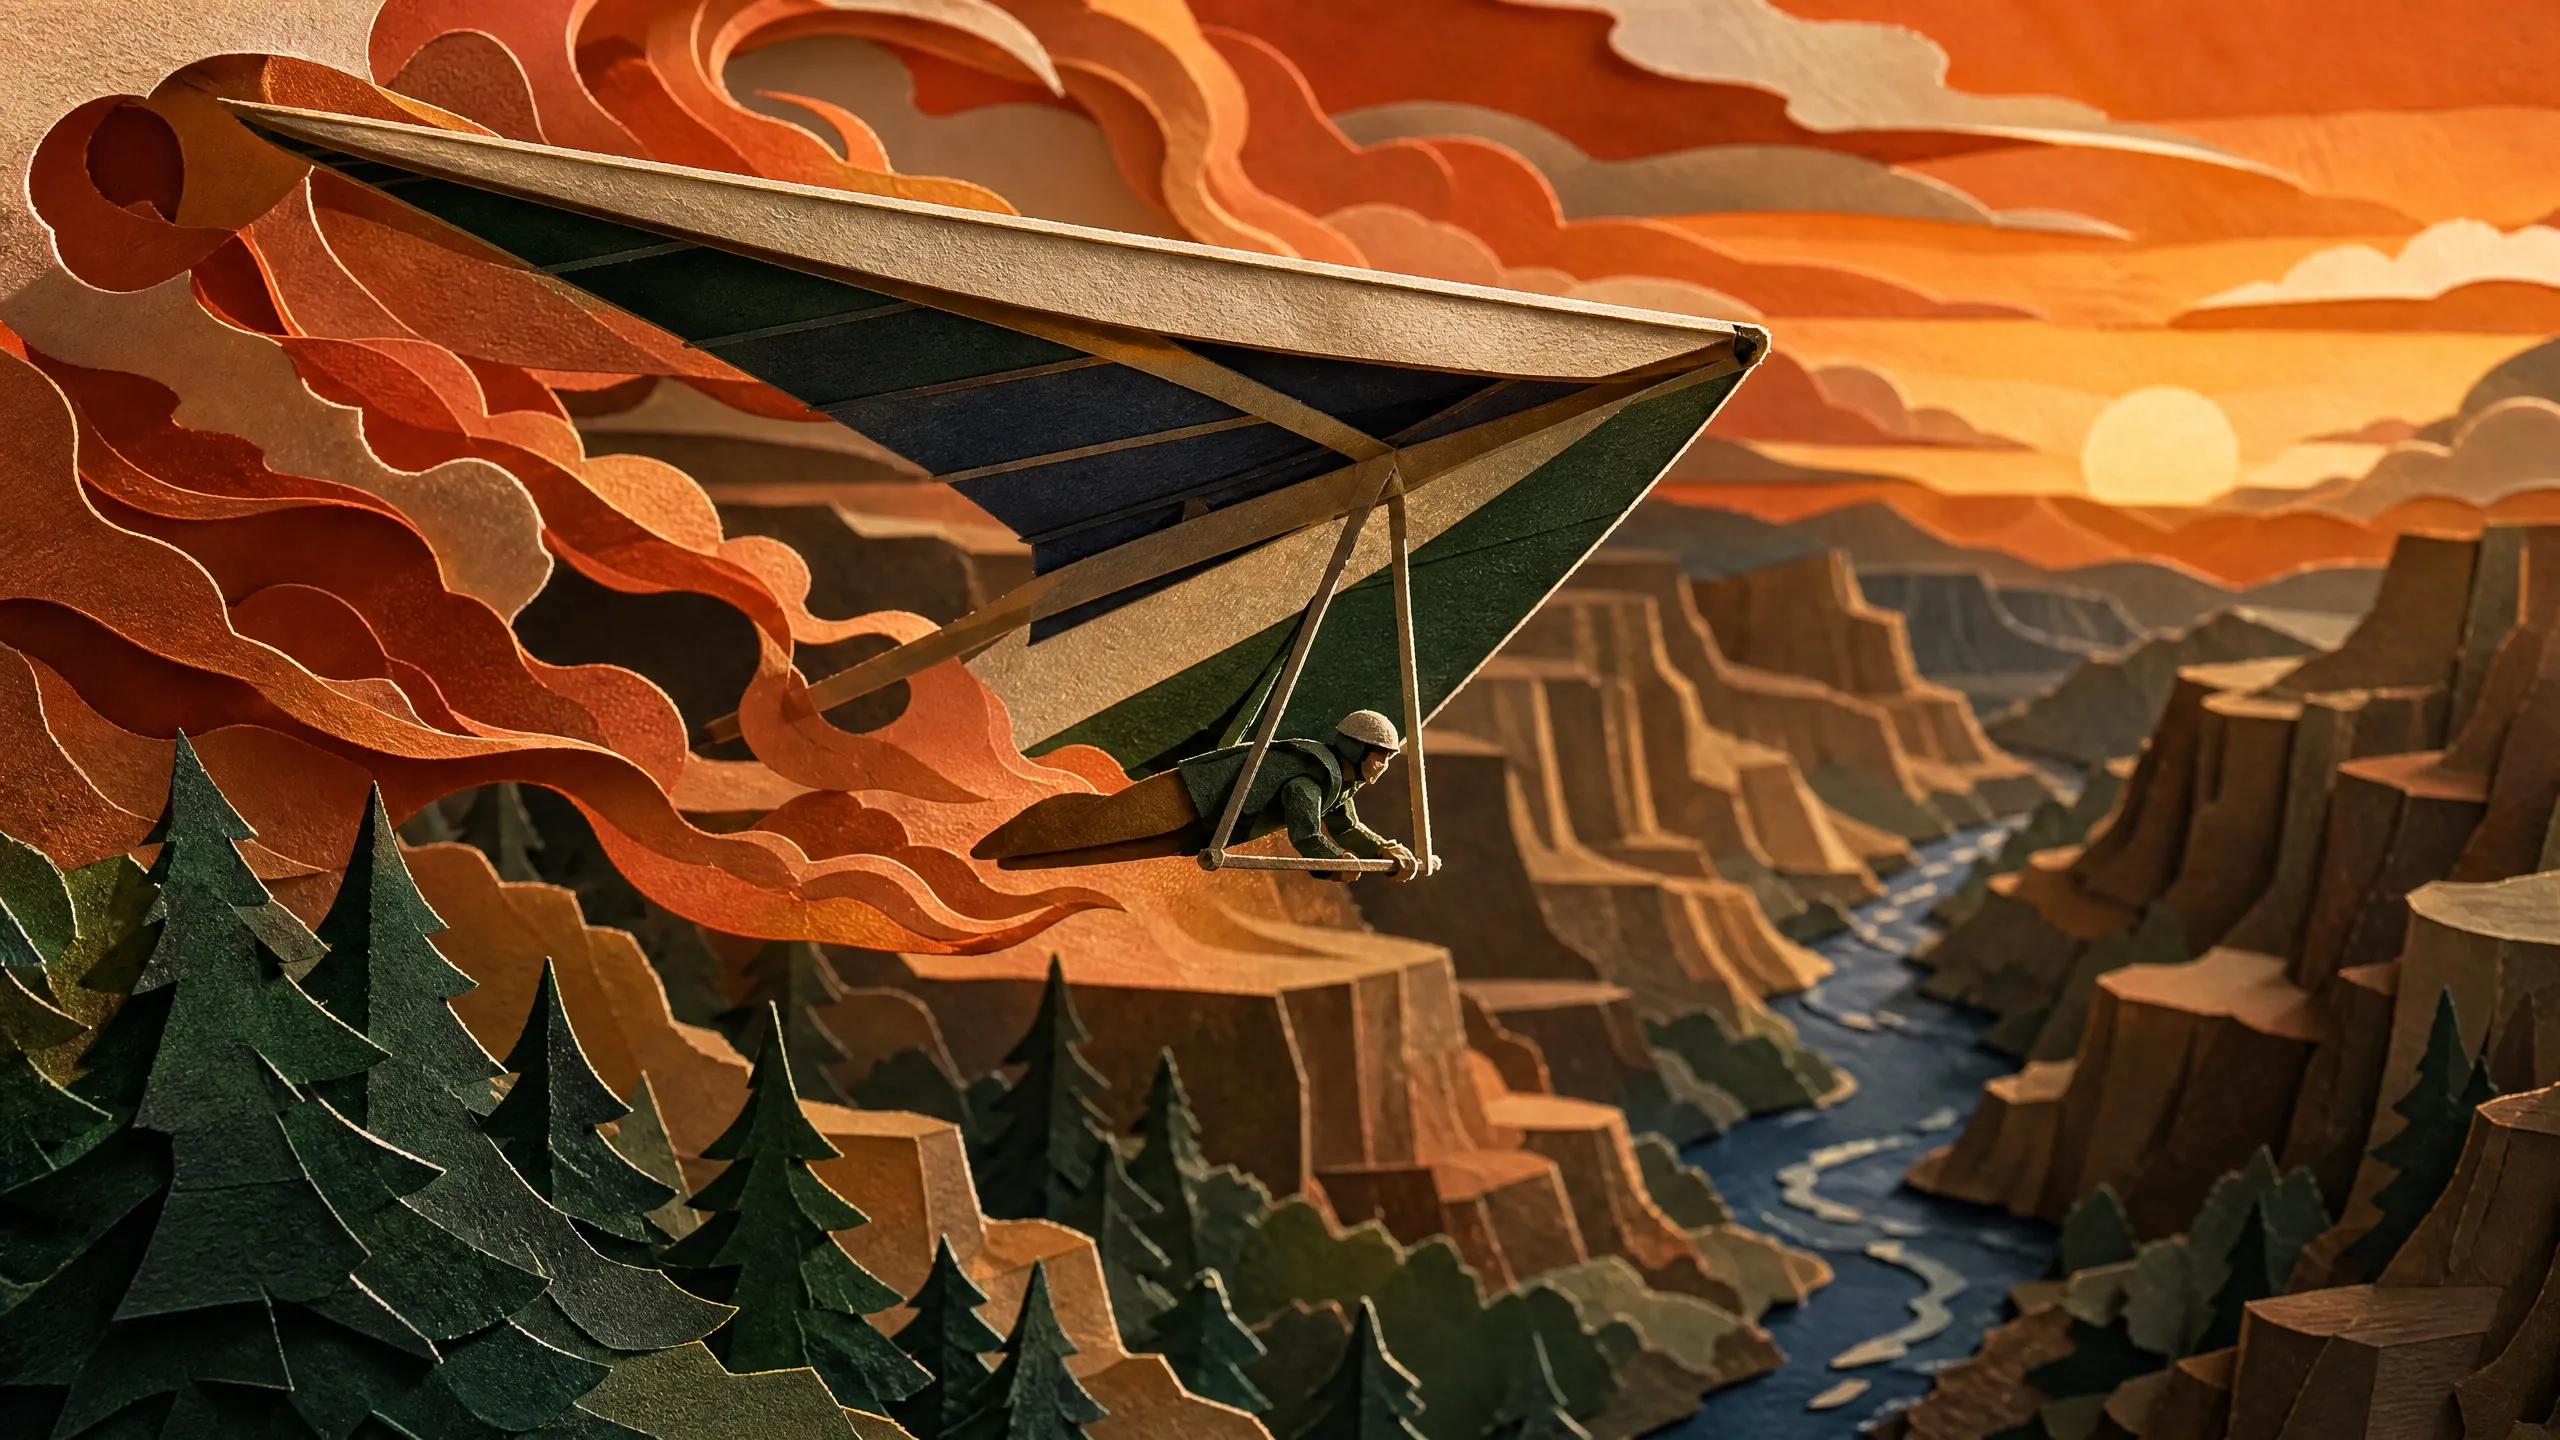
Ember Glider
Run date: 2026-09-23
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
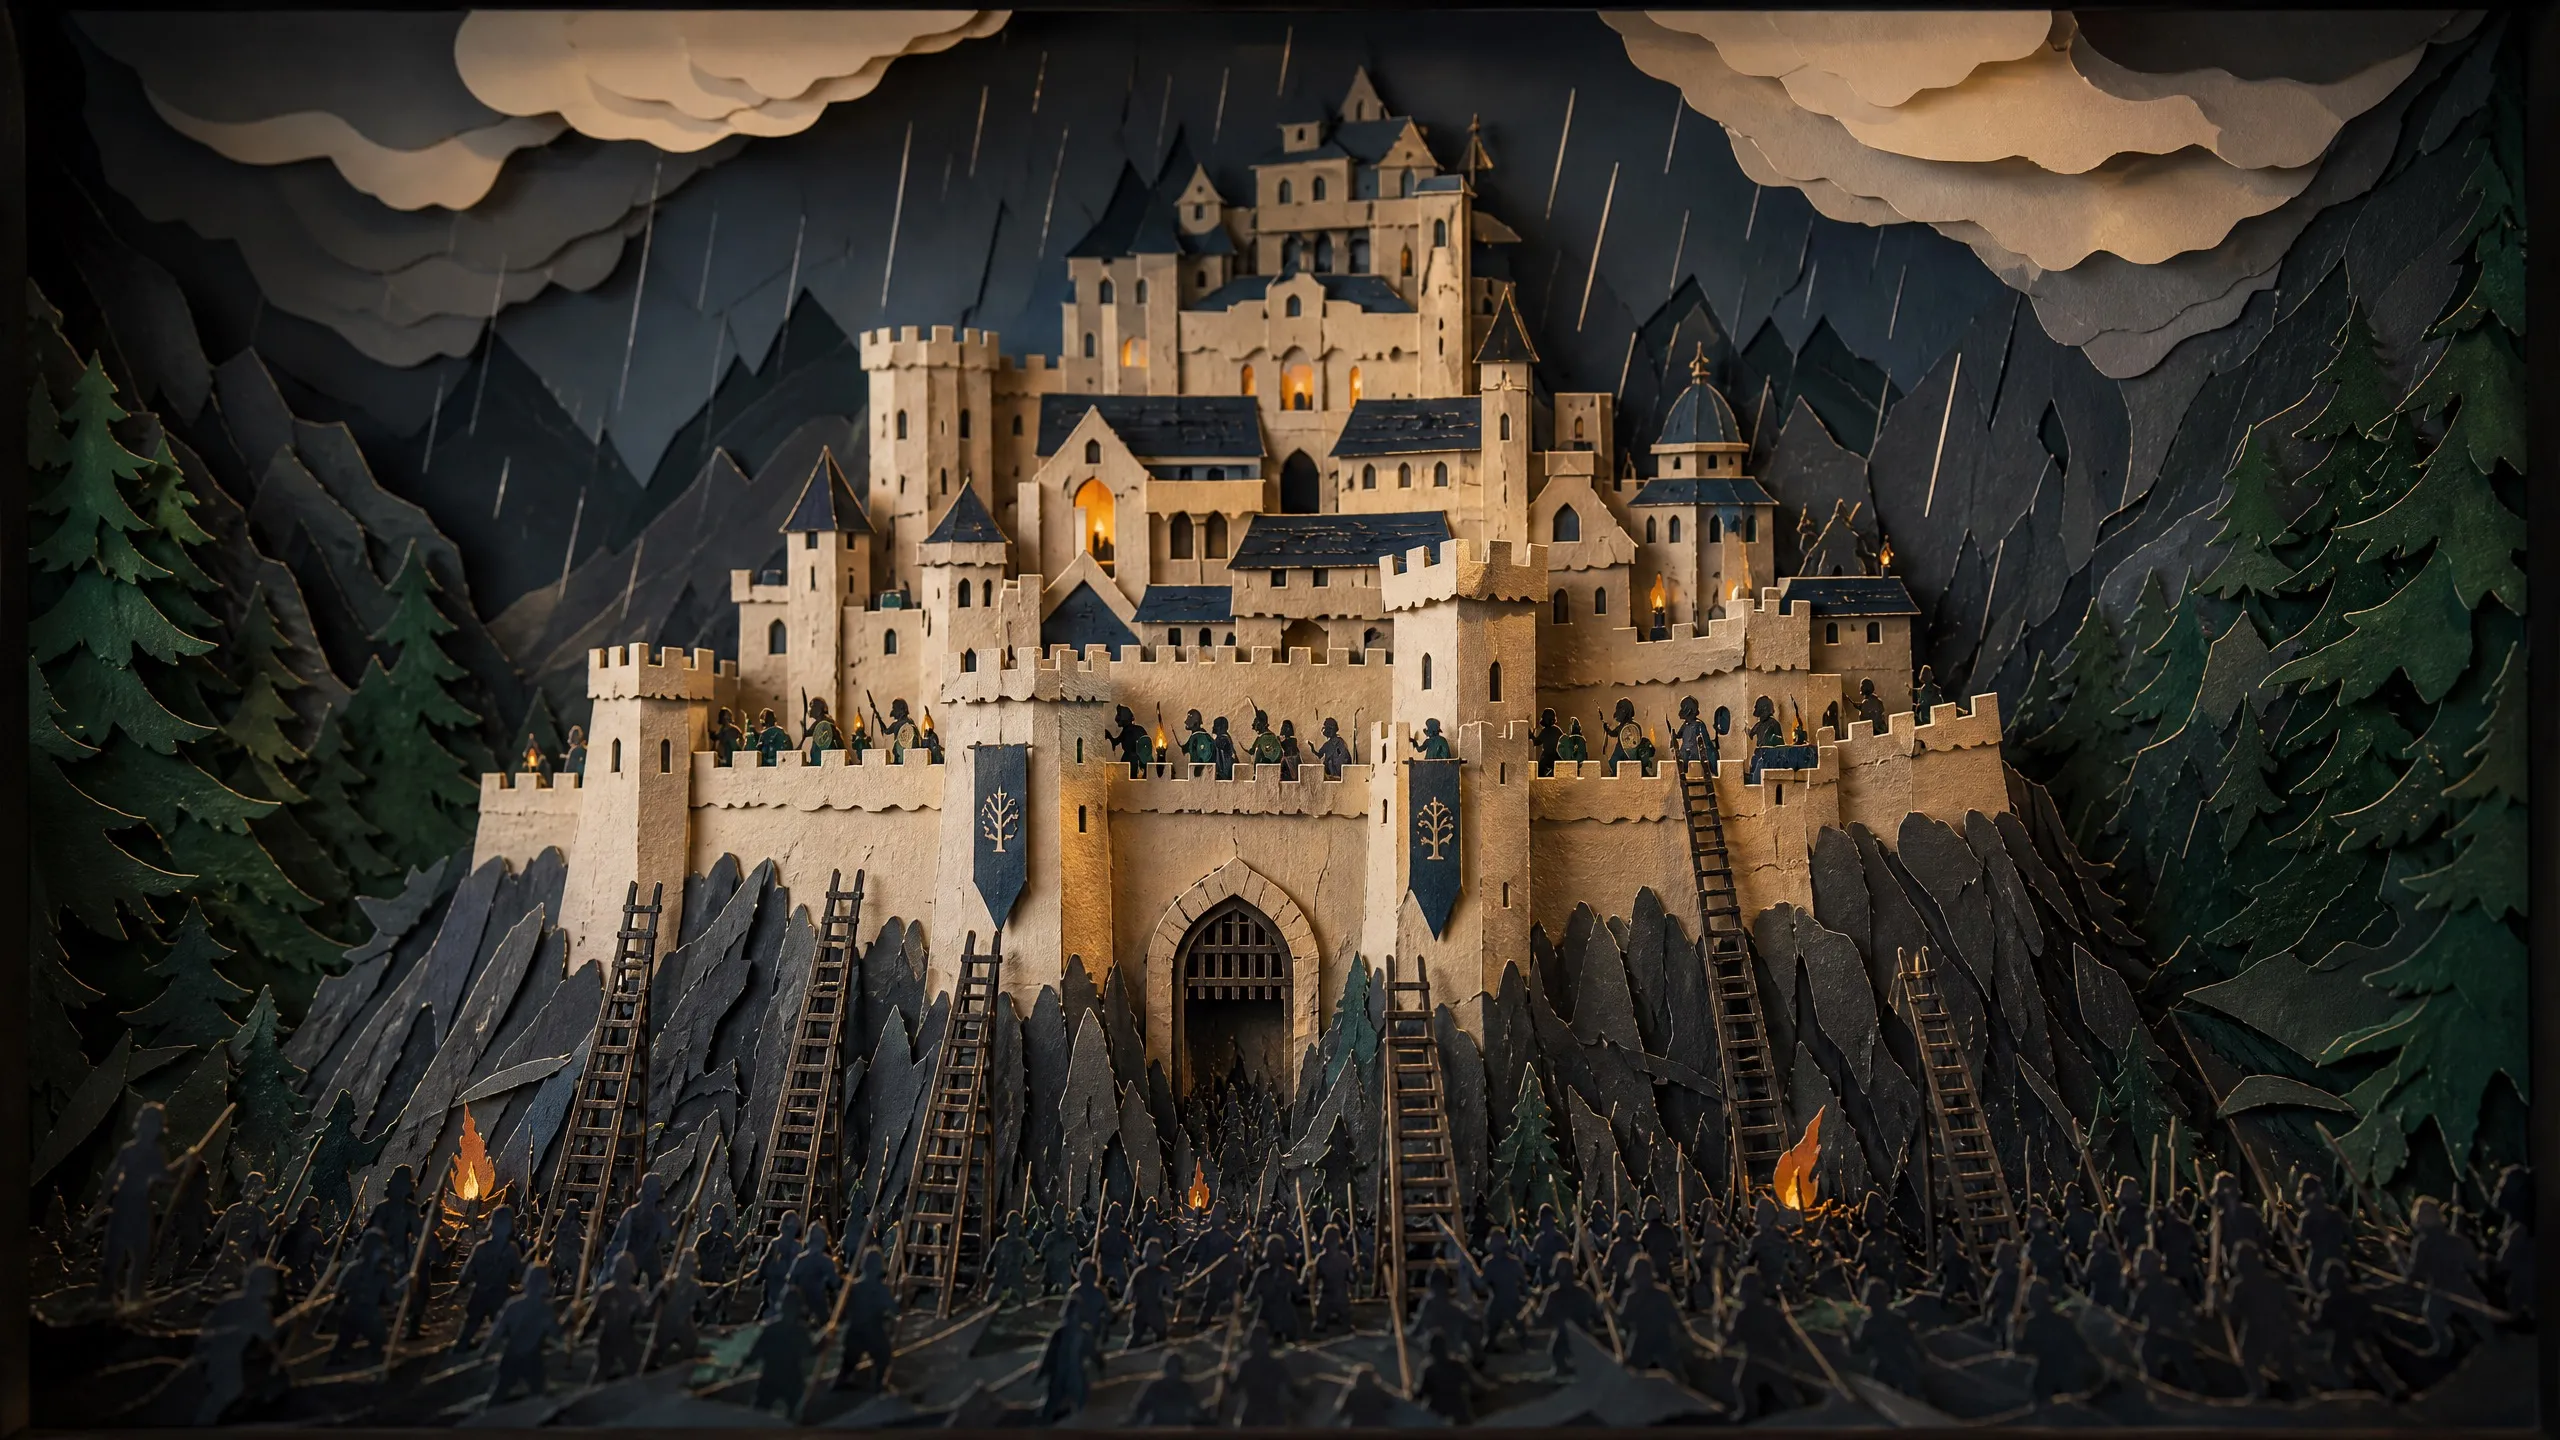
Helm's Deep
Run date: 2026-09-23
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
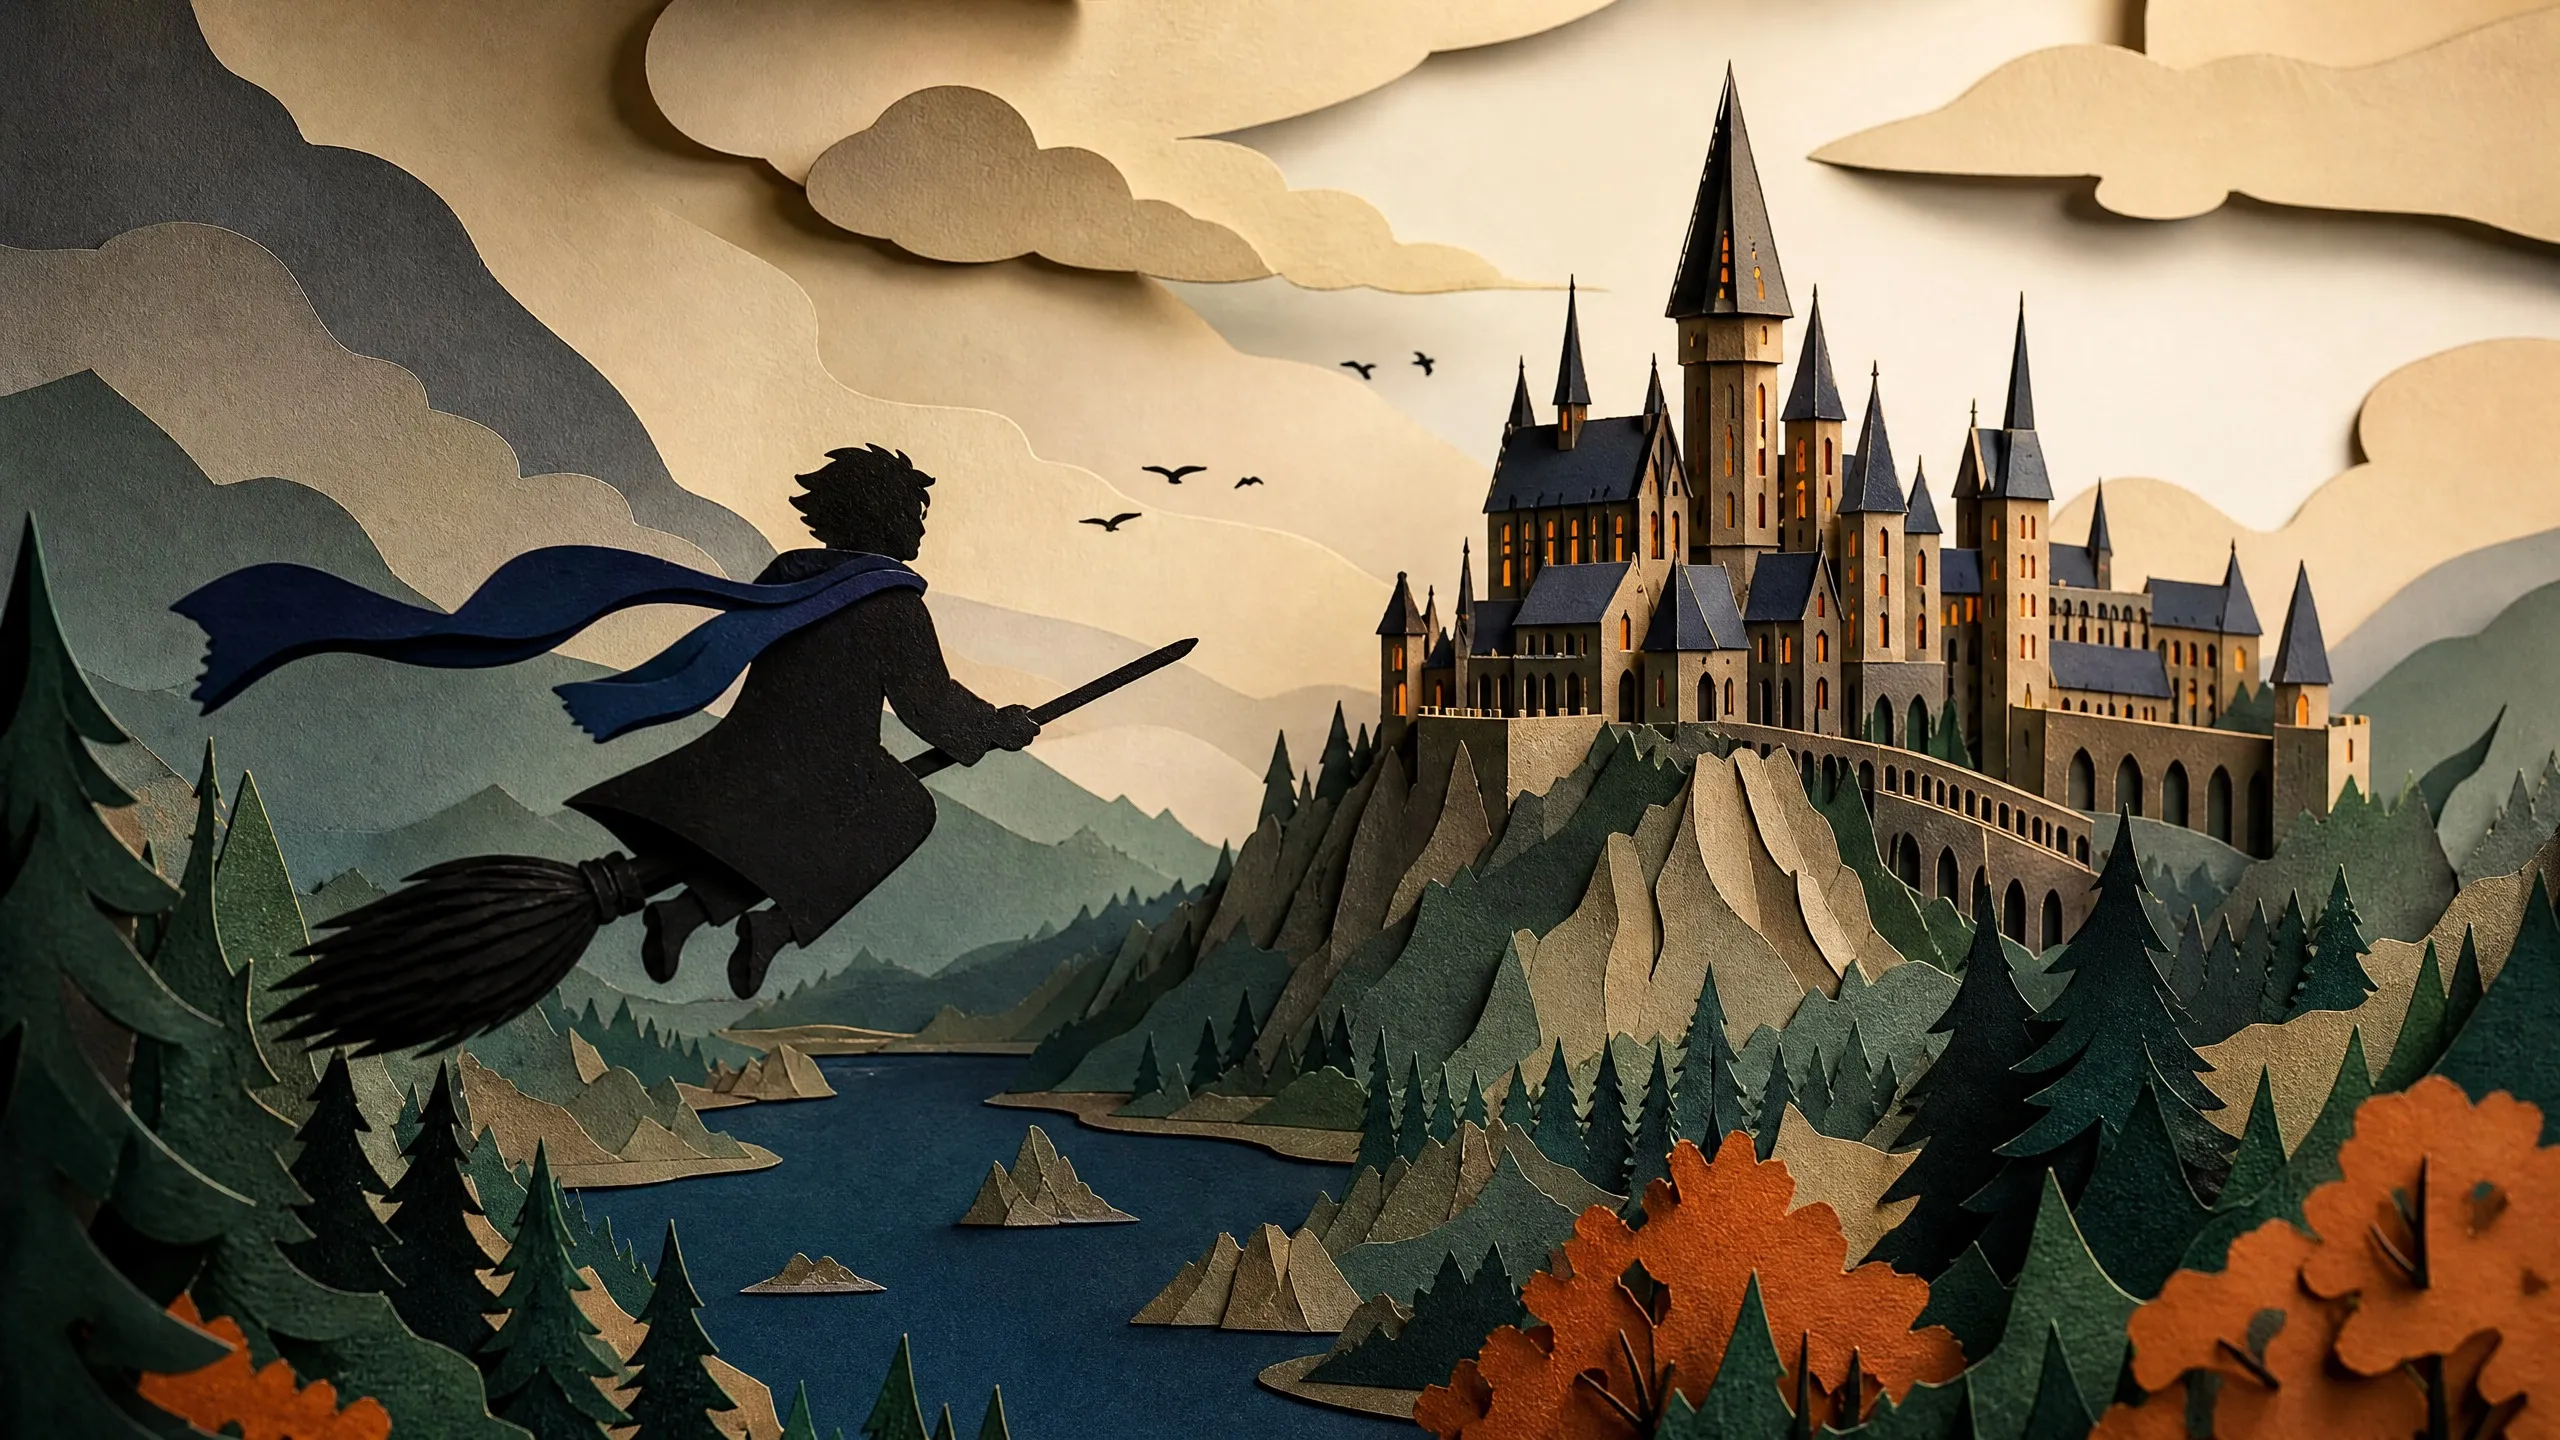
Hogwarts Broom Flight Simulator
Run date: 2026-09-23
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
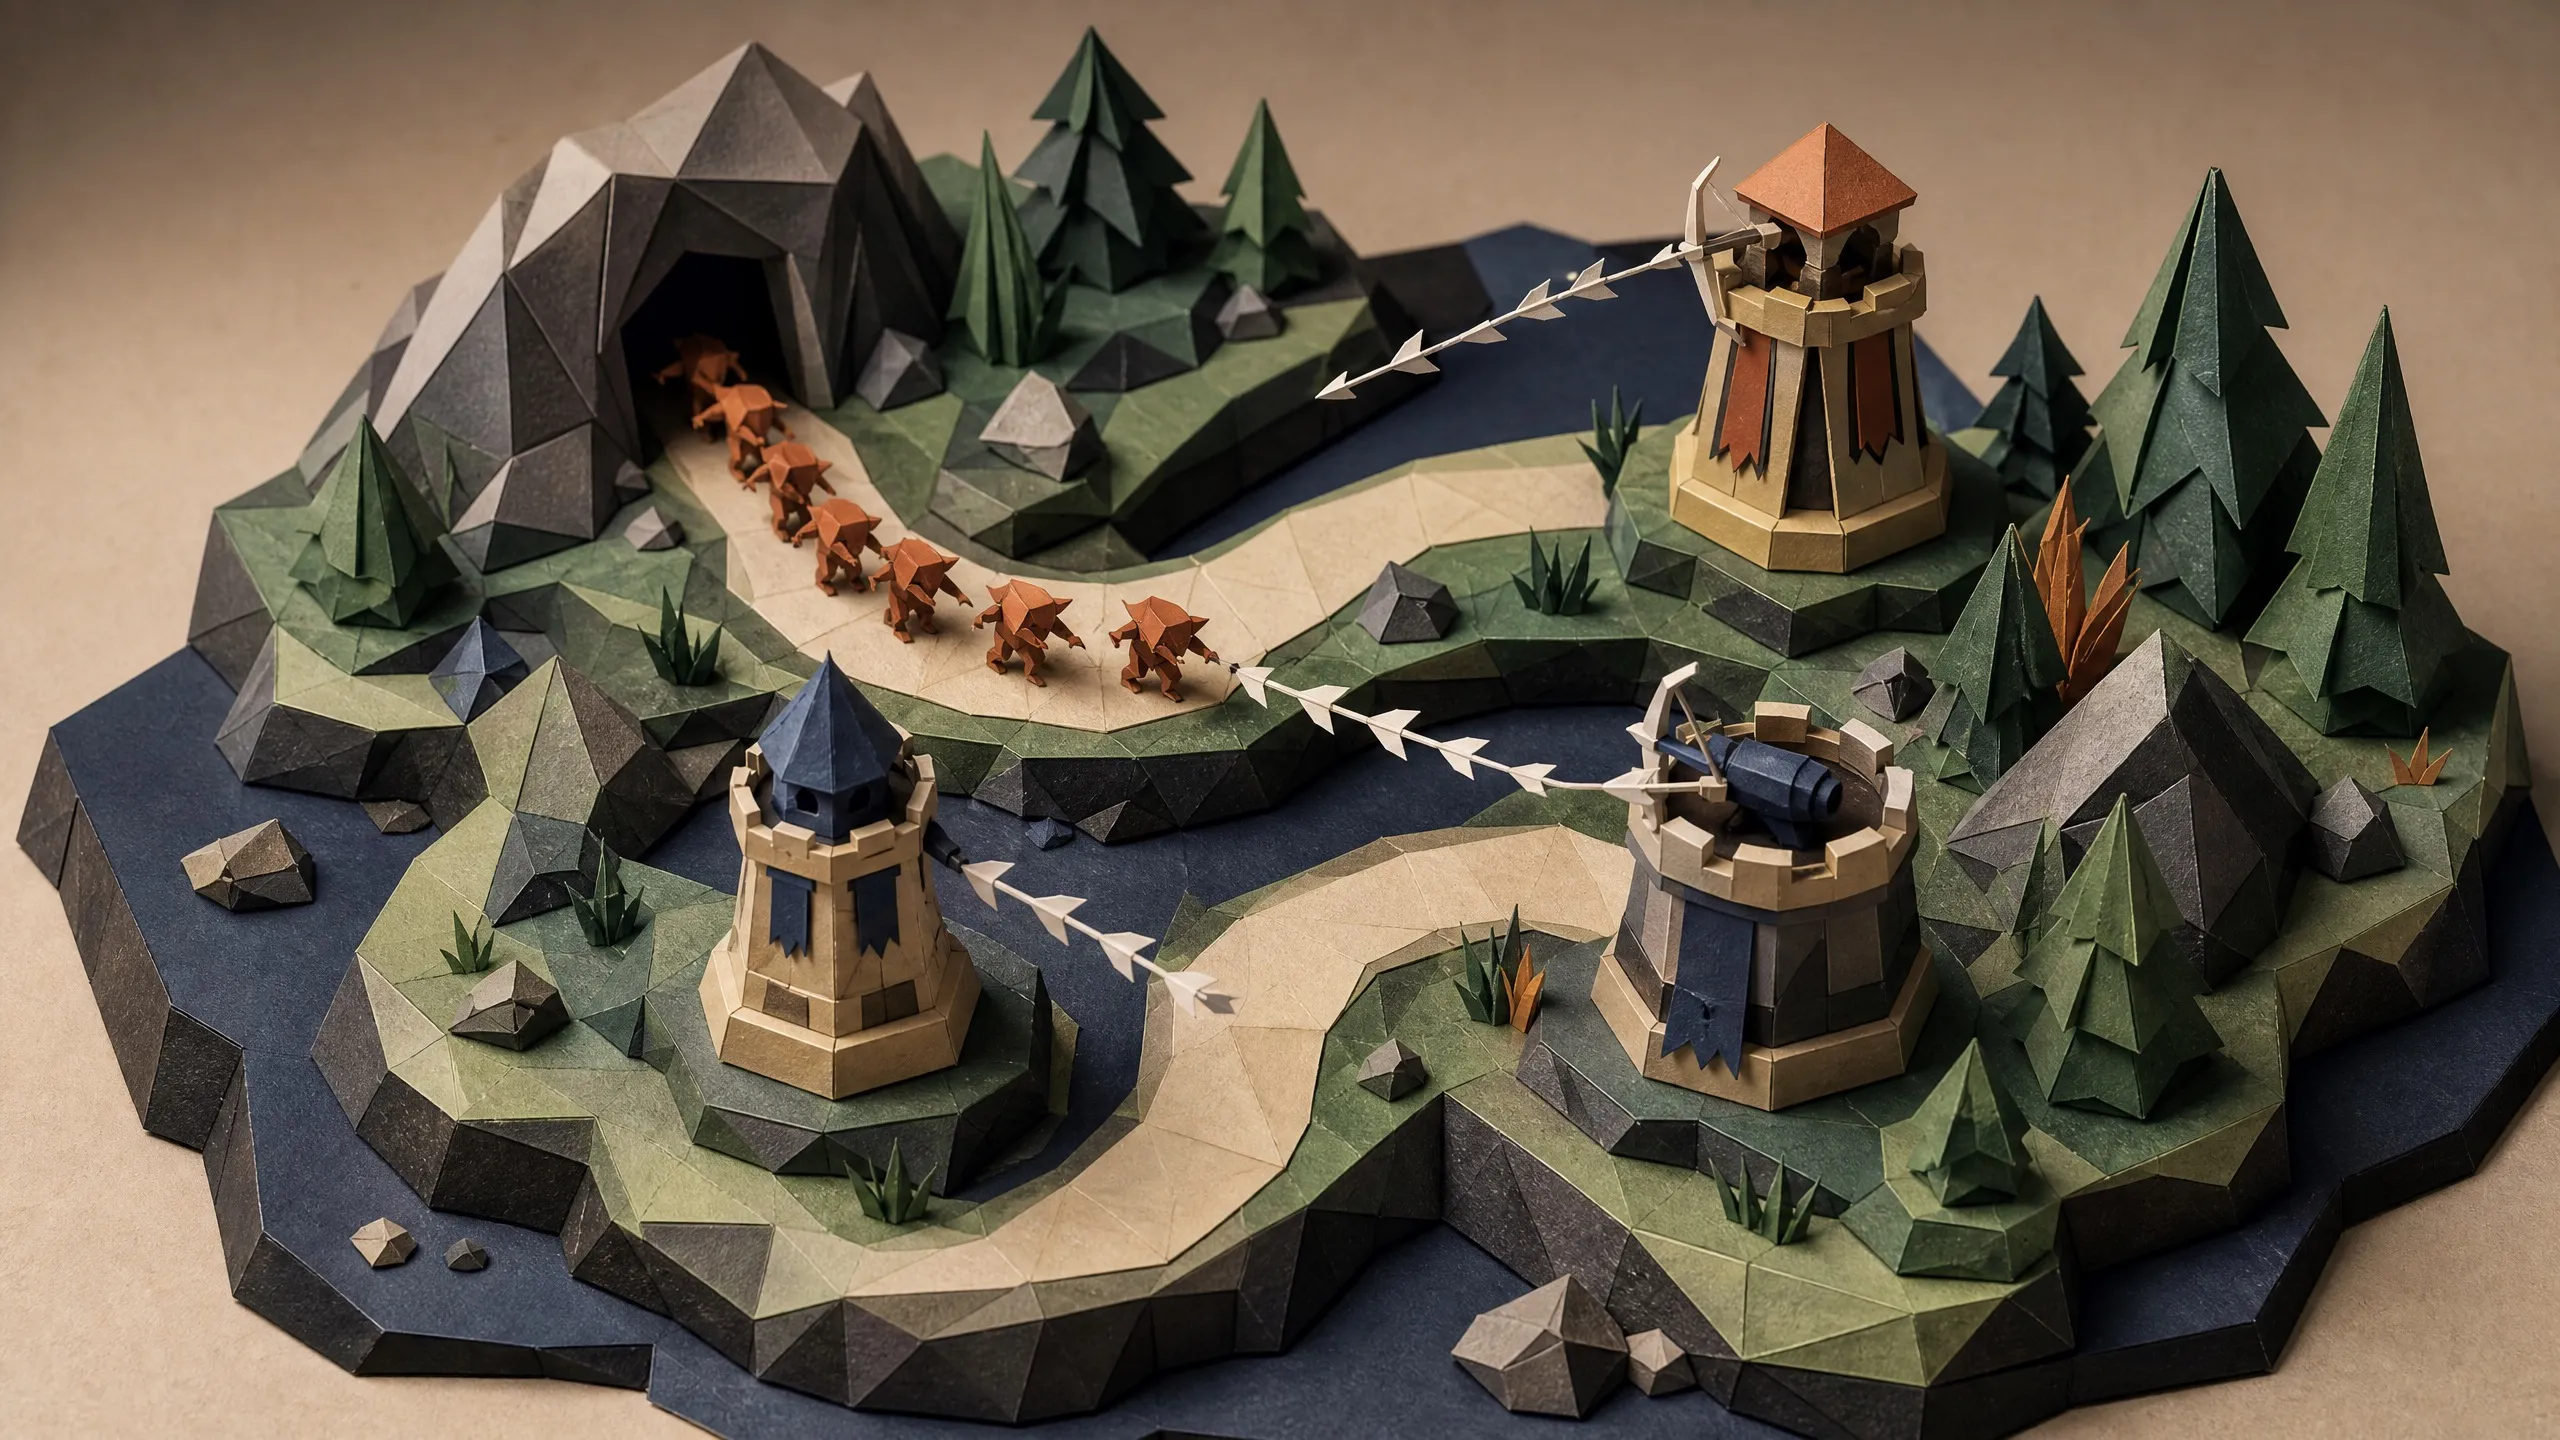
Low-Poly Tower Defense
Run date: 2026-09-23
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
Mechanical Watch Simulator
Run date: 2026-09-23
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.
Neon Drift
Run date: 2026-09-23
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-09-23
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
Stormwind Trebuchet Simulator
Run date: 2026-09-23
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
Yingzao Fashi Assembly
Run date: 2026-09-23
Specialist test · evaluated separately
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Local benchmark run
Prompt-only runs on the active visual suite
Sources, pricing details and methodology
Run identity
Model specifications
- Status
- Available in this Codex session
- Codex model ID
gpt-6-luna- Run date
- September 23, 2026
- Access route
- Selected in Codex for the September 23, 2026 prompt-only visual runs. Public API availability, pricing, and context limits were not assessed.
Benchmark sources
All eight core and two specialist prompts were assigned to GPT-6 Luna. Eight used fresh subagents; two used separate prompt-only continuations after the platform agent-thread cap. No reference implementations, screenshots, or other model outputs were provided as creative material.
GPT-6 Luna prompt-only visual benchmark runThese are inspectable local artifacts, not provider benchmark scores or an aggregate rating. Two continuation assignments retained unrelated prior-task conversation context; the methodology record identifies them. Individual validation reports record browser checks and limitations.
Editorial verdict
Where this model fits
GPT-6 Luna has ten published Superbash visual runs. Eight used fresh agents; two continued unrelated prior tasks because fresh subagent slots were unavailable. Each assignment received only its canonical prompt as creative input, and the methodology records the context difference. B tier is an editorial placement for bounded work with review, not a numeric score.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: GPT-6 Luna is currently placed in Tier B.
The September 2026 editorial roster places GPT-6 Luna at rank 11.
Open source →Superbash visual benchmark suite: GPT-6 Luna
Takeaway: Ten Luna runs are published, with eight fresh agents and two documented continuations.
The methodology records the prompt-only assignments, continuation context, and validation limits.
Open source →Related guides