
OpenAI
GPT-5.6 Luna
A delivery fallback the team rarely reaches for while Terra remains accessible.
API pricing
USD per million tokens · OpenAI API Standard (≤272K input tokens)- Input
- $0.2
- Output
- $1.2
- Cached input
- $0.02
- Context window
- 1.05M
Try the visual runs
Open the generated scene to test it, or compare that prompt with another model.
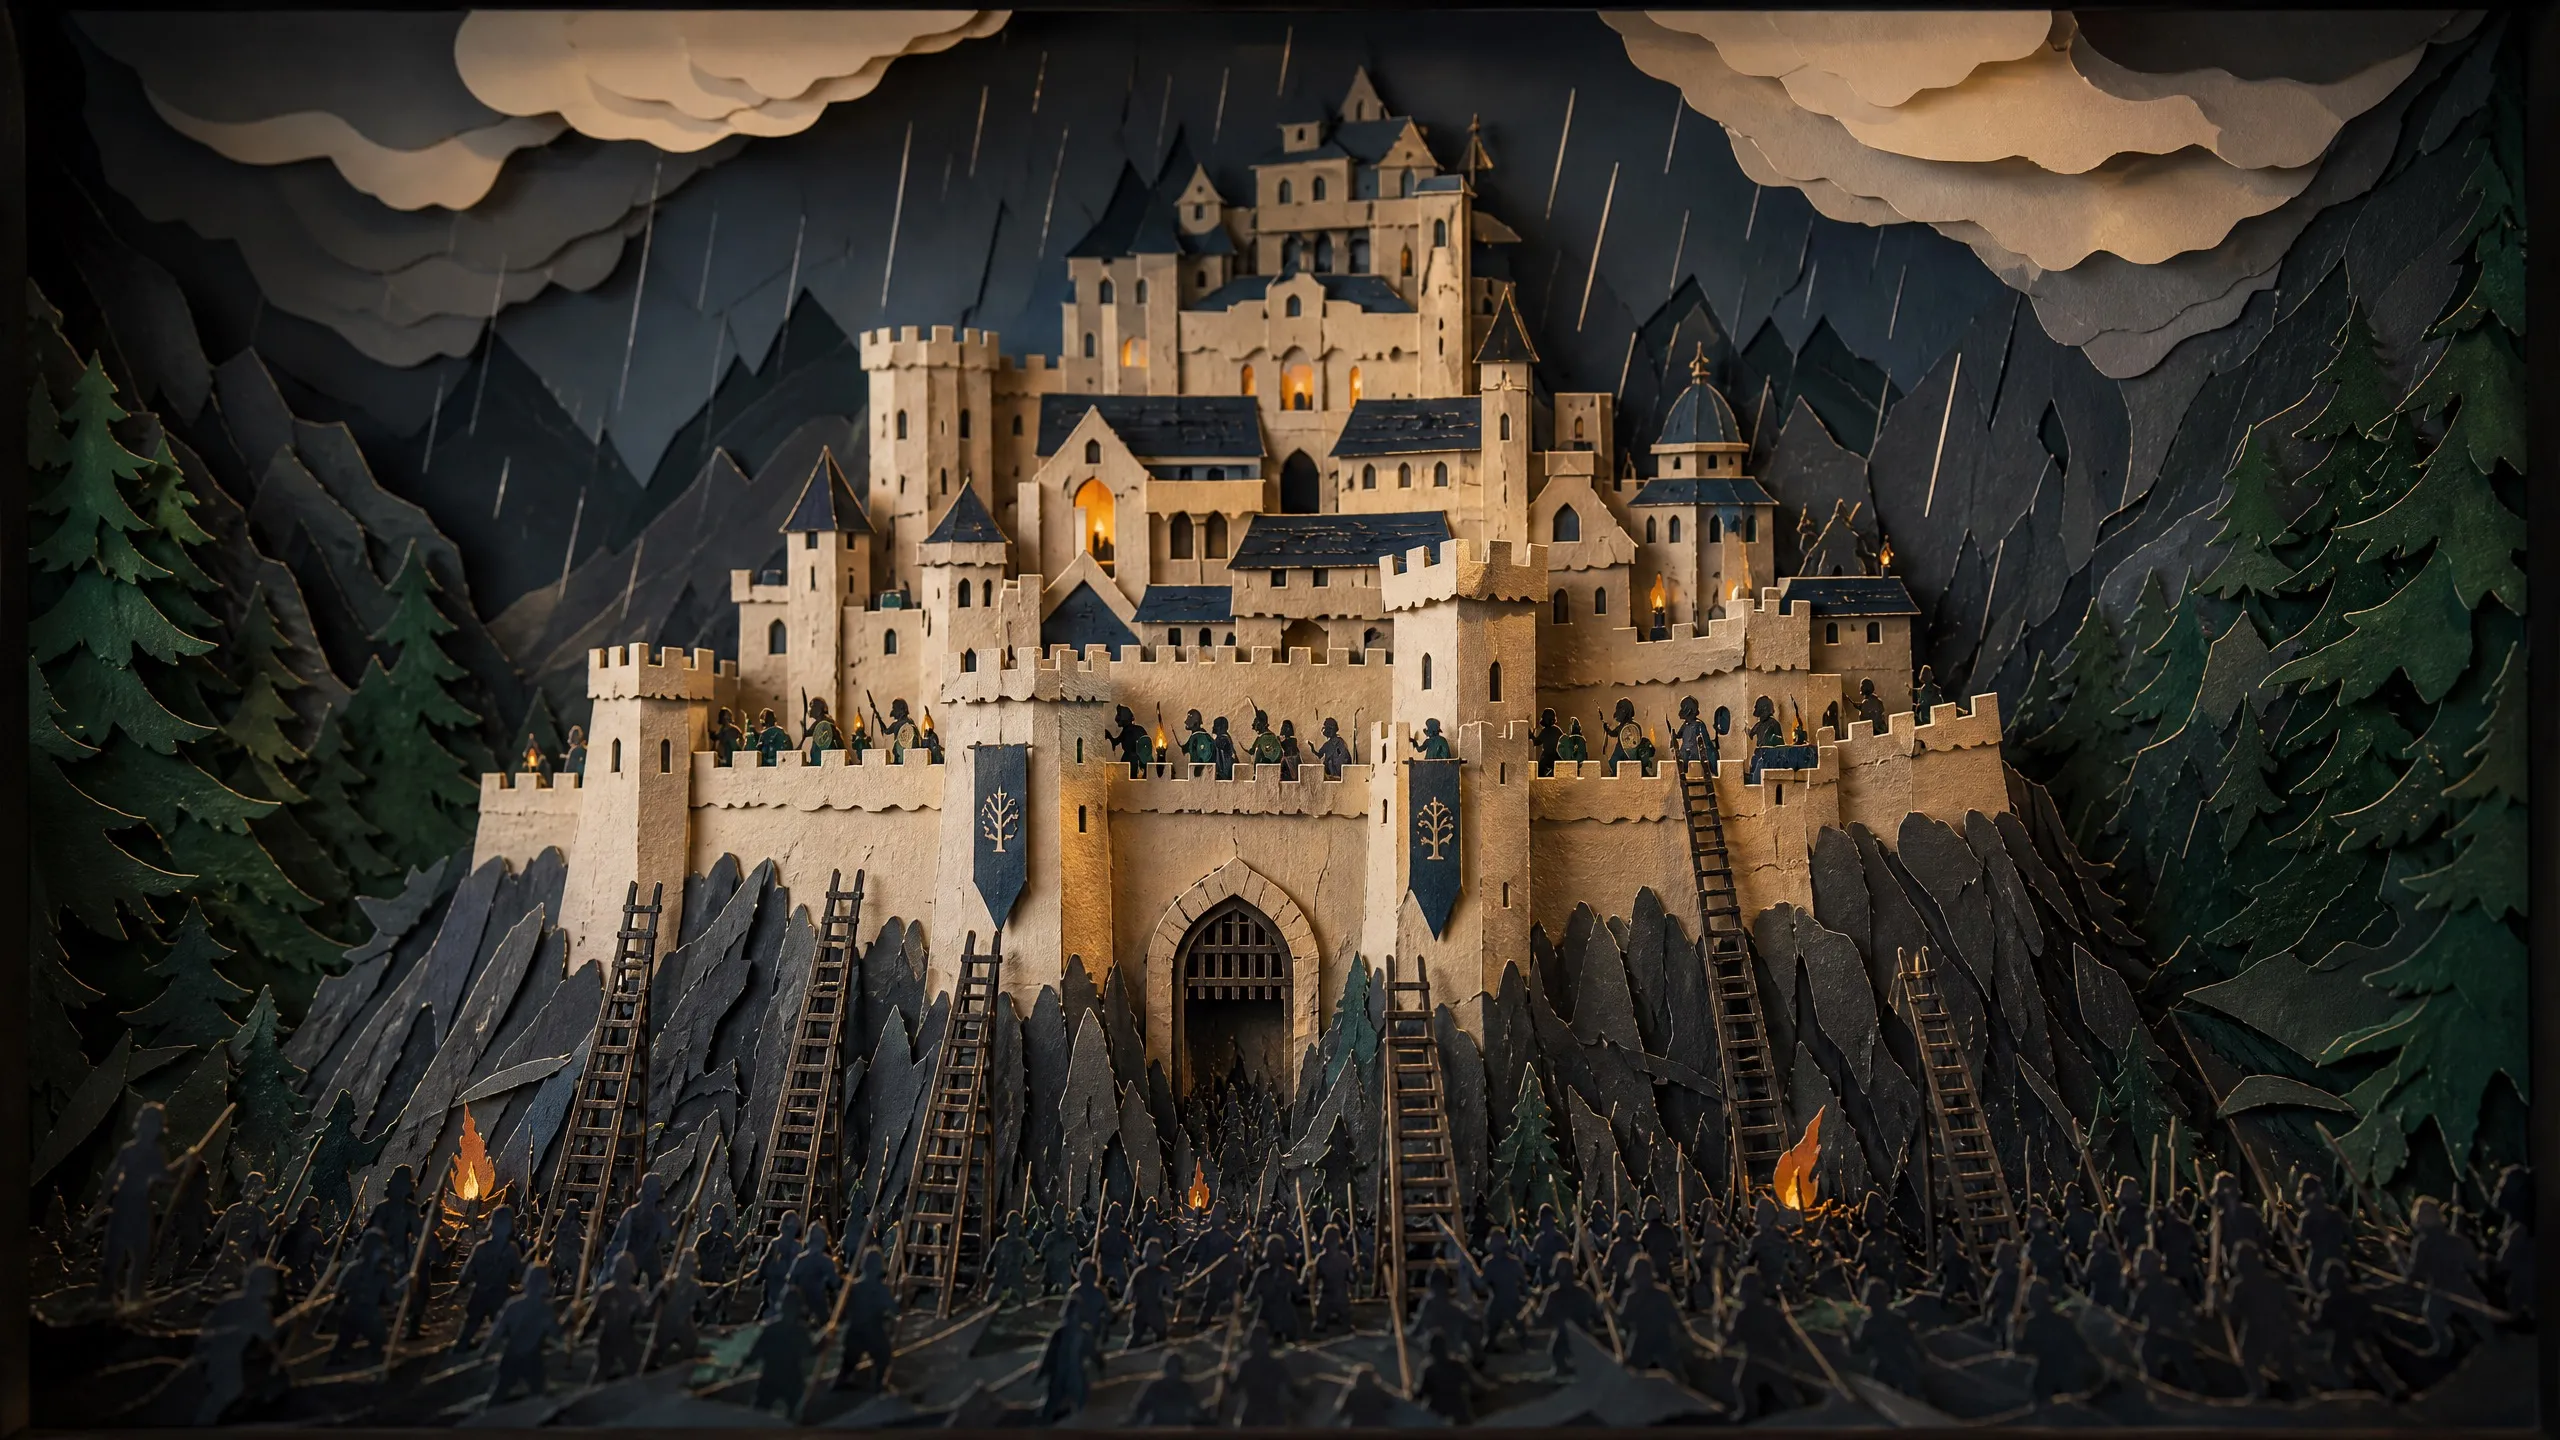
Helm's Deep
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
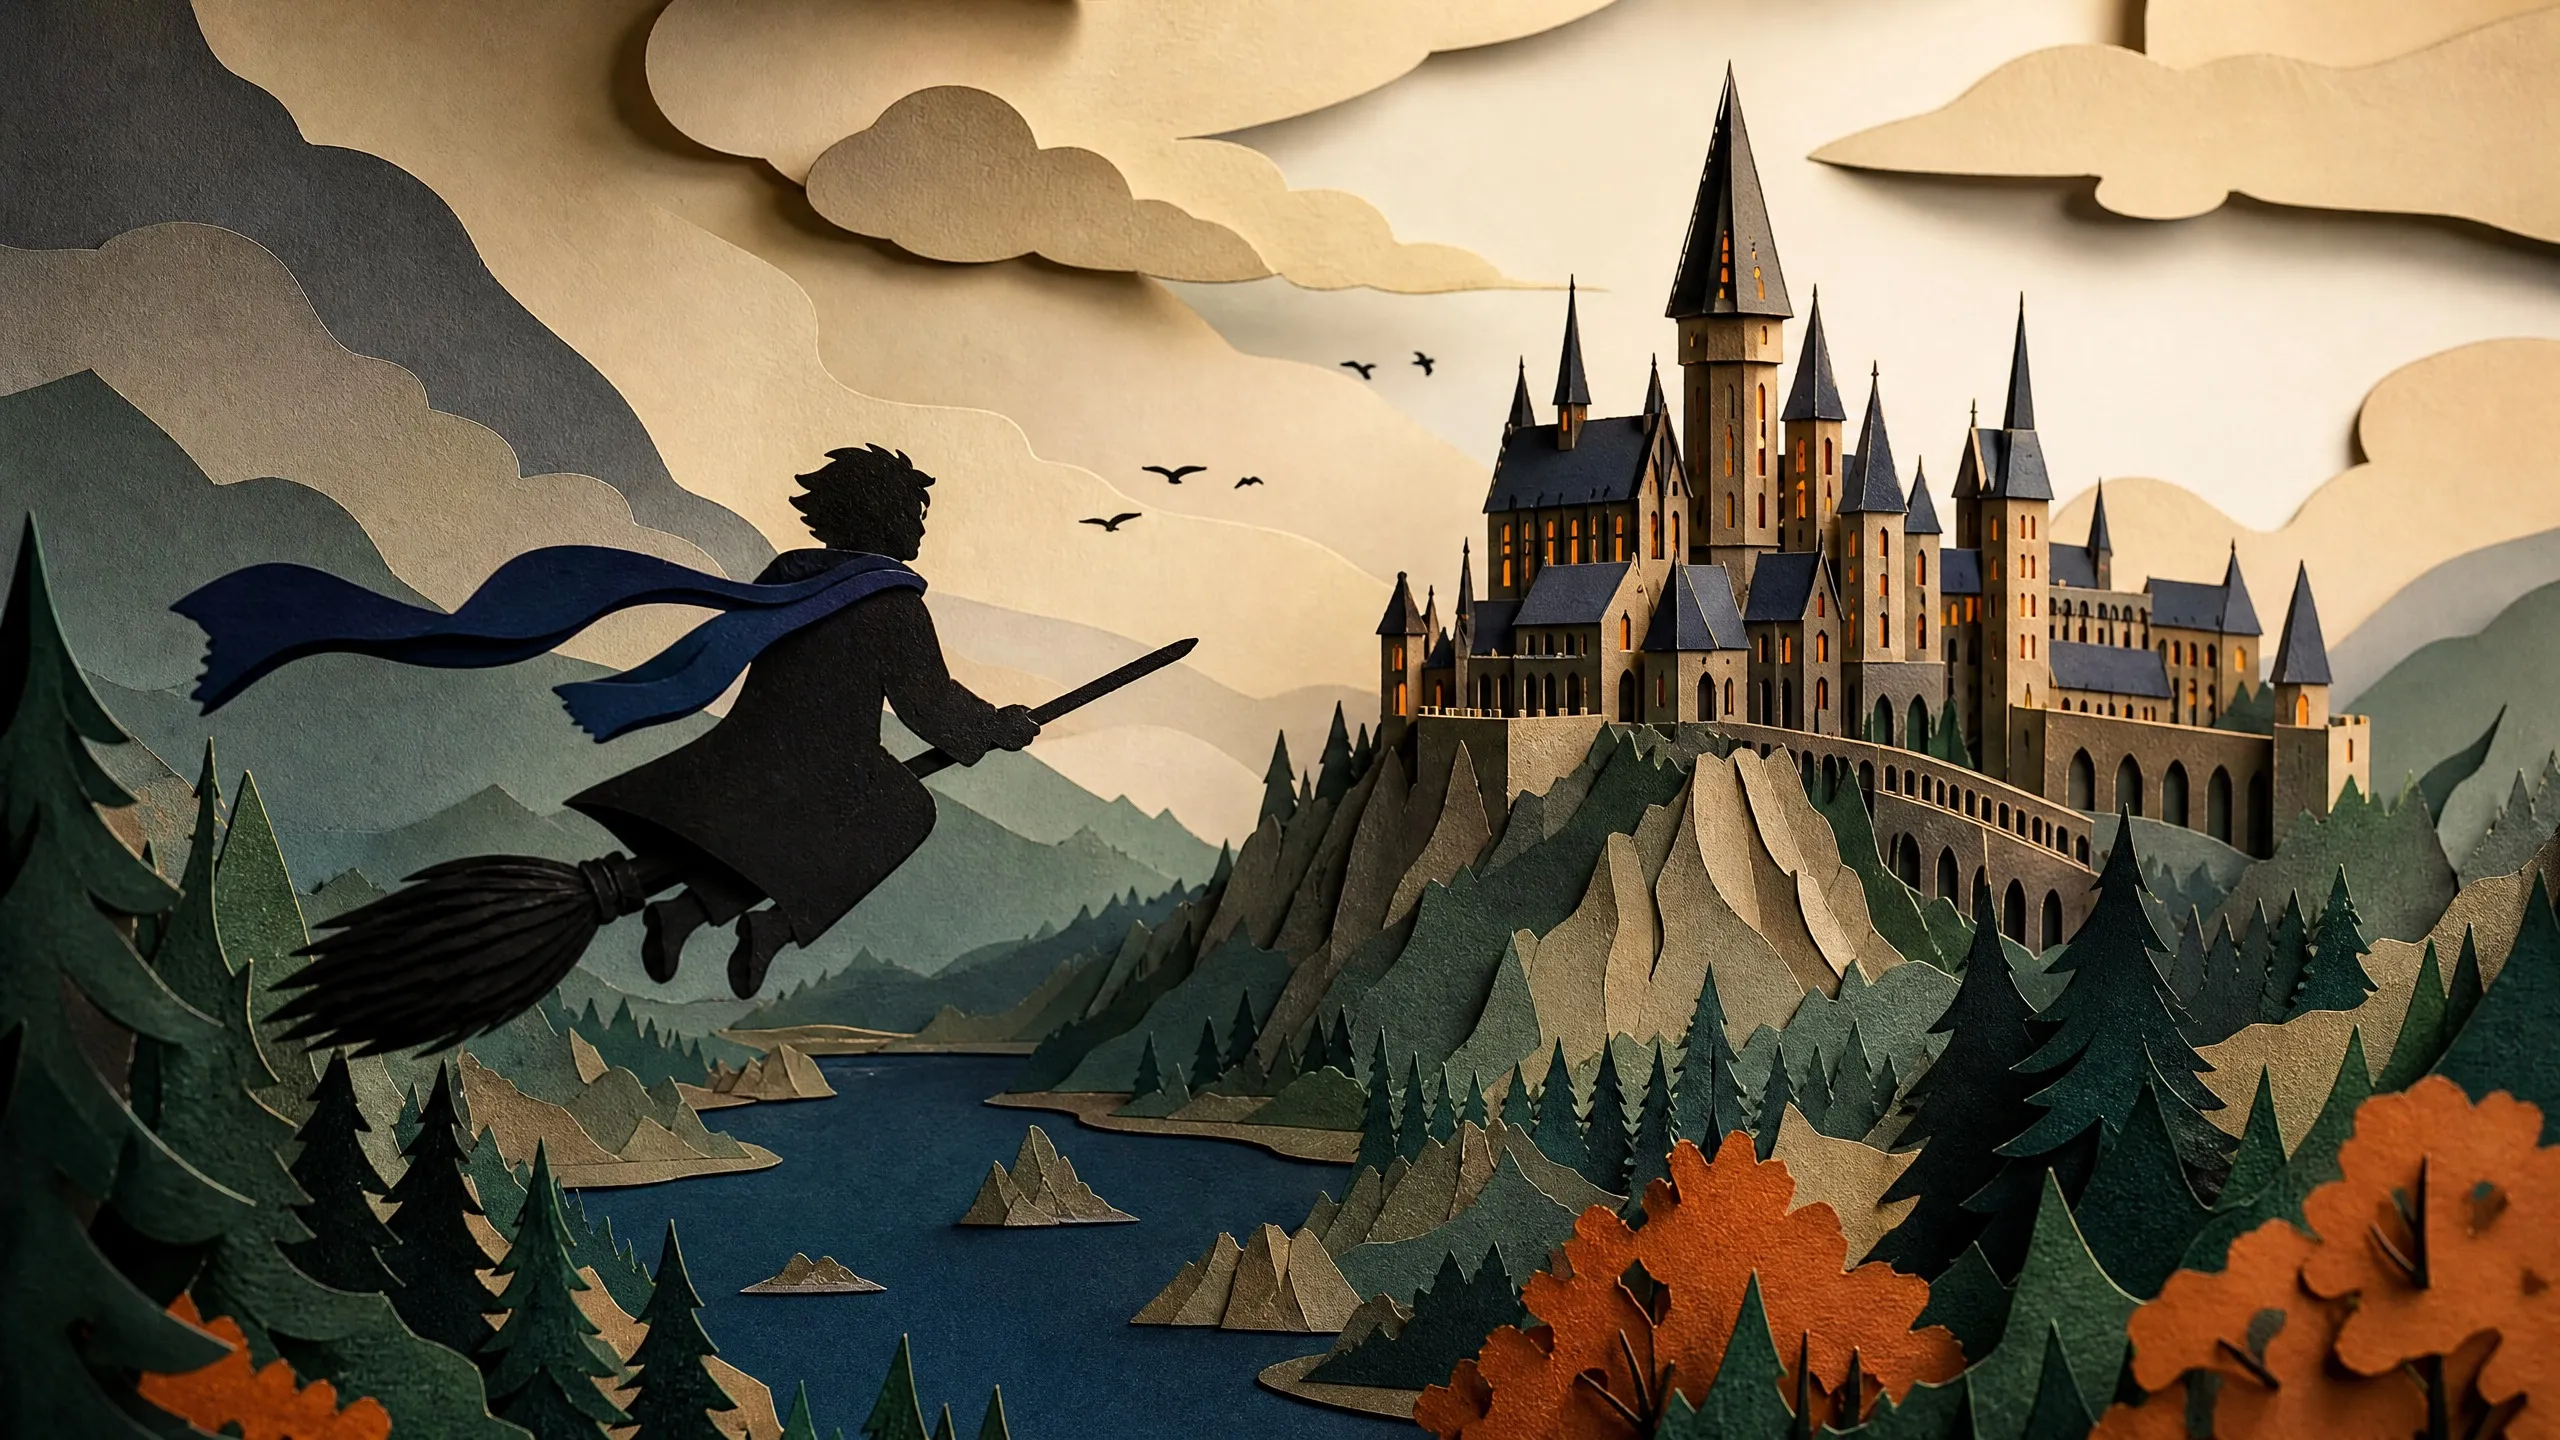
Hogwarts Broom Flight Simulator
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Jabberwock
Dark fantasy encounter testing creature design, forest mood, and narrative staging.

Low Poly World
Stylized island build testing composition, color, and low-poly worldbuilding.

Office Life
Workplace vignette testing everyday scene logic, objects, and believable office detail.

Petri Dish
Microscopic ecosystem testing organic forms, scientific clarity, and cellular detail.

Universe Simulator
Cosmic system testing orbital structure, glowing bodies, scale, and simulation readability.

Vice City
Neon coastal city testing vehicles, architecture, atmosphere, and dense urban layout.
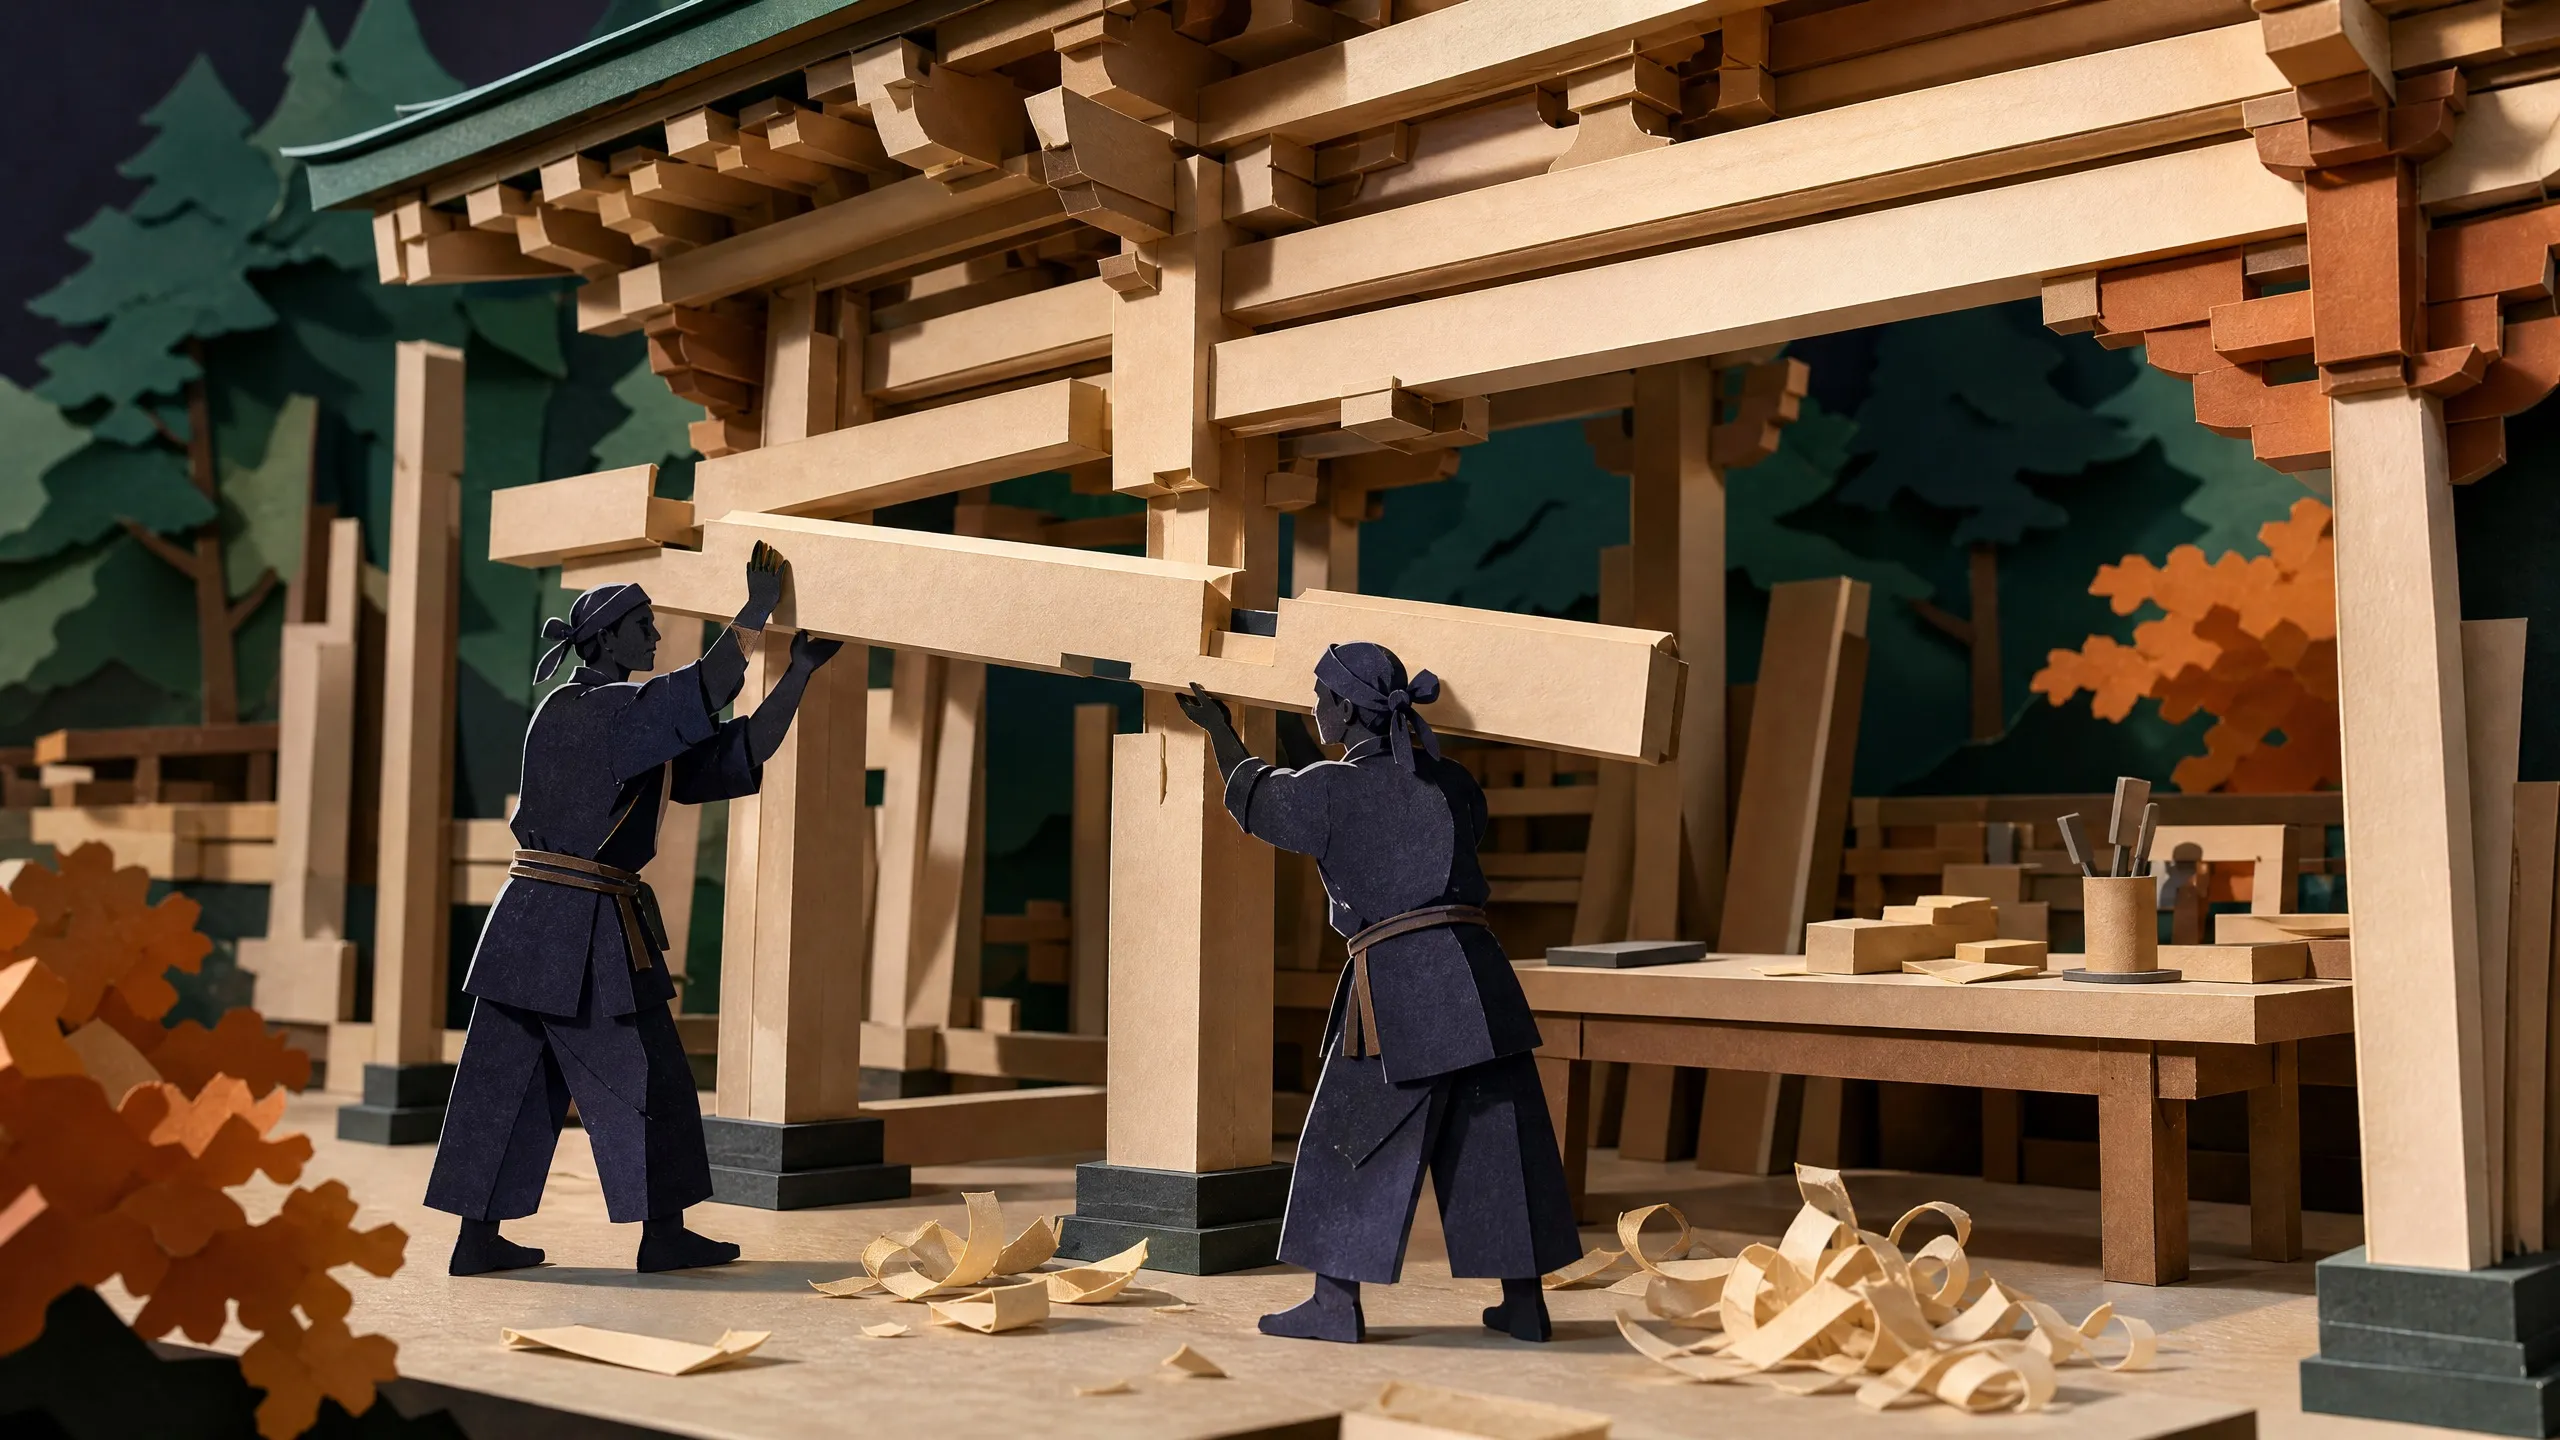
Yingzao Fashi Assembly
Timber assembly scene testing structure, joinery, construction order, and material clarity.
How GPT-5.6 Luna compares
Three relevant peers, side by side.
- GPT-5.6 Luna This model
- Claude Opus 4.8
- GPT-5.5
- GPT-5.6 Sol
6 benchmarks · 4 models
Official benchmark profile
Published scores outside our visual tests
SWE-bench Pro
62.7%Terminal-Bench 2.1
84.7%OSWorld 2.0
45.6%Full official benchmark table9 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| SWE-bench Pro | Coding | 62.7% | |
| Terminal-Bench 2.1 | Agentic coding | 84.7% | |
| OSWorld 2.0 | Computer use | 45.6% | |
| BrowseComp | Tool use | 83.3% | |
| BenchCAD | Computer-aided design | 63.1% | |
| BenchCAD with Python tool | Tool use | 73.9% | |
| GPQA Diamond | Academic reasoning | 92.3% | |
| FrontierMath Tier 1-3 v2 | Math | 78.6% | |
| FrontierMath Tier 4 v2 | Math | 58.5% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
gpt-5.6-luna- Context
- 1.05M
- Max output
- 128K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- OpenAI API Standard (≤272K input tokens) · USD / 1M tokens
- $0.2 input · $0.02 cached input · $0.25 cache write · $1.2 output
Above 272K input tokens, the full request costs $0.4 input, $0.04 cached input, $0.5 cache write, and $1.8 output per 1M tokens. Batch, Flex, Fast mode, and regional pricing differ.
Benchmark sources
OpenAI describes Luna as the fastest and most cost-efficient GPT-5.6 variant. These rows use the shared GPT-5.6 comparison table so scores line up against Sol, Terra, GPT-5.5, Claude, and Gemini where published.
GPT-5.6: Frontier intelligence that scales with your ambitionEvaluation settings
- Shared OpenAI GPT-5.6 comparison table.
- High-effort computer-use comparison table.
- High-effort browsing-agent comparison table.
- Vision2Code score without Python tool.
- Vision2Code score with Python tool.
- Shared reasoning benchmark table.
Editorial verdict
Where this model fits
GPT-5.6 Luna sits in C tier. The team sees it as a delivery model, but in practice uses Terra on low reasoning for the same boring work and has not found a strong reason to choose Luna first.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: GPT-5.6 Luna is currently placed in Tier C.
The September 2026 editorial roster places GPT-5.6 Luna at rank 14.
Open source →Related guides