
DeepSeek
DeepSeek V4.1 Flash
An A-tier open-weight agentic-coding option, based on strong provider-reported results, exceptional API efficiency, and a now-published Superbash visual suite.
API pricing
USD per million tokens · DeepSeek API peak rate- Input
- $0.3
- Output
- $1.2
- Cached input
- $0.006
- Context window
- 1M
Try the active visual tests
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-09-22
Specialist test · evaluated separately
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.
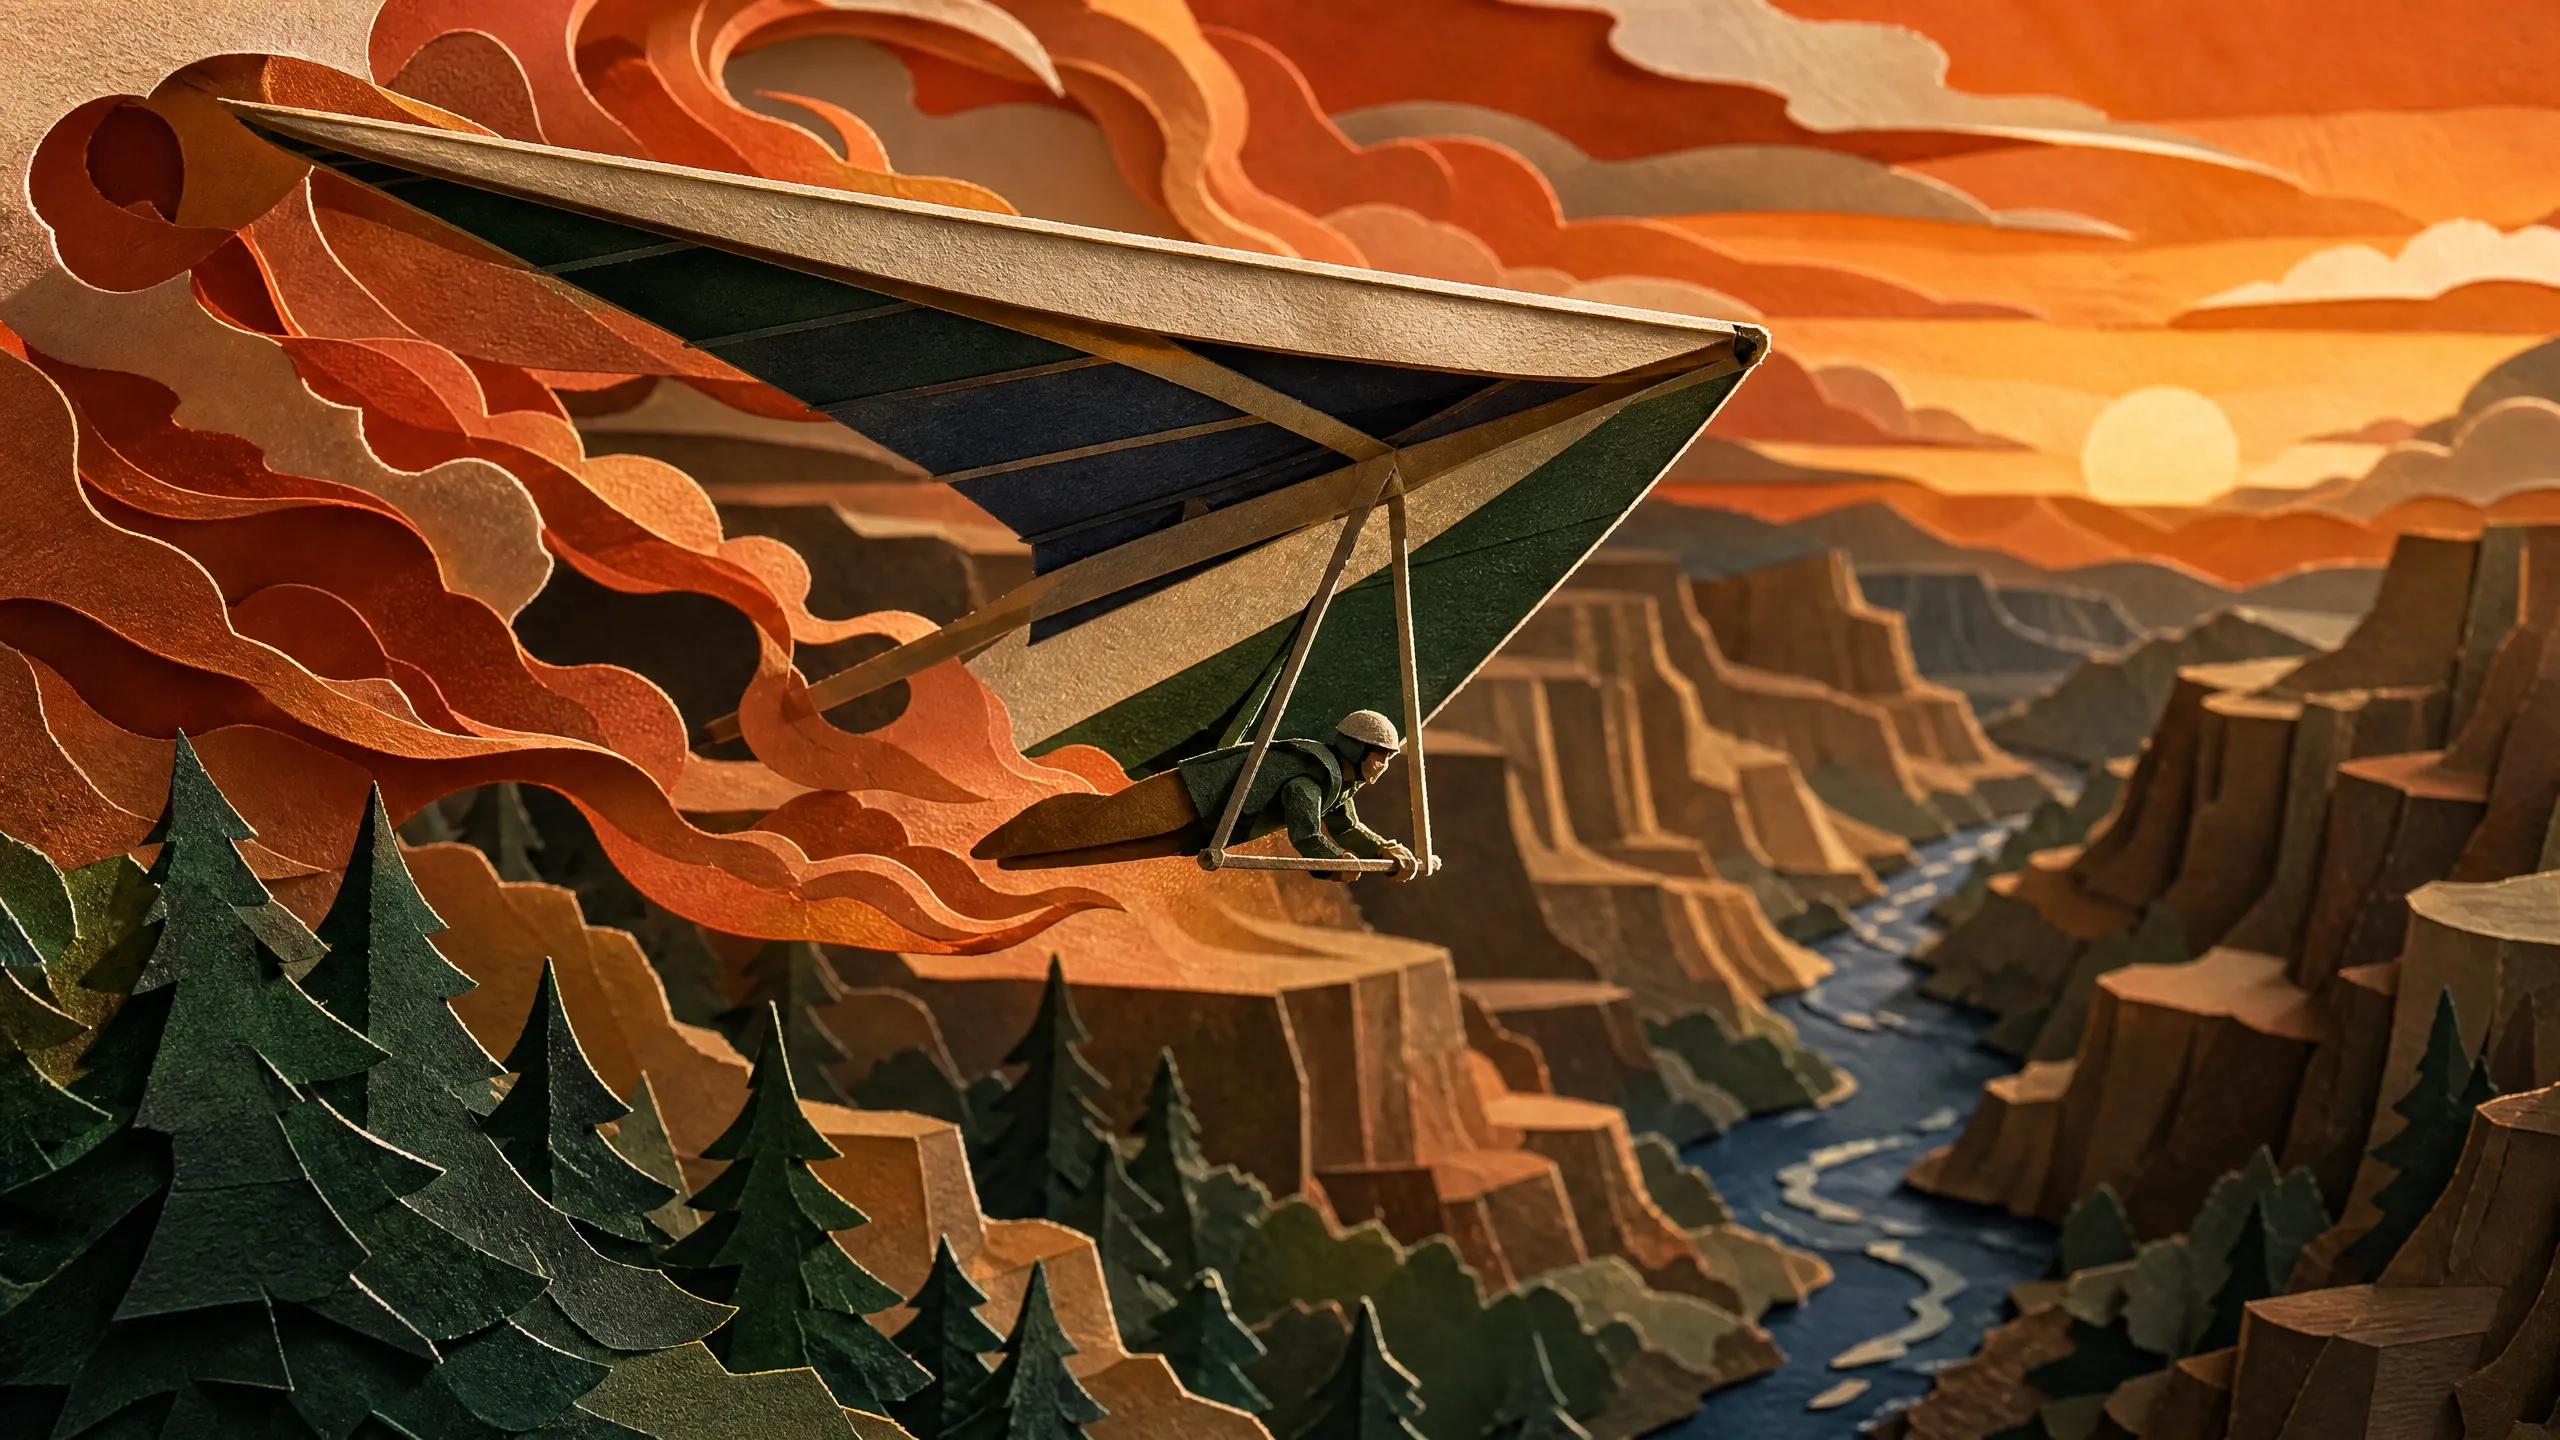
Ember Glider
Run date: 2026-09-22
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
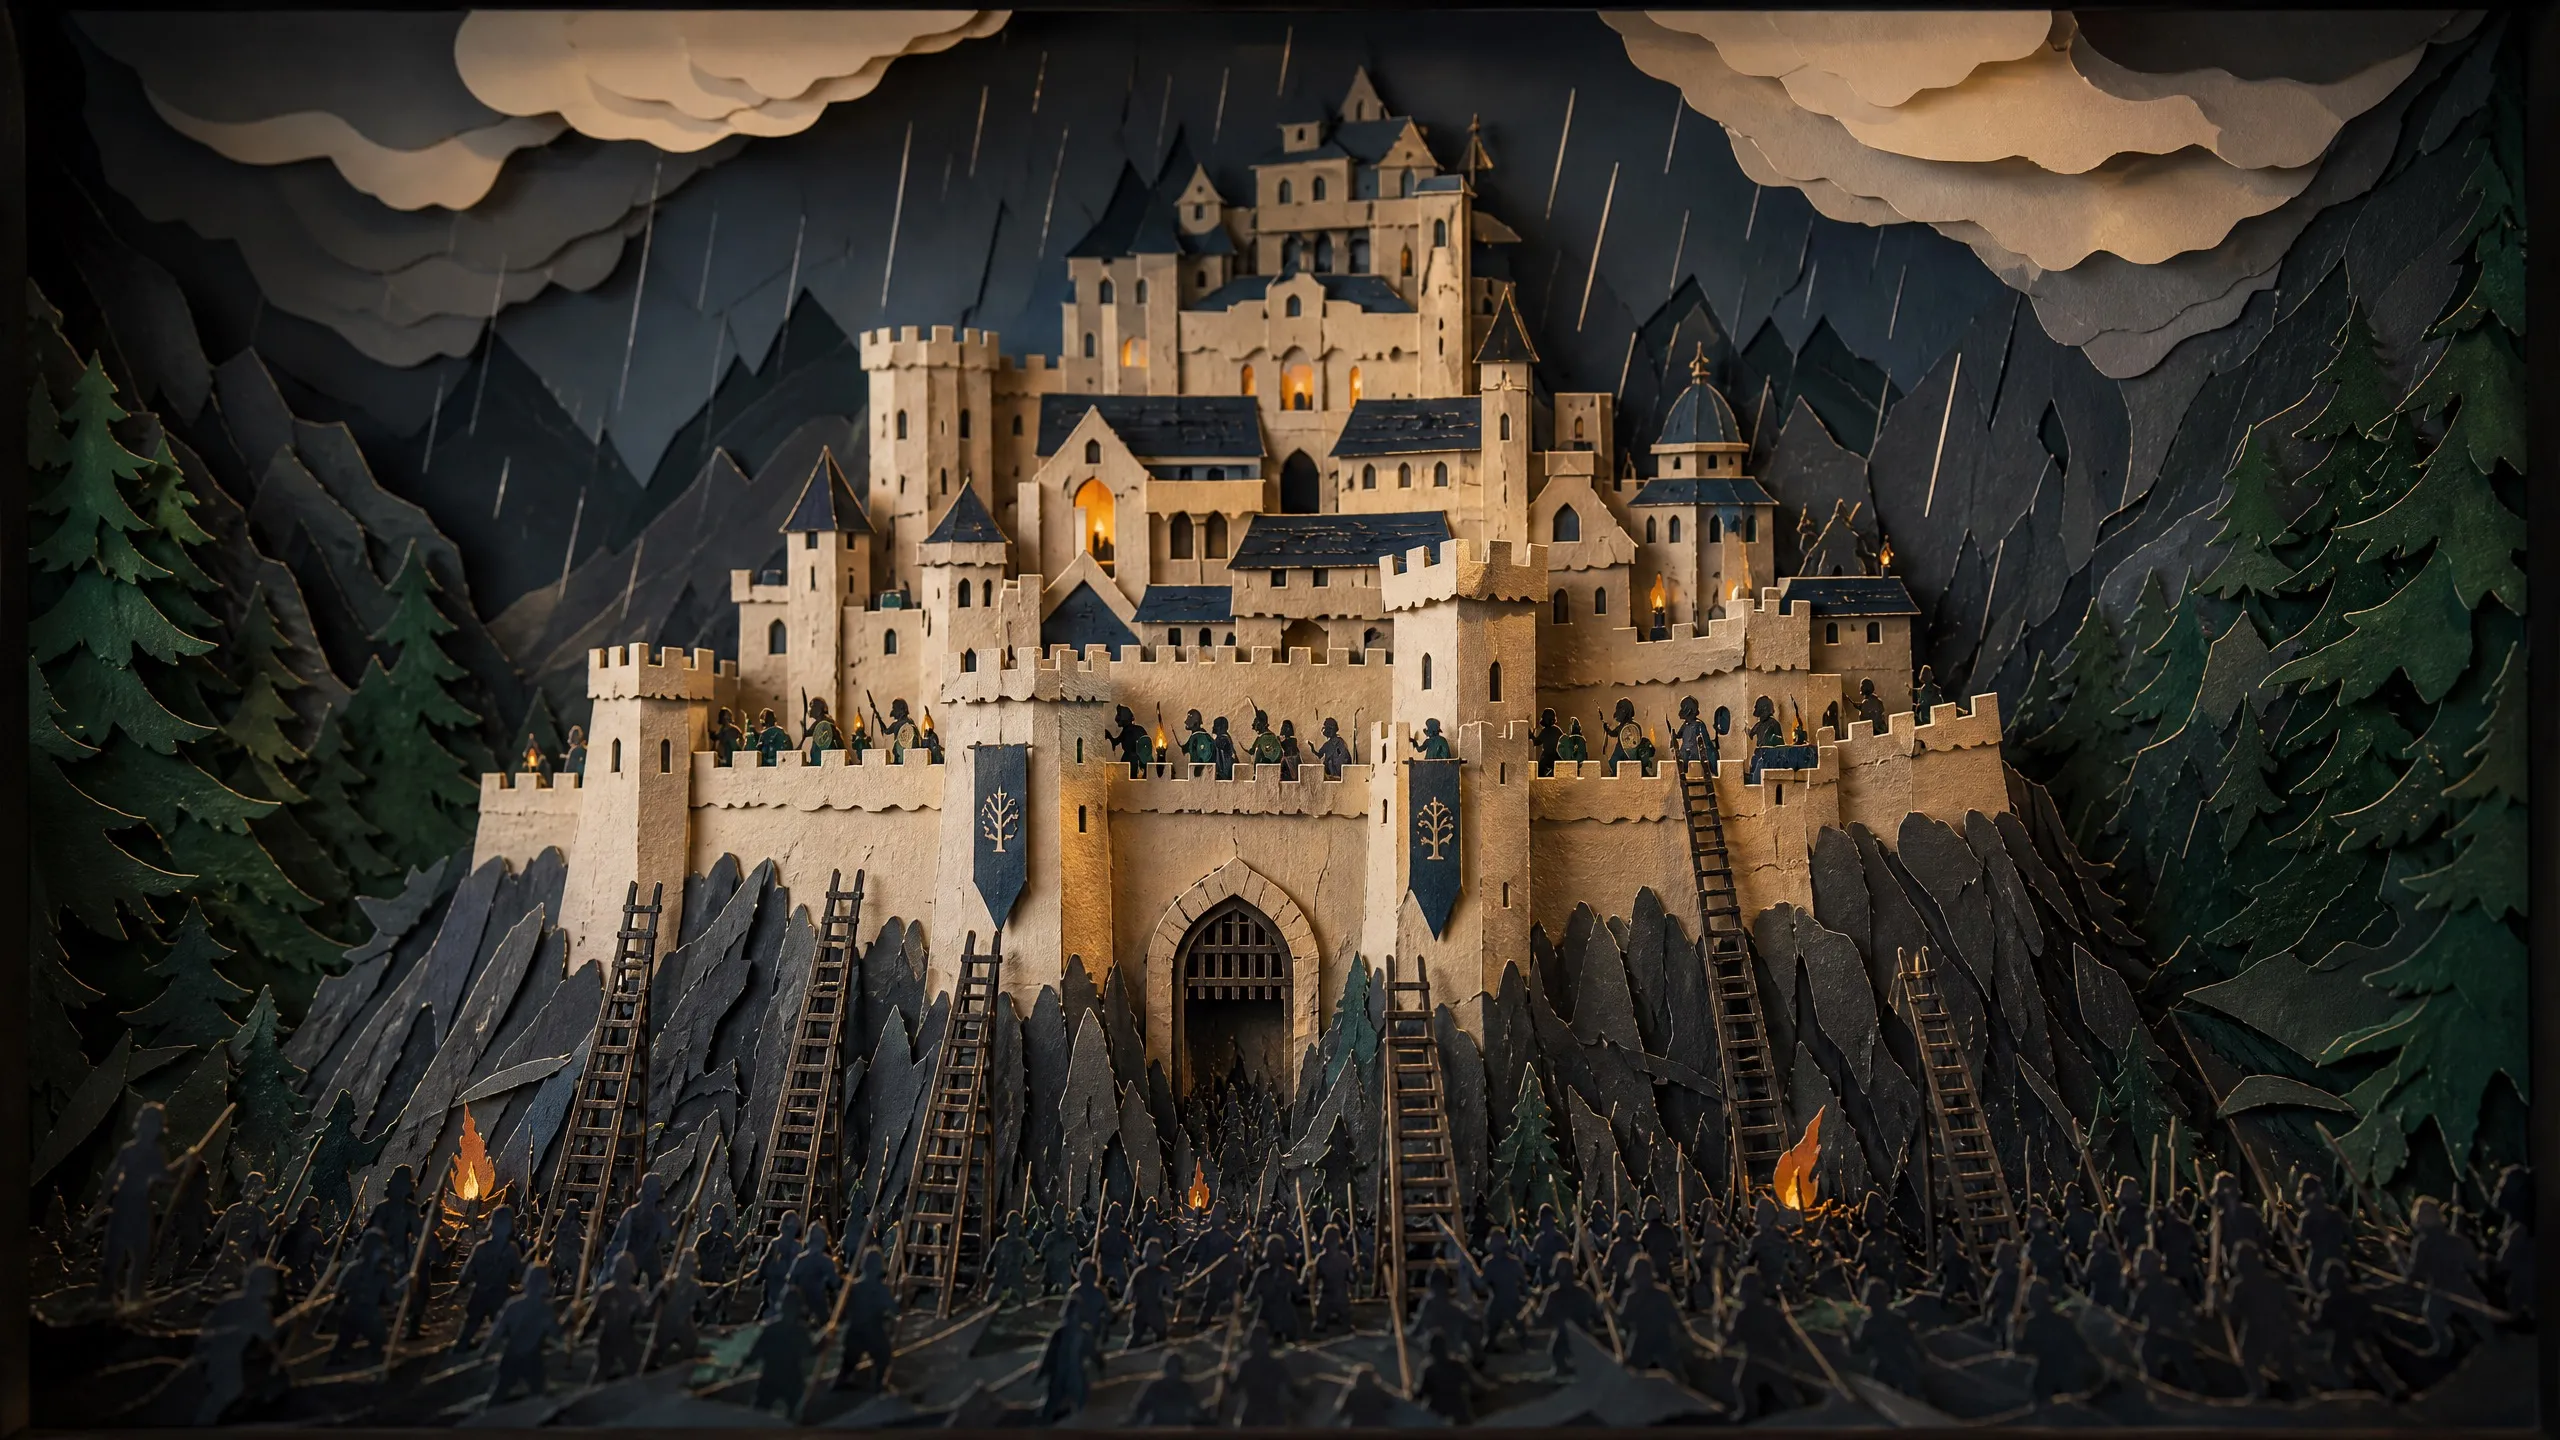
Helm's Deep
Run date: 2026-09-22
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
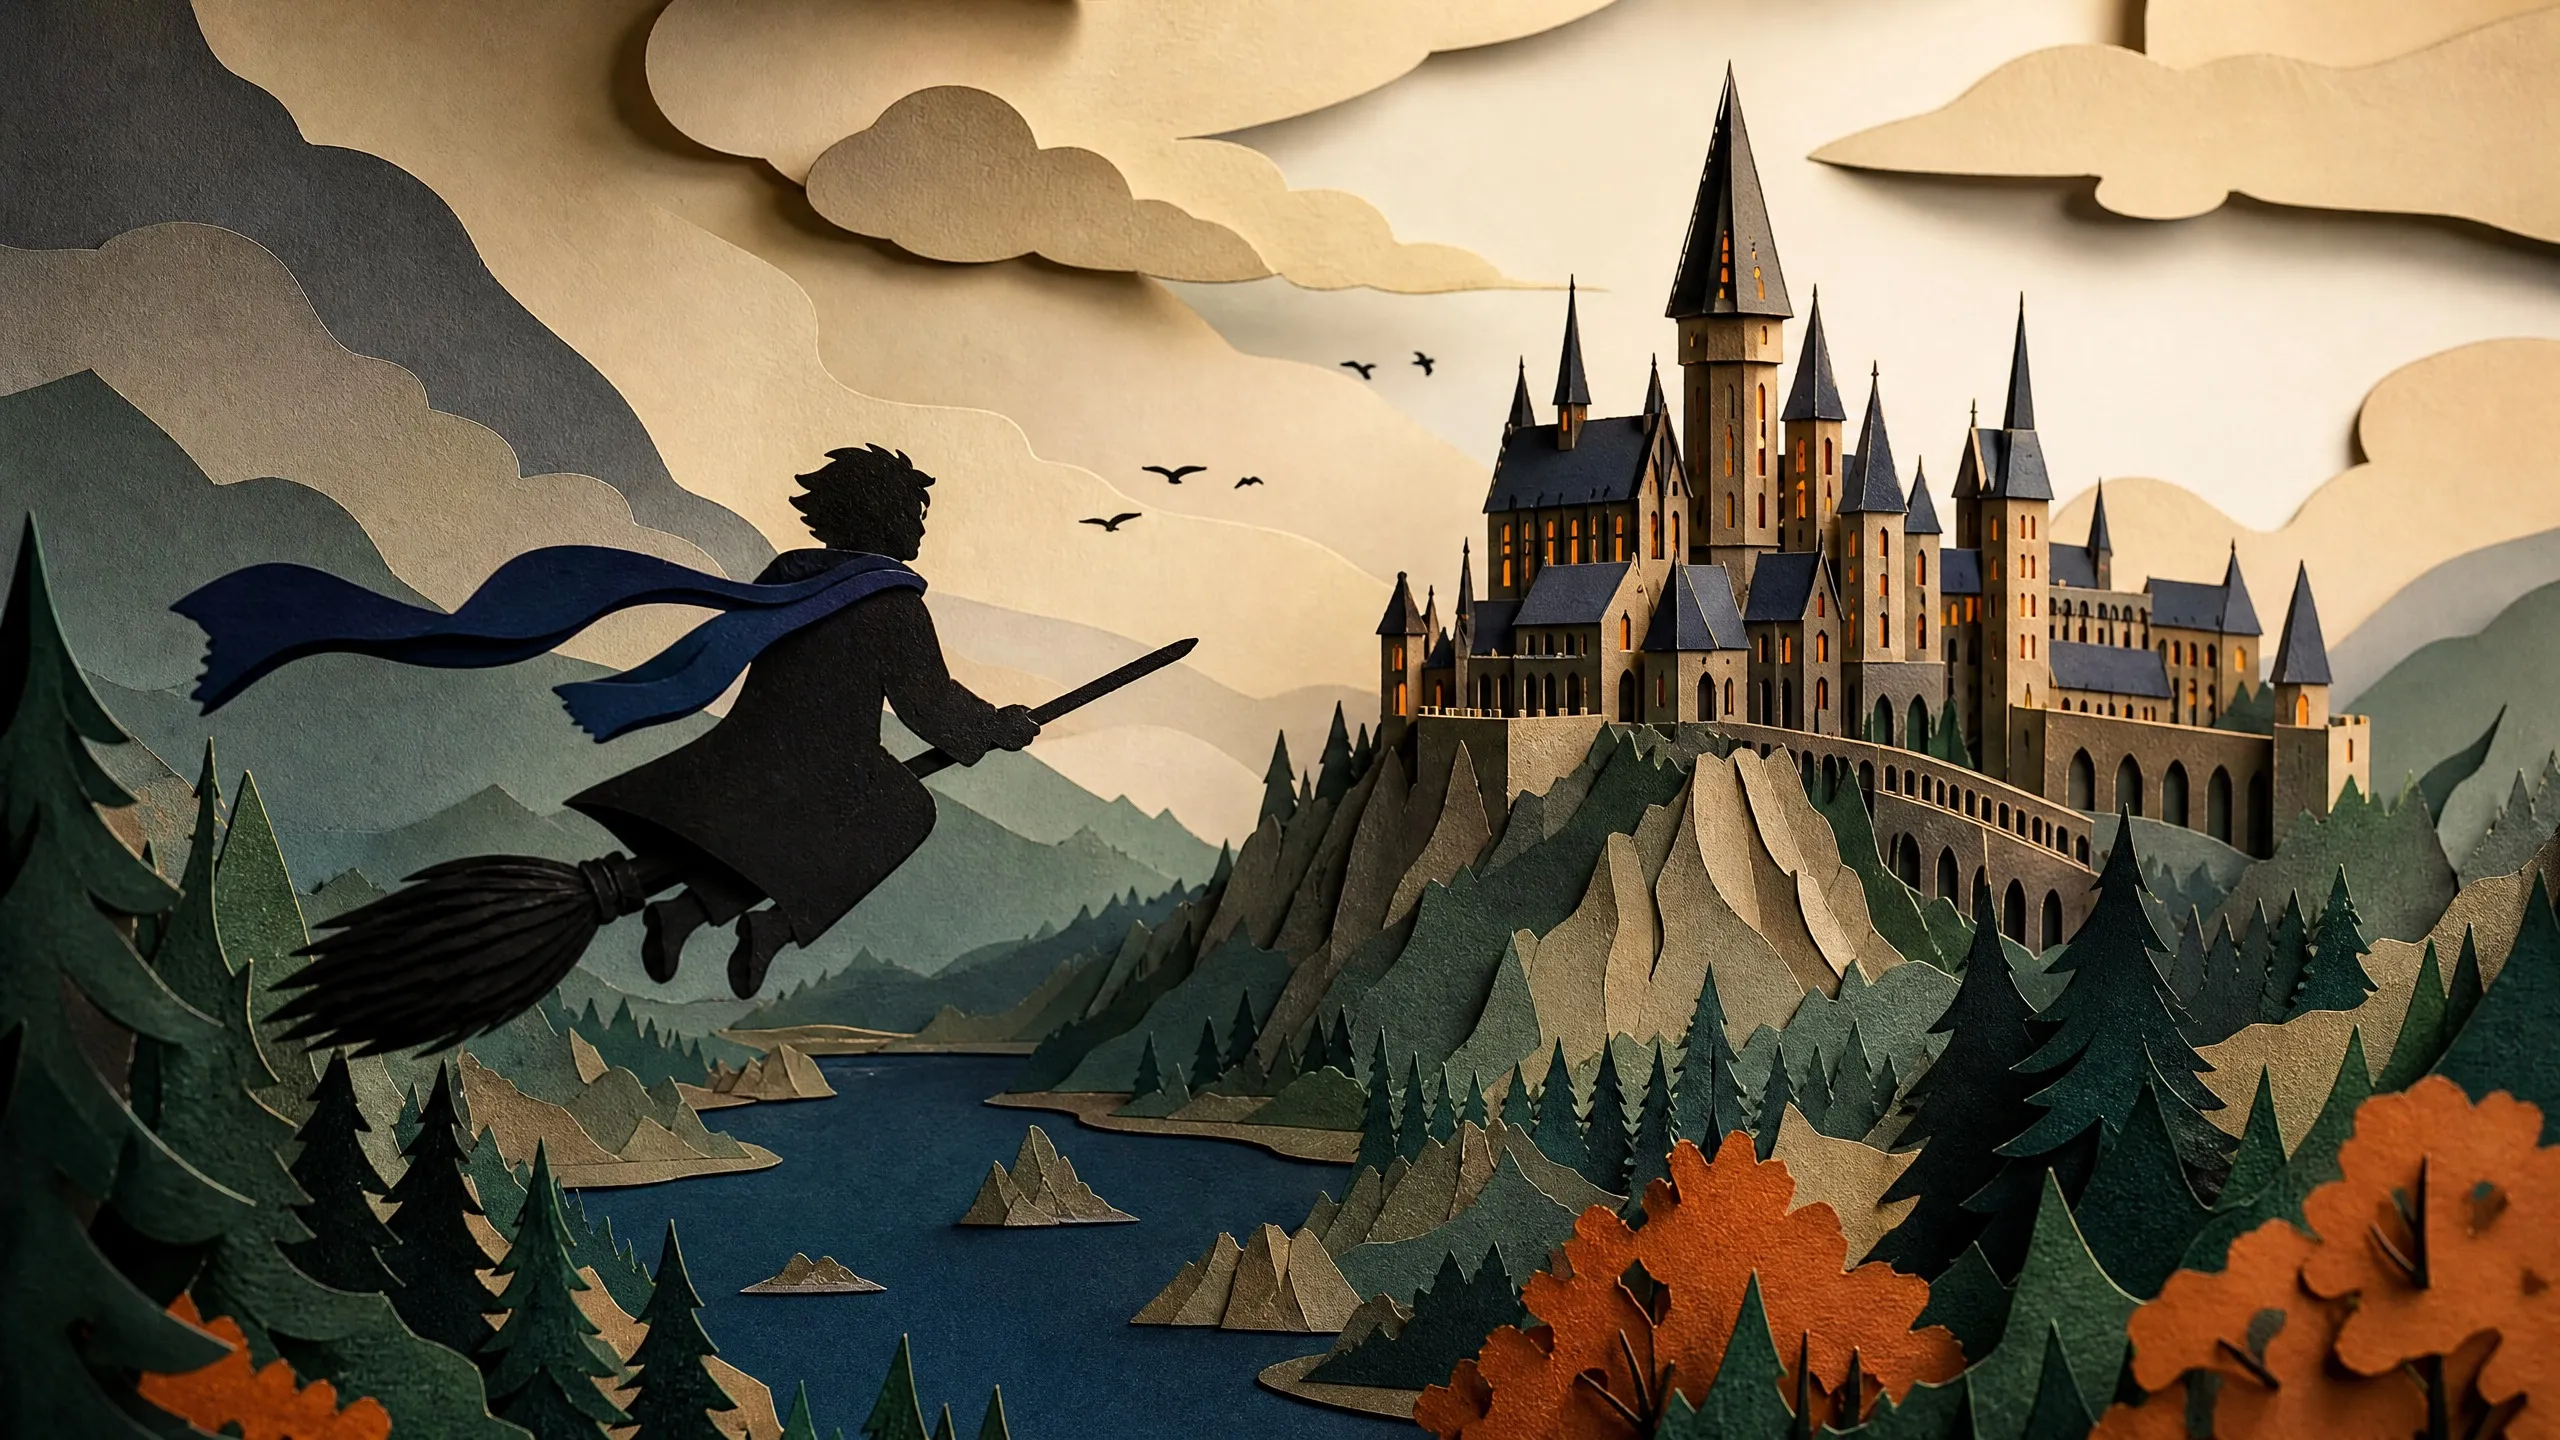
Hogwarts Broom Flight Simulator
Run date: 2026-09-22
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
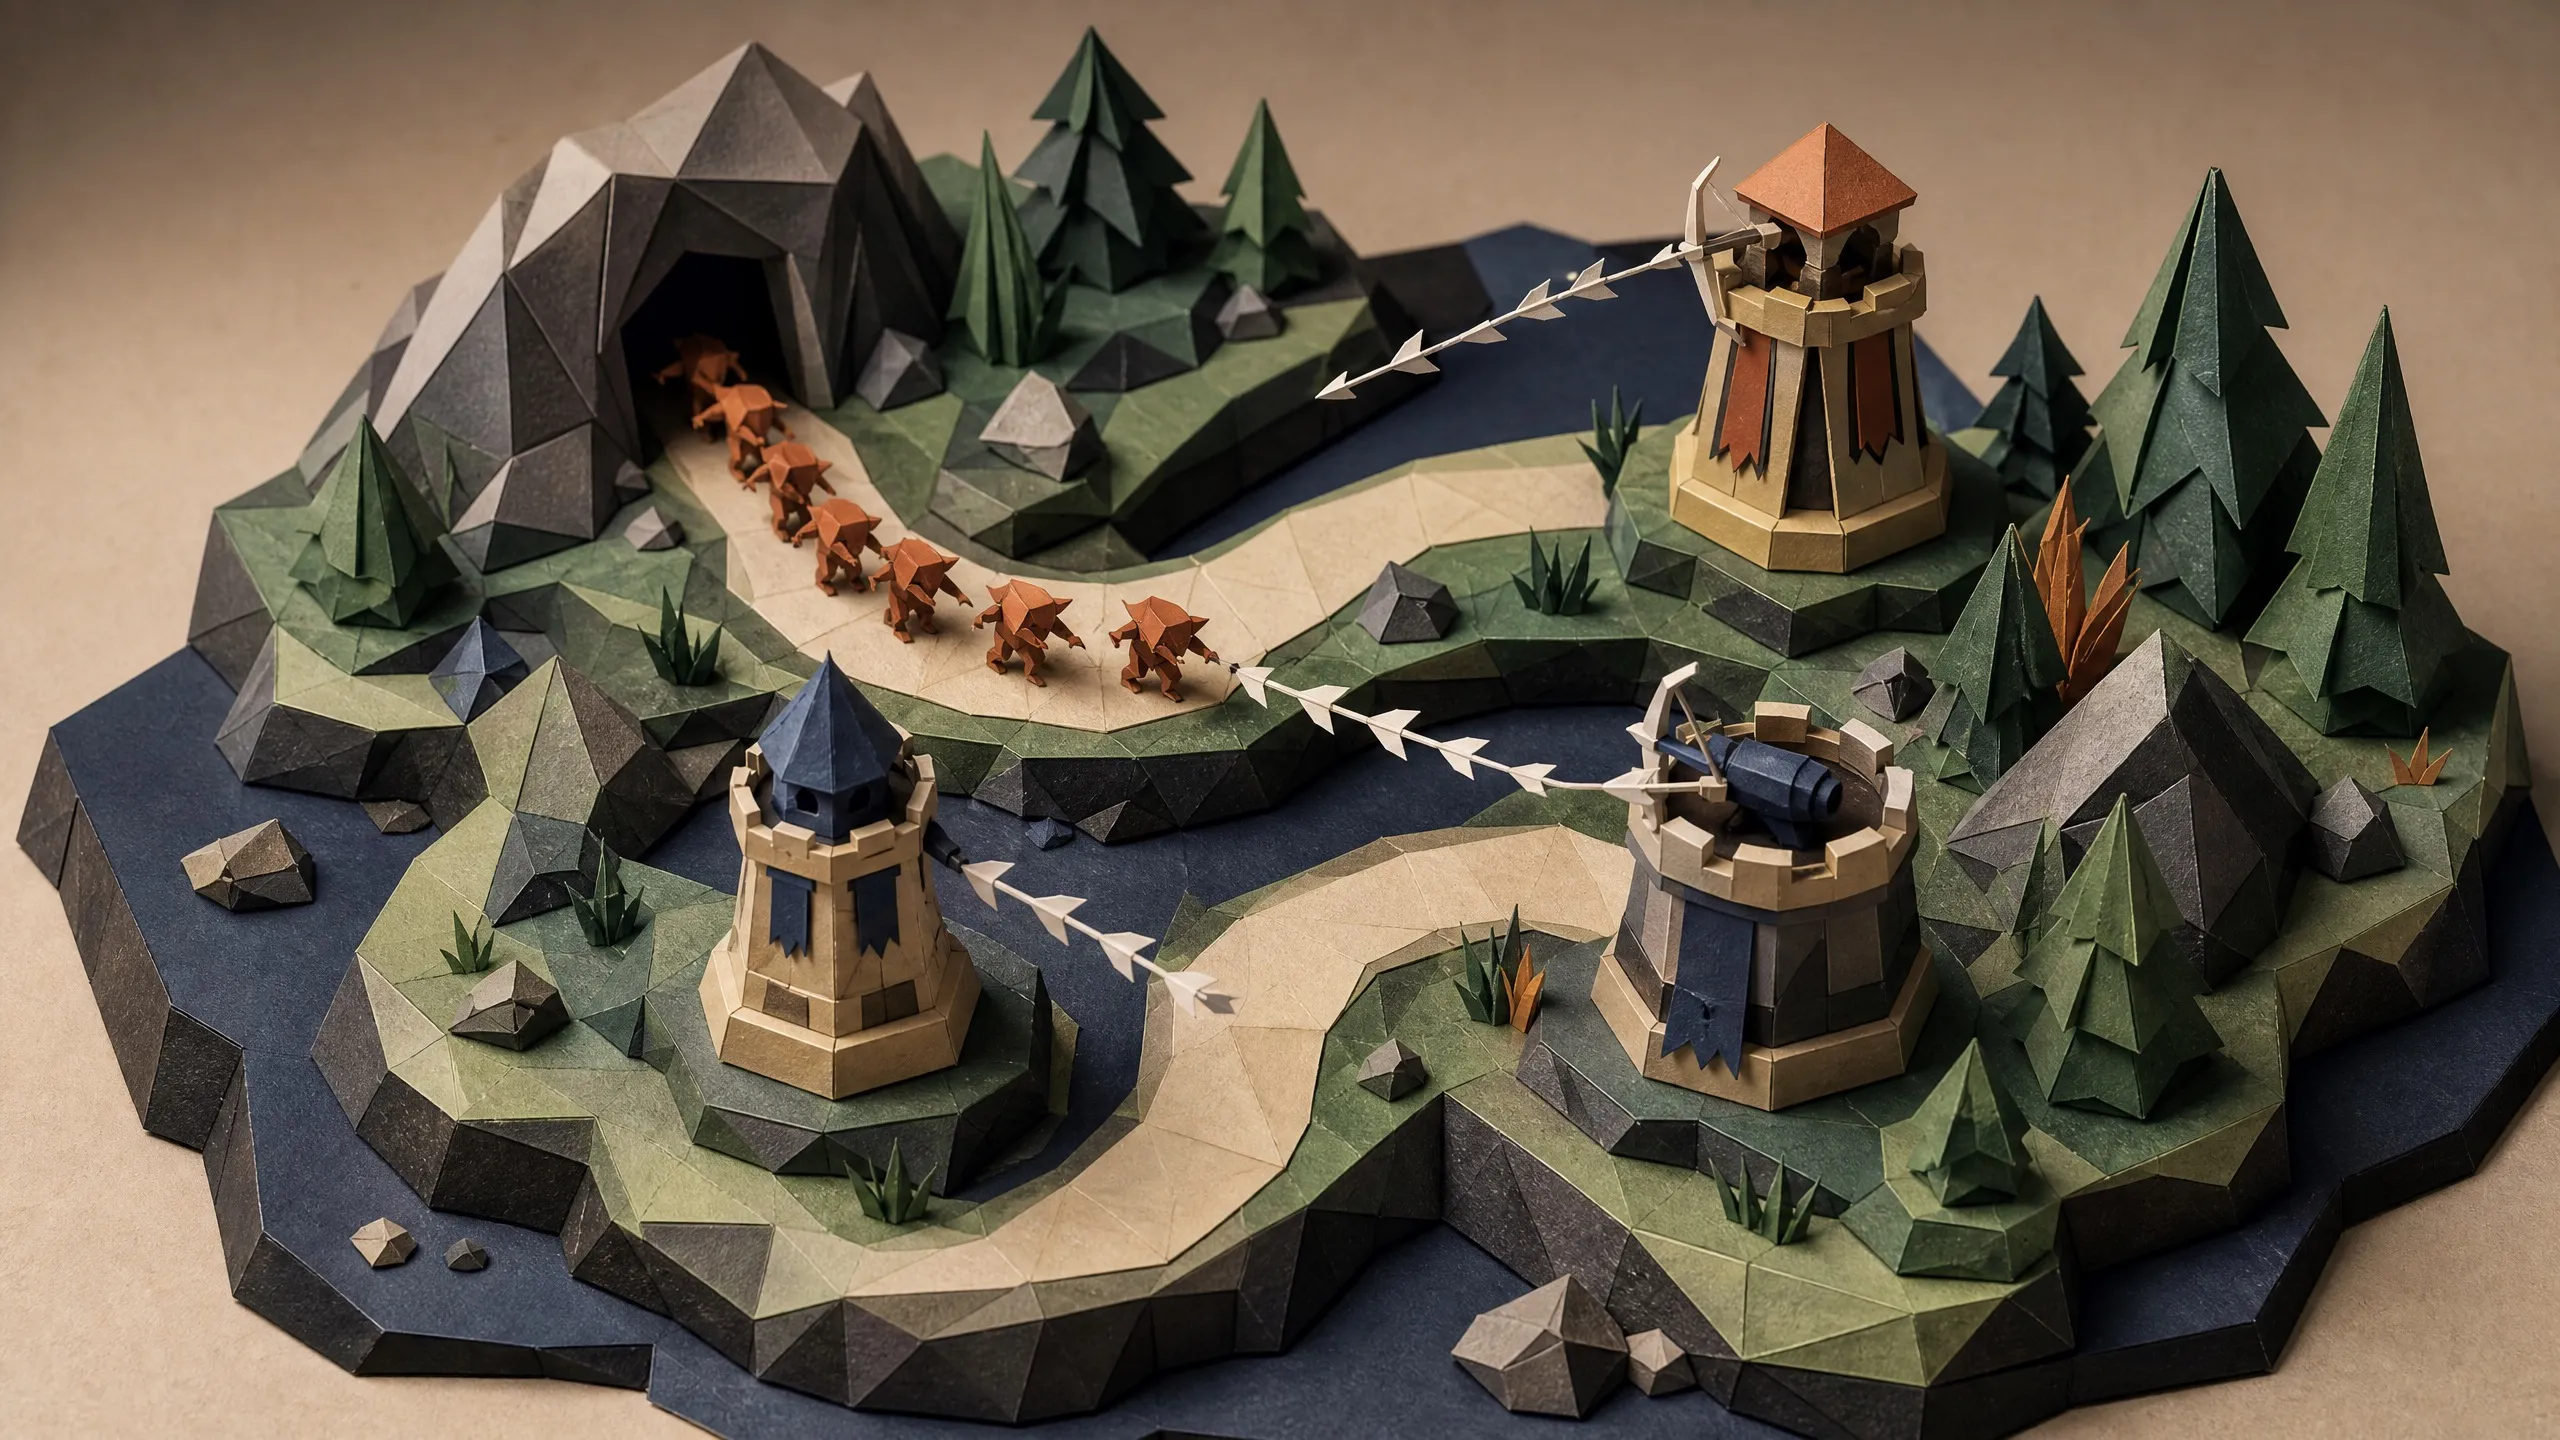
Low-Poly Tower Defense
Run date: 2026-09-22
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
Mechanical Watch Simulator
Run date: 2026-09-22
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.
Neon Drift
Run date: 2026-09-22
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-09-22
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
Stormwind Trebuchet Simulator
Run date: 2026-09-22
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
Yingzao Fashi Assembly
Run date: 2026-09-22
Specialist test · evaluated separately
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How DeepSeek V4.1 Flash compares
2 peers with published comparison scores.
- DeepSeek V4.1 Flash This model
- DeepSeek V4 Flash
- DeepSeek V4 Pro
6 benchmarks · 3 models
Official benchmark profile
Published scores outside our visual tests
GPQA Diamond
90.9%Codeforces
3471Terminal-Bench 2.1
90.6%Full official benchmark table10 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| GPQA Diamond | STEM reasoning | 90.9% | |
| Codeforces | Competitive programming | 3471 | |
| Terminal-Bench 2.1 | Agentic coding | 90.6% | |
| DeepSWE v1.1 | Agentic coding | 74.2% | |
| CyberGym | Cybersecurity agent | 88.1% | |
| SEC-Bench Pro | Security coding | 62.8% | |
| HLE with tools | Tool-using reasoning | 63.9% | |
| AutomationBench | Agentic automation | 54.8% | |
| Agent's Last Exam | Agentic reasoning | 31.8% | |
| ZeroBench-main with tools | Visual agent | 49.0% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
deepseek-flash- Context
- 1M
- Max output
- 384K
- License
- MIT
- Access route
- DeepSeek API; the live API model ID is deepseek-flash. DeepSeek states that legacy V4 Flash, V4 Flash Vision Exp, and V4 Pro IDs temporarily route here.
- Modalities
- text input, image input, text output
- Hardware
- Not publicly verified
- DeepSeek API peak rate · USD / 1M tokens
- $0.3 input · $0.006 cached input · $1.2 output
Peak hours are Monday-Friday, 01:00-04:00 and 06:00-10:00 UTC. Off-peak rates are half: $0.15 input, $0.003 cached input, and $0.60 output per 1M tokens.
Benchmark sources
DeepSeek V4.1 Flash is a 552B-parameter multimodal MoE model with a 1M-token context window. The provider reports 8B active parameters during prefill and 16B during decoding. Scores below are the provider's maximum-reasoning results; agent benchmarks use different harnesses and are not a universal leaderboard.
DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache CompressionThese are DeepSeek-reported results, not Superbash visual benchmark runs. The provider reports maximum reasoning effort (reasoning_effort=100), its named harnesses, and a 1M-token context limit for the code-agent evaluations.
Evaluation settings
- Pass@1 at maximum reasoning effort; DeepSeek-reported.
- Rating at maximum reasoning effort; DeepSeek-reported.
- Pass@1 using DeepSeek Harness Minimal and a 1M-token context; DeepSeek-reported.
- Resolved rate using mini-SWE and a 1M-token context; DeepSeek-reported.
- Pass@1 using the Claude Code harness; DeepSeek-reported.
- Pass@1 using the official scaffold; DeepSeek-reported.
- Pass@5 using the Claude Code harness and a 512K-token context; DeepSeek-reported.
Editorial verdict
Where this model fits
DeepSeek V4.1 Flash is the current DeepSeek API model: a 552B-parameter multimodal MoE with a one-million-token context window. DeepSeek reports results ahead of its retiring V4 Pro on several agentic evaluations, including Terminal-Bench 2.1 and DeepSWE v1.1. A tier reflects that published capability and its unusually low peak API rate. All 16 same-prompt Superbash visual runs are published and stay separate from those first-party scores.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: DeepSeek V4.1 Flash is currently placed in Tier A.
The September 2026 editorial roster places DeepSeek V4.1 Flash at rank 7.
Open source →DeepSeek-V4.1-Flash: Smarter, Faster, More Efficient
Takeaway: V4.1 Flash is DeepSeek’s current API model, with native image understanding, lower API pricing than the retired V4 Flash route, and a now-published 16-run Superbash visual suite.
The official release confirms the live model ID, compatibility routing, native multimodal support, and the V4 Pro transition. The provider benchmark table is presented separately from the Superbash visual runs, which are a same-prompt evidence layer.
Open source →Related guides