Case studies · Tutorial 01
Claude Code for Beginners: Build with a Coding Agent
Put Claude Code inside a real repository and use a write, test, fix loop to build safely. See when Hermes or Cursor is a better fit.
0 of 14 complete
Last tested and updated: September 1, 2026
You’ve pasted a function into ChatGPT and watched the answer look right but fail at runtime. A coding harness closes that gap: it reads your repo, runs your tests, and loops until green. Claude Code is Anthropic’s coding harness.
See L02: Vibe Coding vs Real Coding for the first hands-on.
Work inside the repository
Pick a real task from your last sprint: “Add a ?since= filter to the user list endpoint, and update the tests.”
A chatbot without access to your repository does not know its routes, ORM, test fixtures, or broken serializer. A coding harness can inspect that context, run the tests, and work from the failures.
A coding harness turns an AI from a question-asker into a project-worker. It reads your codebase, runs commands, proposes diffs, and loops on test output until done. Claude Code is the Anthropic-native version.
The write-test-review loop
Claude Code wraps a model in an engineering shell that runs inside your repository. Unlike a standalone chat, it can work with the files and tools that determine whether a change is correct.

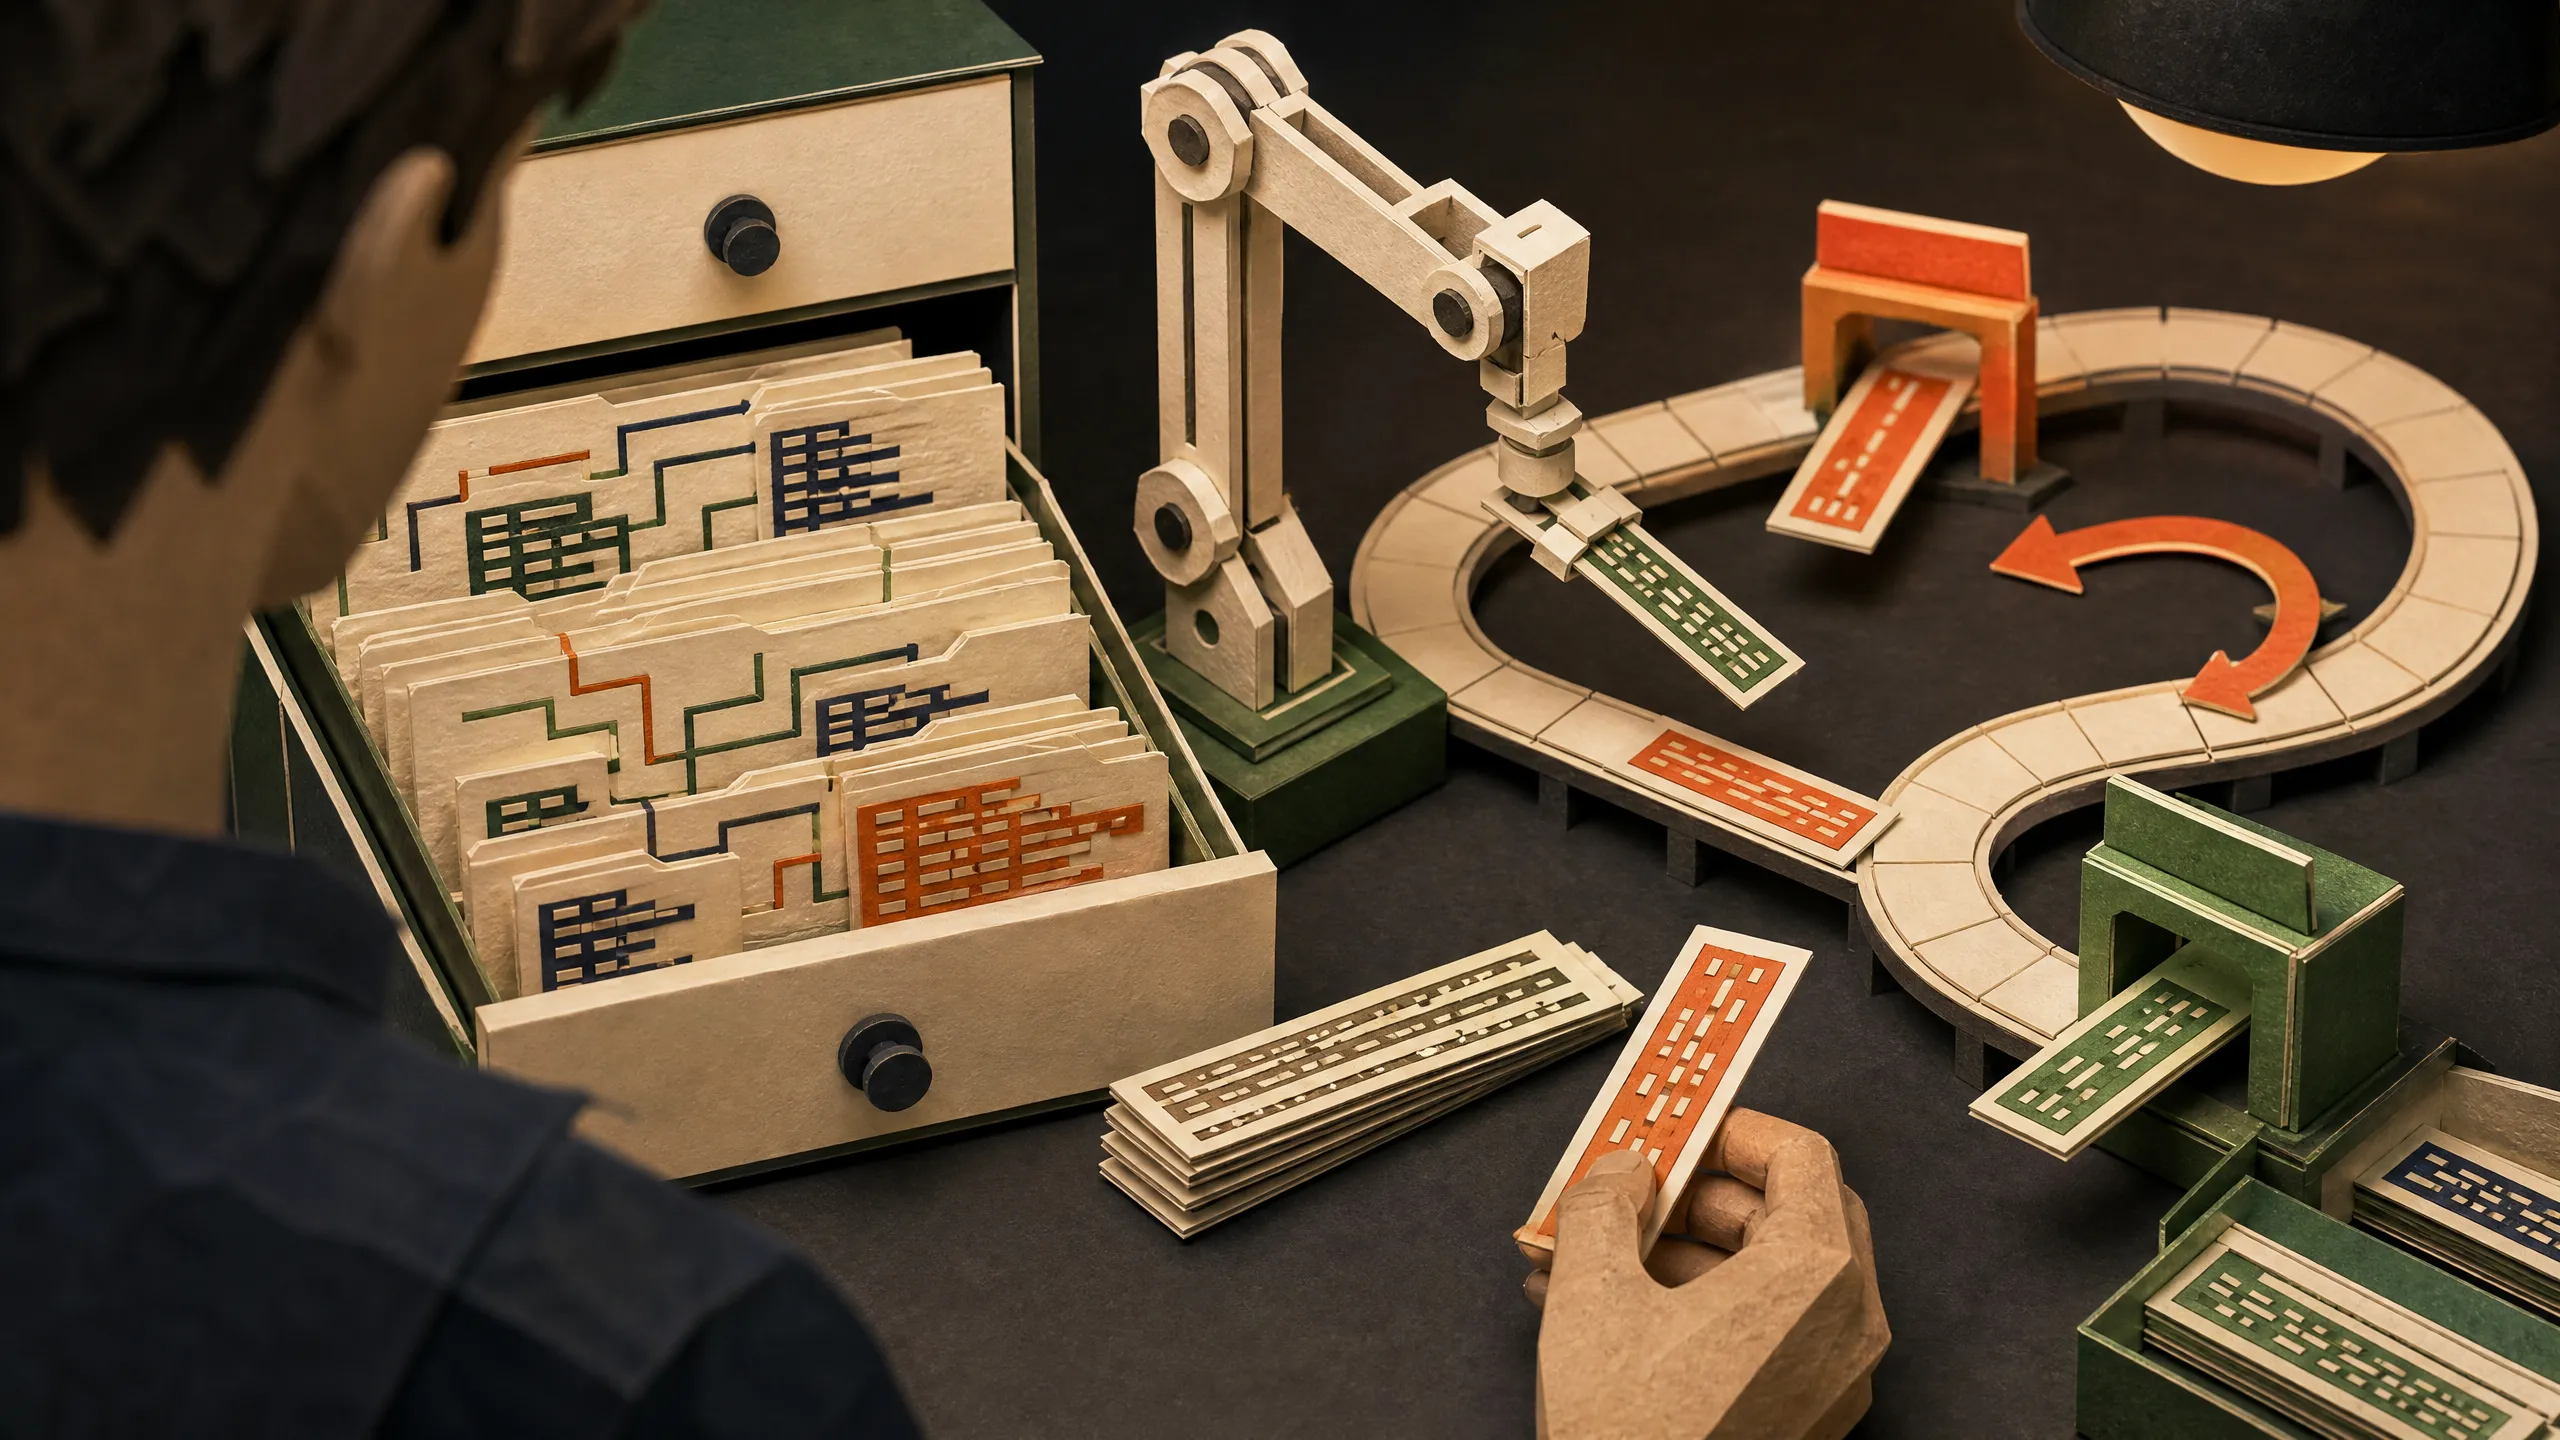
The diagram above is the shape of a real session. The cycle is:
- You open Claude Code in your repo and describe a task in plain English.
- Claude Code reads the relevant files, proposes a diff, and runs the test runner.
- The test runner either goes green, which finishes the loop, or returns an error for another pass.
- When the suite is green, Claude Code commits and opens a pull request for human review.
The point isn’t that Claude Code is “smarter” than a chat model. It owns the engineering shell: the file system, the shell, the test runner, and the Git workflow. The model is the brain. The harness is the body.
Claude Code doesn’t replace the engineering shell. It is the engineering shell. The model inside it is interchangeable; the loop around it is the product.
Match the harness to the job
Claude Code is not the only way to use AI in 2026. Pick wrong in week one and you may not ship by month one.
Coding harnesses verify by running. They live in your repo, run your test suite, and iterate. Claude Code, Kilo Code, and Cursor’s agent mode are the three that matter in 2026.
Agent harnesses verify by inferring. They live outside one codebase, persist across sessions, run on schedules, and integrate with chat channels. Hermes is the flagship. See L01: What Is Hermes Agent?.
Chat interfaces are the third category. They’re a tab you open, a question you type, an answer you copy-paste. Useful for one-shot research, useless for shipping software.
When to pick which
| Goal | Pick | Why |
|---|---|---|
| Ship a feature in a real repo | Claude Code or Kilo Code | Test-driven loop, diff review, Git workflow. |
| Hard refactor across hundreds of files | Claude Code | Polished harness, long context, the best at “really big problems.” |
| Daily incremental work on a budget | Kilo Code + a cheap model | Open-source, BYOK (Bring Your Own Key): you supply the model API key. $15 to $30/mo instead of $200/mo. |
| 7am Discord summary from RSS feeds | Hermes | Long-running, multi-channel, persistent: see L09: Hermes vs Claude Code vs Mavis. |
| Visual / IDE-first workflow | Cursor with agent mode | Editor-native, less test-loop, more “show me the file.” |
| One-off “what does this regex mean?” | Chat interface | Single question, no repo context needed. |
Rule of thumb: work in a repo → coding harness. Work outside one → Hermes. One-shot question → chat tab.
For pricing tiers, BYOK tradeoffs, and the Max plan: see L09: Hermes vs Claude Code vs Mavis.
What Claude Code specifically is
Claude Code is Anthropic’s coding harness. It is a terminal-native program (also packaged as an IDE plugin) that:
- Reads and writes files in the repo you launch it from.
- Runs shell commands:
npm test,pytest,go test,make, whatever your project uses. - Proposes diffs before applying them, so you can review.
- Commits, pushes, and opens pull requests on GitHub.
- Works with any model Anthropic ships (Sonnet for daily, Opus for hard), but you don’t bring your own key.
What Claude Code is not:
- Not a chat app. The interface is a terminal session, not a web tab. There’s a desktop wrapper, but the underlying model is CLI.
- Not a model. Claude Code ships with Anthropic’s models baked in. Pricing is a flat subscription: Pro ($20/mo) for Sonnet, Max ($200/mo) for heavy Opus use.
- Not magic. Claude Code is best at well-bounded, well-tested work. Vague prompts on a sprawling codebase still go sideways, as L02: Vibe Coding vs Real Coding explains.
A side-by-side: Claude Code vs Cursor
The two are the most-confused tools in 2026, and they’re not the same thing.
| Dimension | Claude Code | Cursor (agent mode) |
|---|---|---|
| Where it lives | Terminal (CLI) + IDE plugin | IDE first, chat panel inside |
| Test loop | Yes: runs your suite, iterates | Partial: better for visual diffs |
| Best for | Hard refactors, multi-file work, shipping | Visual refactors, single-file edits, exploration |
| Pricing | $20 / $200 per month | ~$20 per month |
| Open source | No | No |
| Diff review | First-class | Good |
| Beginner-friendly | Moderate (terminal) | Easy (IDE) |
The honest answer: if your work is “I need to ship a feature in my repo this week,” Claude Code. If your work is “I need to fiddle with a component and see the preview live,” Cursor.
Budget Claude Code work around the September 14 transition
Checked September 1, 2026. Re-check your own Usage page before you plan a sprint. Anthropic’s official developer account says the temporary 50% increase to standard Claude Code weekly limits remains through September 14, 2026. Starting that date, it says Pro, Max, Team, and seat-based Enterprise plans receive a permanent 25% increase over the original baseline. Official notice · independent interpretation
This is easy to misread. If the original weekly baseline is B, the temporary level is 1.50B and the permanent level is 1.25B. The permanent level is therefore (1.50B - 1.25B) / 1.50B = 16.7% below the temporary level, while still being 25% above the original baseline. The notice does not publish plan-specific token counts, model-specific limits, rollover behavior, or a guarantee that every account has identical effective capacity.
Run a five-session fit check before committing the week
Freeze five representative tasks first: the repo revision, prompt, enabled tools, model/effort setting, and acceptance test must stay fixed. For each session, record only a non-sensitive plan label and Usage-page indication, plus accepted completion, retries, elapsed time, and human correction. Never turn a meter percentage into an invented token count.
Use this fixed gate: recommend the current weekly workflow only if at least 90% of the five tasks are accepted within the post-change allowance, with no API-credit overage and no dependence on the temporary boost. With five tasks, that means all five must qualify. If the check fails—or is unmeasured—queue non-urgent work, reduce retry-heavy or open-ended tasks, and route lower-risk work to an approved alternative until you can re-measure.
For a strict subscription budget, decline API-credit continuation and wait for reset rather than using overage to make the experiment pass. Anthropic describes API-credit continuation as optional and says Pro/Max users can stay within their included allocation by declining it and waiting for reset. Plan usage and billing guidance
The reproducible, privacy-preserving manifest and calculation are in benchmarks/claude-code-usage-limits/. Current Claude plan copy says usage limits apply and plans may change; use it as a current plan reference, not as a token quota table. Claude plans and pricing
Map one real task
The exercise
You do not need to install anything for this conceptual exercise.
Open a text file on your computer. Write down the answer to this in your own words, no copy-paste:
“Pick a real task from your last week of coding, such as a bug, refactor, or feature. Walk it through the loop: editor → harness → test runner → pull request. Where would Claude Code have helped? Where would you still need to be the engineer?”
A good answer names where Claude Code would have caught a regression. It also names where you stay in the loop: design, ambiguous requirements, diff review.