Anthropic
Claude Fable 5
Version 1.0 benchmark runs across the shared Superbash visual prompts.
API pricing
USD per million tokens · Claude API Standard- Input
- $10
- Output
- $50
- Cached input
- $1
- Context window
- 1M
Inspect the original visual runs
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Run date: 2026-09-02
Specialist test · evaluated separately
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.
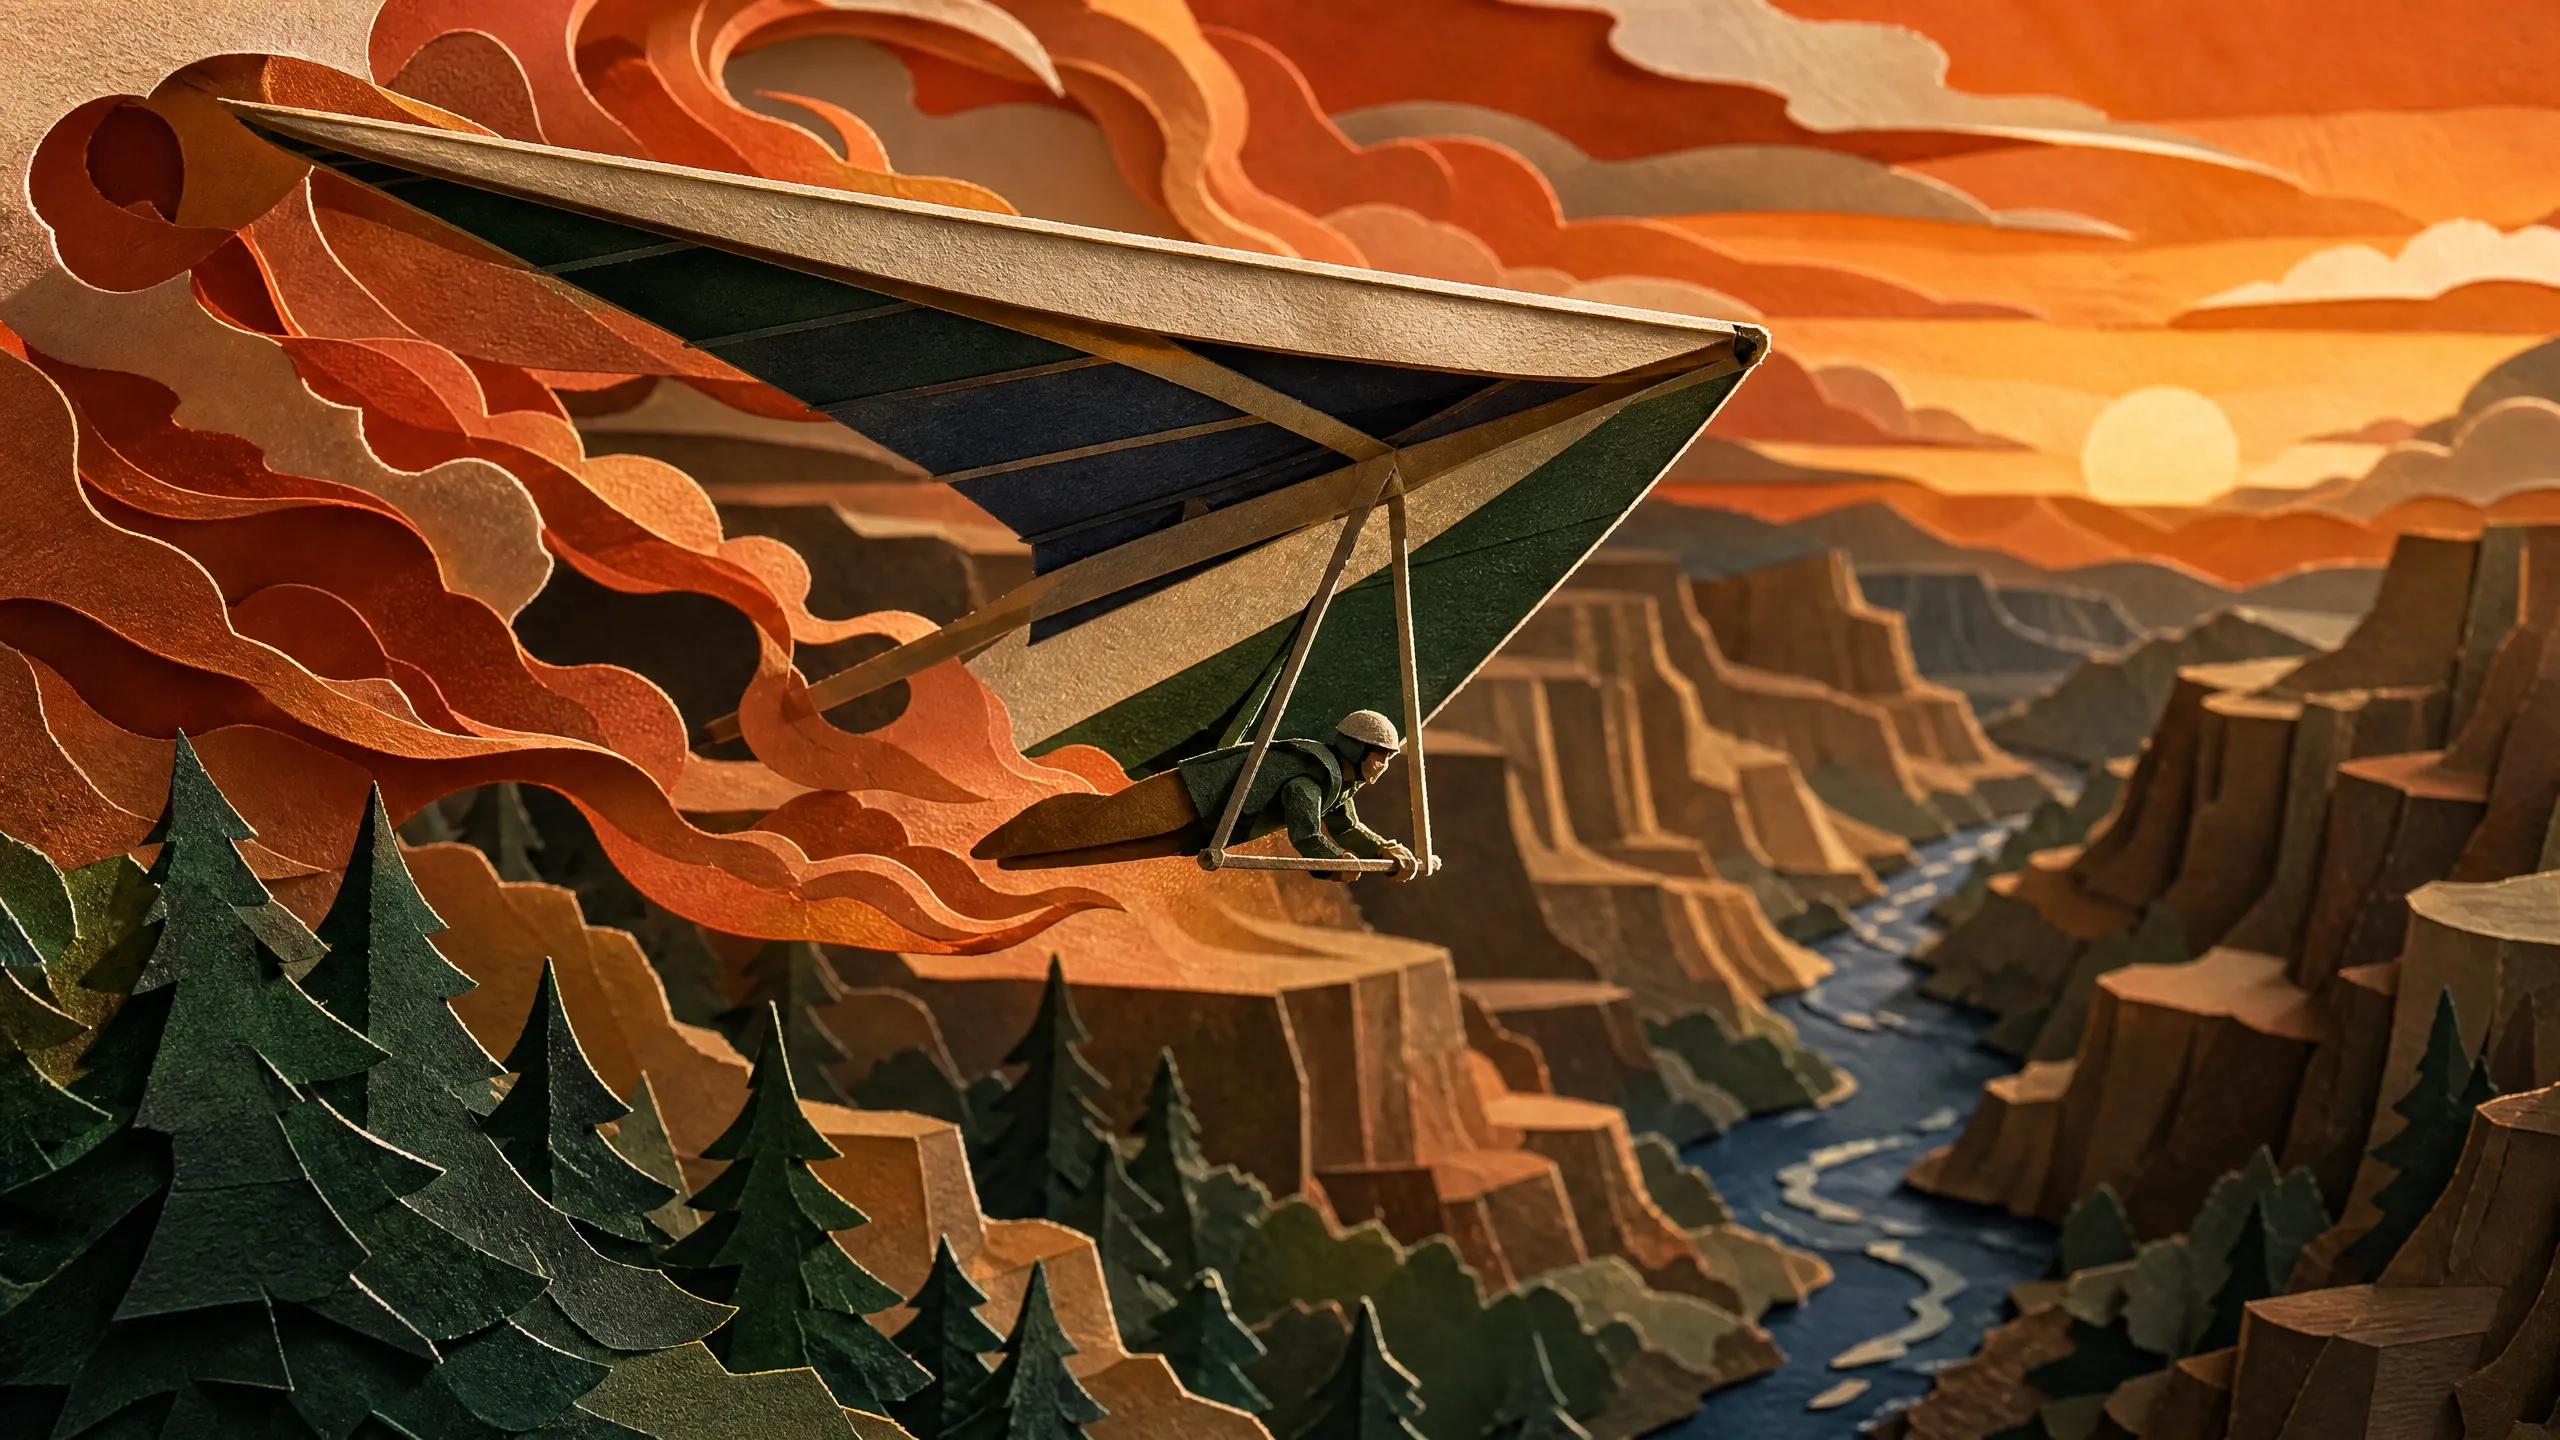
Ember Glider
Run date: 2026-09-02
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
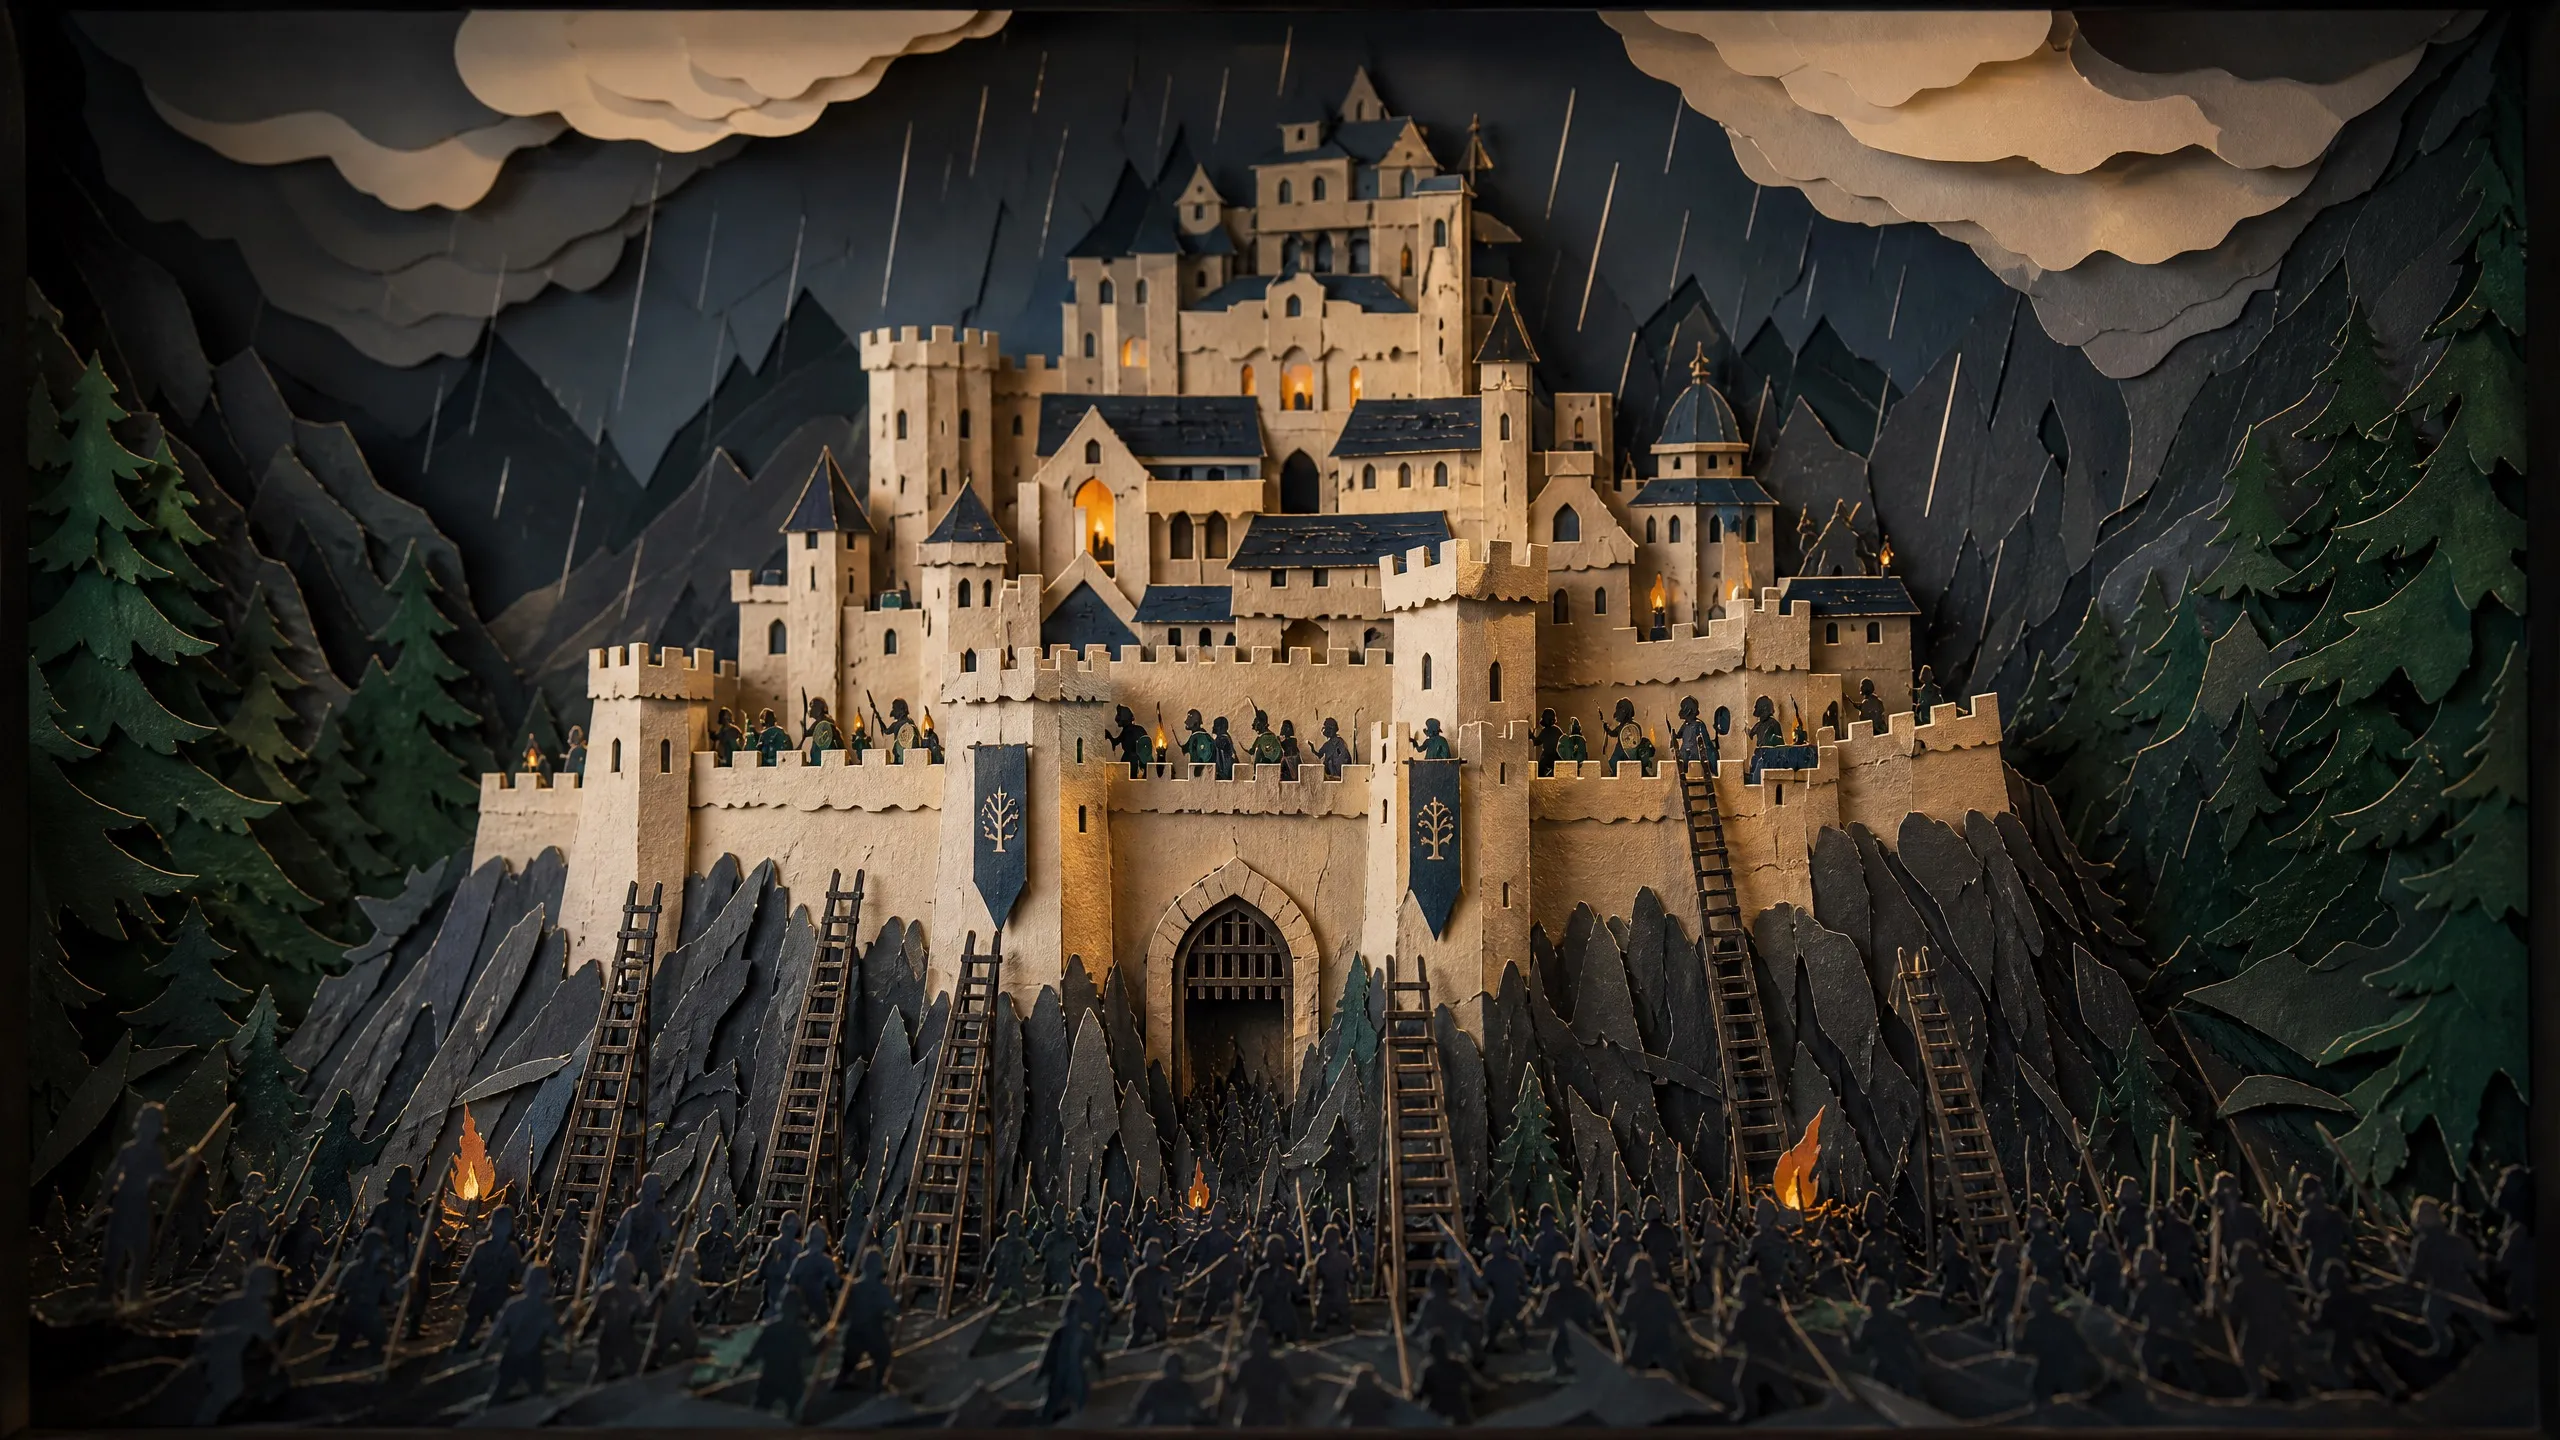
Helm's Deep
Run date: 2026-07-21
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
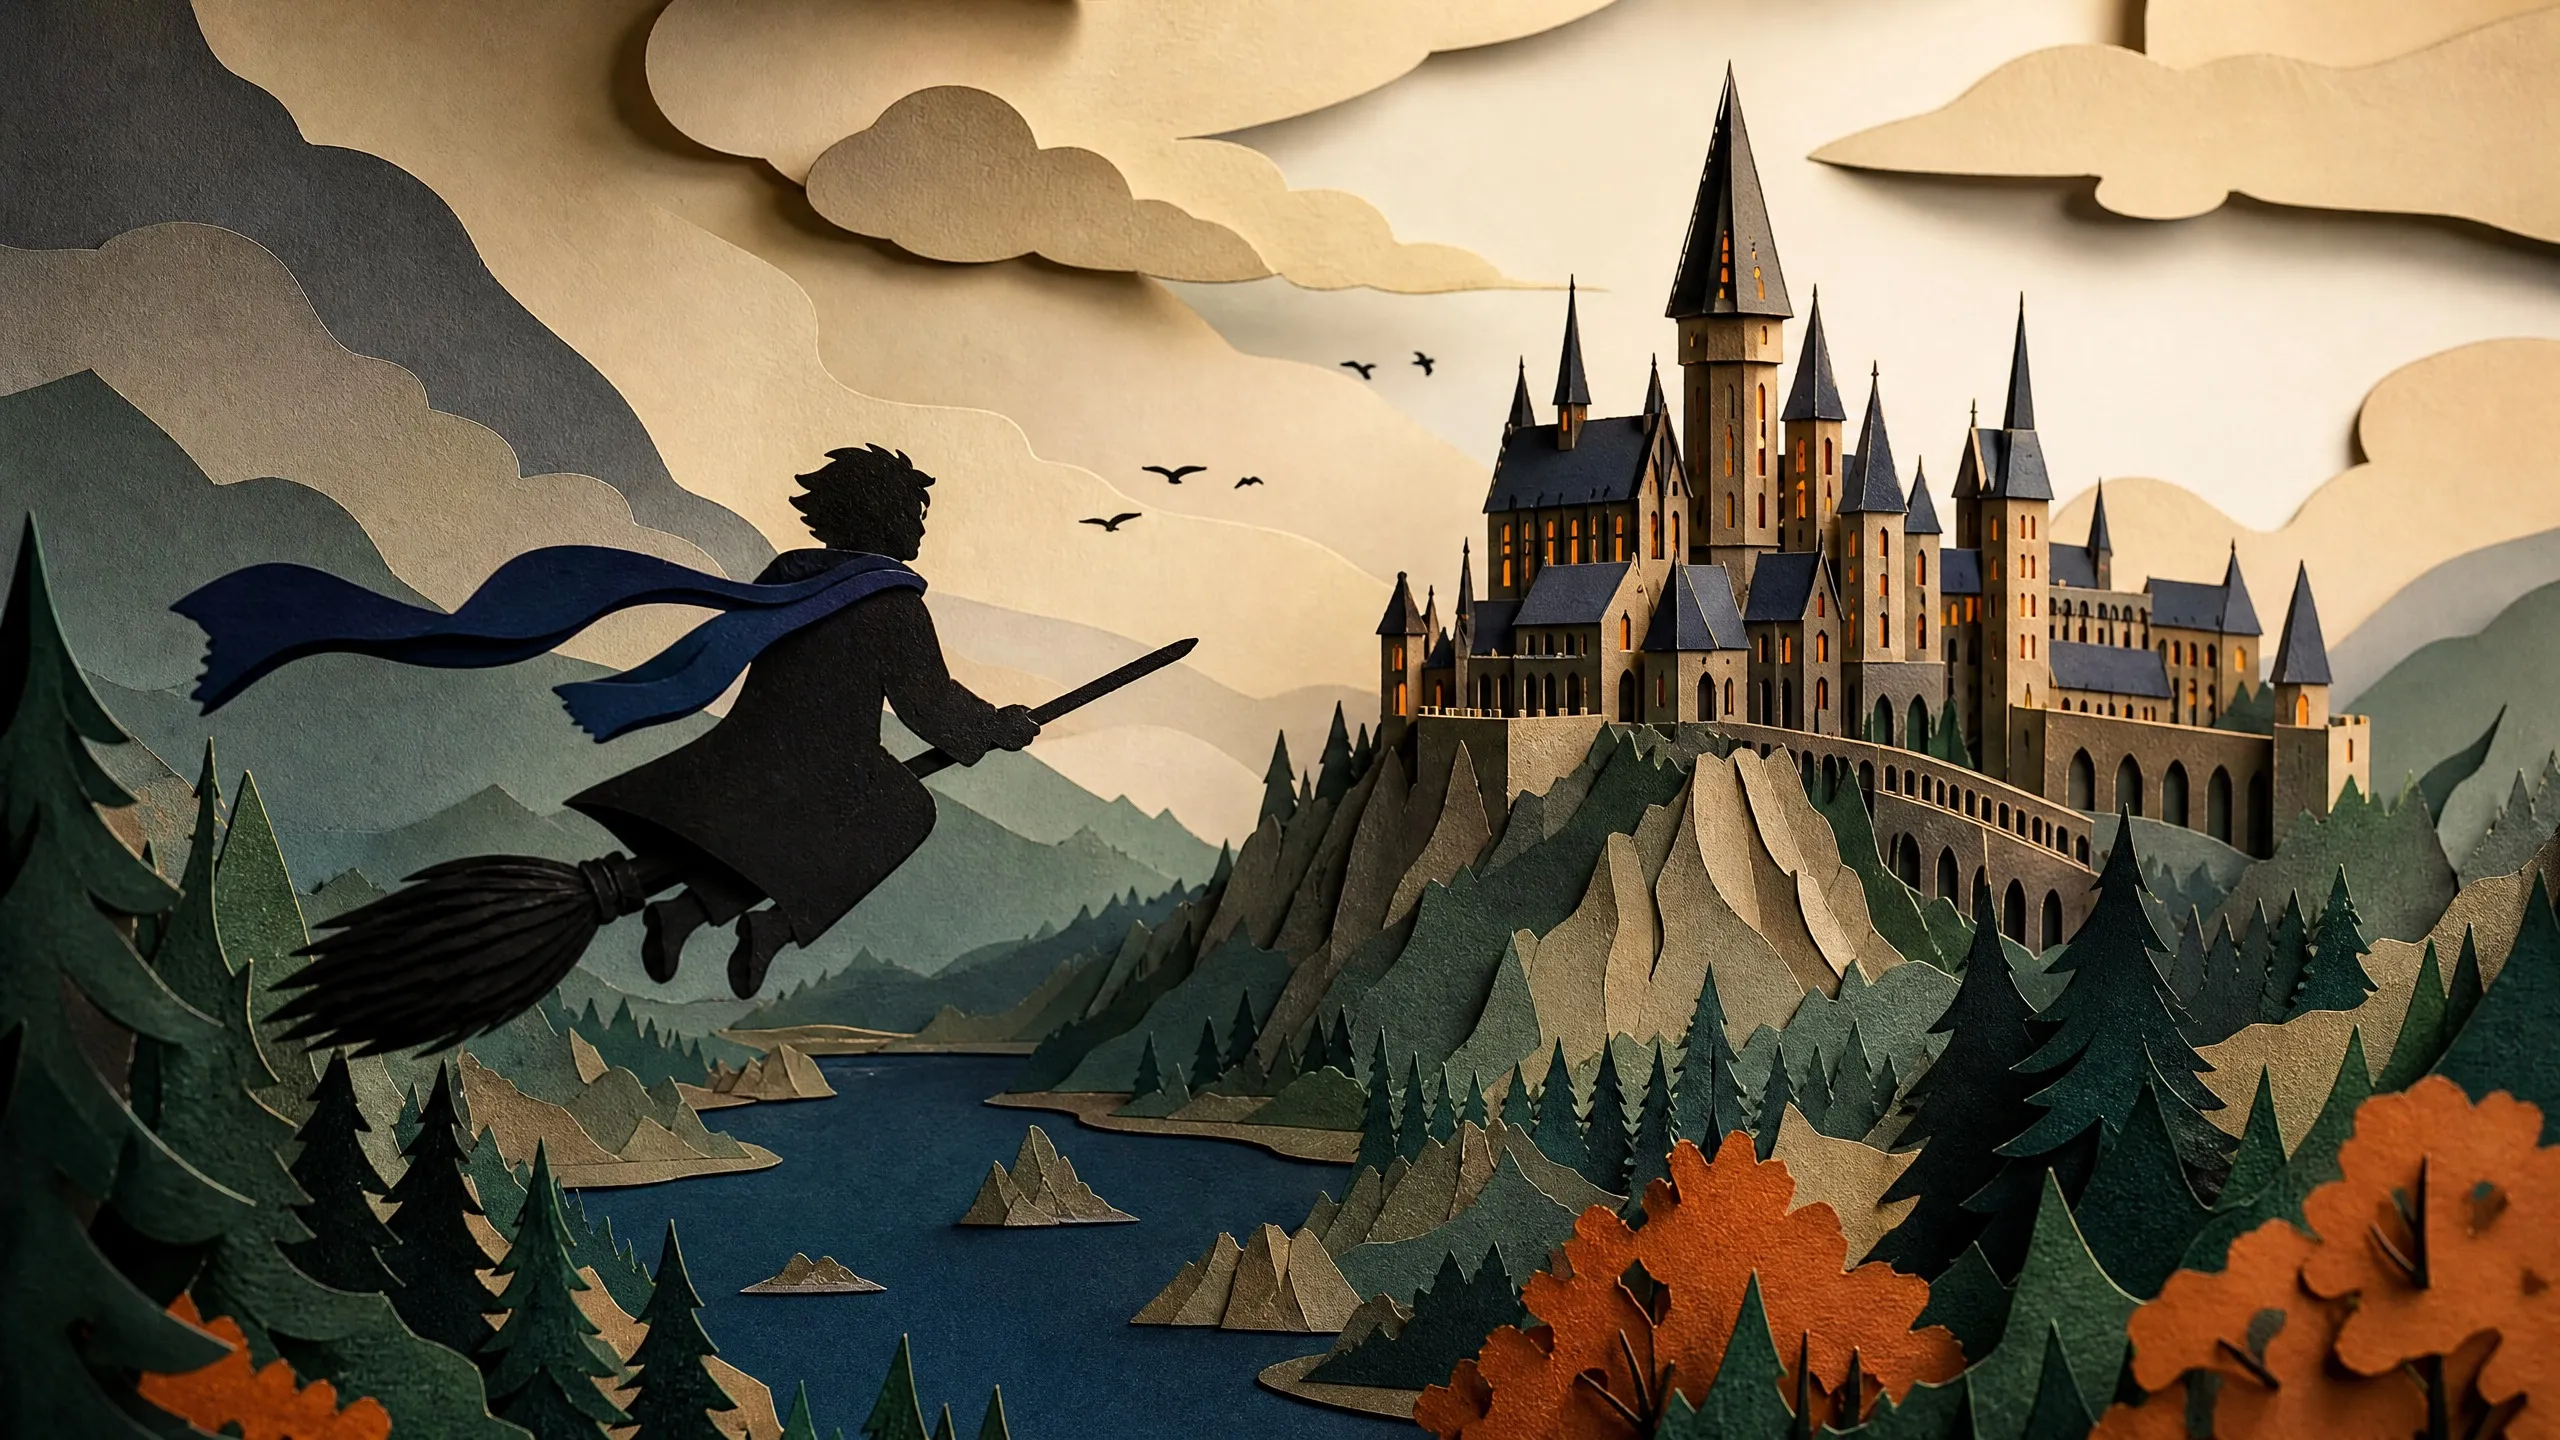
Hogwarts Broom Flight Simulator
Run date: 2026-07-21
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
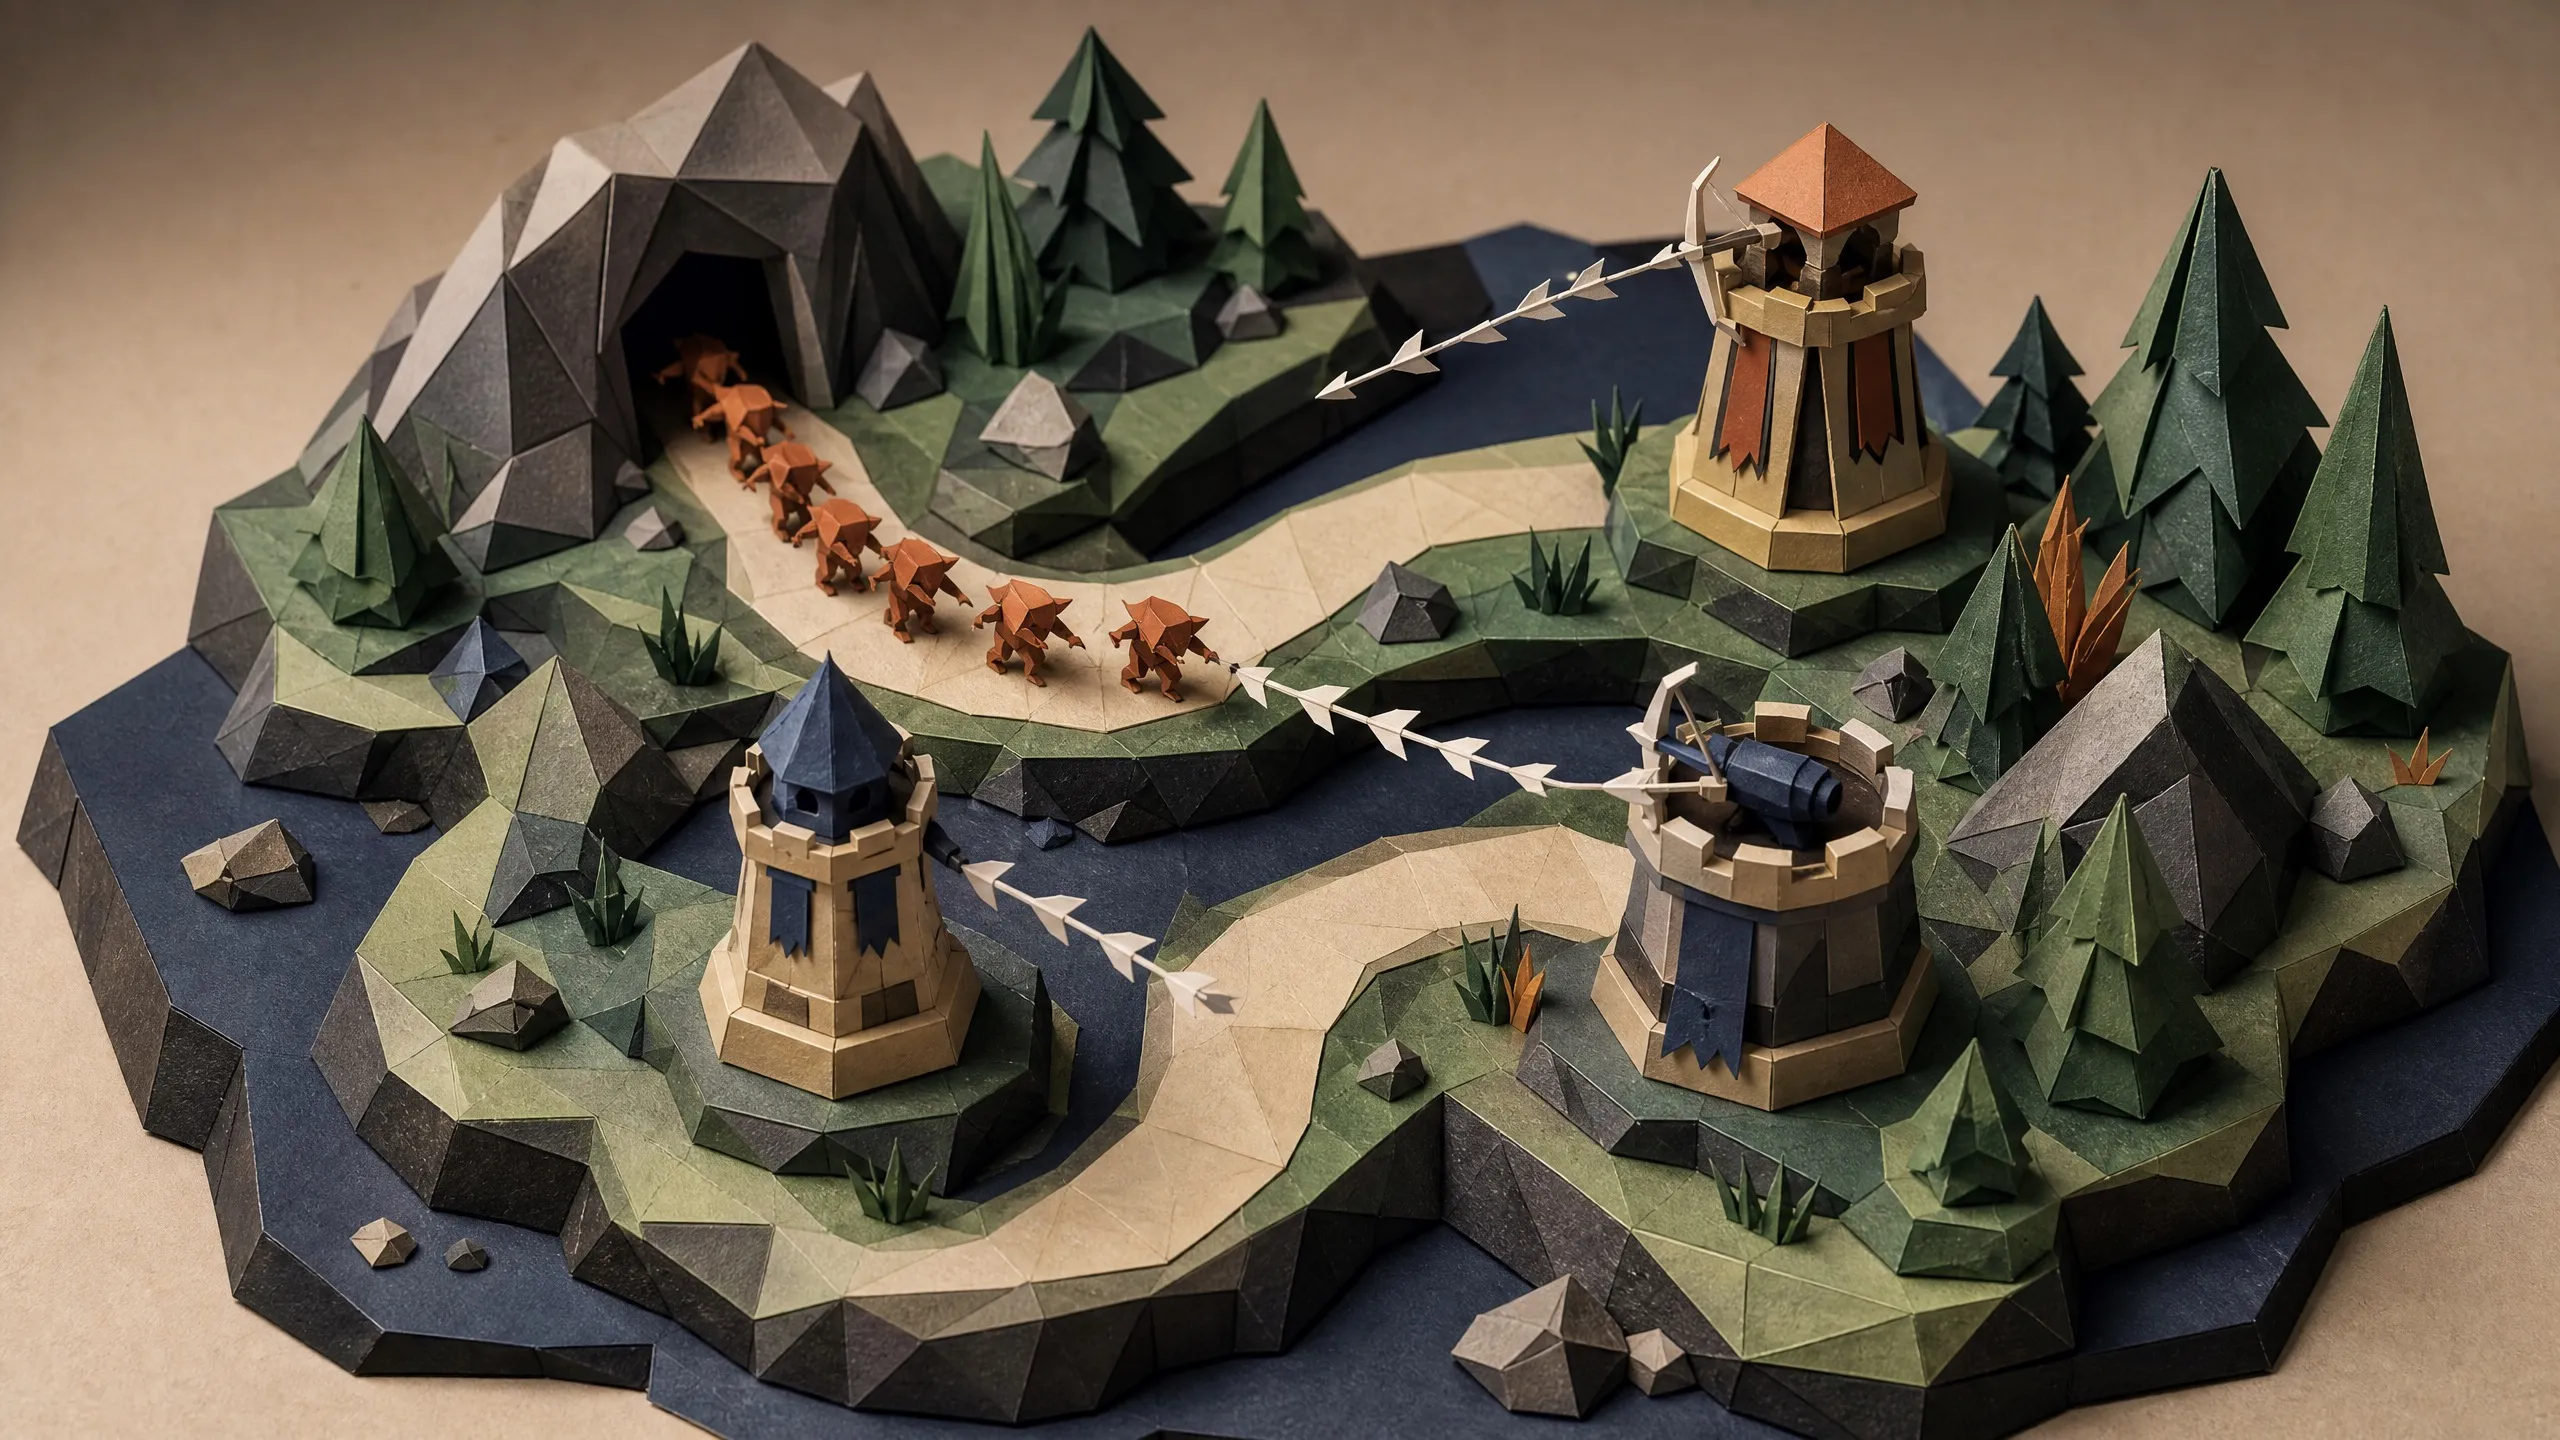
Low-Poly Tower Defense
Run date: 2026-09-02
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.
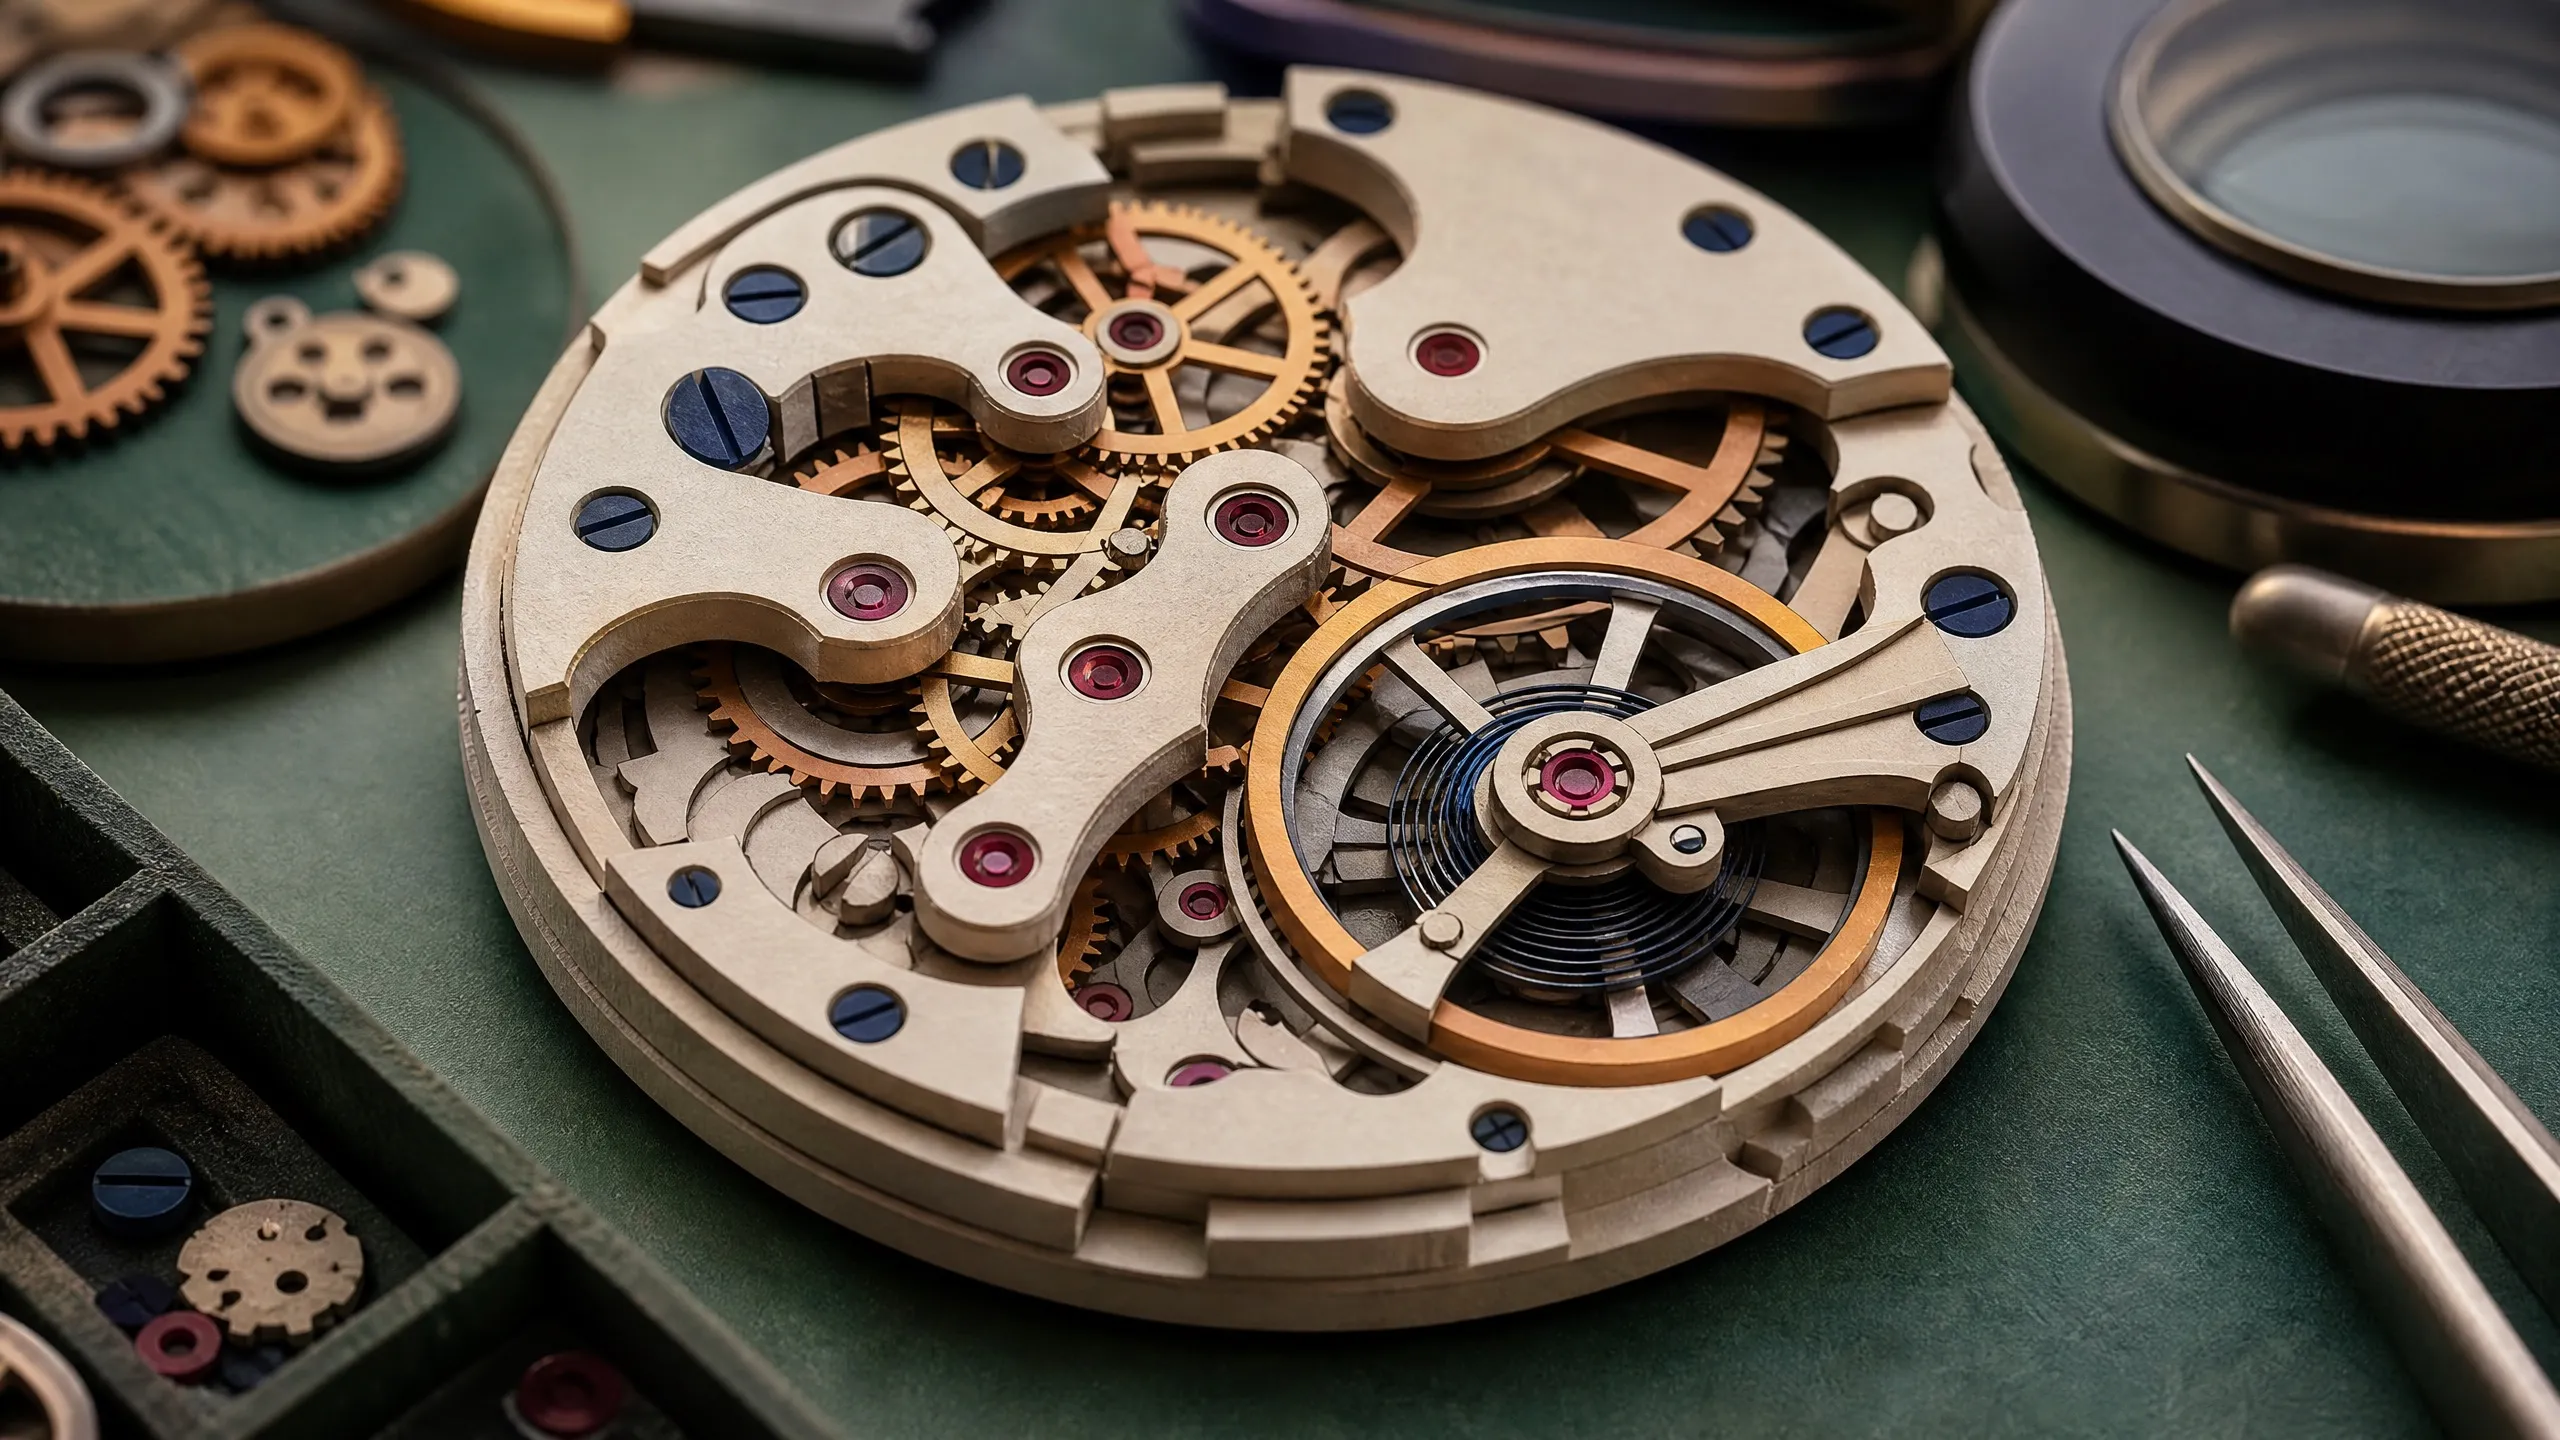
Mechanical Watch Simulator
Run date: 2026-09-02
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.
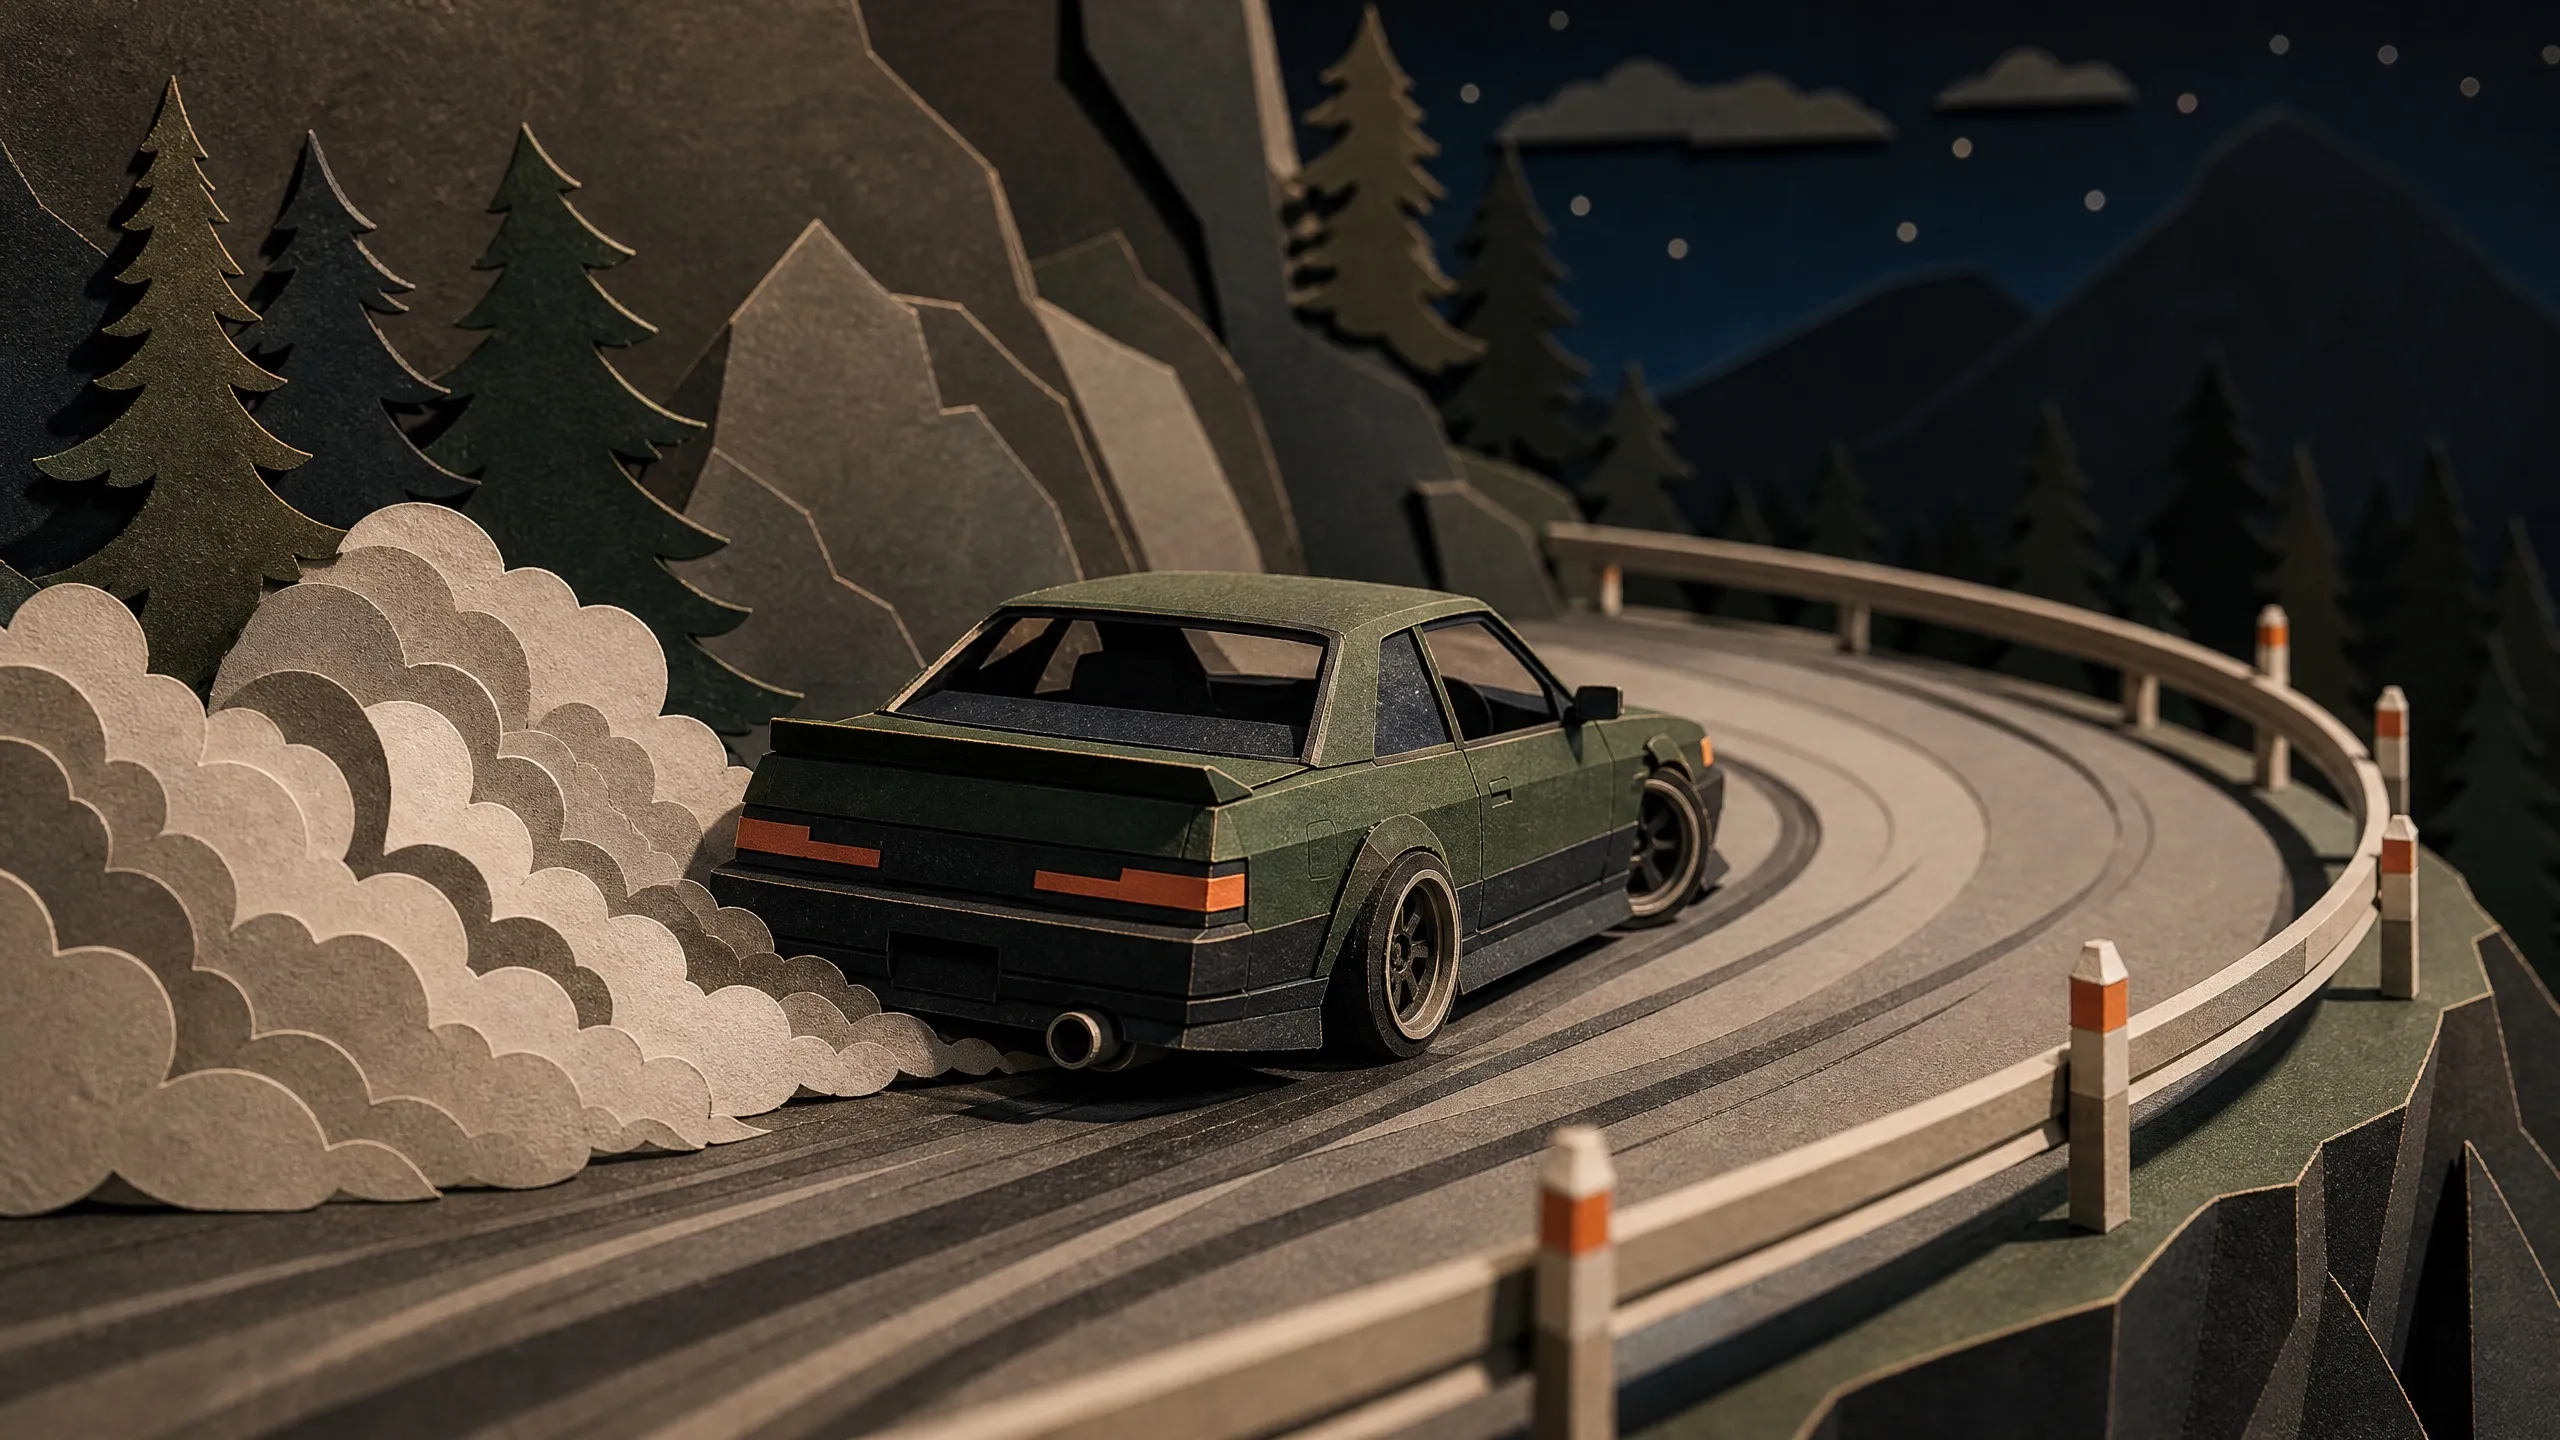
Neon Drift
Run date: 2026-09-02
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Starfall Arena
Run date: 2026-09-02
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
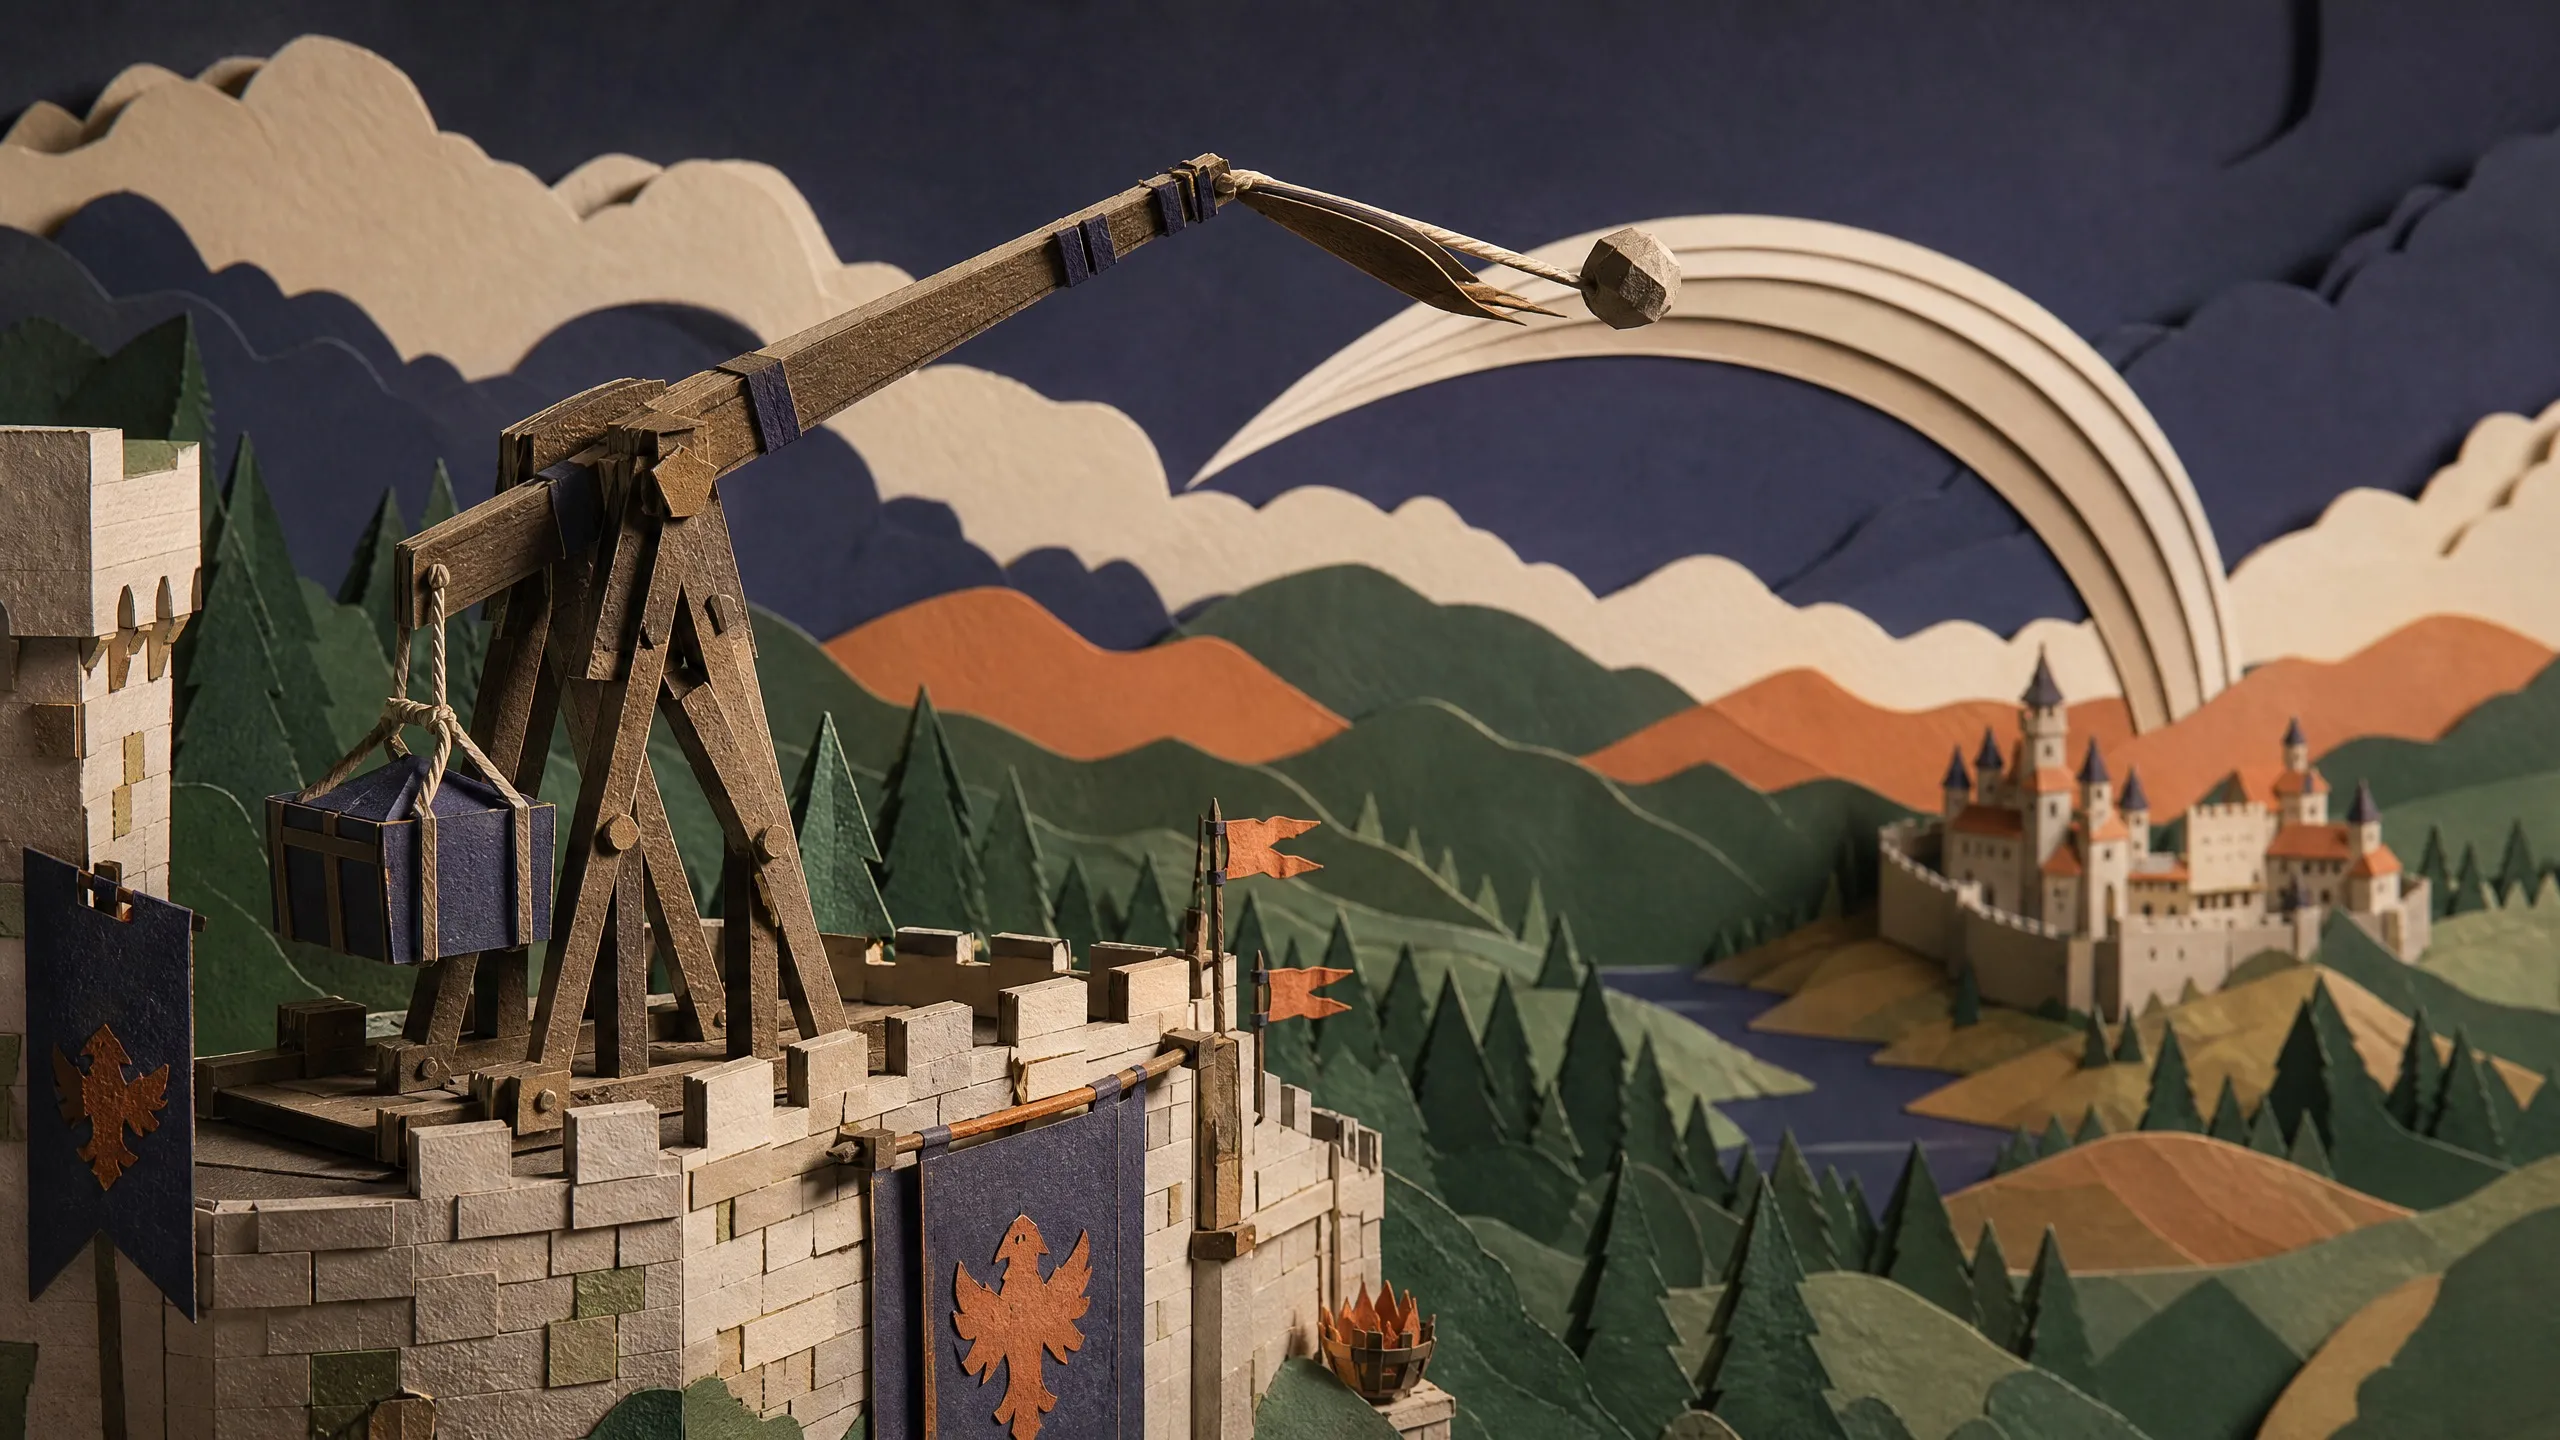
Stormwind Trebuchet Simulator
Run date: 2026-09-02
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
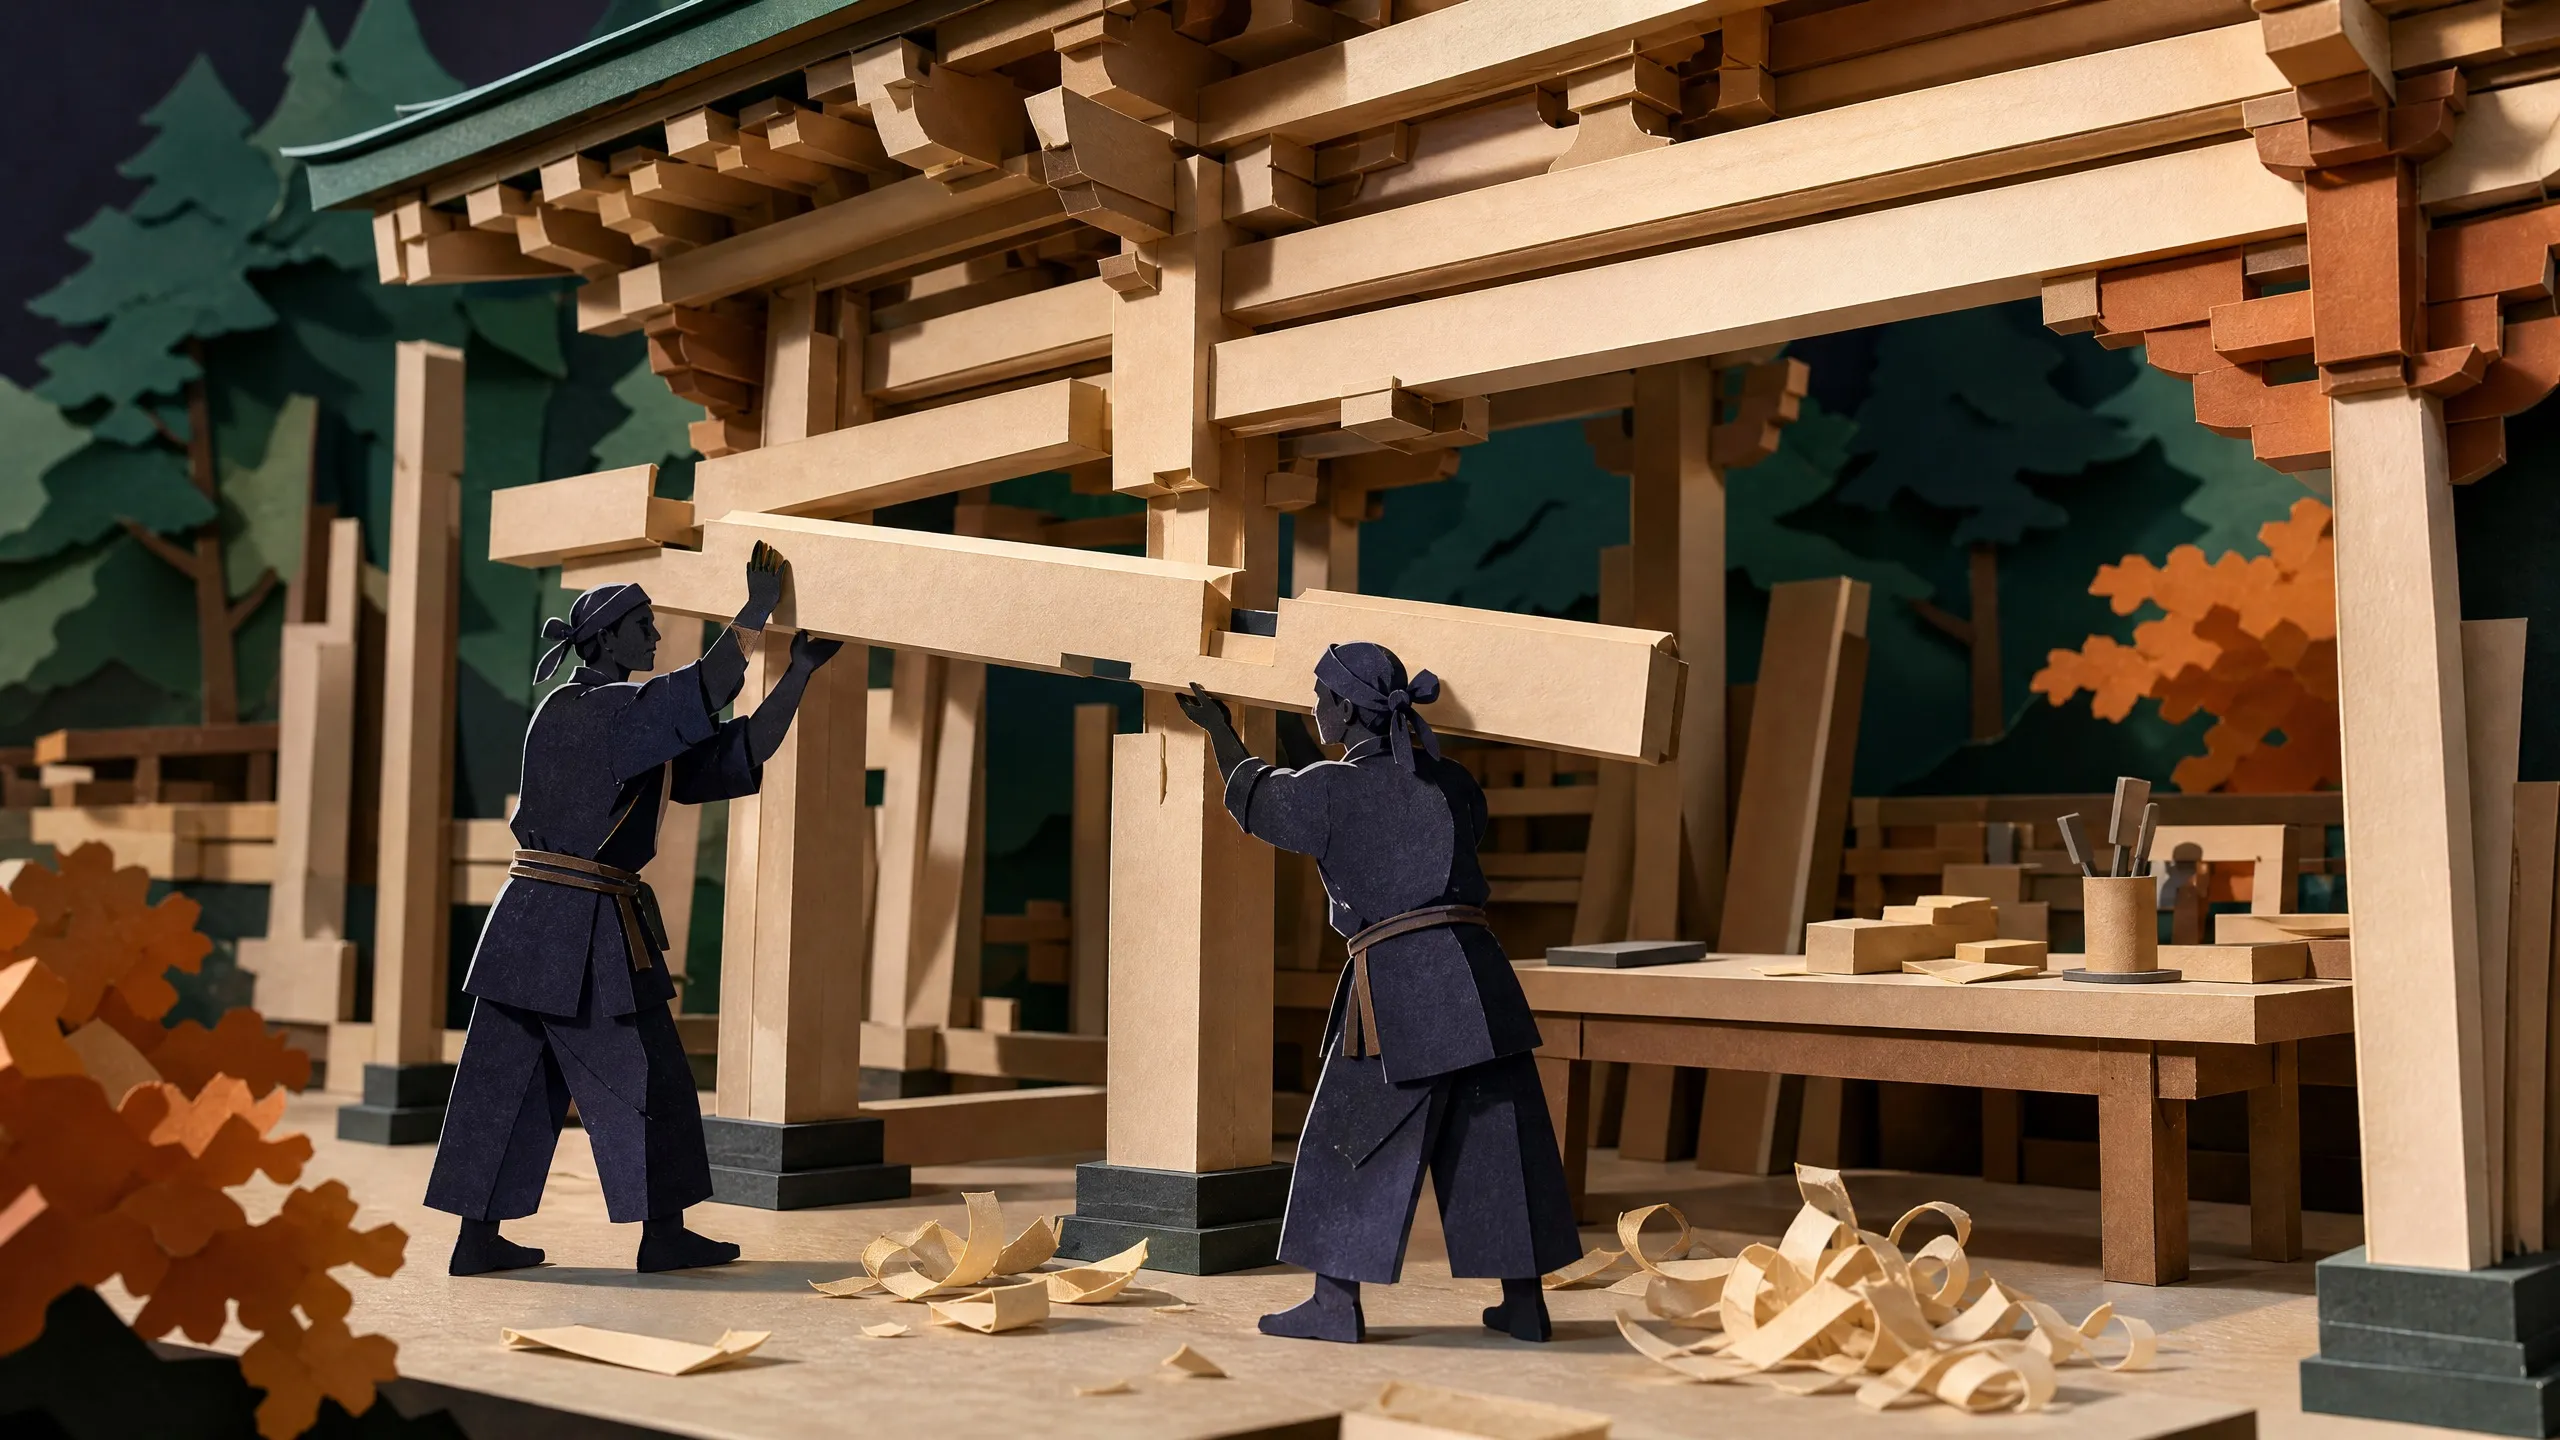
Yingzao Fashi Assembly
Run date: 2026-07-21
Specialist test · evaluated separately
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How Claude Fable 5 compares
Three relevant peers, side by side.
- Claude Fable 5 This model
- Claude Fable 5.1
- GPT-6 Astra
- Claude Opus 5
6 benchmarks · 4 models
Official benchmark profile
Published scores outside our visual tests
SWE-bench Pro
80.0%SWE-bench Verified
95.0%Terminal-Bench 2.1
84.3%Full official benchmark table14 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| SWE-bench Pro | Coding | 80.0% | |
| SWE-bench Verified | Coding | 95.0% | |
| Terminal-Bench 2.1 | Agentic coding | 84.3% | |
| FrontierCode Diamond | Agentic coding | 29.3% score / 30.2% pass | |
| FrontierCode Main | Agentic coding | 46.3% score / 48.8% pass | |
| CursorBench | Agentic coding | 72.9% | |
| GPQA Diamond | Academic reasoning | 92.6% | |
| FrontierMath Tier 1-3 v2 | Math | 87.0% | |
| FrontierMath Tier 4 v2 | Math | 87.8% | |
| OSWorld-Verified | Computer use | 85.0% | |
| Blueprint-Bench 2 | Spatial reasoning | 38.6% | |
| OfficeQA Pro | Document reasoning | 57.9% | |
| Finance Agent Benchmark v2 | Finance | 56.31% | |
| MCP Atlas | Office work | 83.3% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Superseded in this ranking
- API model ID
claude-fable-5- Context
- 1M
- Max output
- 128K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- Claude API Standard · USD / 1M tokens
- $10 input · $1 cached input · $12.5 cache write · $50 output
Cache write shown is the 5-minute rate; 1-hour cache writes cost $20 per 1M tokens. Standard global routing; Batch, Fast mode where available, and regional pricing differ.
Benchmark sources
Comparable numeric rows from the Anthropic system card and the shared GPT-5.6 comparison table. Marketing-only claims such as ViBench and spreadsheet speedups are excluded unless a score is published.
Claude Fable 5 & Claude Mythos 5 System CardEvaluation settings
- Average over 5 trials; standard configuration with thinking blocks included.
- Average over 5 trials on the 500-problem verified subset.
- Anthropic mini-SWE-agent harness at high effort; OpenAI’s shared table reports Fable at 83.1%.
- Mean@5 at xhigh reasoning effort on Cognition’s Diamond subset.
- Mean@5 at xhigh reasoning effort on Cognition’s Main subset.
- Cursor production agent harness at maximum effort.
- Shared GPT-5.6 comparison table.
- Pass@1 averaged over 5 runs on 361 tasks with 100 action steps.
- Andon Labs standard harness; normalized composite floor-plan score.
- Databricks image-based OfficeQA Pro evaluation.
- Vals AI evaluation with adaptive thinking and max effort.
- Pass rate on real-world MCP tool-use workflows.
Comparison methodology
Maximum reported score at any effort; research/API environments. A shared table does not guarantee identical harnesses, budgets, or safeguards. Gaps describe reported scores, not statistical significance. Percentage bars run from 0 to 100; index bars use a 0–100 display scale.
- Terminal-Bench Science 0.1
- Anthropic reports standard error of about 3.5–4.5 points per model; small gaps may be noise.
- Artificial Analysis Intelligence Index v4.1.1
- Independent index as reproduced in OpenAI’s launch table; separate from the older v4.1 observations in the cost explorer.
- FrontierCode 1.1 Extended (score)
- Astra uses additional developer guidance about keeping code and tests scoped (source footnote 8).
- FrontierCode 1.1 Main (score)
- Astra uses additional developer guidance about keeping code and tests scoped (source footnote 8).
- OSWorld 2.0 · offline, v2026.08.08
- Partial score on the offline subset. Anthropic’s modified tasks and grading are incompatible; no Fable 5.1 value is supplied here.
- ScreenSpot-Pro (no tools)
- The source labels Mythos’s 87.3 as Fable 5 (footnote 17). It is excluded from the Fable column here because the model’s safeguards differ.
- BenchCAD (with tools)
- Claude results use three evaluation modifications. Scores shown for context; no direct gap is calculated.
- HealthBench Professional (length-adjusted)
- OpenAI re-evaluation with GPT-5.4 grading. Fable 5.1 uses Opus 5 fallback for refusals; not a standalone Fable result.
- ExploitBench
- Astra and Sol evaluated without production safeguards.
- ExploitGym
- The source’s Fable columns are Mythos 5.1 (30.4) and Mythos 5 (28.4), excluded here. Astra/Sol have no six-hour limit and no production safeguards. Not a production-model comparison.
- ExploitBench (June–August 2026)
- OpenAI internal set, without production safeguards. Sol’s 5.5 is affected by a 300-turn cap; source also reports 11.5 with fewer limits.
- SRE-Bench (single attempt)
- Cyber capability evaluation without production safeguards.
- Computer-use safety (OpenAI internal)
- Lower is better. Research harness without production confirmations; provider safeguards and tools still differ.
- ARC-AGI-3
- OpenAI Responses harness with two modified settings; see source footnote 1.