
Anthropic
Claude Fable 5.1
Anthropic's current flagship with adaptive thinking, production safeguards, and the strongest Terminal-Bench 4.0 result published at launch.
Verified model facts
Identity, limits, and pricing
- Status
- Current
- API model ID
claude-fable-5-1- Context
- 1M
- Max output
- 128K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- text input, image input, text output
- Hardware
- Not publicly verified
- API price / 1M tokens
- $10 input · $0.25 cached input · $50 output
Same input and output prices as Fable 5. Cache reads dropped from $1 to $0.25 per 1M tokens. Adaptive thinking is always on; the effort parameter controls thinking depth.
Same-prompt visual tests
Inspect the actual runs
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
Helm's Deep
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
Hogwarts Broom Flight Simulator
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Jabberwock
Dark fantasy encounter testing creature design, forest mood, and narrative staging.

Low-Poly Tower Defense
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.

Low Poly World
Stylized island build testing composition, color, and low-poly worldbuilding.
Mechanical Watch Simulator
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Office Life
Workplace vignette testing everyday scene logic, objects, and believable office detail.

Petri Dish
Microscopic ecosystem testing organic forms, scientific clarity, and cellular detail.

Starfall Arena
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
Stormwind Trebuchet Simulator
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.

Universe Simulator
Cosmic system testing orbital structure, glowing bodies, scale, and simulation readability.

Vice City
Neon coastal city testing vehicles, architecture, atmosphere, and dense urban layout.
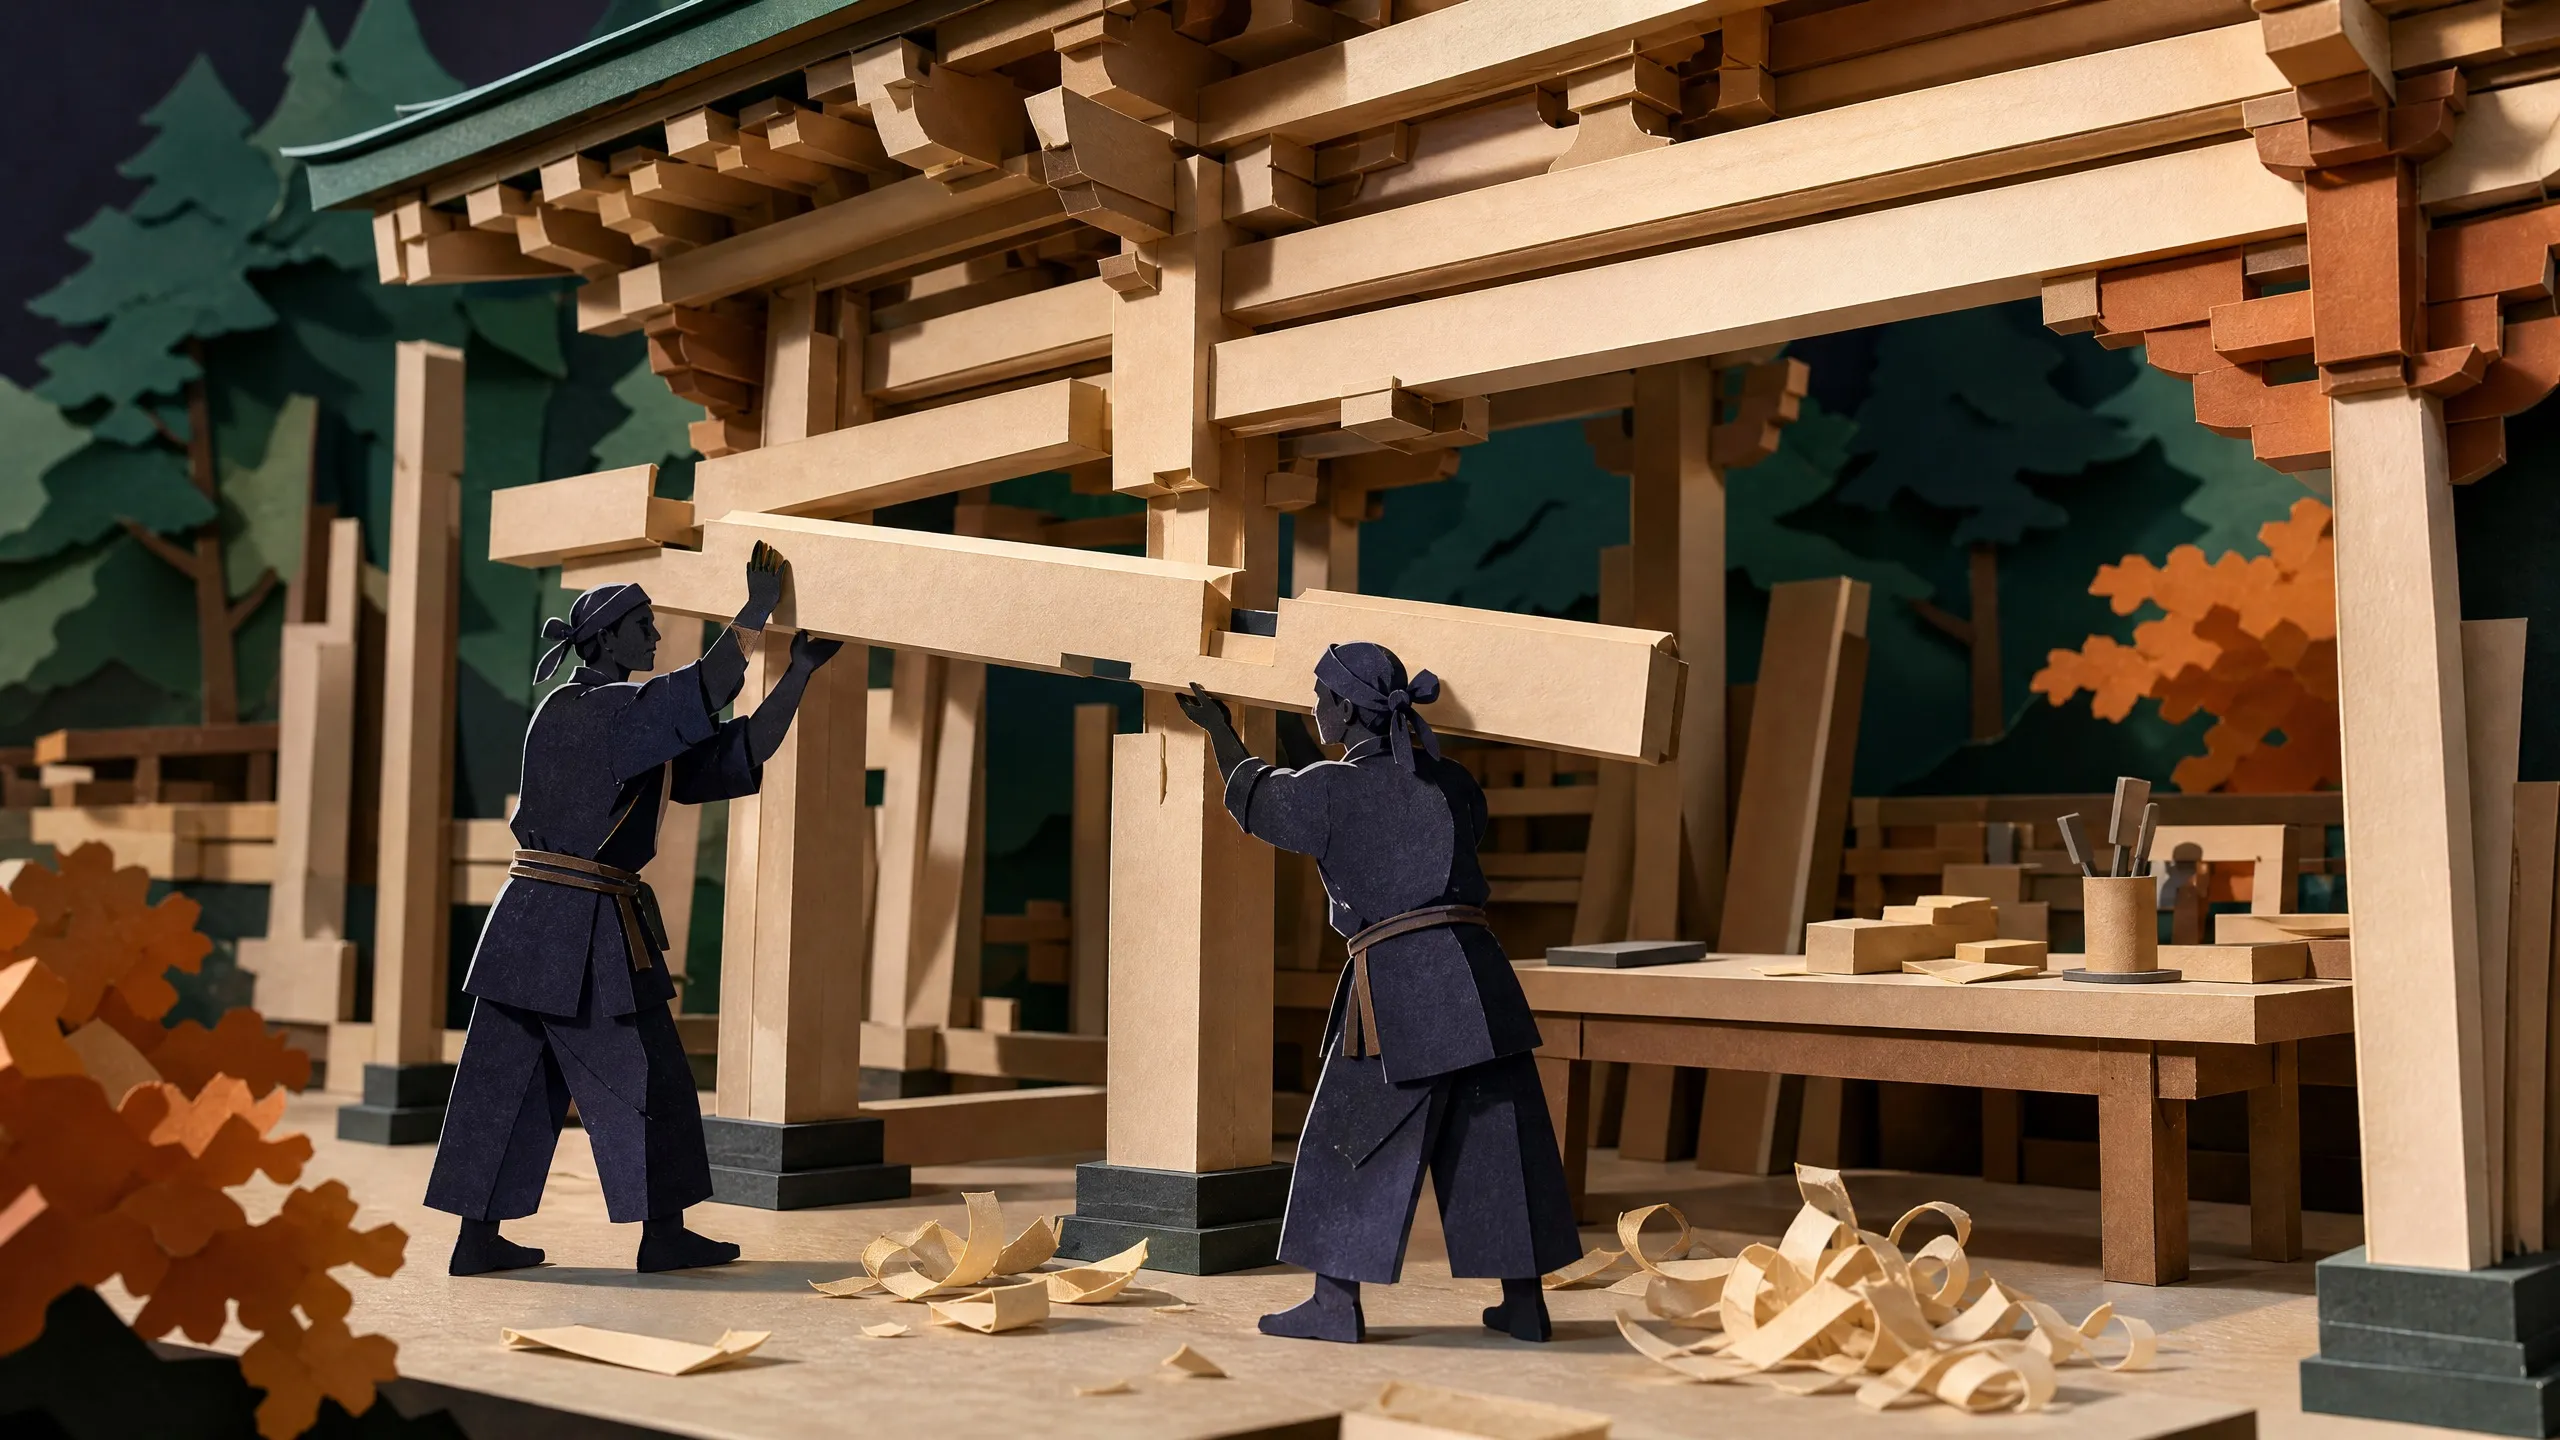
Yingzao Fashi Assembly
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Official benchmark profile
Claude Fable 5.1 launch results for agentic coding, research, and automation.
Anthropic released Claude Fable 5.1 on September 1, 2026 as the successor to Fable 5 at the same $10 / $50 per 1M token prices with cache reads cut to $0.25. The launch chart reports gains over Fable 5 and Opus 5 on terminal-based coding, scientific research, and multi-step automation.
Terminal-Bench-Science 0.1
52.6%Terminal-Bench 4.0
55.8%CursorBench 3.2.0
73.4%Full official benchmark table4 rows with source settings and peer charts
| Benchmark | Area | Score | Setting / comparison |
|---|---|---|---|
| Terminal-Bench-Science 0.1 | Agentic research | 52.6% | Anthropic launch chart; standard error about 3.5 to 4.5 points per model. Anthropic reproduces Opus 5 at 29.0% and Fable 5 at 24.7% in its own setup. |
| Terminal-Bench 4.0 | Agentic coding | 55.8% | Anthropic launch chart. Mythos 5.1, the same model without production safeguards, scores 60.9%. |
| CursorBench 3.2.0 | Agentic coding | 73.4% | Anthropic launch chart; Cursor production agent harness. |
| AutomationBench | Multi-step automation | 31.4% | Anthropic launch chart. Safeguard interventions score zero, which Anthropic says lowers Fable 5 in particular. |
Editorial verdict
Where this model fits
Fable 5.1 replaced Fable 5 on September 1, 2026 as Anthropic's top model. It ships with the same $10 / $50 per 1M token pricing but cuts cache reads to $0.25 and enables adaptive thinking by default. The launch chart reports 55.8% on Terminal-Bench 4.0 and 73.4% on CursorBench 3.2.0 with production safeguards enabled.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: Claude Fable 5.1 is currently placed in Tier S.
The August 2026 editorial roster places Claude Fable 5.1 at rank 1.
Open source →Related guides