
DeepSeek
DeepSeek V4 Pro
The A-tier value flagship, pending more direct testing of the new Pro release.
API pricing
USD per million tokens · DeepSeek API peak rate- Input
- $1.32
- Output
- $3.96
- Cached input
- $0.044
- Context window
- 1M
Try the visual runs
Open the generated scene to test it, or compare that prompt with another model.

City Scroll Journey
Cinematic scroll journey testing AI-generated scene continuity, scroll-scrubbed camera motion, and art-directed landing craft.

Ember Glider
Sunset gliding journey testing flight energy management, checkpoint flow, and atmospheric scene craft.
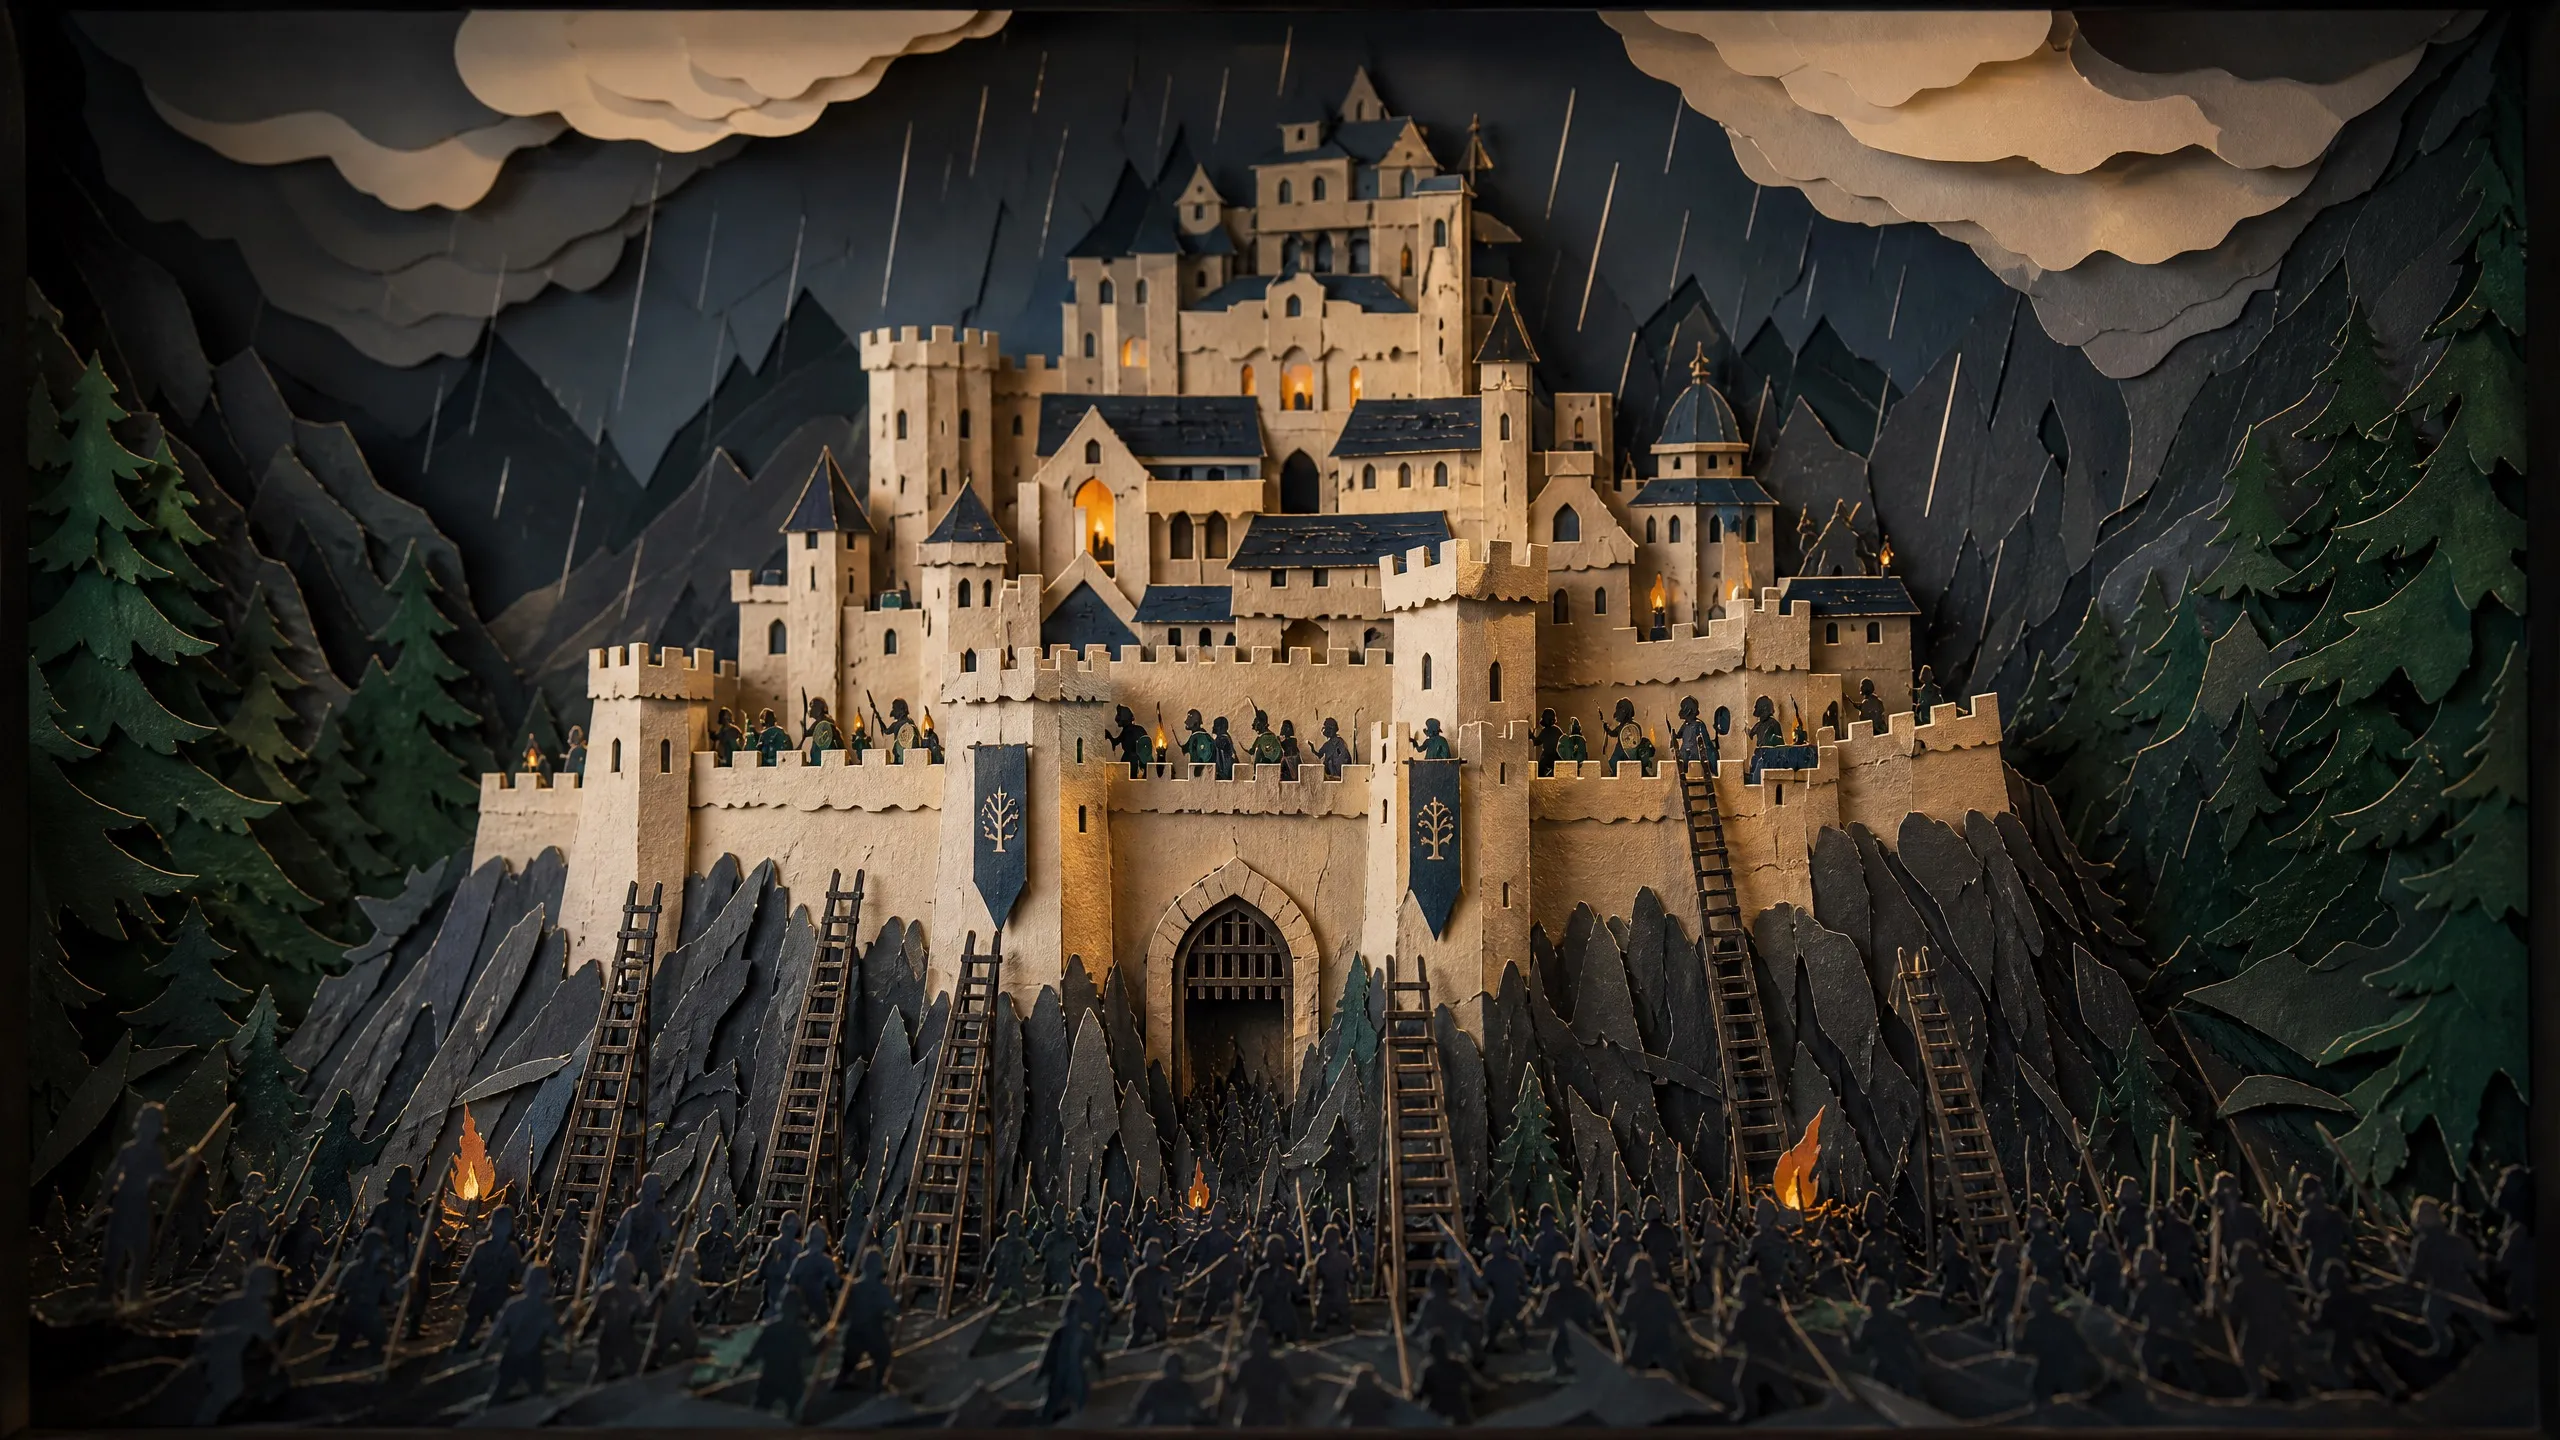
Helm's Deep
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
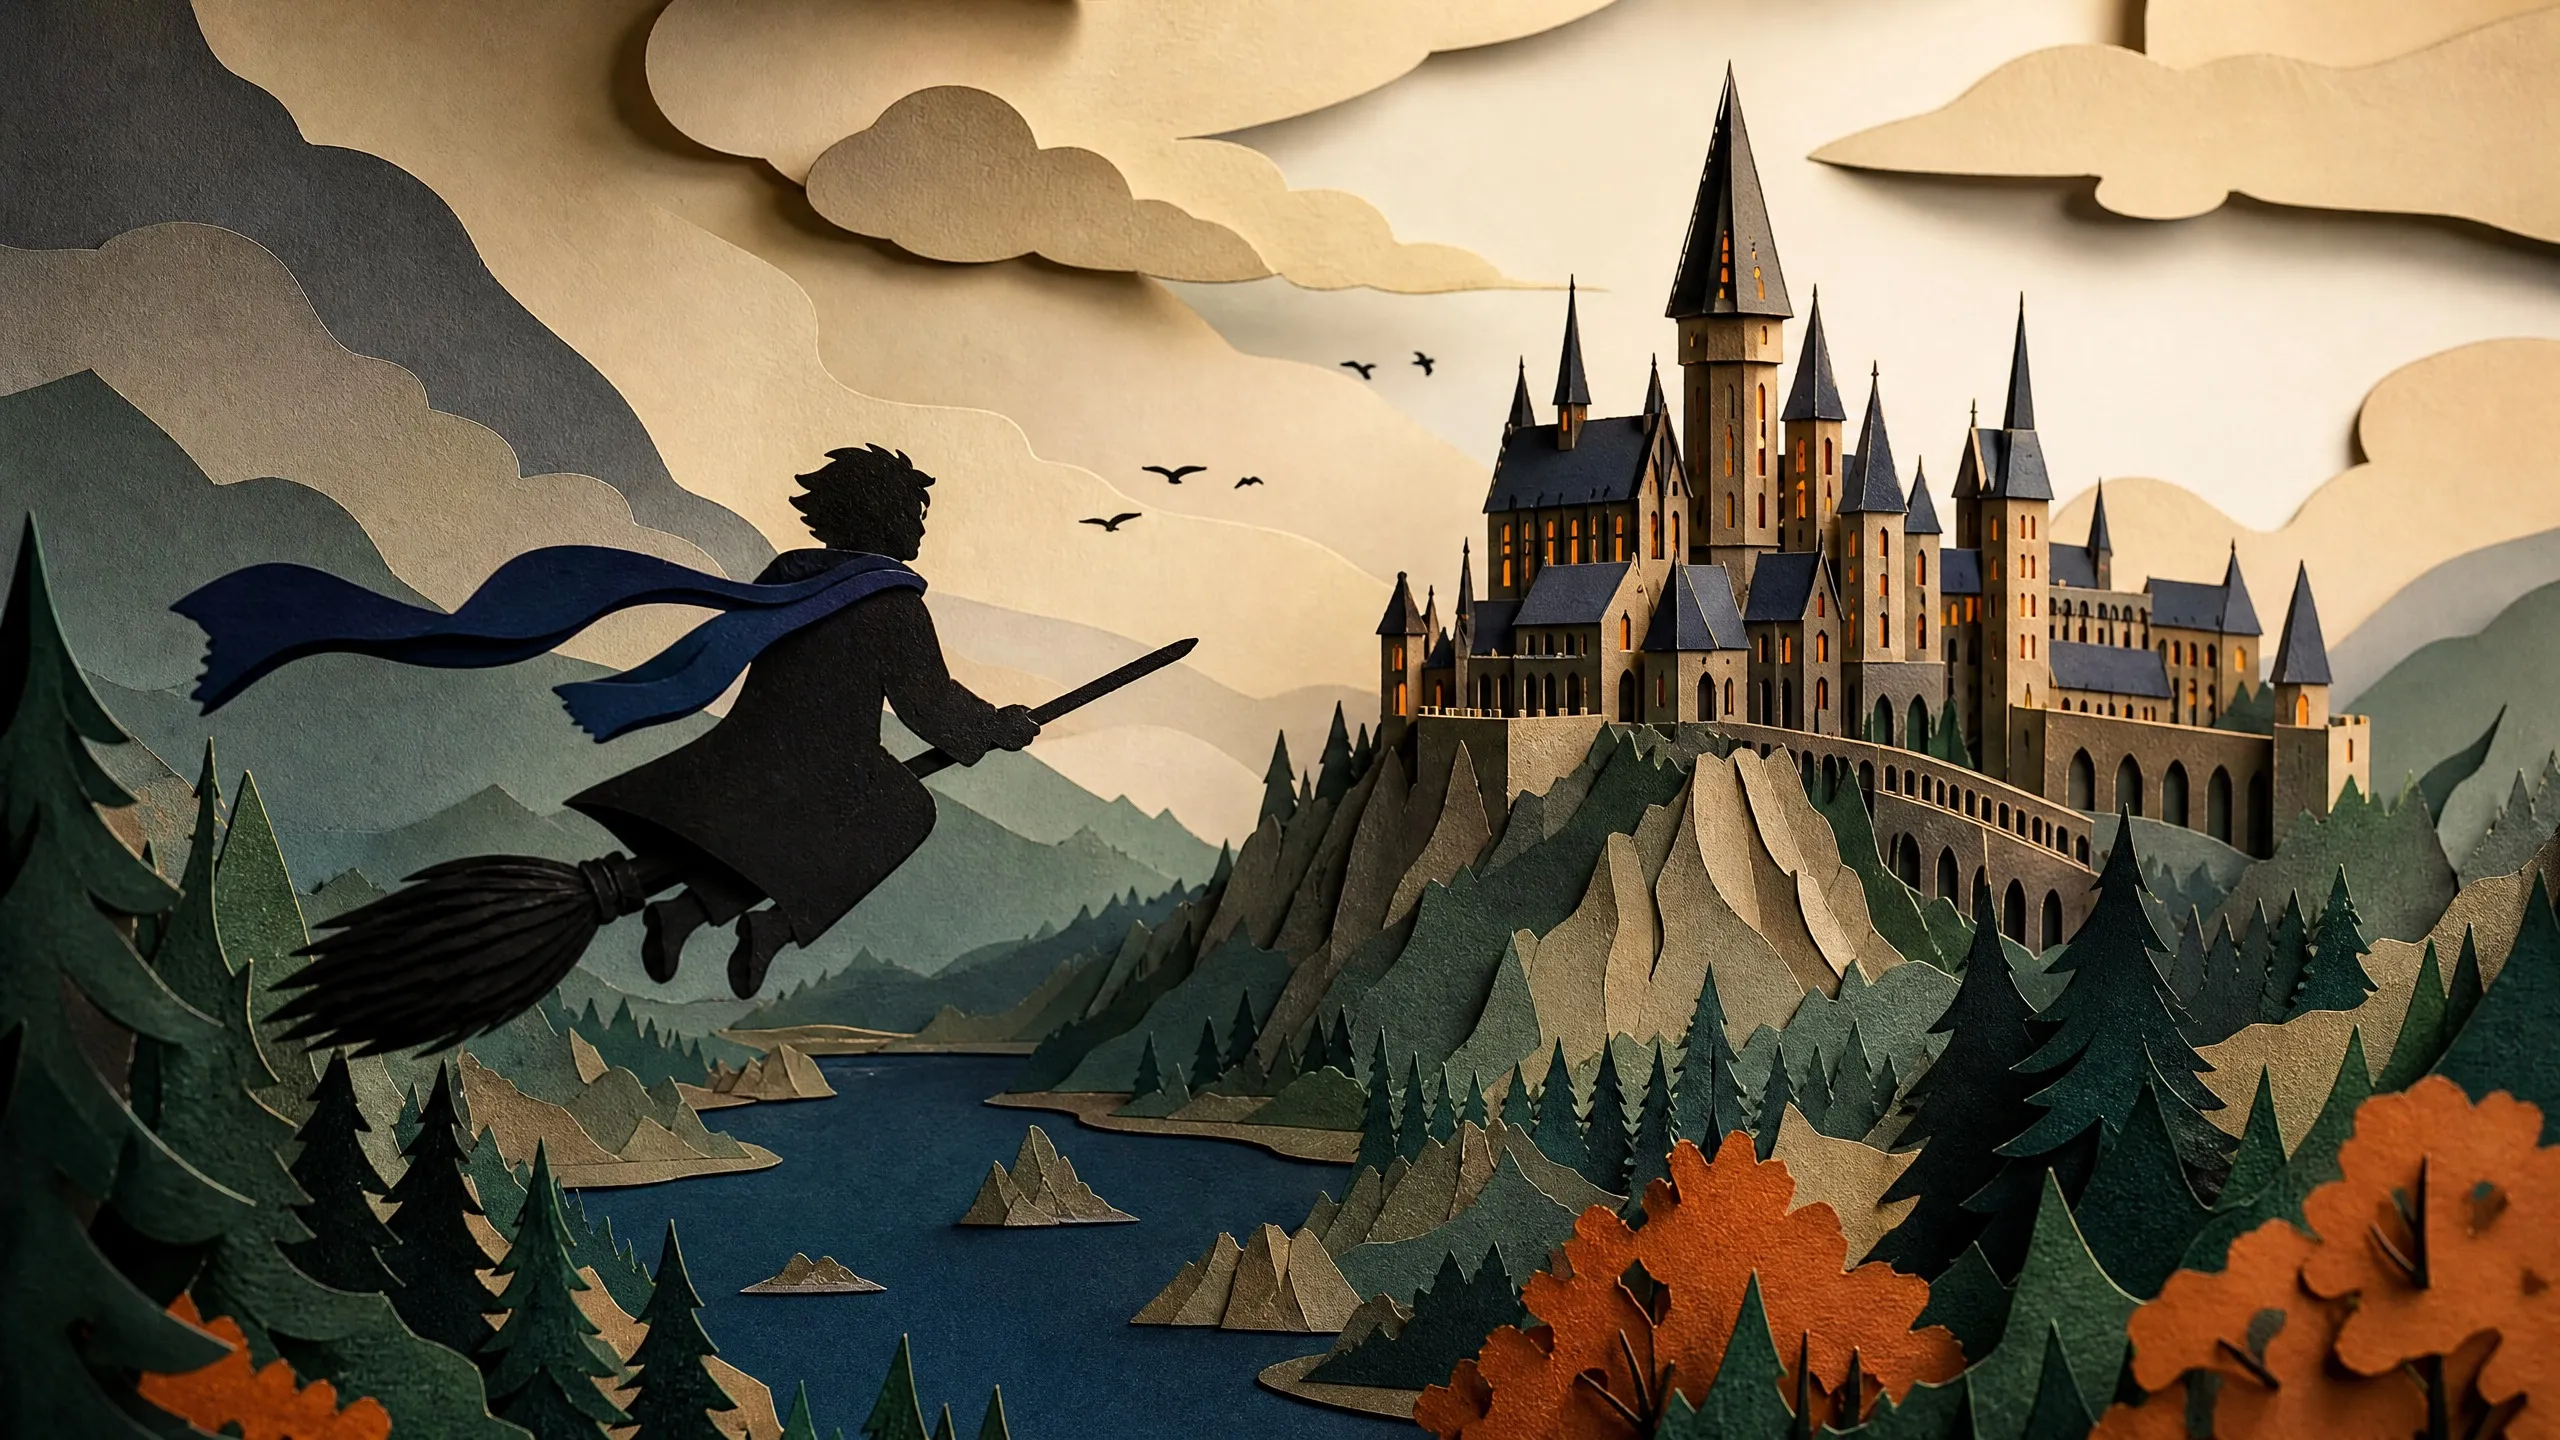
Hogwarts Broom Flight Simulator
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.

Jabberwock
Dark fantasy encounter testing creature design, forest mood, and narrative staging.

Low-Poly Tower Defense
Diorama tower defense testing economy balance, wave design, placement rules, and combat readability.

Low Poly World
Stylized island build testing composition, color, and low-poly worldbuilding.
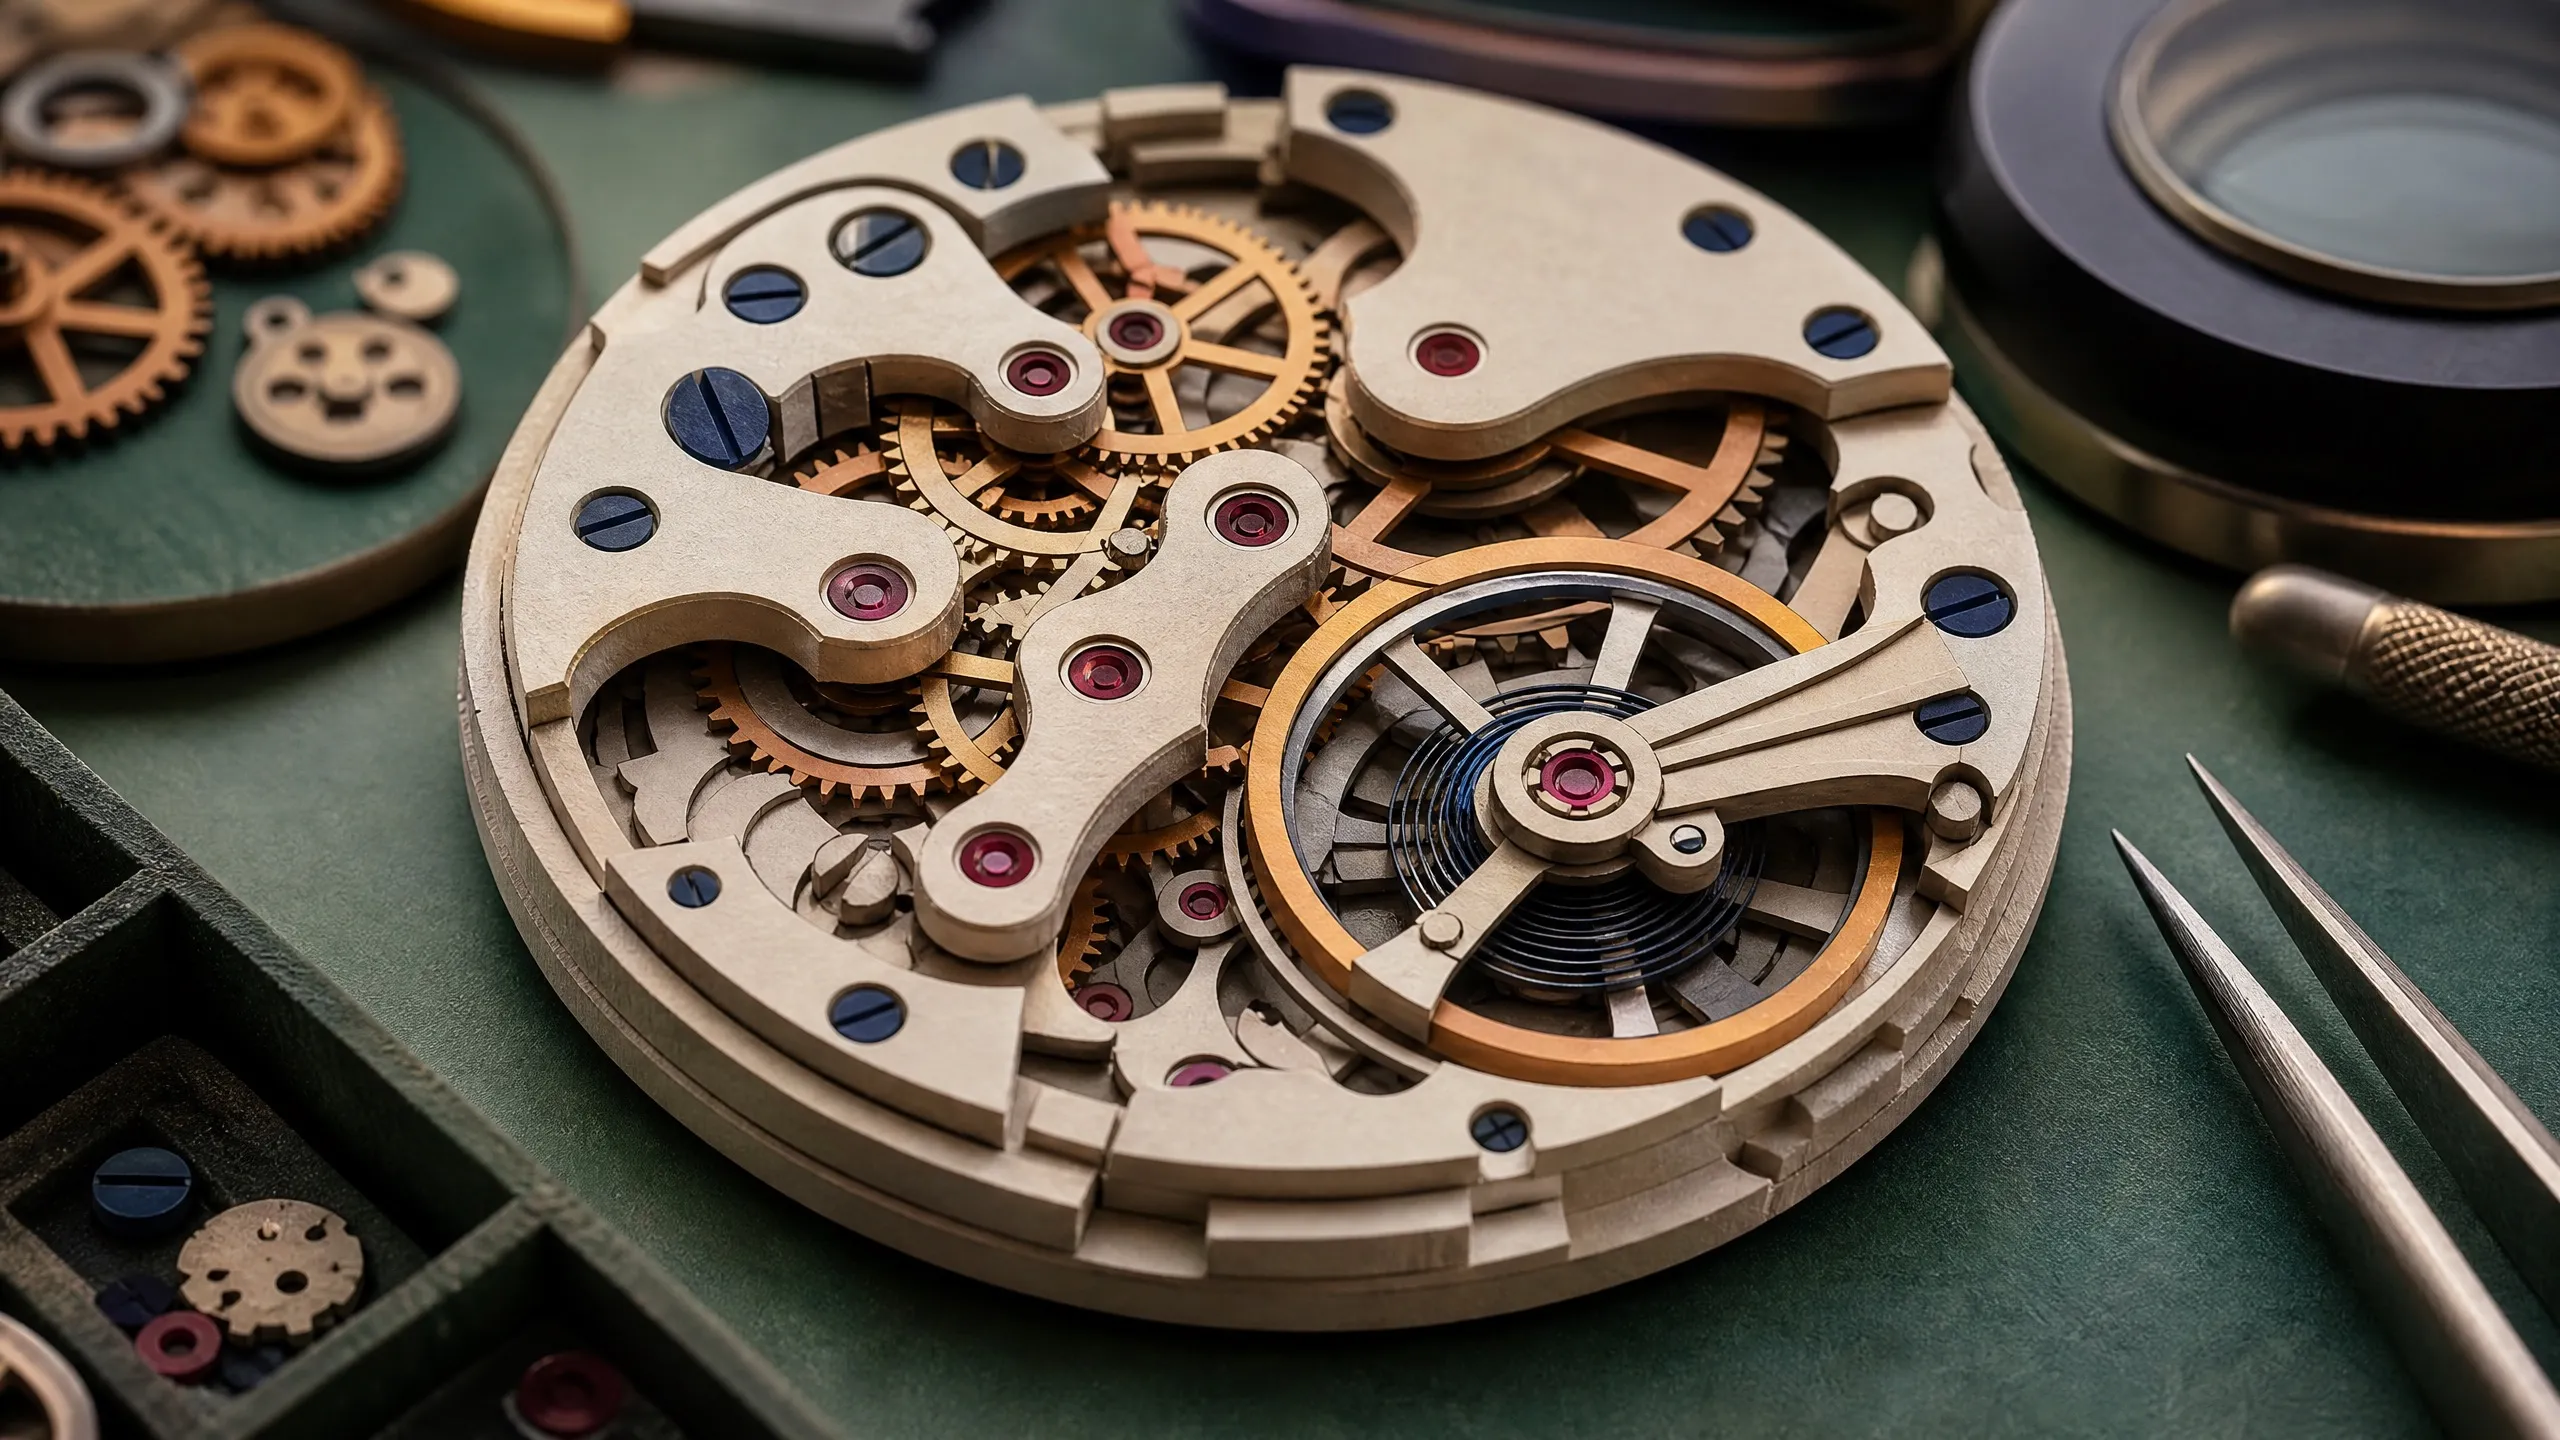
Mechanical Watch Simulator
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.

Neon Drift
Synthwave time-trial racing testing drift physics, lap timing, ghost replay, and unlock progression.

Office Life
Workplace vignette testing everyday scene logic, objects, and believable office detail.

Petri Dish
Microscopic ecosystem testing organic forms, scientific clarity, and cellular detail.

Starfall Arena
Neon arena survival testing wave escalation, upgrade builds, particle feedback, and boss design.
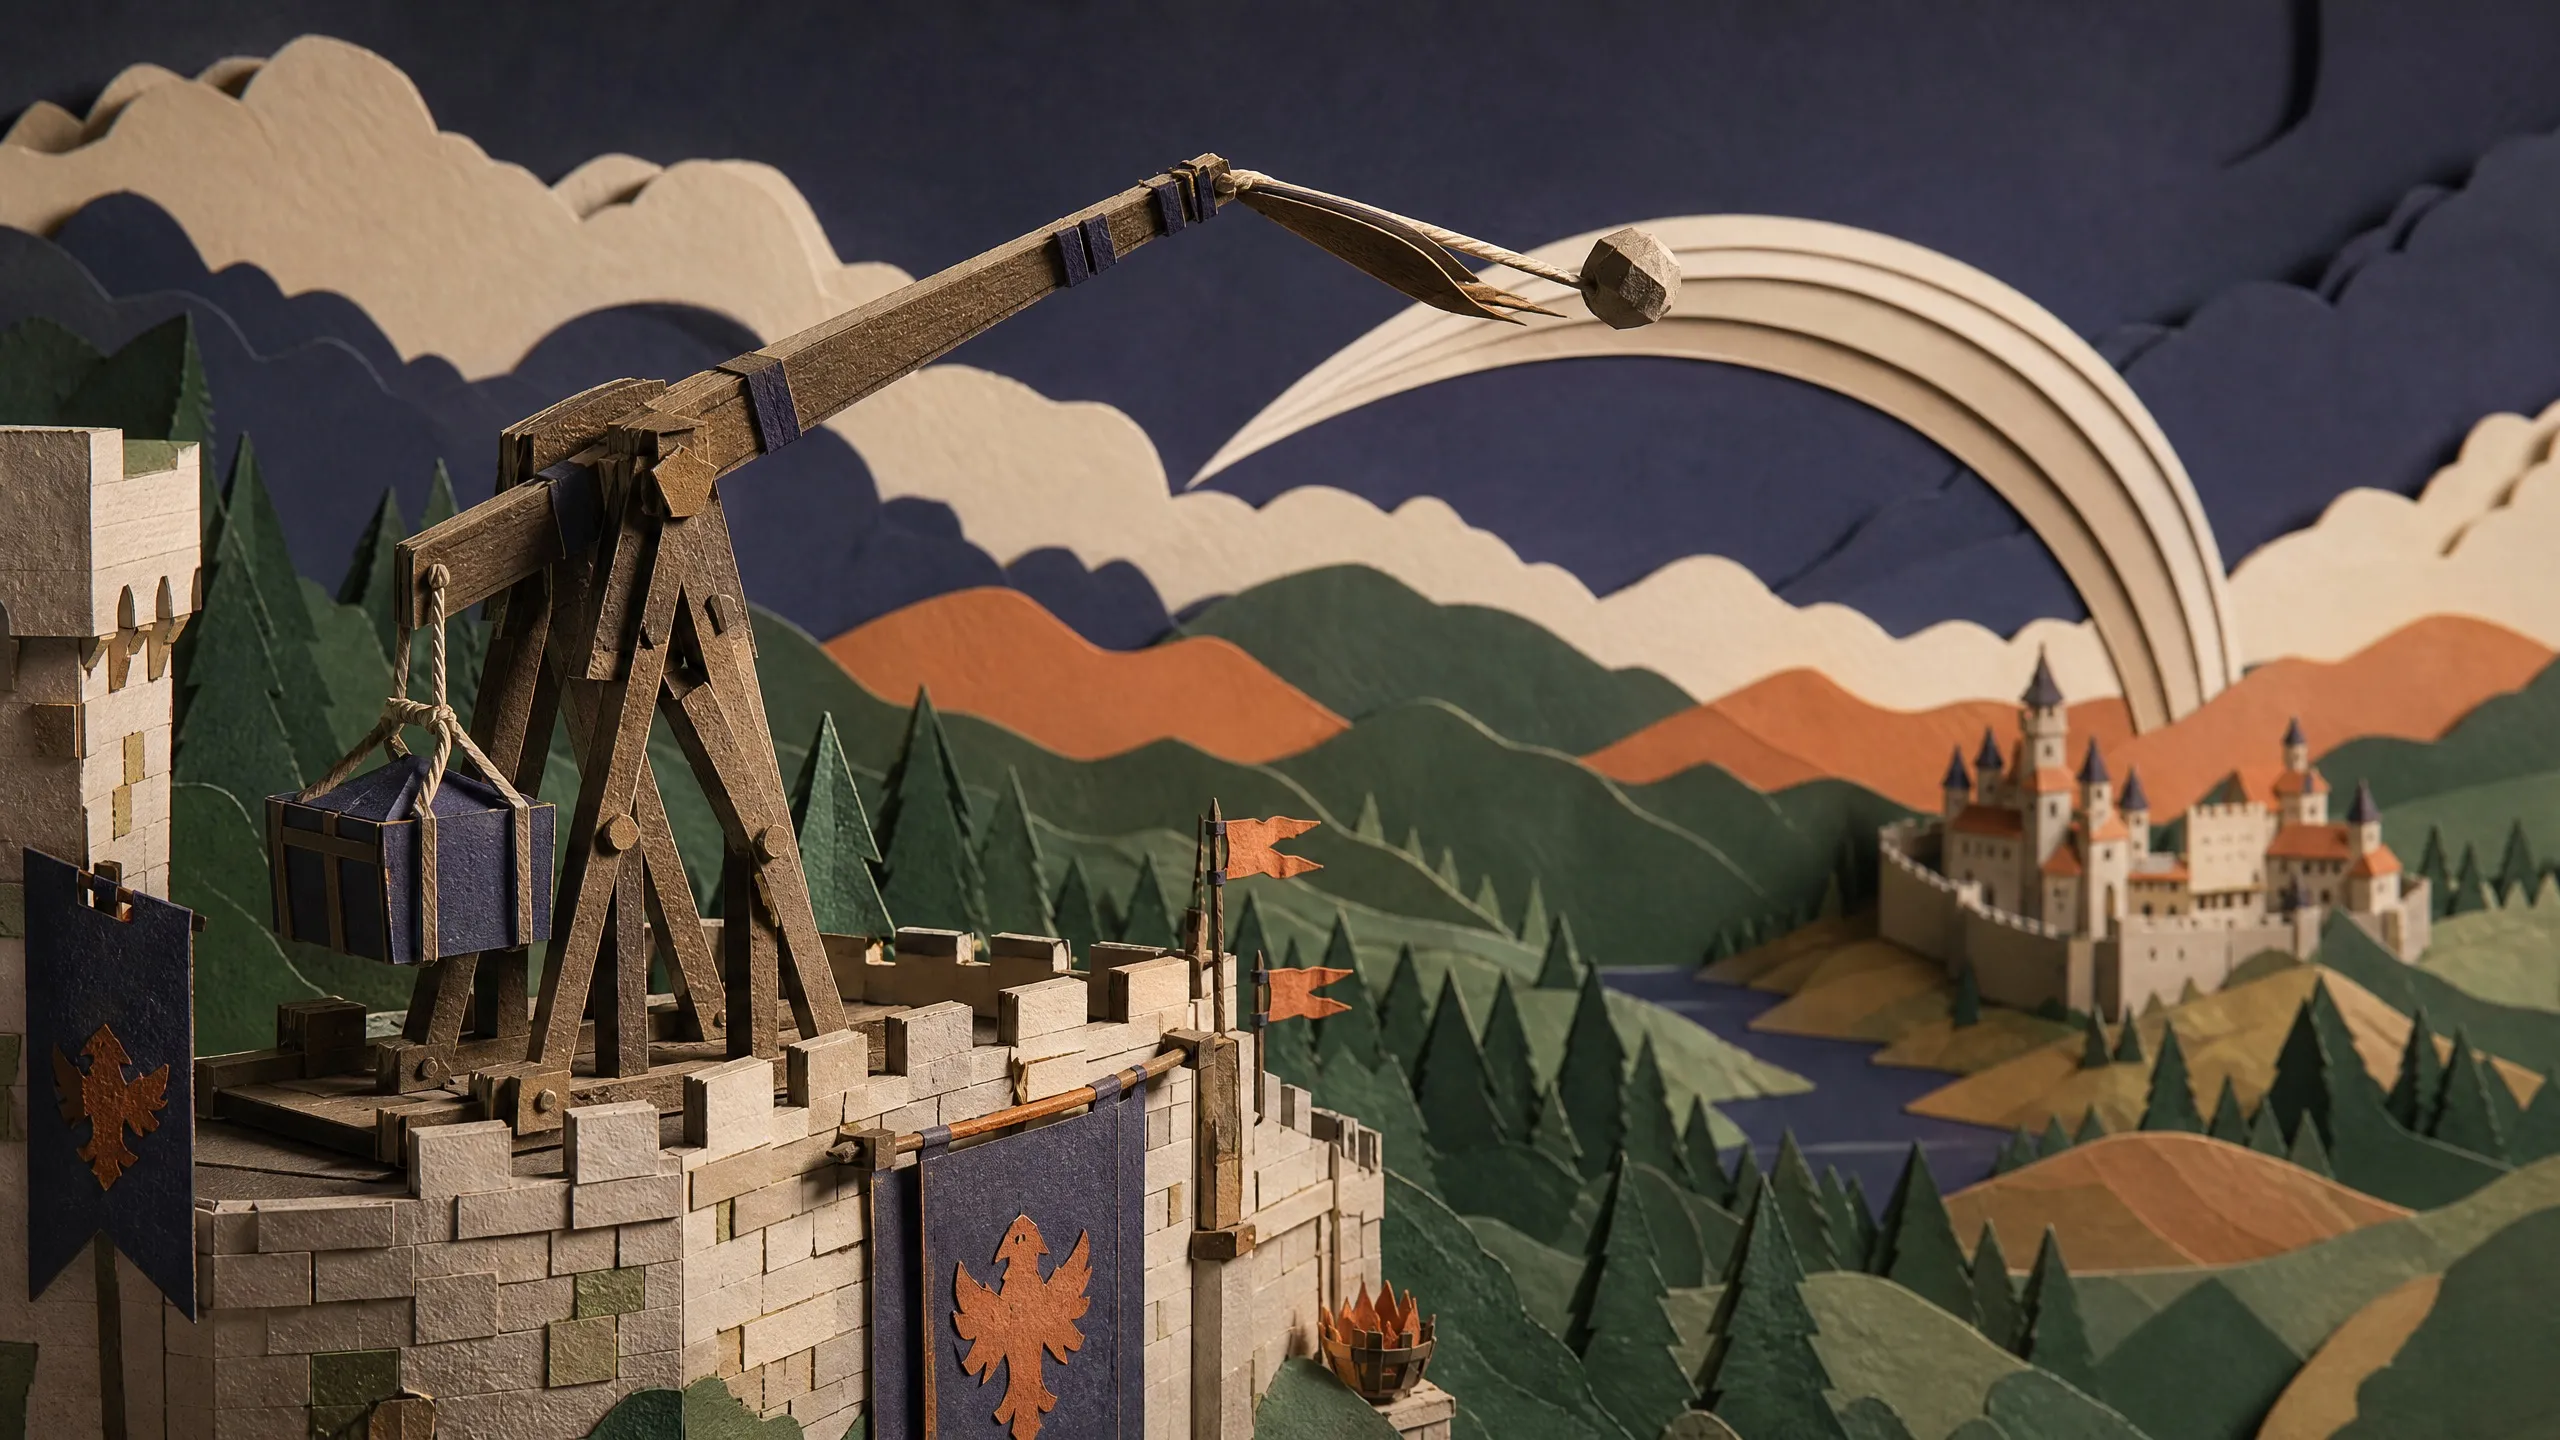
Stormwind Trebuchet Simulator
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.

Universe Simulator
Cosmic system testing orbital structure, glowing bodies, scale, and simulation readability.

Vice City
Neon coastal city testing vehicles, architecture, atmosphere, and dense urban layout.
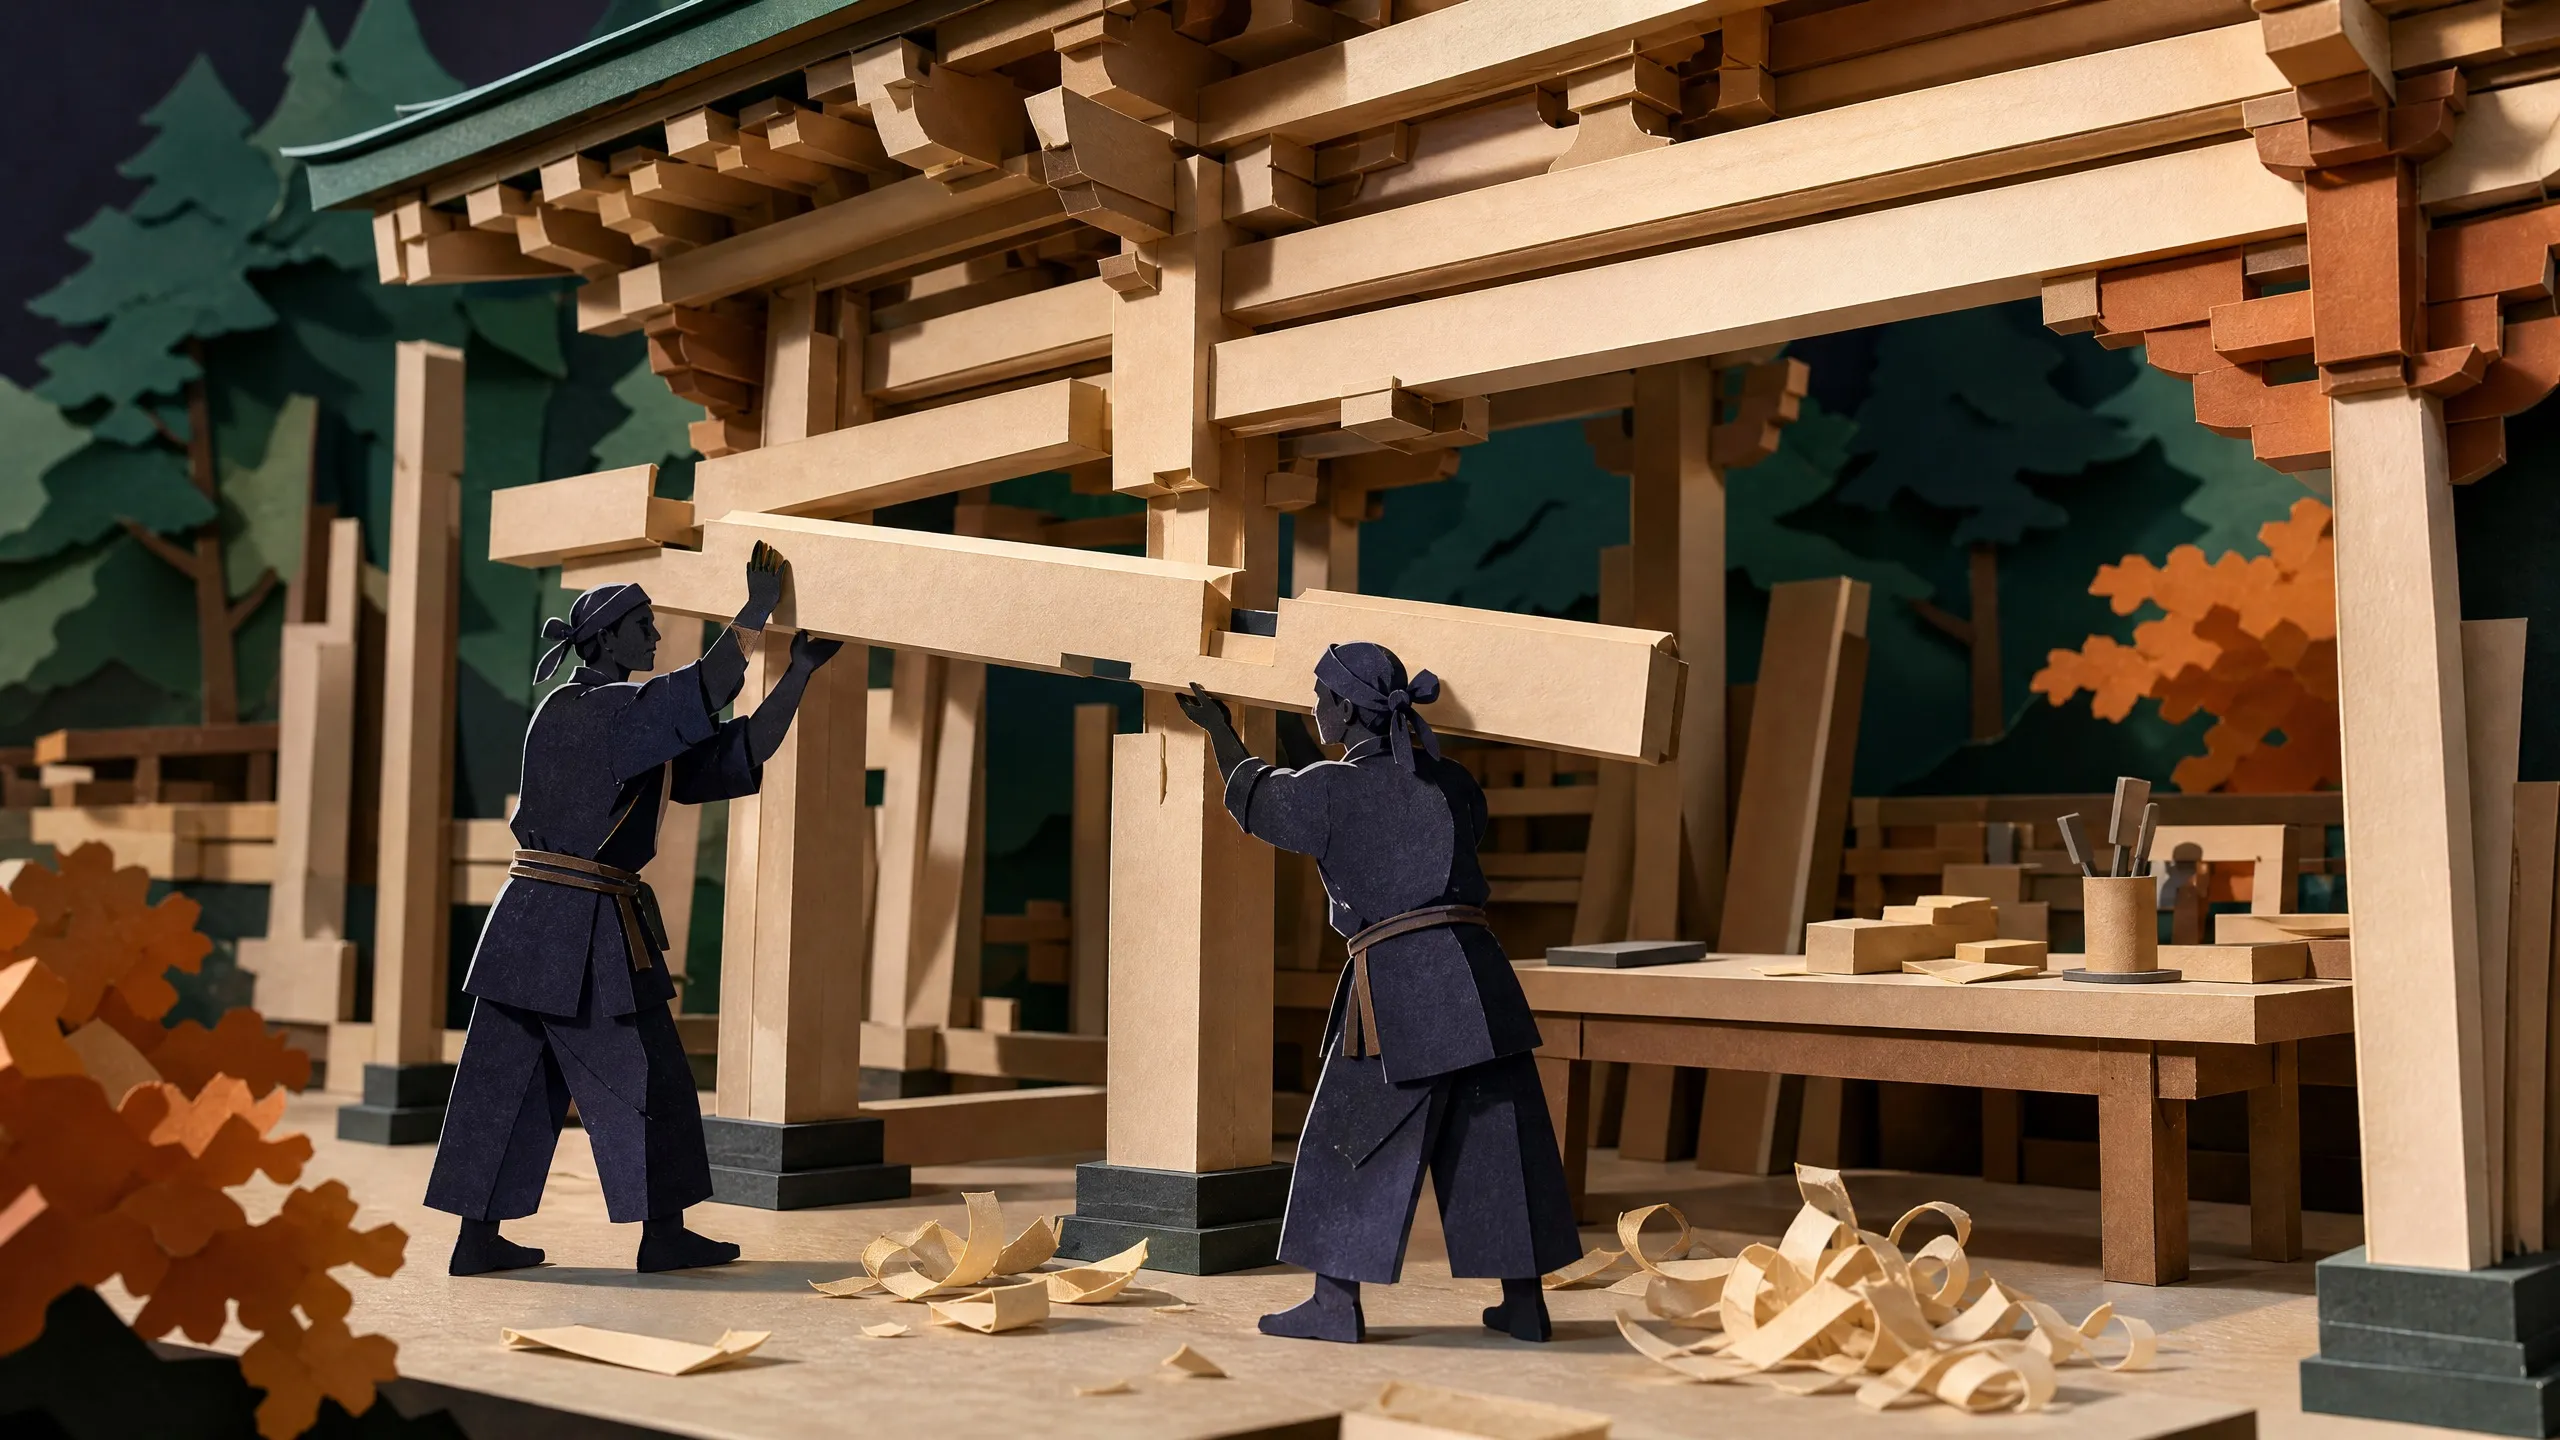
Yingzao Fashi Assembly
Timber assembly scene testing structure, joinery, construction order, and material clarity.
How DeepSeek V4 Pro compares
Three relevant peers, side by side.
- DeepSeek V4 Pro This model
- DeepSeek V4 Flash Max
- Claude Opus 4.6 Max
- Gemini 3.1 Pro High
6 benchmarks · 4 models
Official benchmark profile
Published scores outside our visual tests
MMLU-Pro
87.5%GPQA Diamond
90.1%LiveCodeBench
93.5%Full official benchmark table12 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| MMLU-Pro | Knowledge | 87.5% | |
| GPQA Diamond | STEM reasoning | 90.1% | |
| LiveCodeBench | Code reasoning | 93.5% | |
| HMMT February 2026 | Math | 95.2% | |
| IMOAnswerBench | Math reasoning | 89.8% | |
| MRCR 1M | Long context | 83.5% | |
| Terminal-Bench 2.0 | Agentic coding | 67.9% | |
| SWE-bench Verified | Agentic coding | 80.6% | |
| SWE-bench Pro | Agentic coding | 55.4% | |
| BrowseComp | Web research | 83.4% | |
| MCP Atlas | Tool use | 73.6% | |
| Toolathlon | Tool use | 51.8% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Current
- API model ID
deepseek-v4-pro- Context
- 1M
- Max output
- 384K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- DeepSeek API peak rate · USD / 1M tokens
- $1.32 input · $0.044 cached input · $3.96 output
Peak hours: Monday–Friday, 01:00–04:00 and 06:00–10:00 UTC. All other hours use half-price off-peak rates: $0.66 input, $0.022 cached input, and $1.98 output per 1M tokens.
Benchmark sources
DeepSeek V4 Pro activates 49B of 1.6T parameters with a 1M-token context. These are the official V4-Pro Max results, which use the largest published reasoning budget and differ from the non-thinking and high settings.
DeepSeek-V4: Towards Highly Efficient Million-Token Context IntelligenceEvaluation settings
- Exact match at V4-Pro Max reasoning effort.
- Pass@1 at V4-Pro Max reasoning effort.
- Mean matching rate at the 1M-token setting.
- Accuracy in the official DeepSeek comparison table.
- Resolved rate in the official DeepSeek comparison table.
- Pass@1 in the official DeepSeek comparison table.
Editorial verdict
Where this model fits
DeepSeek V4 Pro moves into A tier on the strength of the new architecture and DeepSeek’s exceptional cost efficiency. The team had not yet completed a direct V4 Pro evaluation when recording, so this is a provisional flagship placement informed partly by hands-on V4 Flash use.
Best for
Watch out
Why it is ranked here
Evidence
Superbash editorial model ranking
Takeaway: DeepSeek V4 Pro is currently placed in Tier A.
The September 2026 editorial roster places DeepSeek V4 Pro at rank 5.
Open source →NEW AI Model Tier List for Vibe Coding!
Takeaway: Use DeepSeek V4 Pro for cost-conscious reasoning, then review the UI carefully.
The source video’s front-end caveat remains relevant even with the current A-tier placement.
Open source →Related guides