DeepSeek
DeepSeek V4 Flash
Version 1.0 benchmark runs across the shared Superbash visual prompts.
API pricing
USD per million tokens · DeepSeek API peak rate- Input
- $0.44
- Output
- $1.32
- Cached input
- $0.014
- Context window
- 1M
Inspect the original visual runs
Open the generated scene to test it, or compare that prompt with another model.
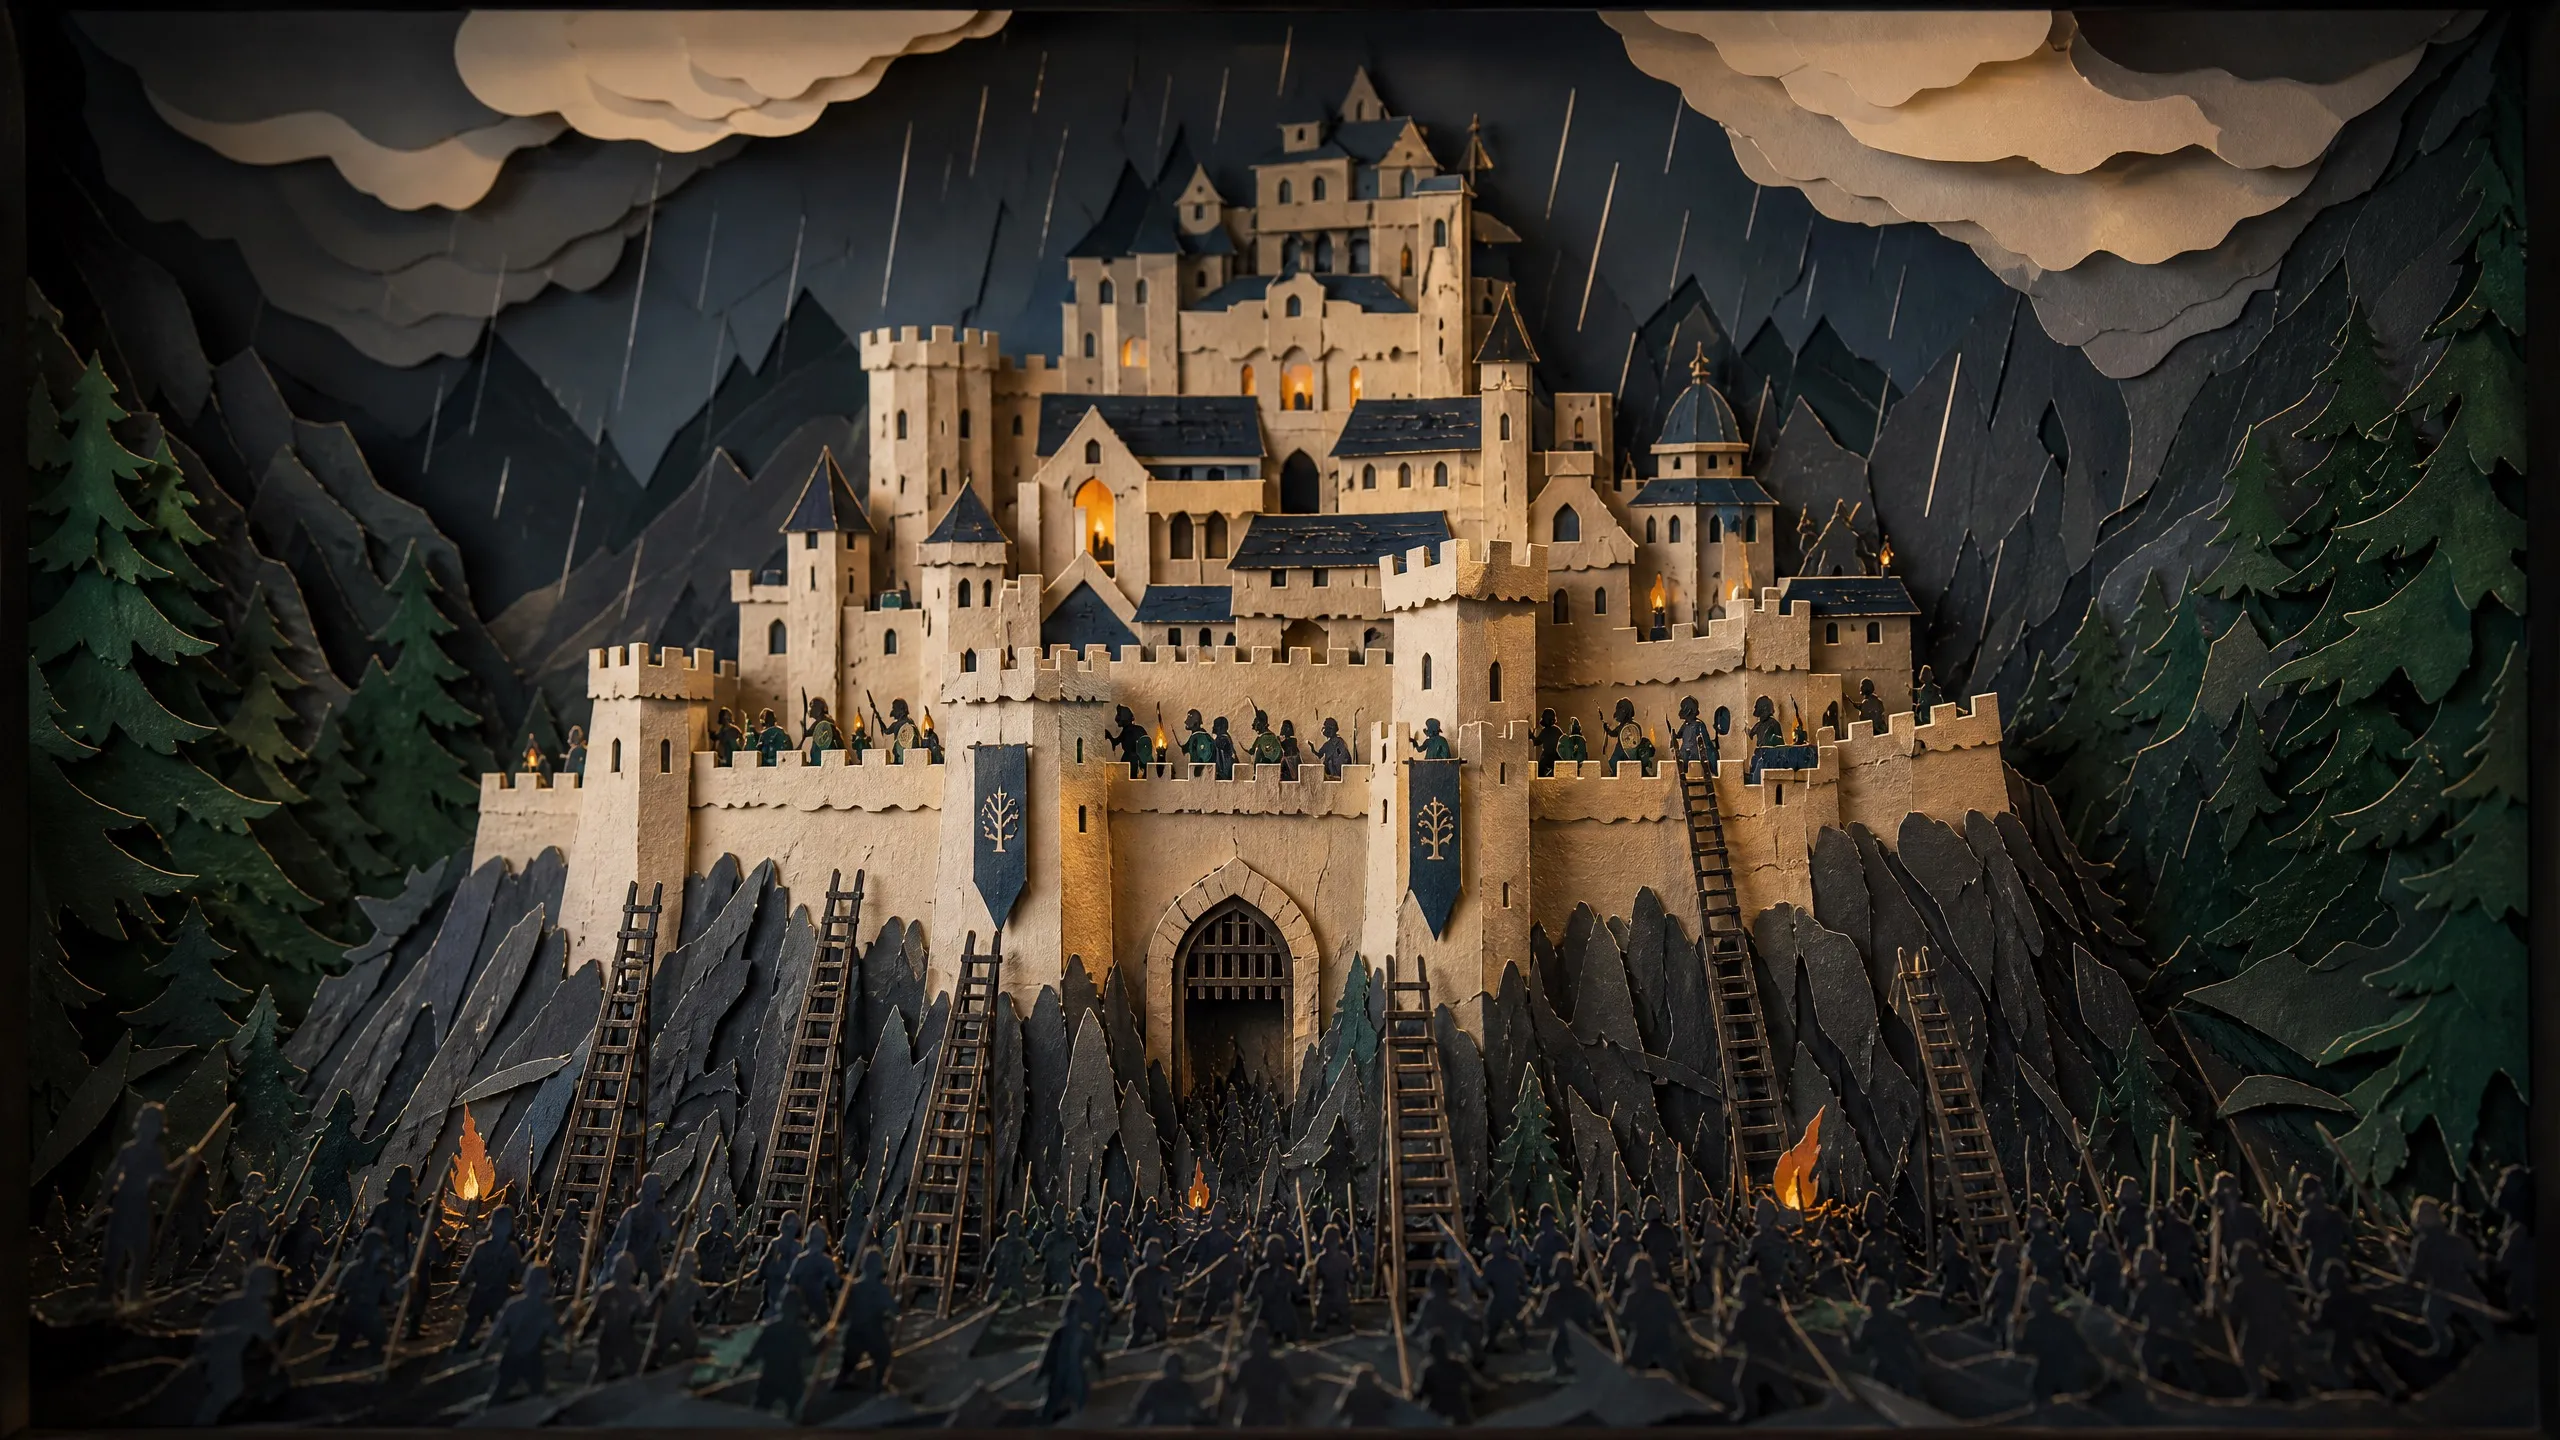
Helm's Deep
Run date: 2026-08-04
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
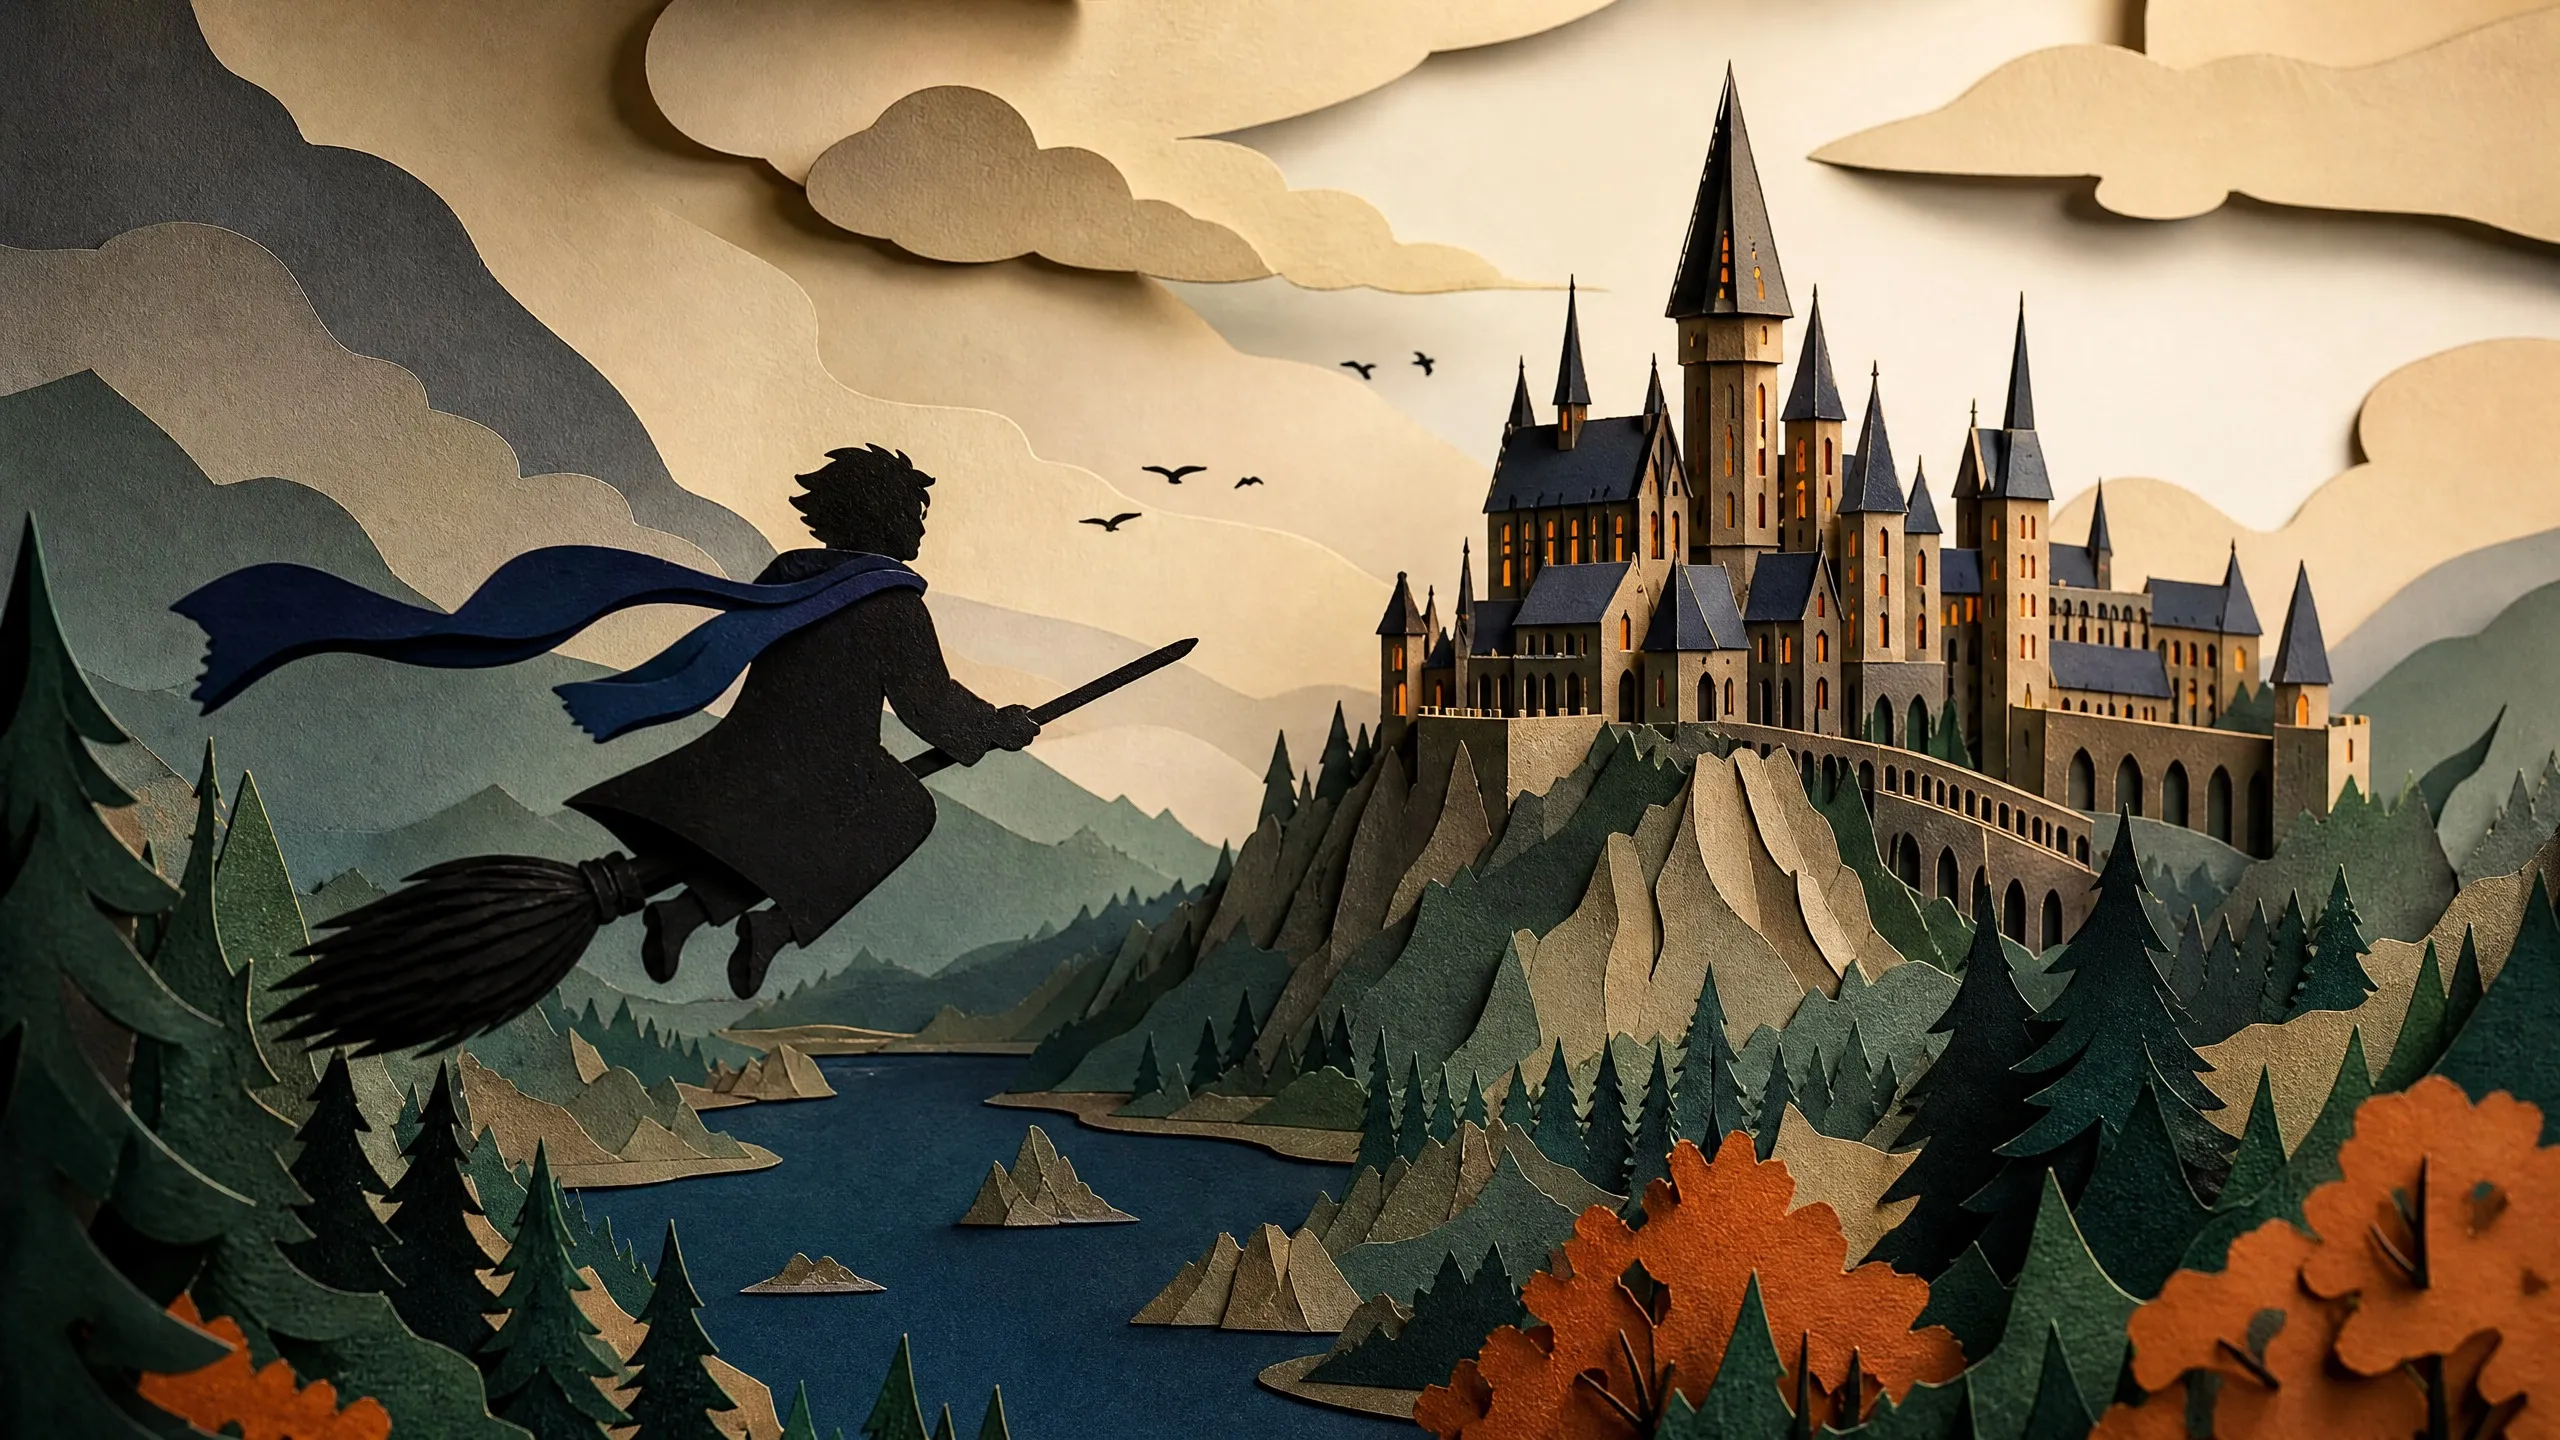
Hogwarts Broom Flight Simulator
Run date: 2026-08-04
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
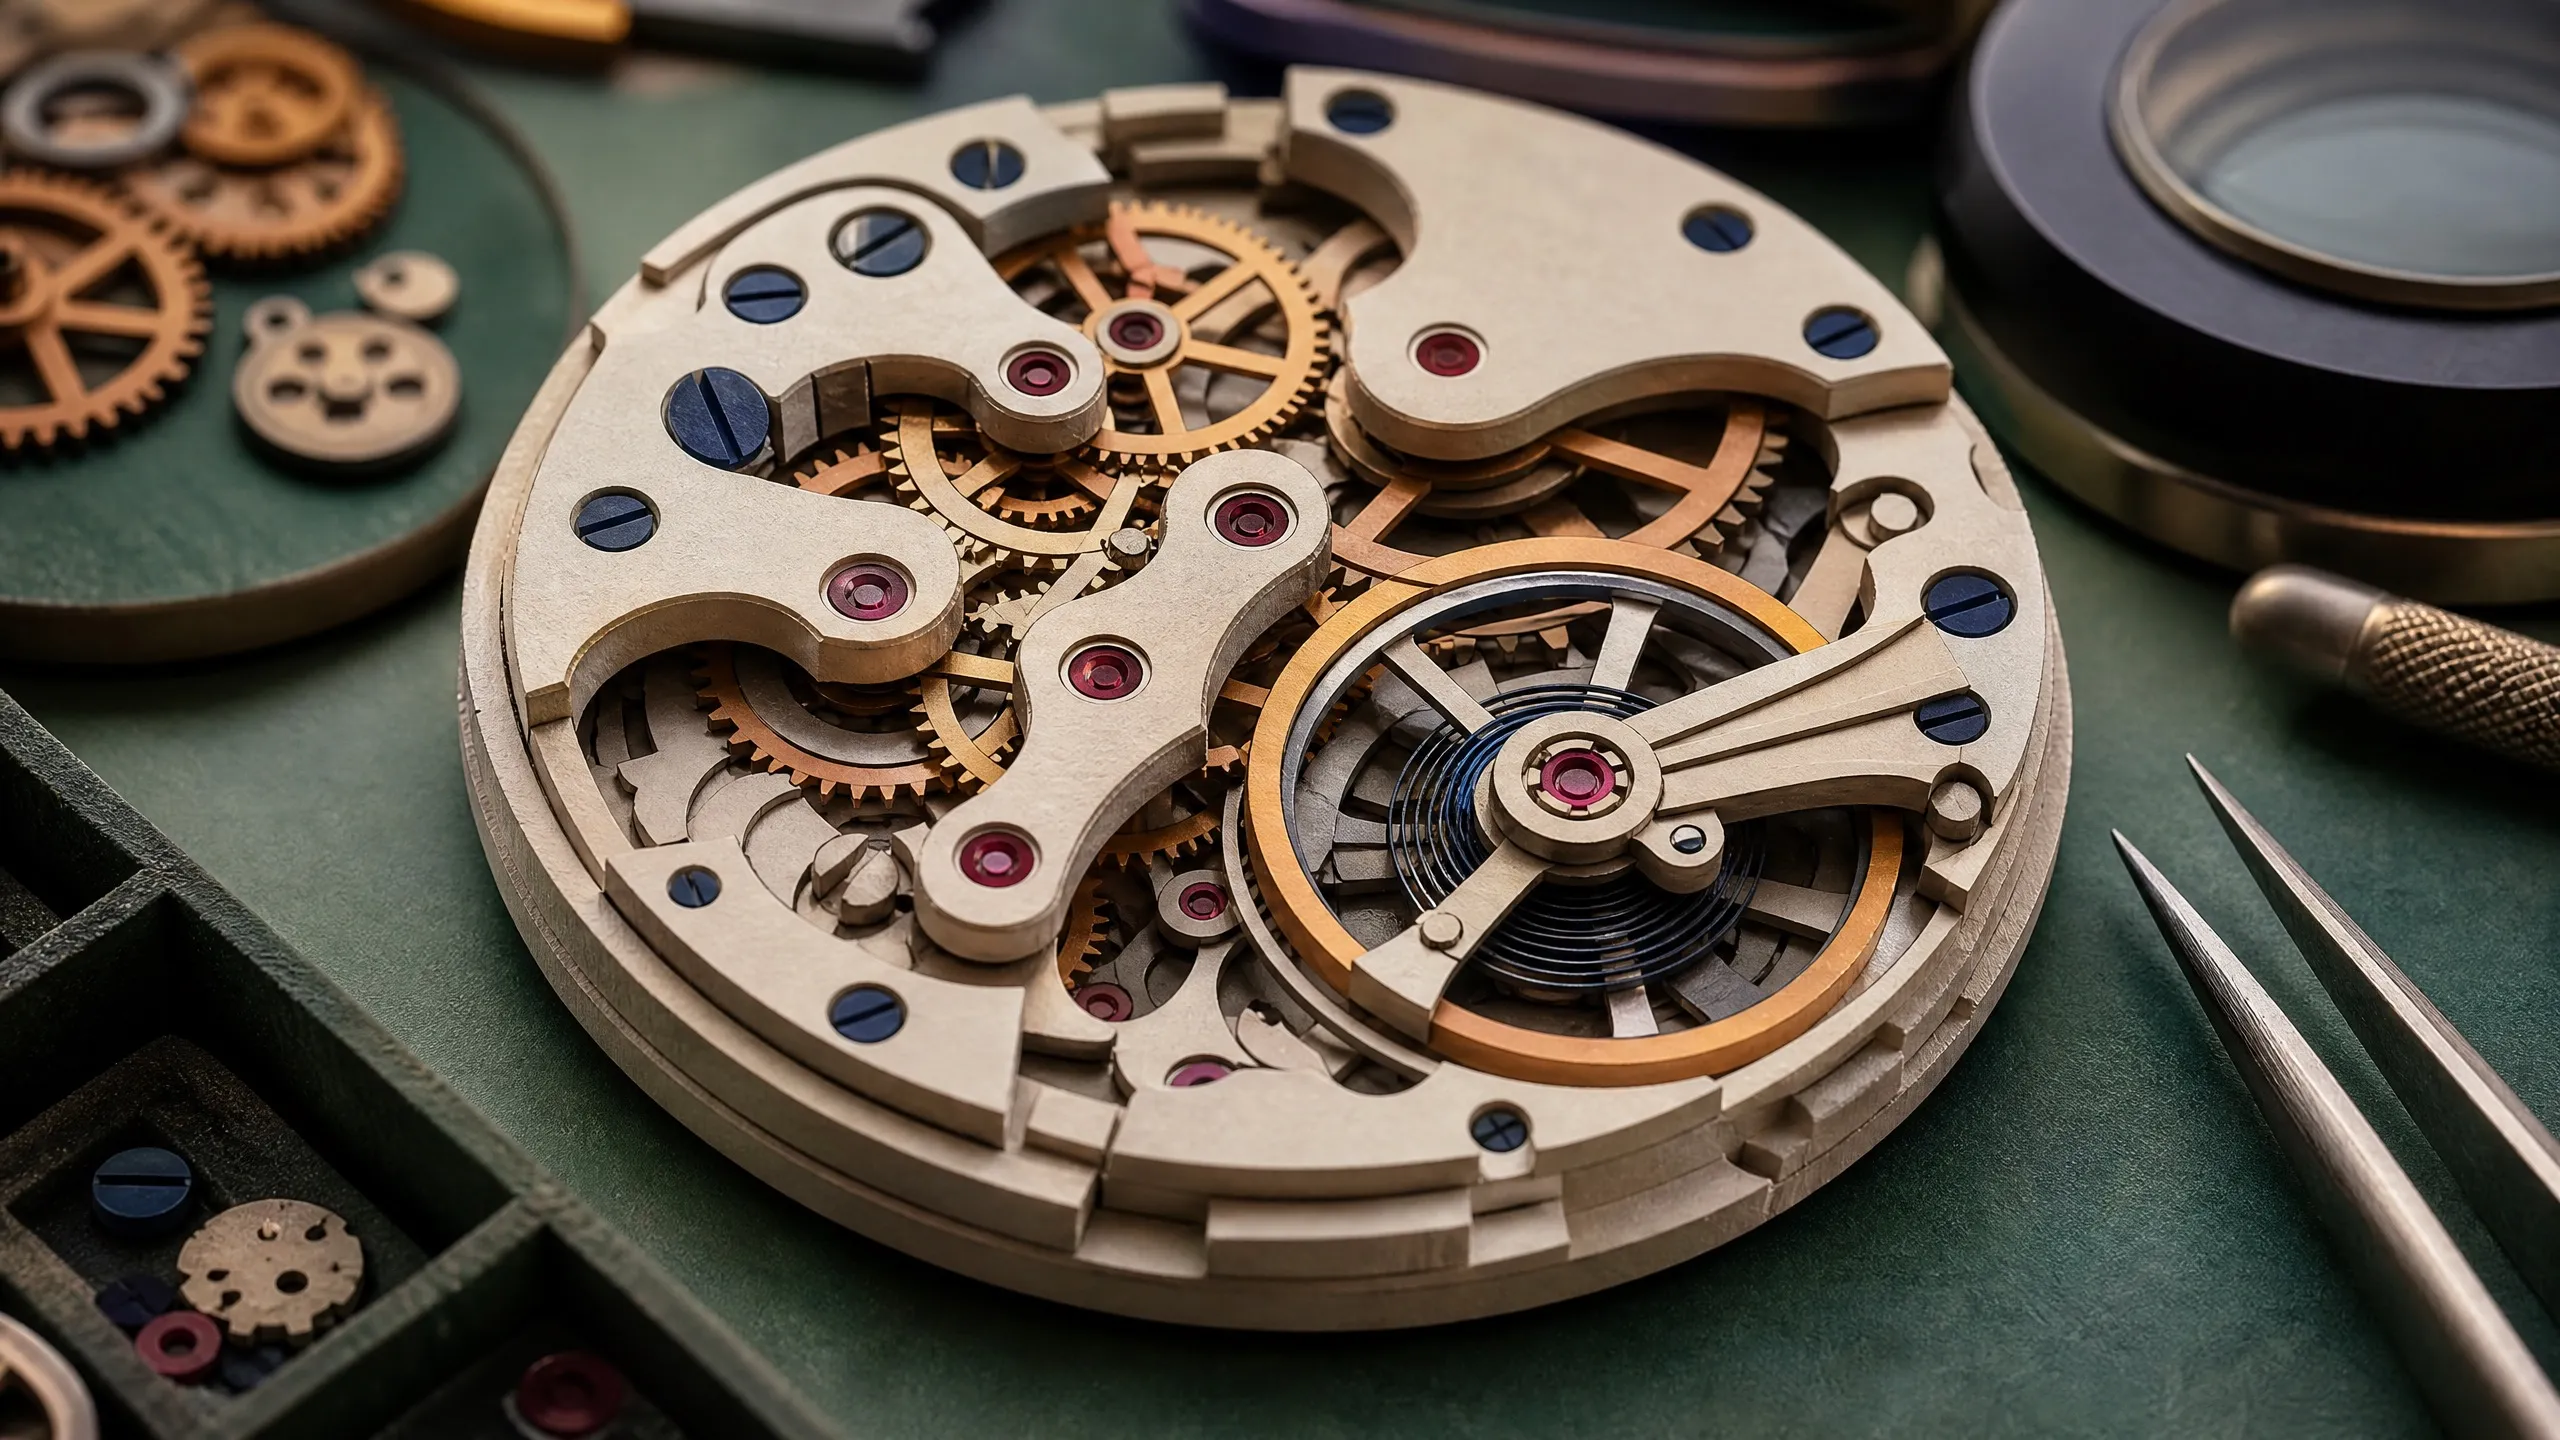
Mechanical Watch Simulator
Run date: 2026-08-04
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.
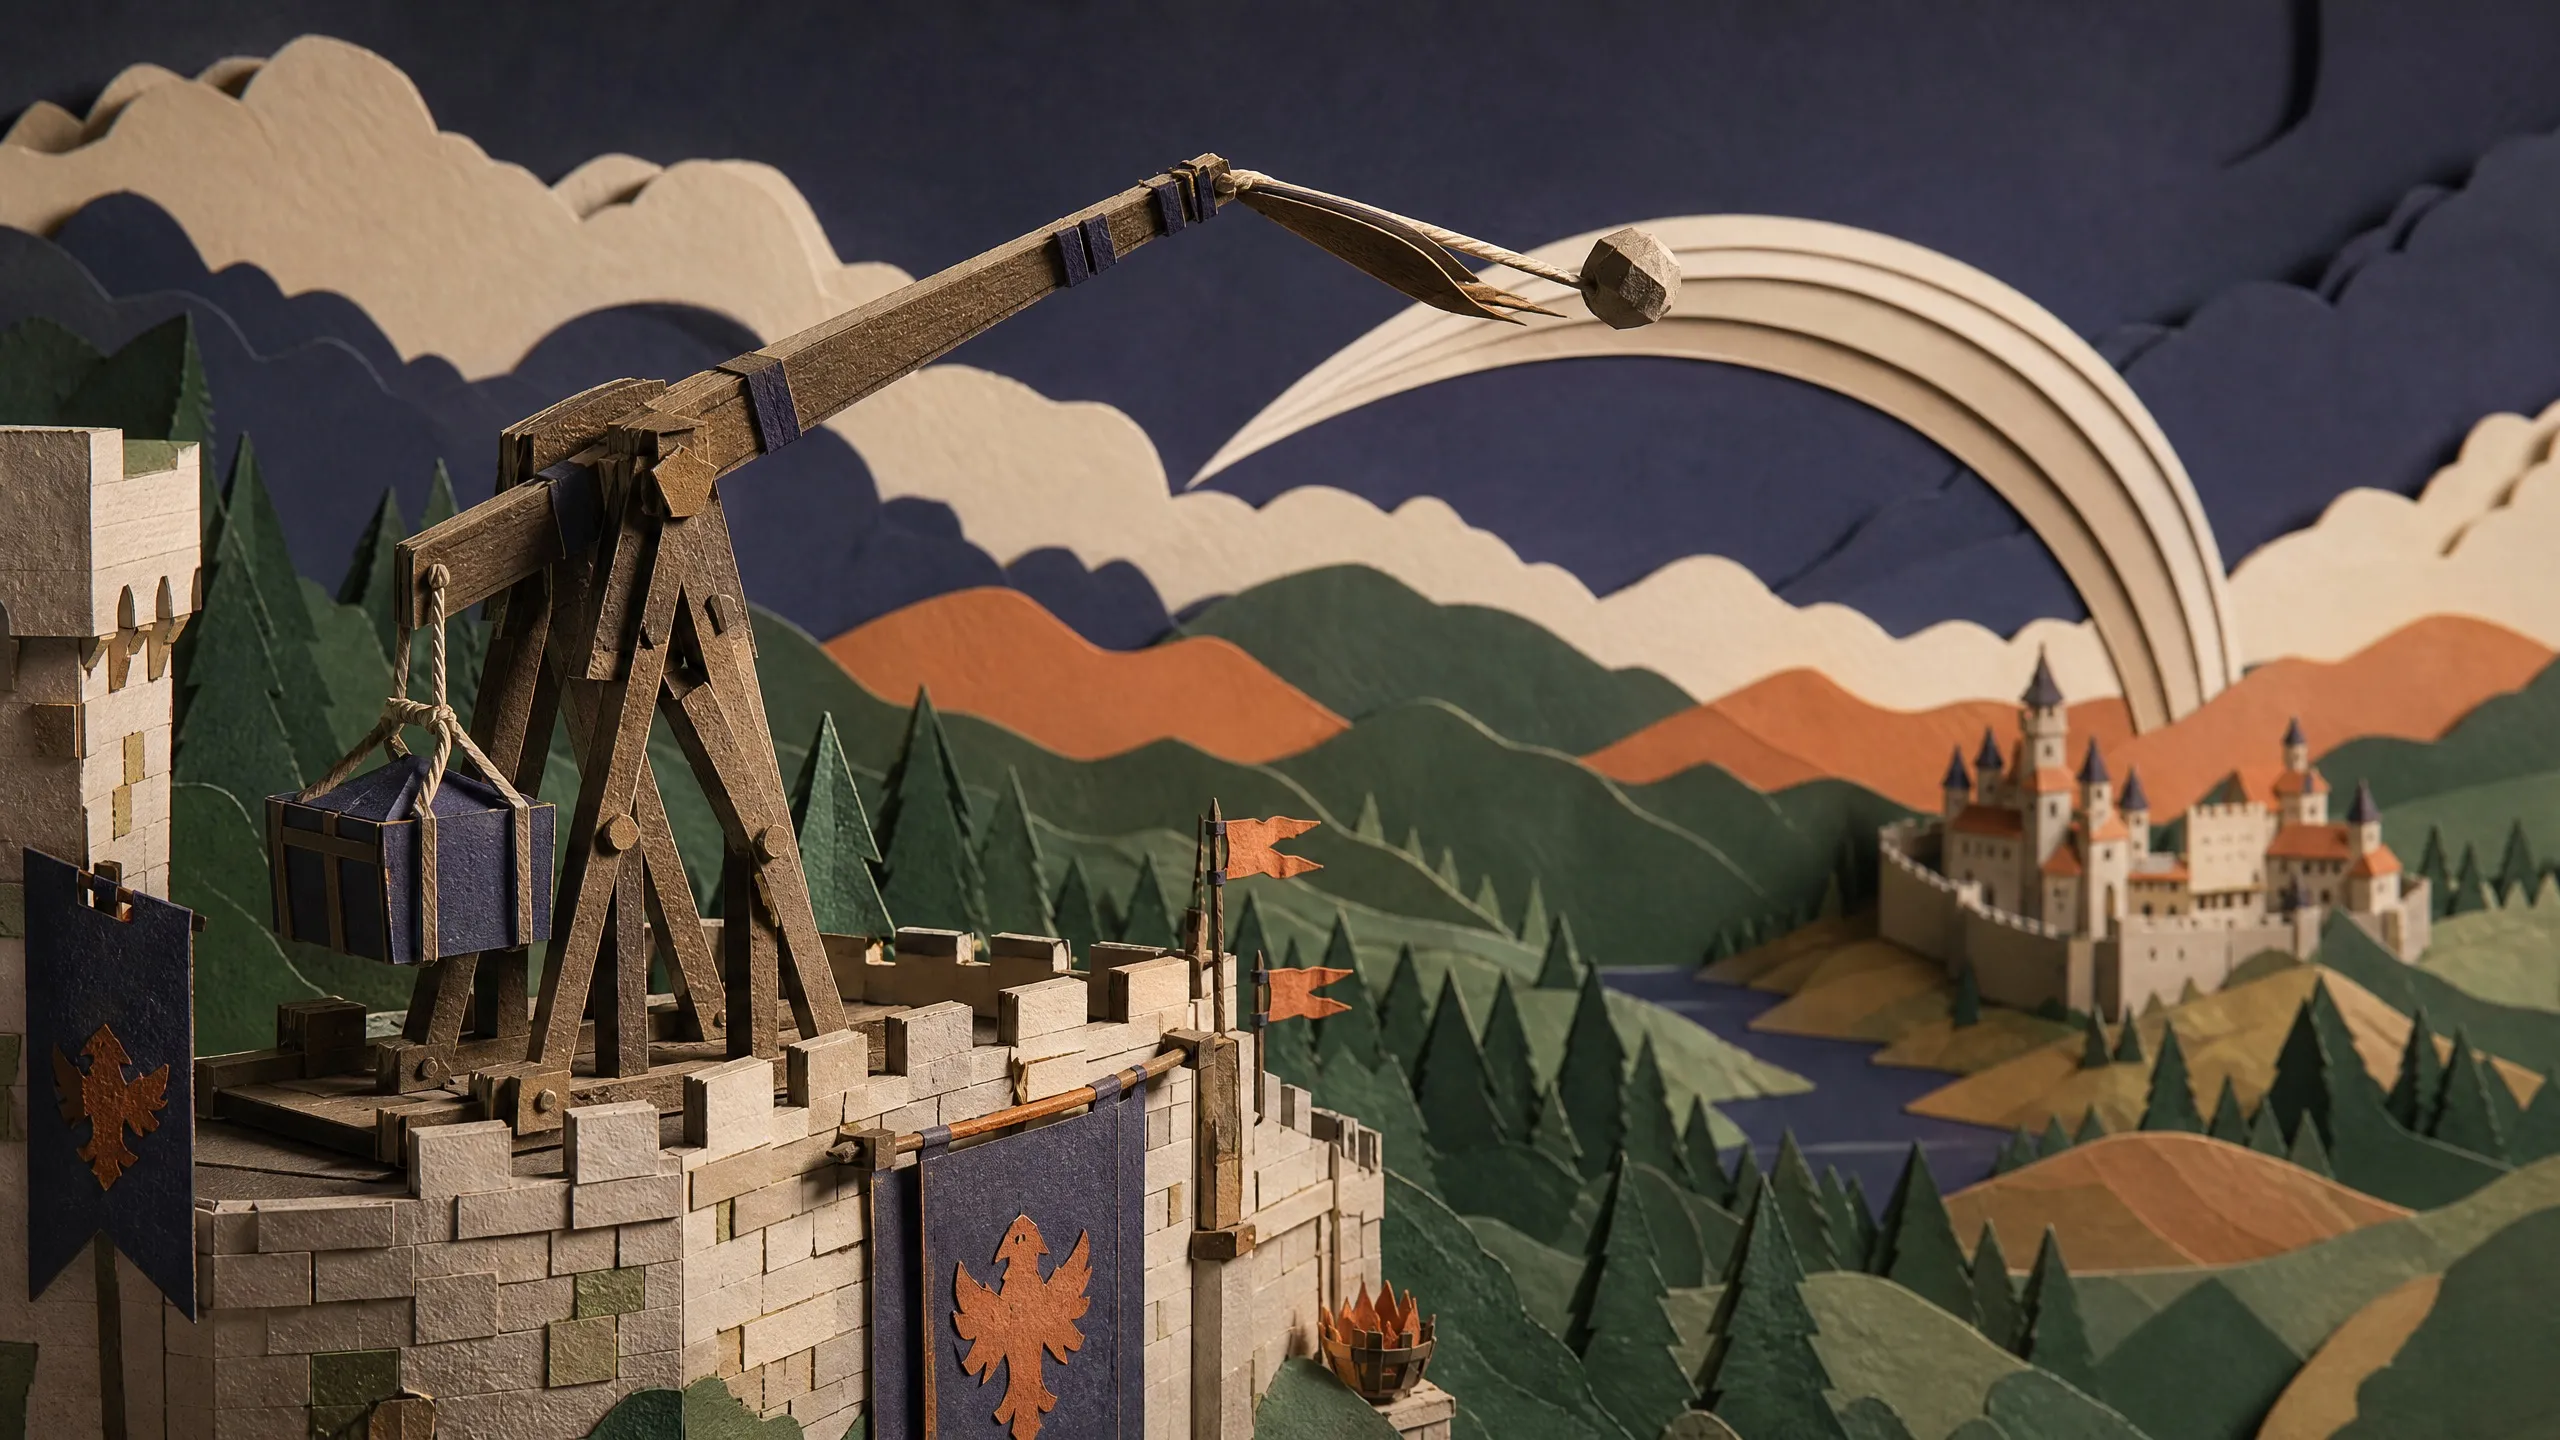
Stormwind Trebuchet Simulator
Run date: 2026-08-04
Counterweight siege simulation testing coupled mechanics, trajectory prediction, projectile cameras, and interactive tuning.
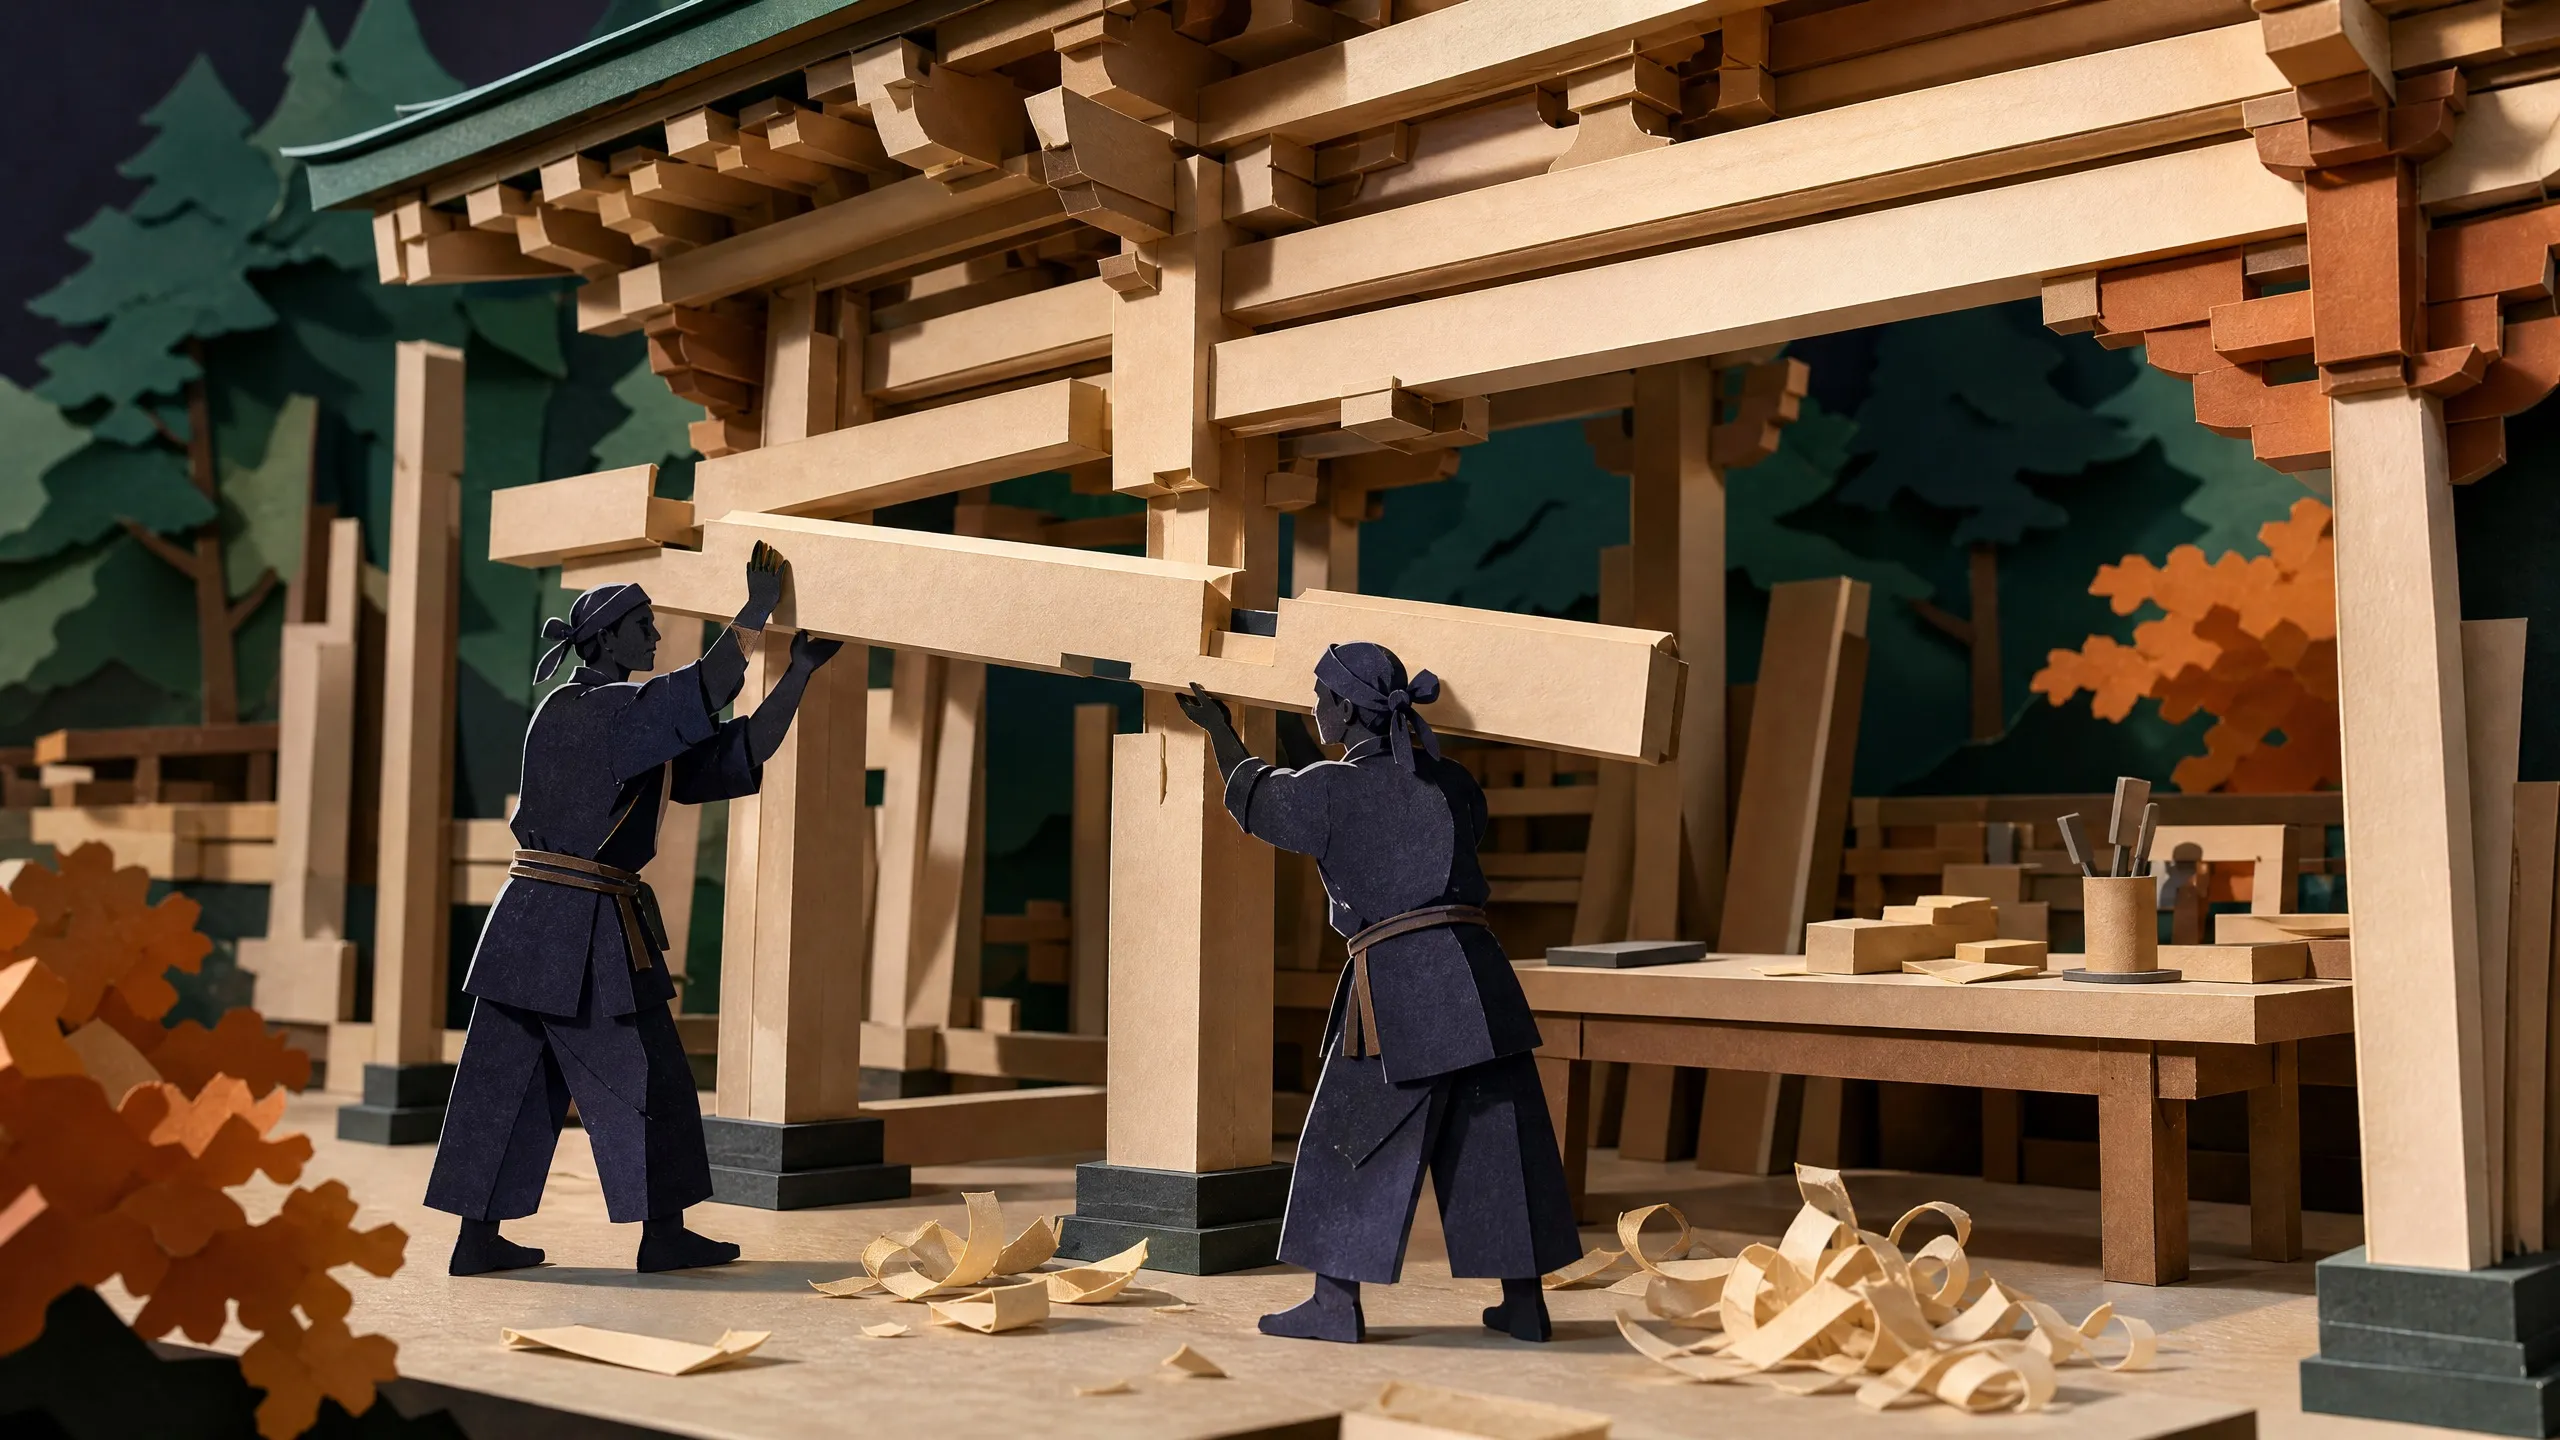
Yingzao Fashi Assembly
Run date: 2026-08-04
Specialist test · evaluated separately
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How DeepSeek V4 Flash compares
Three relevant peers, side by side.
- DeepSeek V4 Flash This model
- DeepSeek V4 Pro Max
- Gemini 3.1 Pro High
- Claude Opus 4.6 Max
6 benchmarks · 4 models
Official benchmark profile
Published scores outside our visual tests
MMLU-Pro
86.2%GPQA Diamond
88.1%LiveCodeBench
91.6%Full official benchmark table12 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| MMLU-Pro | Knowledge | 86.2% | |
| GPQA Diamond | STEM reasoning | 88.1% | |
| LiveCodeBench | Code reasoning | 91.6% | |
| HMMT February 2026 | Math | 94.8% | |
| IMOAnswerBench | Math reasoning | 88.4% | |
| MRCR 1M | Long context | 78.7% | |
| Terminal-Bench 2.0 | Agentic coding | 56.9% | |
| SWE-bench Verified | Agentic coding | 79.0% | |
| SWE-bench Pro | Agentic coding | 52.6% | |
| BrowseComp | Web research | 73.2% | |
| MCP Atlas | Tool use | 69.0% | |
| Toolathlon | Tool use | 47.8% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Superseded in this ranking
- API model ID
deepseek-v4-flash- Context
- 1M
- Max output
- 384K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- DeepSeek API peak rate · USD / 1M tokens
- $0.44 input · $0.014 cached input · $1.32 output
Peak hours: Monday–Friday, 01:00–04:00 and 06:00–10:00 UTC. All other hours use half-price off-peak rates: $0.22 input, $0.007 cached input, and $0.66 output per 1M tokens.
Benchmark sources
DeepSeek V4 Flash activates 13B of 284B parameters with a 1M-token context. These are the official V4-Flash Max results, which use the largest published reasoning budget and differ from the non-thinking and high settings.
DeepSeek-V4: Towards Highly Efficient Million-Token Context IntelligenceEvaluation settings
- Exact match at V4-Flash Max reasoning effort.
- Pass@1 at V4-Flash Max reasoning effort.
- Mean matching rate at the 1M-token setting.
- Accuracy in the official DeepSeek comparison table.
- Resolved rate in the official DeepSeek comparison table.
- Pass@1 in the official DeepSeek comparison table.