Moonshot AI
Kimi K3
Version 3 benchmark runs across the shared Superbash visual prompts.
API pricing
USD per million tokens · Kimi API- Input
- $3
- Output
- $15
- Cached input
- $0.3
- Context window
- 1.05M
Suggested for this guide
Kimi
Use the same Kimi family tested on this page. Check the current plan and model access before subscribing.
Best for: Claude Code setups and cost-aware model work
Check Kimi plansPartner link. It supports Superbash Learn at no extra cost to you.Inspect the original visual runs
Open the generated scene to test it, or compare that prompt with another model.
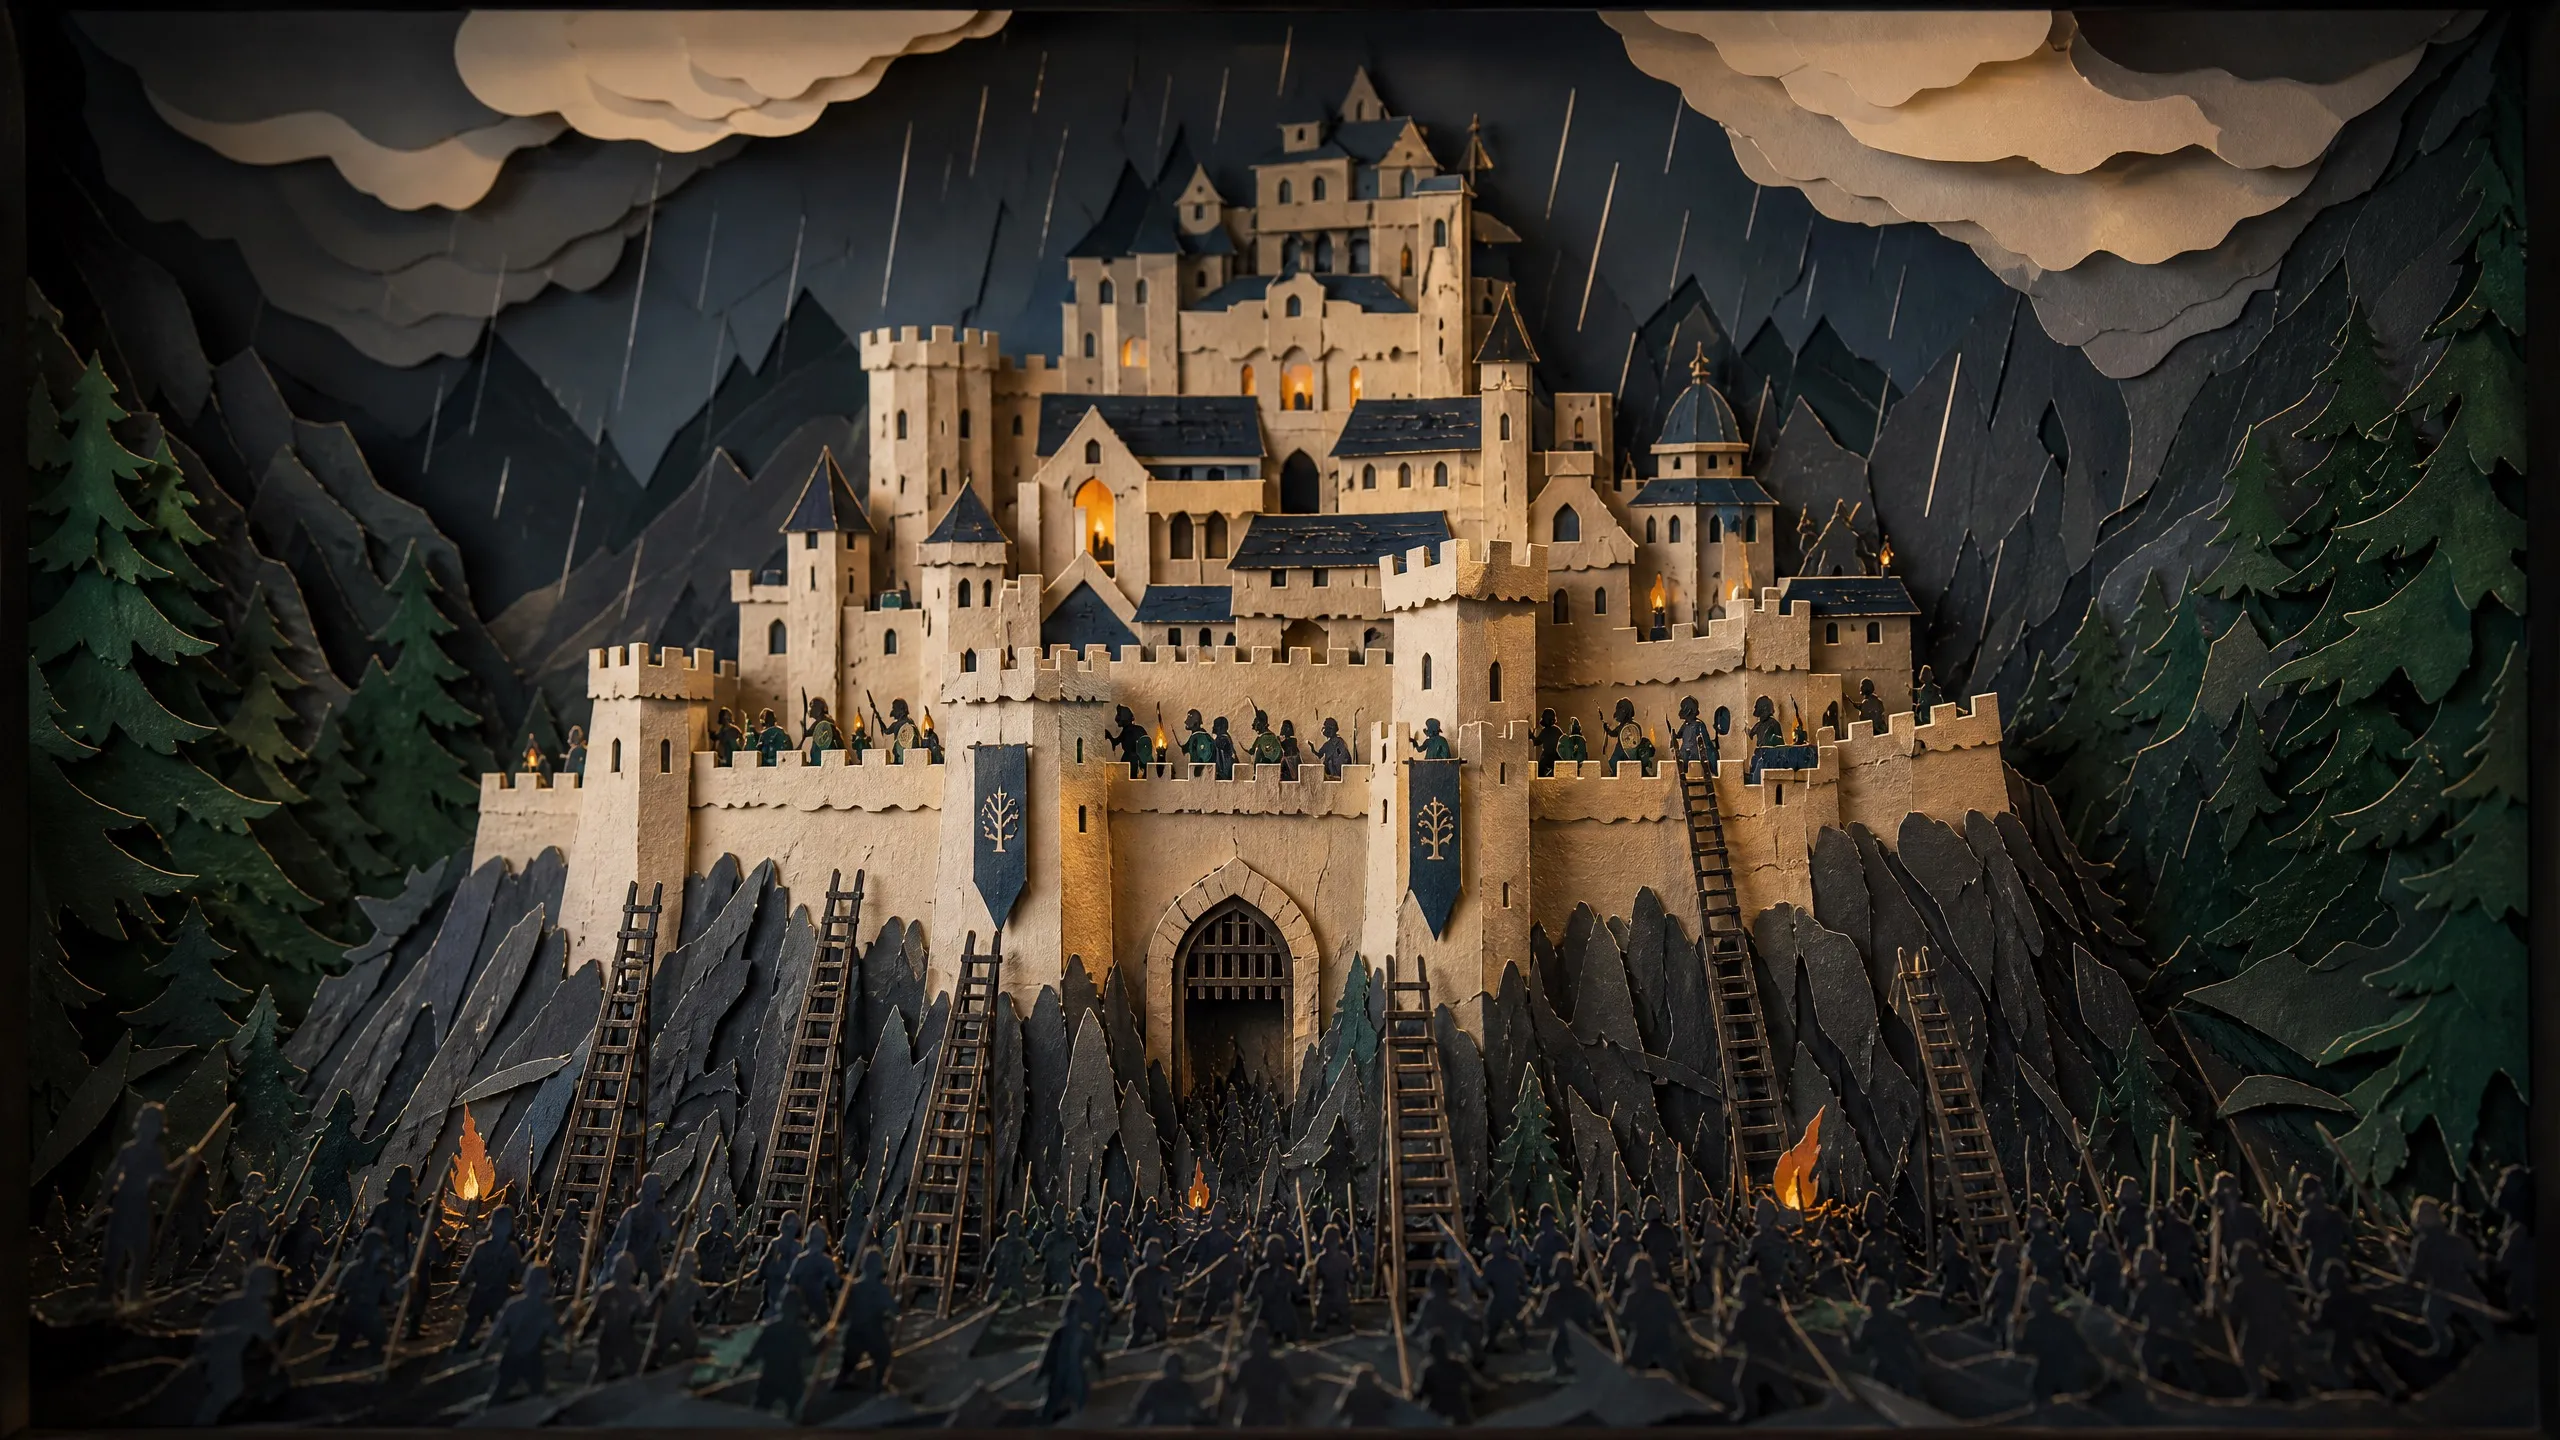
Helm's Deep
Run date: 2026-07-16
Generation provenance: unrecorded
Fortress siege scene testing scale, lighting, architecture, and cinematic atmosphere.
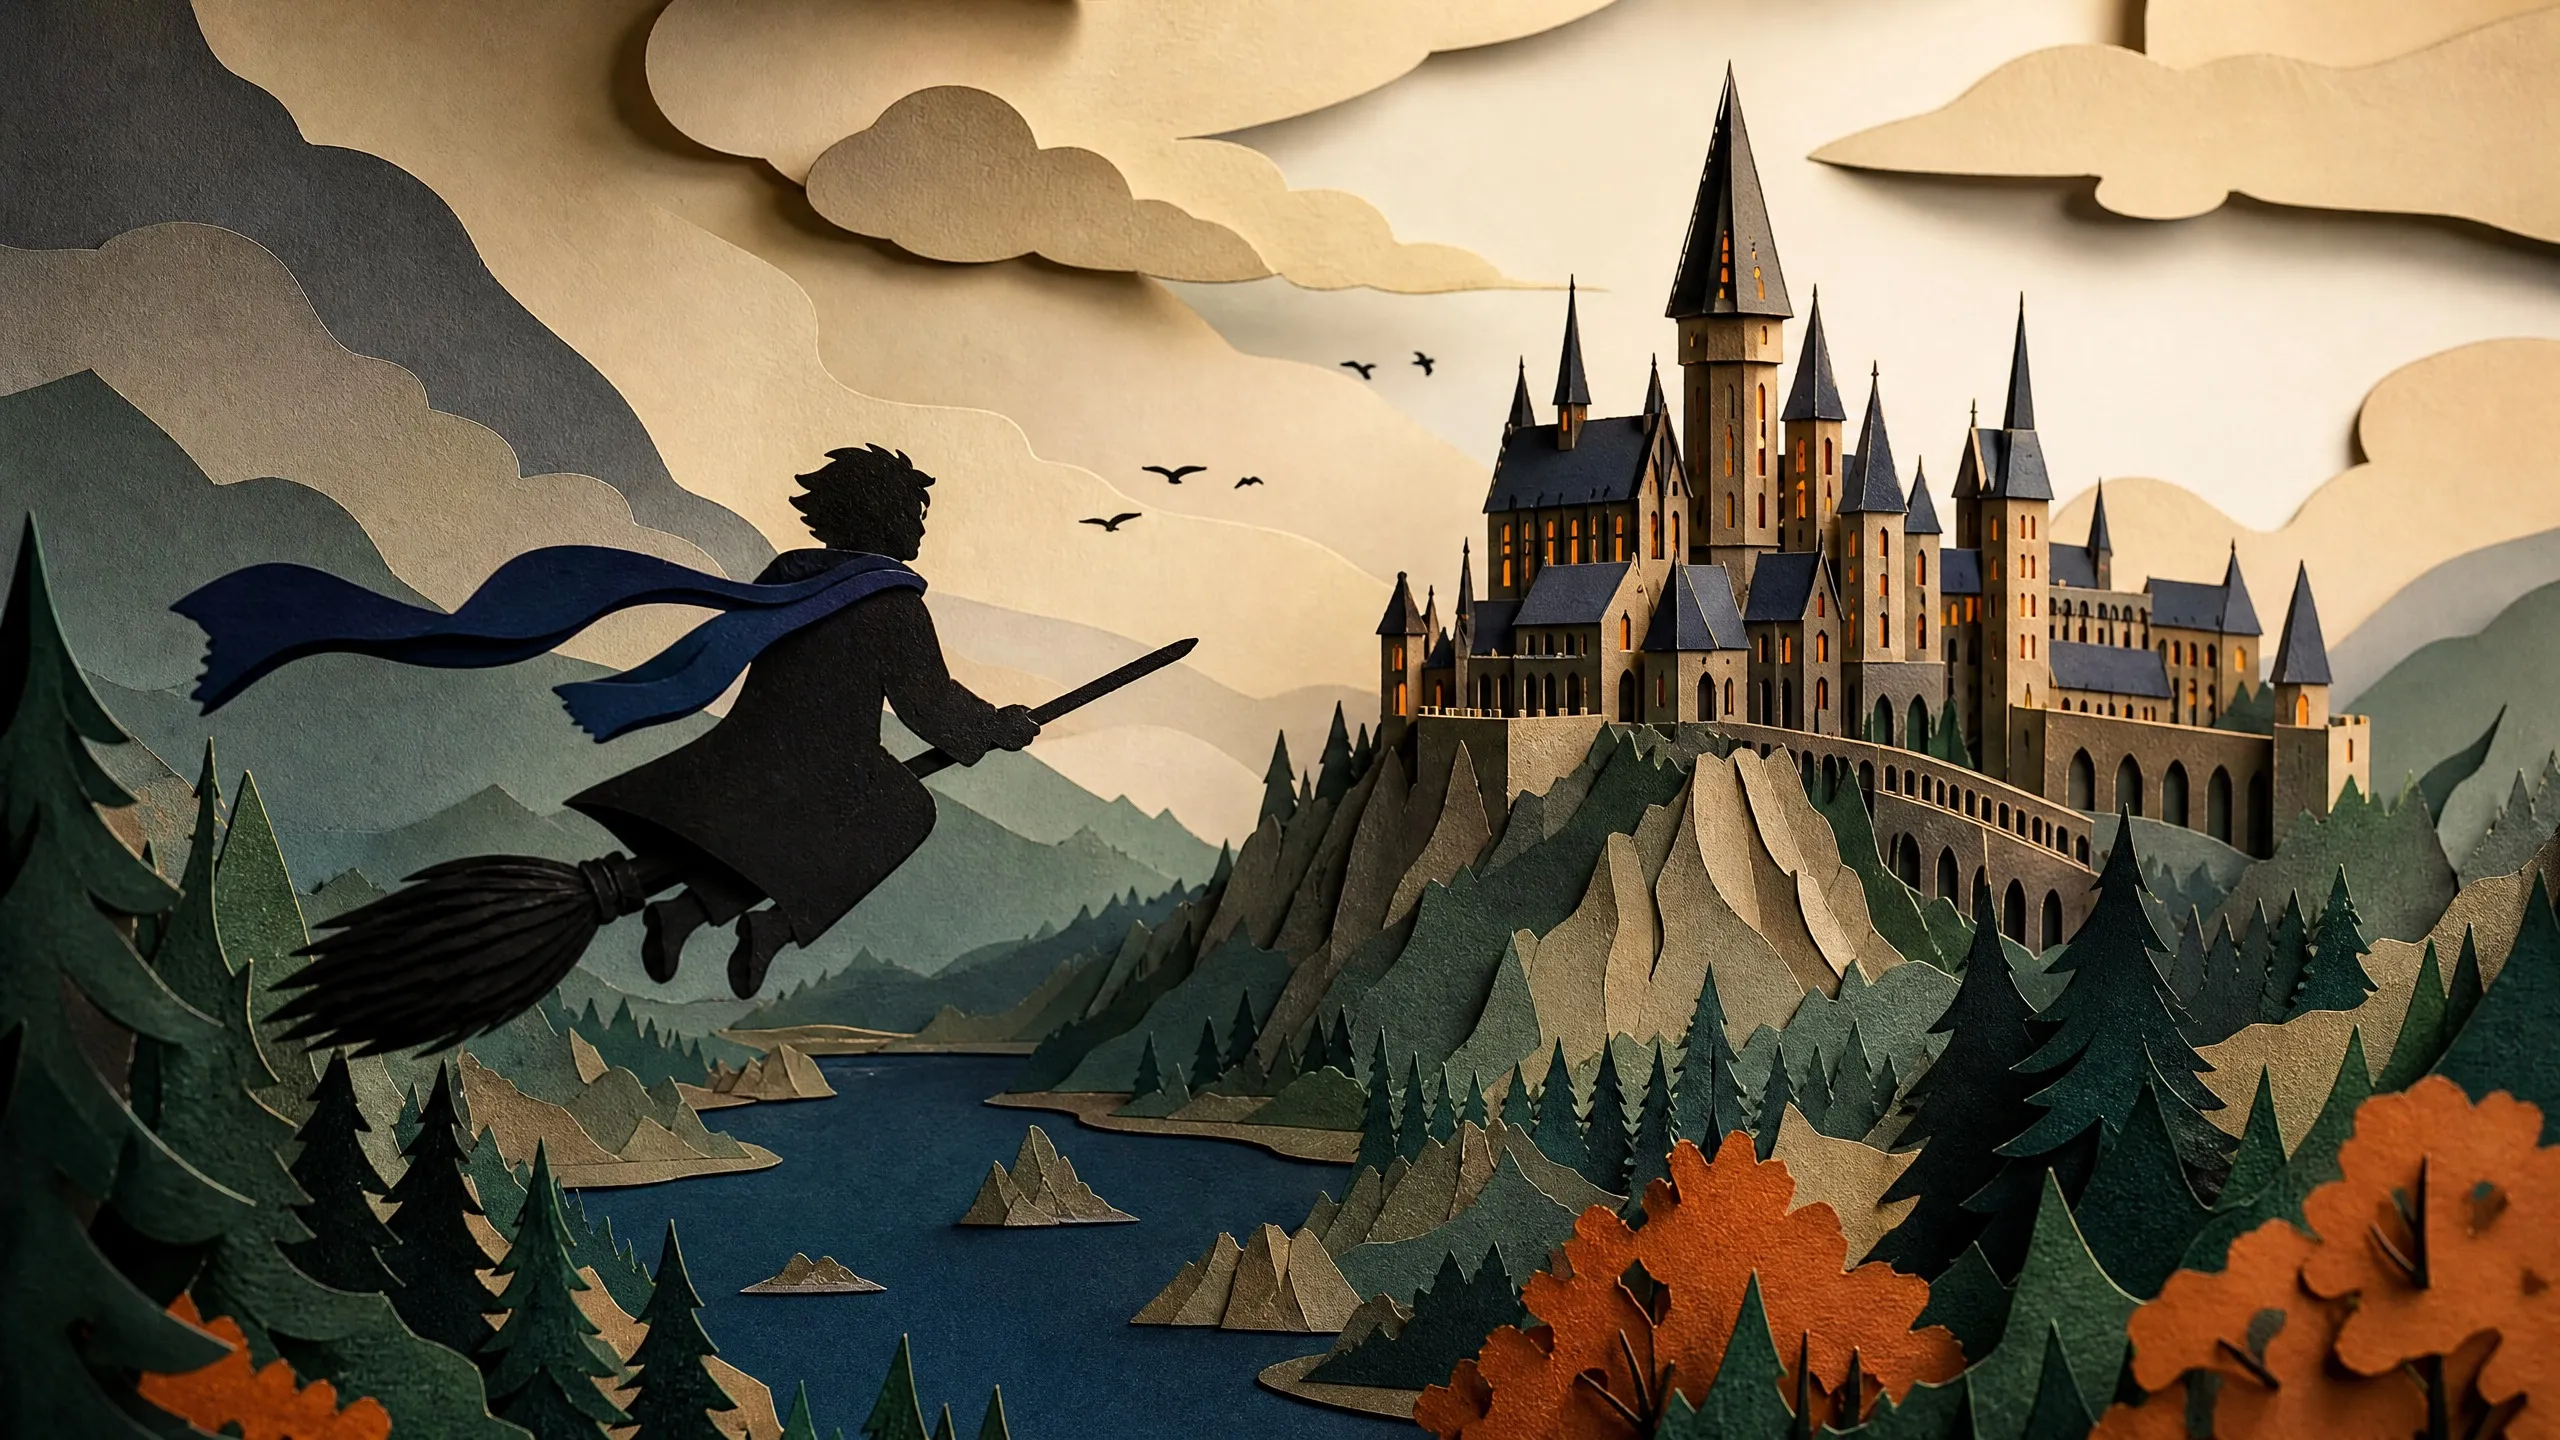
Hogwarts Broom Flight Simulator
Run date: 2026-07-16
Generation provenance: unrecorded
Broom-flight scene testing depth, motion cues, castle scale, and fantasy mood.
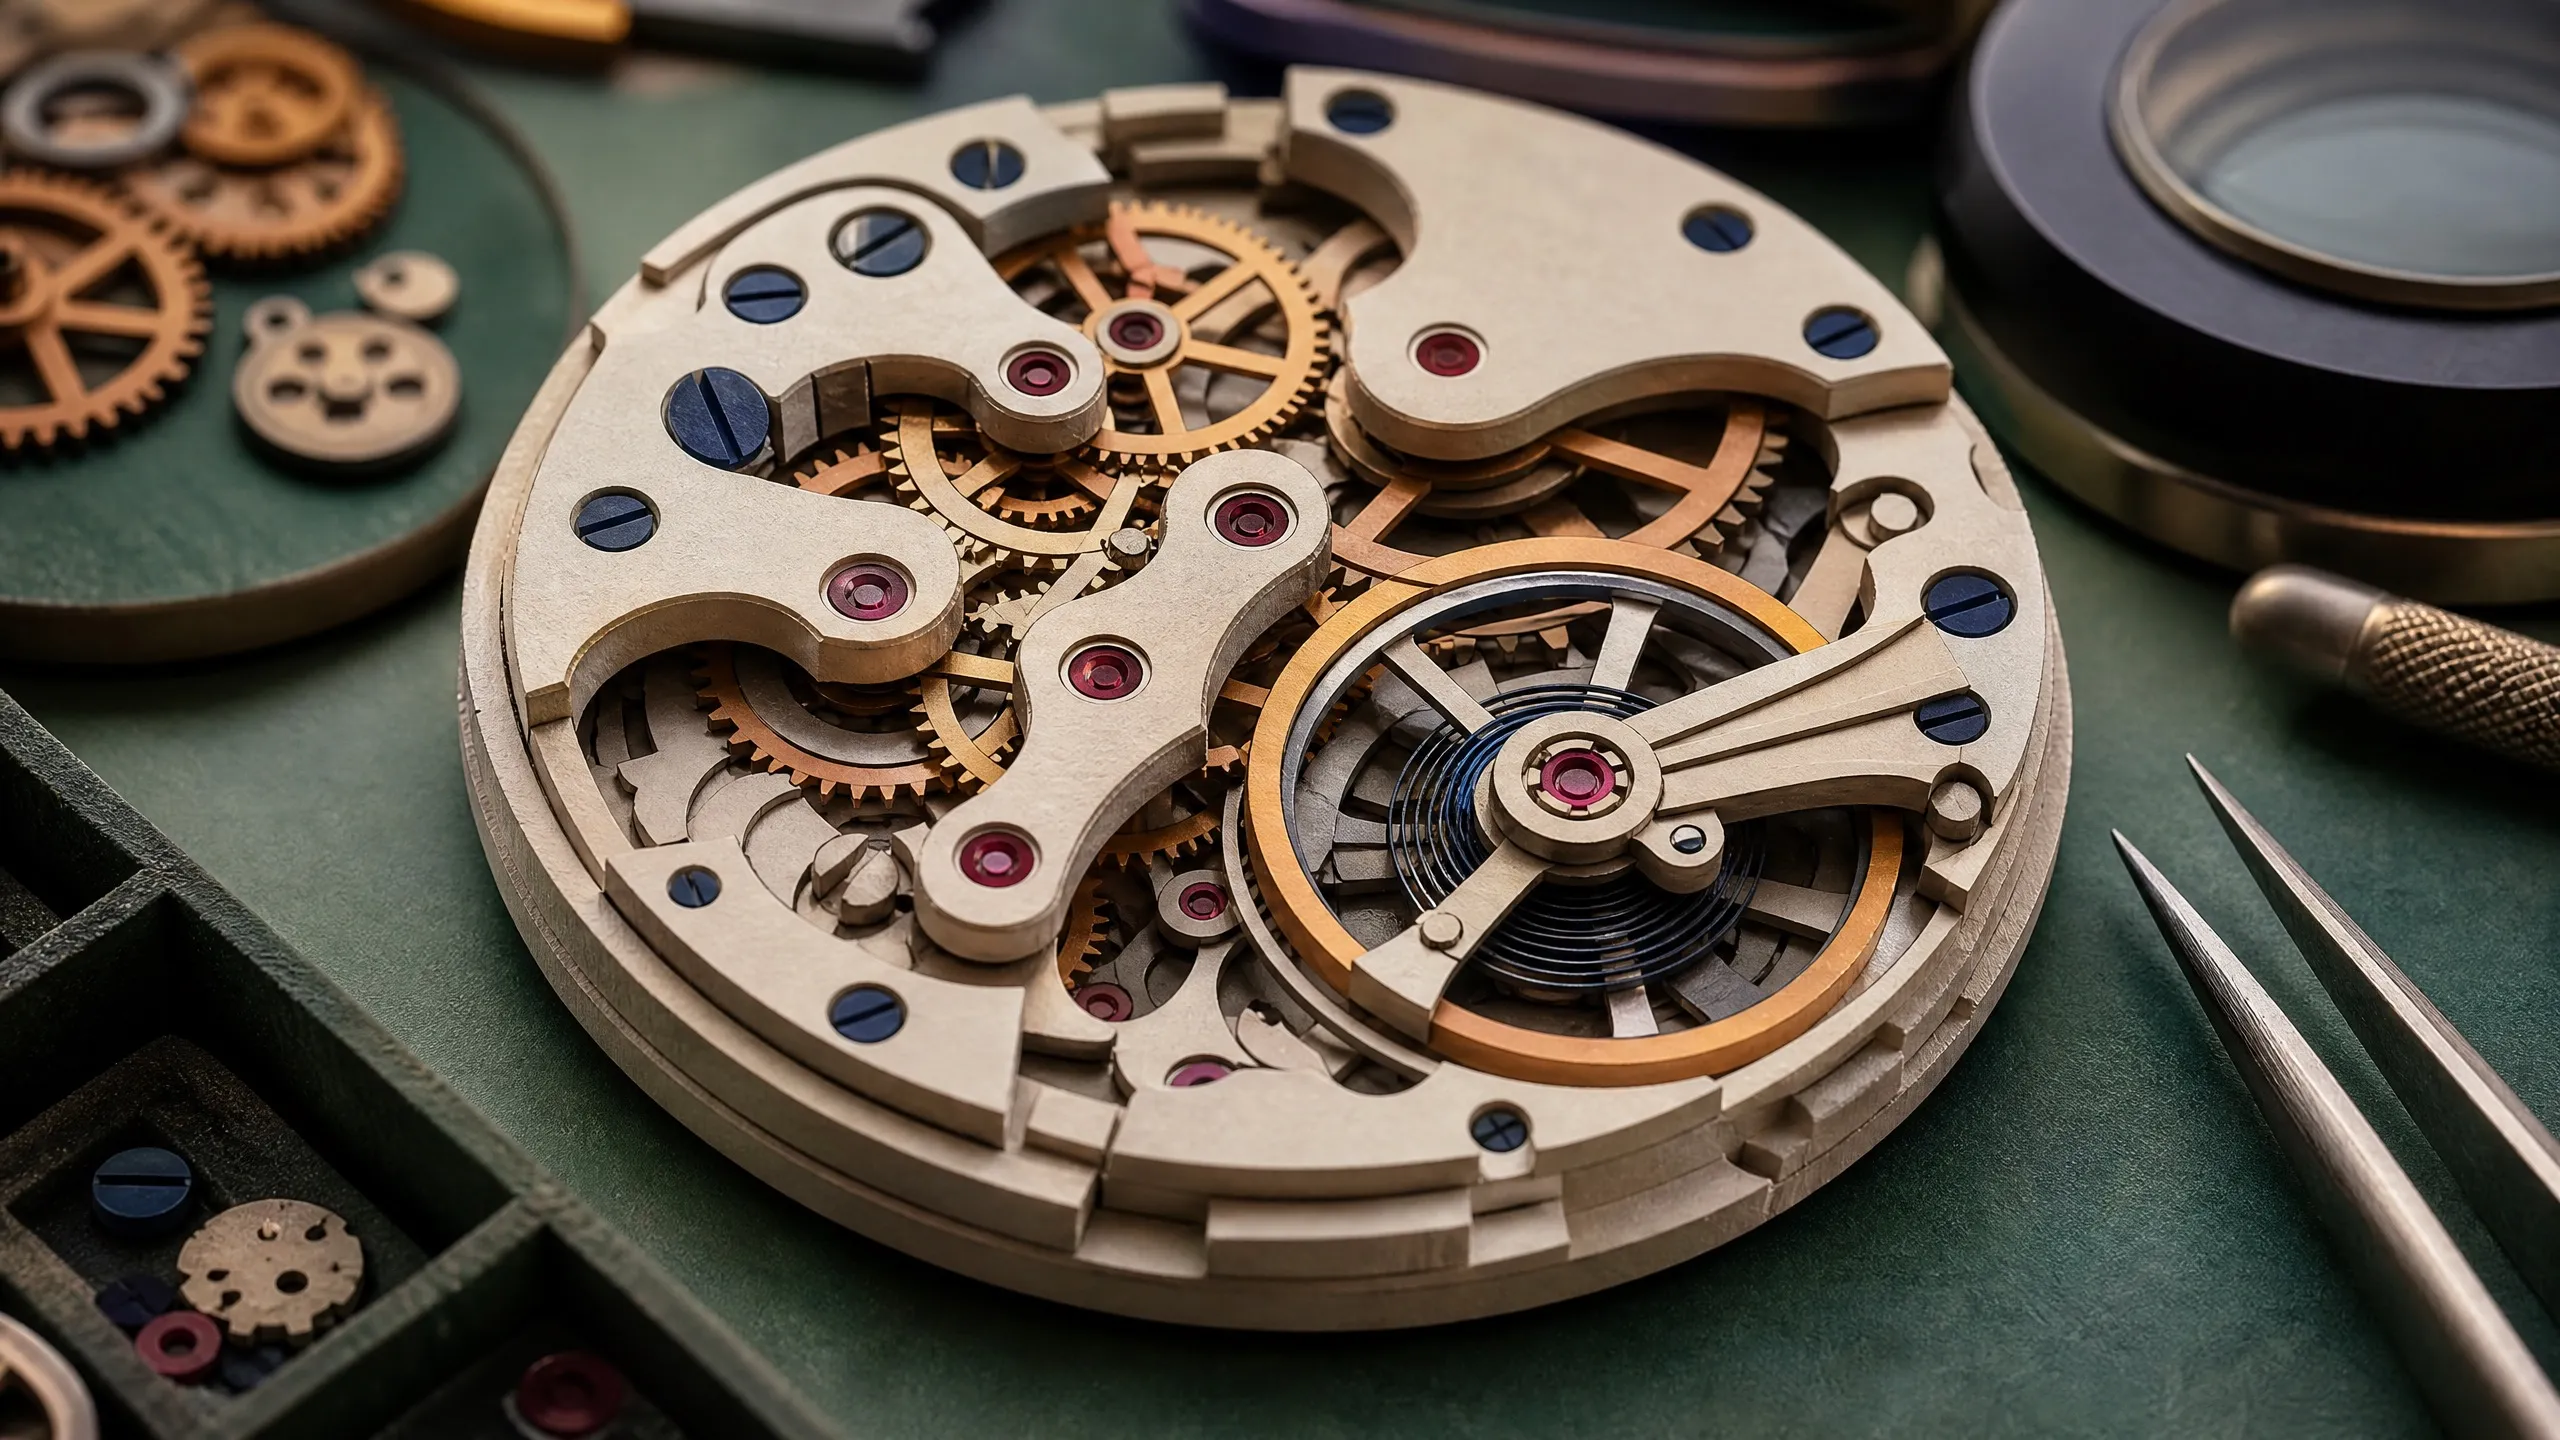
Mechanical Watch Simulator
Run date: 2026-07-24
Generation provenance: unrecorded
Interactive watch movement testing mechanical legibility, accurate relative motion, and real-time 3D controls.
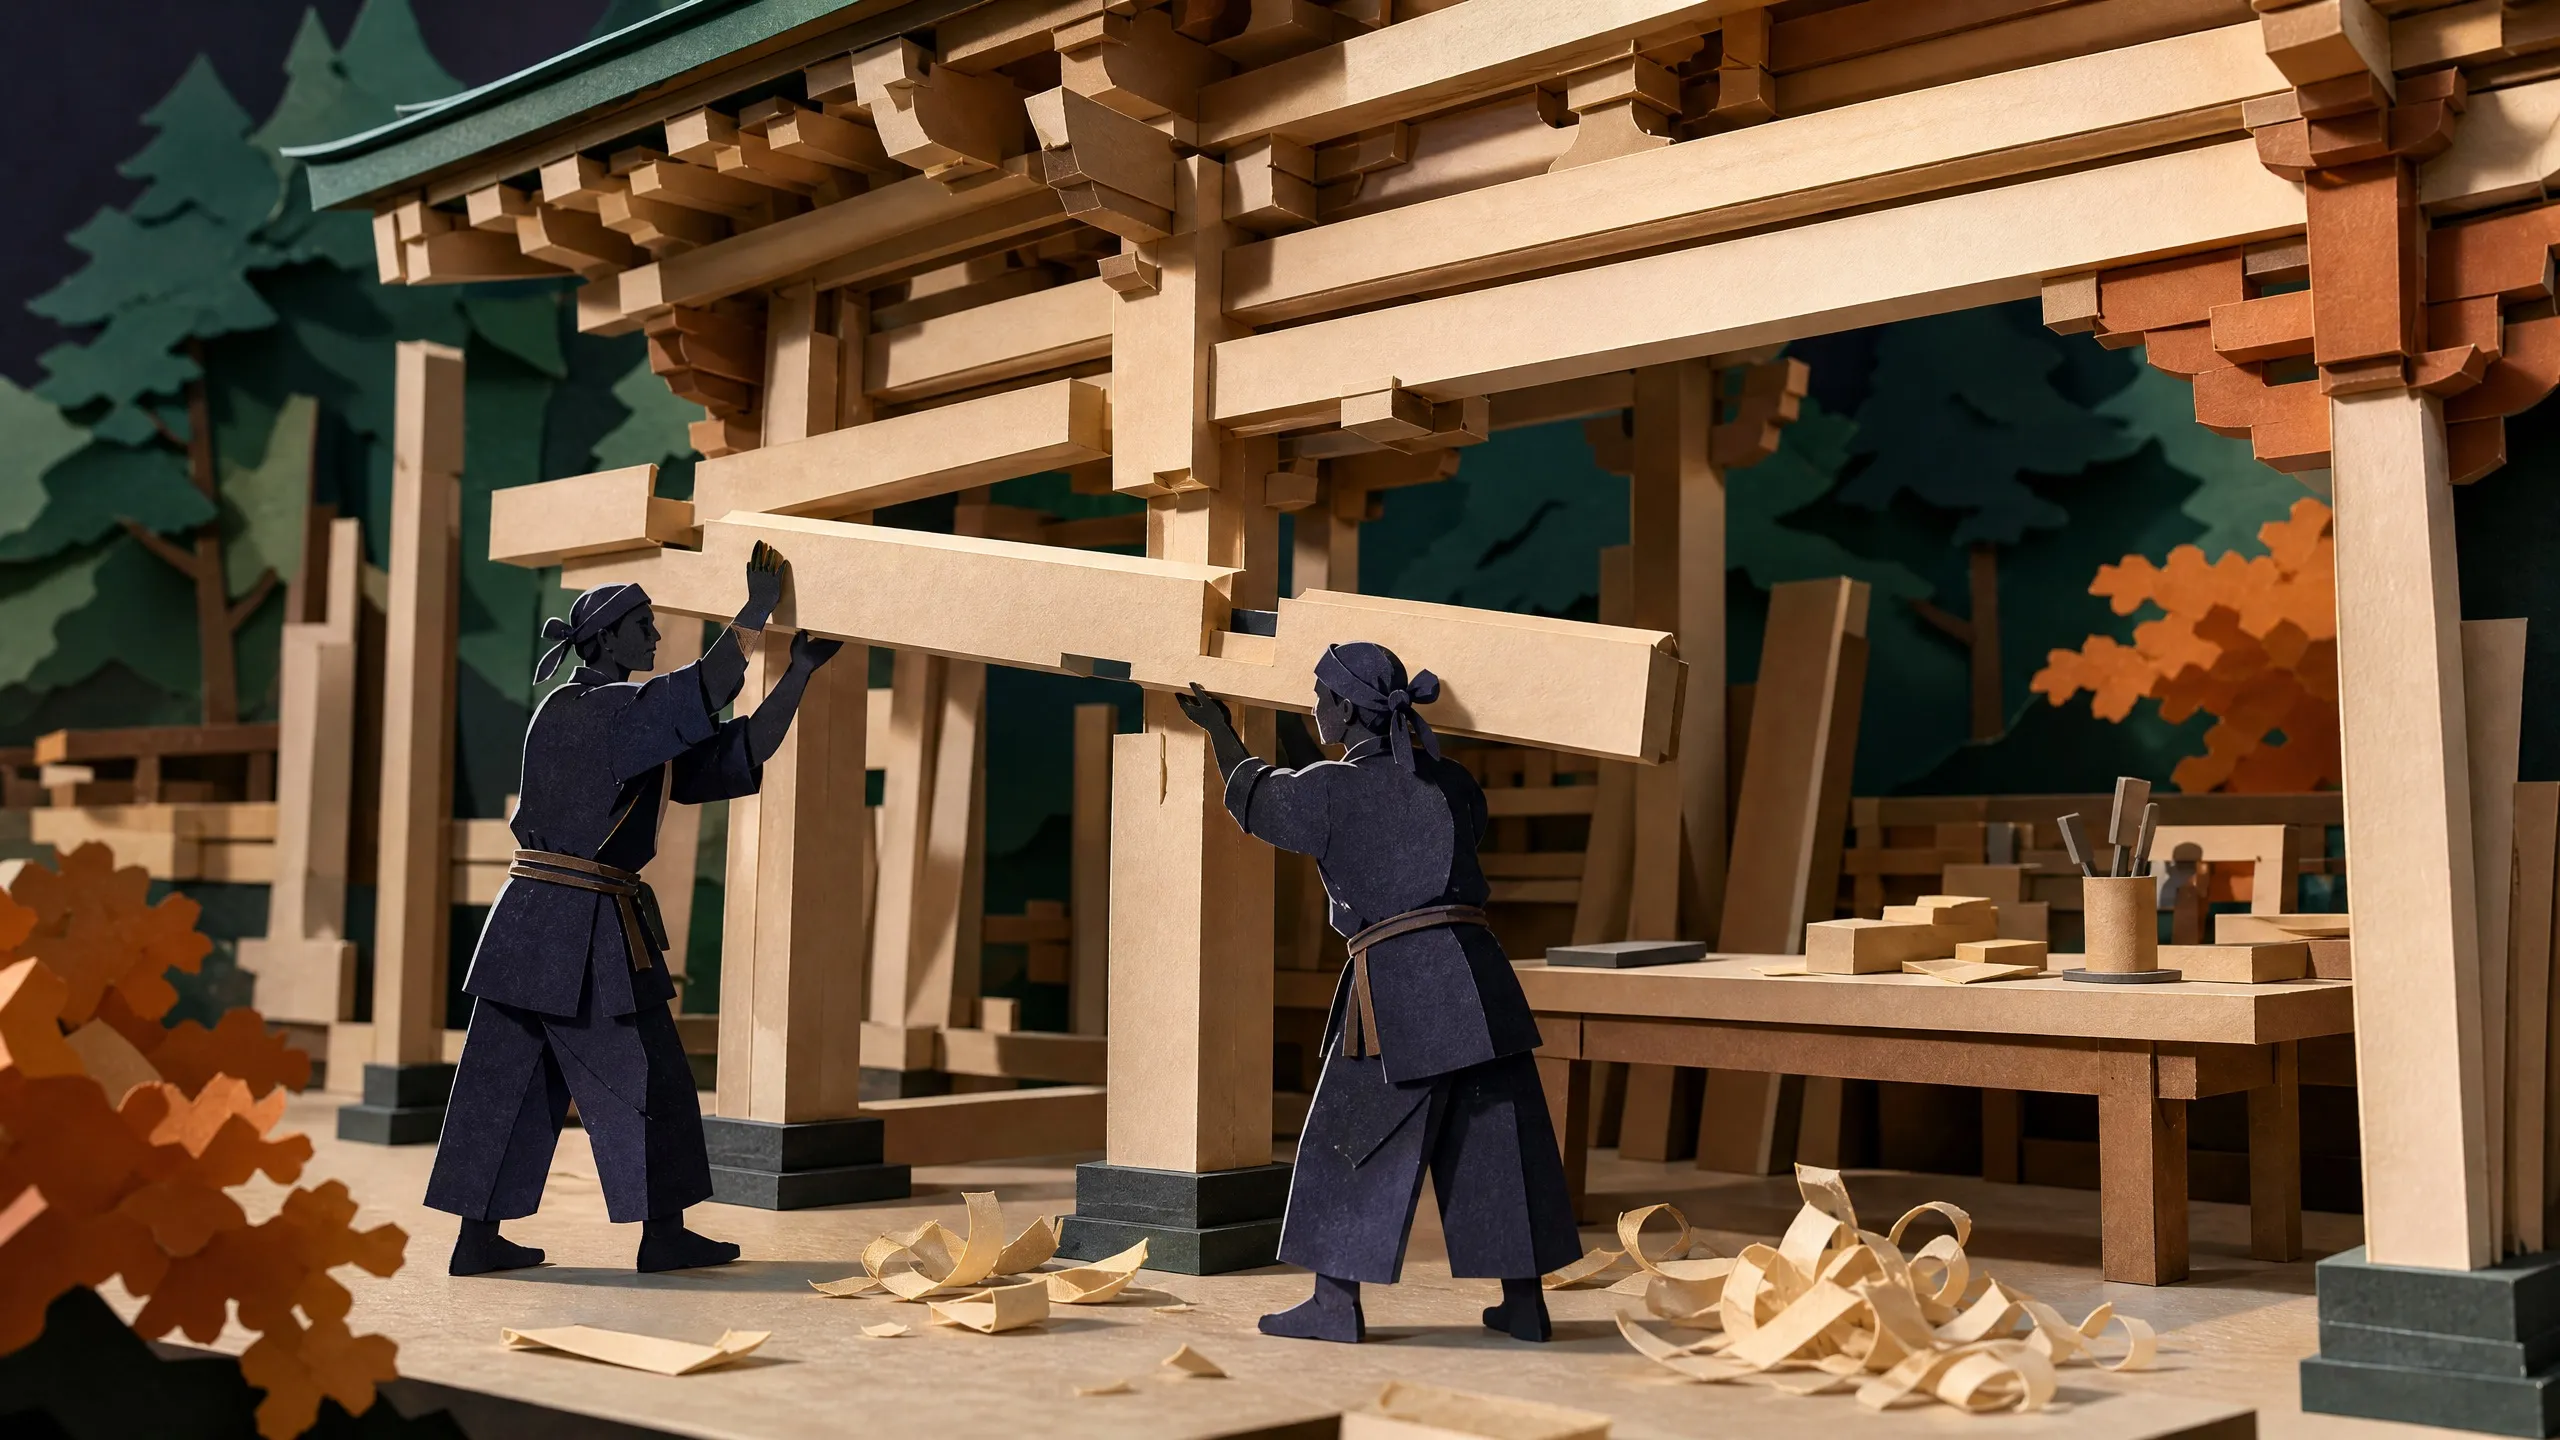
Yingzao Fashi Assembly
Run date: 2026-07-16
Specialist test · evaluated separately
Generation provenance: unrecorded
Timber assembly scene testing structure, joinery, construction order, and material clarity.
Retired tests · 6 archived runs
These tests are no longer in the active suite. Their original results remain available for inspection.
How Kimi K3 compares
Three relevant peers, side by side.
- Kimi K3 This model
- Claude Fable 5
- GPT-5.6 Sol
- Claude Opus 4.8
6 benchmarks · 4 models
Official benchmark profile
Published scores outside our visual tests
GPQA Diamond
93.5%DeepSWE
67.5%Terminal-Bench 2.1
88.3%Full official benchmark table12 scores and peer comparisons
| Benchmark | Area | Score | Comparison |
|---|---|---|---|
| GPQA Diamond | Academic reasoning | 93.5% | |
| DeepSWE | Coding | 67.5% | |
| Terminal-Bench 2.1 | Agentic coding | 88.3% | |
| SWE-Marathon | Long-horizon coding | 42.0% | |
| BrowseComp | Agentic research | 91.2% | |
| DeepSearchQA (F1) | Deep research | 95.0% | |
| MCPMark-Verified | Tool use | 94.5% | |
| AutomationBench | Workflow automation | 30.8% | |
| SpreadsheetBench 2 | Spreadsheet work | 34.8% | |
| OmniDocBench | Document understanding | 91.1% | |
| MMMU-Pro | Multimodal reasoning | 81.6% / 83.4% | |
| CharXiv (RQ) | Chart reasoning | 84.8% / 91.3% |
Sources, pricing details and methodology
Verified model facts
Model specifications
- Status
- Superseded in this ranking
- API model ID
kimi-k3- Context
- 1.05M
- Max output
- 131K
- License
- Not publicly verified
- Access route
- Not publicly verified
- Modalities
- Not publicly verified
- Hardware
- Not publicly verified
- Kimi API · USD / 1M tokens
- $3 input · $0.3 cached input · $15 output
Prices exclude applicable taxes and separately billed tools.
Benchmark sources
Moonshot reports Kimi K3 at maximum reasoning effort across coding, research, tool use, document work, and vision. The official table mixes provider harnesses on some agent tasks, so each row keeps its evaluation setting.
Kimi K3 Technical ReportEvaluation settings
- Maximum reasoning effort, temperature 1.0, top-p 0.95.
- Kimi Code harness on DeepSWE v1.1 tasks.
- Kimi Code harness; peers use each provider's cited best harness.
- Claude Code for Kimi and Claude; Codex for GPT-5.6 on the July 9 H20-calibrated task branch.
- Context compaction at 300K tokens; the full 1M-context run without context management scored 90.4%.
- Maximum reasoning effort, temperature 1.0, top-p 1.0.
- 600-task public subset with the official benchmark setup.
- Claude Code for Kimi and Claude; Codex for GPT models.
- Maximum reasoning effort; average over three multimodal runs.
- Without tools / with Python; original input order; average over three runs.
- Without tools / with Python; average over three runs.
- DeepSWE
- The official leaderboard score under mini-SWE-agent is 67.3%.